Paper: 2604.02329 Authors: Zheng-Hui Huang, Zhixiang Wang, Jiaming Tan, Ruihan Yu, Yidan Zhang, Bo Zheng, Yu-Lun Liu, Yung-Yu Chuang, Kaipeng Zhang Categories: cs.CV
The Gap
The paper is aimed at a bottleneck people in inverse rendering and controllable video generation have been bumping into for a while: the models are getting stronger, but the supervision is still weak in exactly the wrong way.
The mainstream recipe before this paper looked roughly like this:
- For inverse rendering: train on synthetic datasets with clean geometry, material maps, normals, depth, and segmentation because real-world ground truth is expensive or impossible to get.
- For forward rendering / controllable generation: use those same structural signals, often G-buffers, as conditioning to generate or edit images and video.
That sounds fine in theory, but existing synthetic datasets tend to be:
- too small,
- too static,
- too visually simple,
- too lacking in hard real-world effects like motion blur, weather, dense clutter, temporal changes, and cinematic lighting.
So the field has had two bad options:
- Physically neat but visually unrealistic synthetic data from simulators/game engines built for annotation, which gives labels but not real visual complexity.
- Real videos without labels, which give realism but not the aligned geometry/material supervision needed for inverse rendering.
This paper fills that gap by saying: instead of building another sanitized simulator dataset, harvest the complexity already present in AAA games, and do it in a way that keeps synchronized RGB and multiple G-buffer channels over long temporal sequences.
That matters because the paper is not just claiming “more data helps.” The actual claim is narrower and more useful: dynamic, visually rich, temporally continuous synthetic data can reduce the domain gap for both inverse rendering and G-buffer-guided generation.
There is a second gap too: evaluating inverse rendering in the wild is awkward because there is often no ground-truth decomposition. The paper proposes a VLM-based protocol that scores semantic, spatial, and temporal consistency, and argues that it correlates with human judgment.
[Problem]
   |
   v
[Existing synthetic data
 too clean too static
 too small]
   |
   v
[Assumption
 realism and temporal
 continuity matter for
 transfer]
   |
   v
[Method
 AAA game capture
 + stitched dual screen
 + RGB and 5 G buffers
 + 4M continuous frames
 + VLM based eval]
   |
   v
[Evidence
 better cross dataset
 inverse rendering
 better controllable
 generation
 VLM scores align with
 humans]
   |
   v
[Conclusion
 richer dynamic synthetic
 worlds can bridge more
 of the real world gap]
The Increment
One sentence: Before this paper, “synthetic supervision” for rendering mostly meant clean but toy-like data; after it, there is a credible path to training and evaluating on synthetic data that actually looks and behaves like messy visual reality.
Core Mechanism
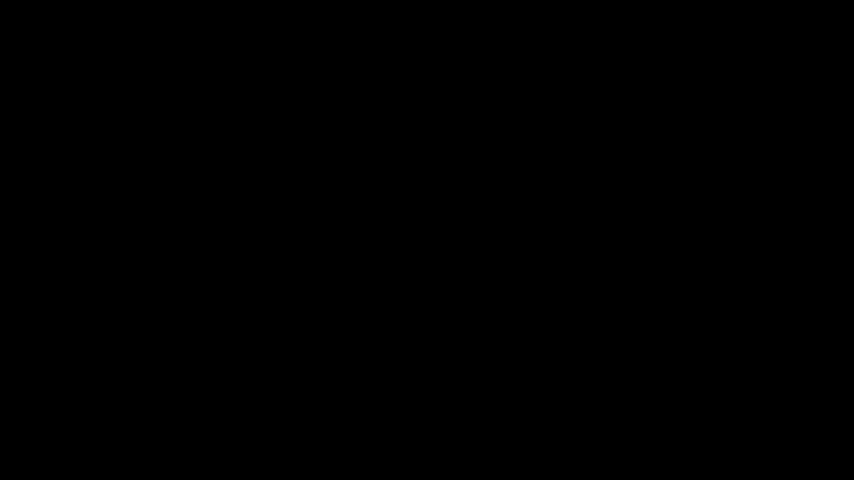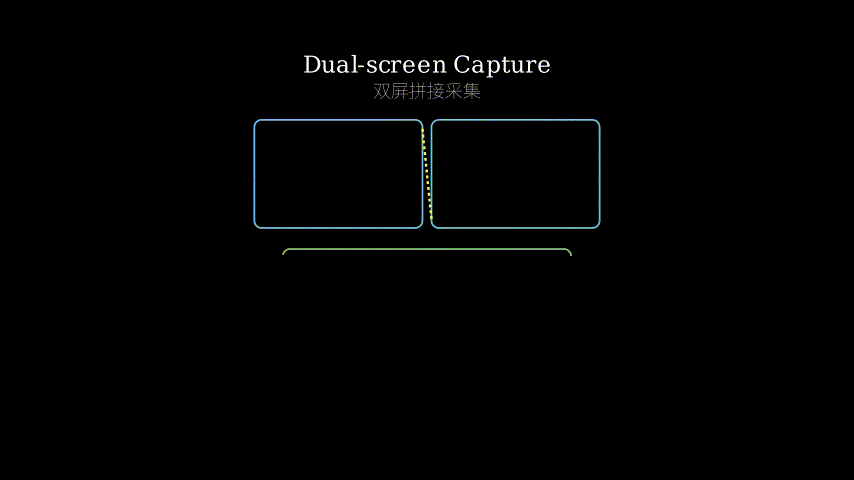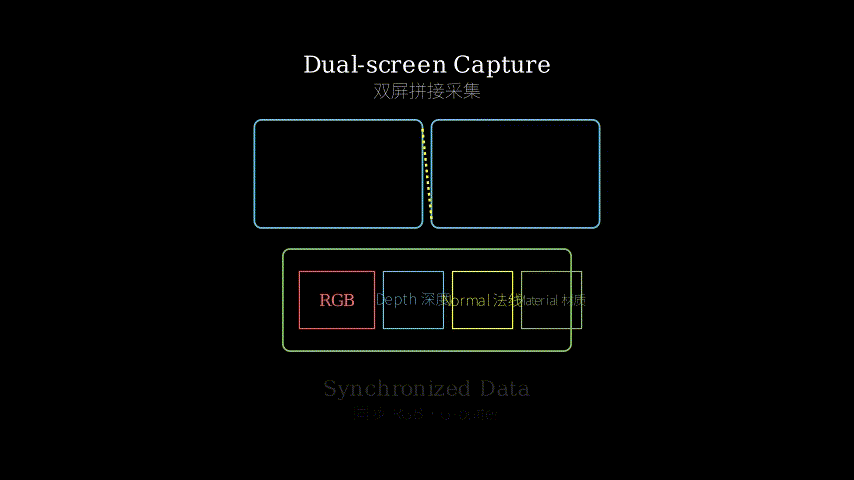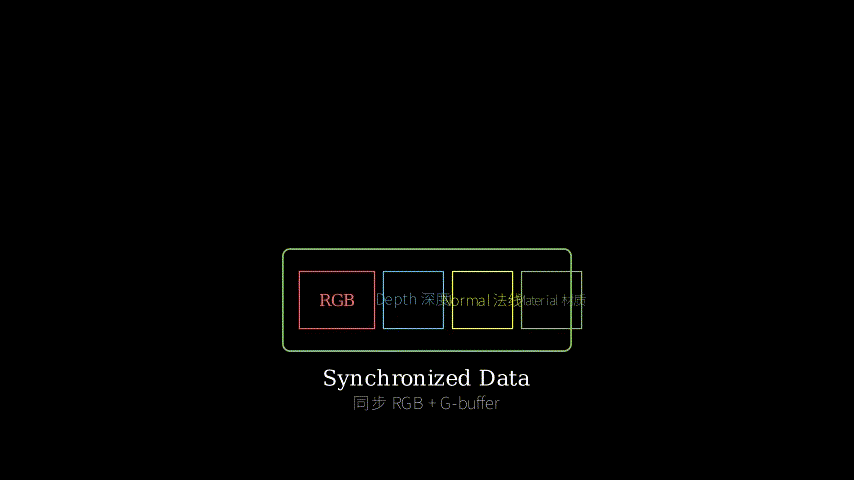
At the center of the paper is really a data-and-evaluation system, not a radically new neural architecture. The first component is the dataset construction pipeline. The authors capture gameplay footage from visually complex AAA games using a dual-screen stitched capture setup. The point of that setup is to recover synchronized signals: one stream provides the rendered RGB frames, and another provides multiple aligned G-buffer channels. They report five such channels, which likely include the usual scene-structure signals such as depth, normals, material-related buffers, and segmentation-like attributes. The important thing is alignment over time: they collect continuous video sequences, not isolated screenshots.
The second component is how that data is used. For inverse rendering, the dataset becomes supervision for learning decompositions from RGB into scene attributes like geometry and material cues under much harder visual conditions than prior synthetic corpora. For forward rendering, those same G-buffers become conditioning signals for image or video generation, so the model can edit appearance while preserving scene structure. This makes the dataset bidirectional: it supports both RGB -> scene factors and scene factors -> RGB/video.
The third component is the evaluation protocol. Since wild inverse rendering usually lacks ground-truth intrinsic maps, the authors bring in a vision-language model as a judge. Instead of asking “is this normal map numerically correct?” they ask whether the predicted decomposition, when used or inspected, preserves semantic consistency, spatial layout, and temporal coherence. The pitch here is pragmatic: if exact labels do not exist, use a model that can still judge whether outputs remain faithful in the ways humans care about.
[AAA game worlds]
      |
      v
[Dual screen stitched capture]
      |
      v
[Aligned streams]
   /                    \
  v                      v
[RGB video]        [5 G buffer channels]
  |                      |
  |                      |
  v                      v
[Inverse rendering]   [Forward rendering]
[RGB > geometry       [G buffers + text
 material factors]     > styled video]
   \                    /
    v                  v
   [Cross dataset generalization
    controllability temporal coherence]
                 |
                 v
        [VLM based evaluation]
        [semantic spatial temporal]
A good way to think about the method is as a movie studio with a perfectly instrumented backlot.
- The AAA game world is the backlot: it looks rich, crowded, cinematic, and weathered, unlike a sterile lab set.
- The RGB capture is the final movie shot that audiences see.
- The G-buffers are the hidden production logs: where the walls are, what surfaces are made of, how objects face the camera, what belongs to what.
- The continuous sequences are not publicity stills but full takes, so you can see whether things stay consistent from frame to frame.
- The inverse renderer is a forensic crew trying to infer the hidden production logs just from the released movie.
- The forward renderer is an editor who takes the production logs and regrades or restyles the film while keeping the scene intact.
- The VLM evaluator is a seasoned continuity supervisor who cannot inspect physical ground truth but can still say, “the coat changed color across cuts,” or “the geometry no longer matches the action.”
This metaphor is load-bearing because it captures why this dataset matters. If your training data is only clean CAD-like snapshots, that is like training filmmakers from empty rehearsal rooms. AAA-game capture gives you real production complexity while still exposing the hidden logs.
Key Concepts
-
G-buffer: In graphics pipelines, a G-buffer is like the scene’s backstage notebook. A rendered image only tells you what things look like. A G-buffer tells you extra facts about each pixel, such as how far away it is, which way the surface faces, or what material it belongs to. For example, two cars might both look dark blue in RGB, but a G-buffer can reveal that one is glossy metal and the other is matte plastic. That extra structure is exactly what makes controllable generation and inverse rendering possible.
-
Domain gap: This is the mismatch between the world you train on and the world you test on. If you train a decomposition model on crisp, static simulator scenes and then test it on rainy, blurry, fast-moving urban footage, the model fails not because decomposition is impossible, but because it learned the wrong visual habits. A dataset from AAA games narrows the gap because it includes clutter, lighting effects, weather, and motion patterns closer to what hard real imagery contains.
-
Temporal coherence: A single frame can look good while the video still looks bad. Temporal coherence means the output behaves stably across time. If a material map says a wall is concrete in frame 1, it should not suddenly become polished stone in frame 2 just because the camera moved. This paper emphasizes continuous sequences, which is important because many datasets quietly dodge this issue by treating video as unrelated images.
Framework Shift
Before (mainstream approach):        After (this paper):

[clean synthetic world]              [AAA game world]
          |                                   |
          v                                   v
 [single images or short clips]      [long continuous video]
          |                                   |
          v                                   v
 [RGB + neat labels]                  [RGB + rich G buffers]
          |                                   |
          v                                   v
 [train on easy visuals]              [train on hard visuals]
          |                                   |
          v                                   v
 [good in synthetic regime]           [better transfer and
                                      controllable generation]
From label-rich but visually toy-like supervision to label-rich and visually dynamic supervision, the core shift is treating realism itself as a missing part of the annotation pipeline.
Expert Assessment
Problem choice: This is a real gap, not a manufactured one. The field has spent years pretending that if the labels are perfect enough, the images can be simplistic. That was always a temporary bargain. As generative and inverse rendering systems move toward open-world deployment, data realism and temporal continuity become first-order issues. So the paper sits in a very sensible place in the field’s trajectory.
Method maturity: The main insight is more systems-and-dataset engineering than algorithmic novelty. That is not a criticism; it is just the right classification. The clever part is recognizing that AAA games are a sweet spot: much richer than standard synthetic benchmarks, still instrumentable enough to expose structural signals. The VLM-based evaluation is also pragmatic. That said, this is not a deep new rendering theory. If you are looking for a new model class, this is not that paper.
Experimental integrity: Based on the abstract, the claims seem directionally plausible: improved cross-dataset generalization, stronger controllable generation, and VLM judgments correlating with human ratings. Those are the right things to test. The thing I would want to inspect closely in the full paper is whether the gains come mainly from scale, visual richness, or temporal continuity. If the ablations do not disentangle those factors, then the takeaway becomes fuzzier. I would also want to know how broad the AAA-game coverage is and whether there is hidden style concentration from a small number of titles.
Writing quality: The abstract is clear, but it compresses several contributions into one stream: dataset, capture method, bidirectional rendering use case, evaluation protocol, and application demo. In the full paper, the section that most needs careful writing is the evaluation methodology. If they want the VLM-based metric to be taken seriously, they need to explain exactly what prompts, criteria, failure modes, and calibration steps were used. That section could make or break confidence in the work.
Verdict: weak accept — strong practical relevance and a meaningful dataset contribution, but the novelty is more infrastructural than conceptual, so the paper will live or die by the rigor of its ablations and evaluation details.
Takeaways
What a practitioner can steal here is pretty concrete:
- If your structured prediction problem lacks real labels, look for instrumented synthetic worlds with richer appearance, not just cleaner annotations. The data source choice can matter as much as model choice.
- Prefer continuous sequence capture over isolated frames when your downstream task will be judged temporally. This applies far beyond rendering: robotics, driving, tracking, video understanding.
- Use hidden engine signals as supervision and control channels. In other domains, that might mean simulator state, game logs, or system telemetry instead of only pixels.
- When ground truth is unavailable, evaluate via decomposed consistency dimensions rather than a single scalar metric. Semantic consistency, spatial faithfulness, and temporal stability is a portable framing.
- AAA-game worlds are an underused middle ground between sterile simulation and expensive real-world annotation. That framing could transfer to embodied AI, scene understanding, imitation learning, and video generation.
论文: 2604.02329 作者: Zheng-Hui Huang, Zhixiang Wang, Jiaming Tan, Ruihan Yu, Yidan Zhang, Bo Zheng, Yu-Lun Liu, Yung-Yu Chuang, Kaipeng Zhang 分类: cs.CV
缺口
这篇论文瞄准的是一个很实在、而且越来越卡脖子的地方:生成式逆向渲染和正向渲染的模型已经越来越强,但训练它们的数据仍然停留在“标注完整但视觉过于玩具化”的阶段。
此前主流路径大概是这样:
- 做逆向渲染,就依赖带真值的合成数据,因为真实世界里法线、深度、材质分解这些标签几乎拿不到。
- 做可控生成/正向渲染,就把 G-buffer 之类的结构信号拿来当条件,让模型按几何和材质约束生成图像或视频。
问题在于,现有很多 synthetic benchmark 虽然“干净”,但也真的太干净了。
它们常常有几个共性短板:
- 场景规模不够大。
- 视频连续性不够。
- 视觉复杂度不够。
- 缺少恶劣天气、运动模糊、电影化光照、复杂特效、密集遮挡这些真正让模型犯错的因素。
于是领域里长期有个尴尬二选一:
- 有标签,但不够像真实世界。
- 像真实世界,但没有结构真值。
这篇论文的补位点很明确:
它不再去造一个“更规整的合成世界”,而是直接把AAA 游戏当作高复杂度、可采集、可持续输出结构信息的“半真实世界”。
再通过一个双屏拼接采集方法,把 RGB 视频和多个 G-buffer 通道同步抓出来,而且是长时间连续序列。
这件事的重要性在于,它不是泛泛地说“数据更大就更好”。
它真正想证明的是:如果合成数据同时具有视觉复杂度和时间连续性,那么它对逆向渲染的泛化,以及对 G-buffer 引导生成的可控性,都会明显更有帮助。
论文还补了第二个缺口:
逆向渲染在野外场景里经常没有真值,所以评价很难做。
作者提出了一个基于 VLM 的评测协议,不去死磕逐像素真值,而是从语义一致性、空间一致性、时间一致性三个角度判断模型输出是否“像那么回事”,并声称它和人类判断相关性较高。
[问题]
   |
   v
[现有合成数据
 太干净 太静态
 太小]
   |
   v
[假设
 视觉真实感和
 时间连续性
 决定迁移效果]
   |
   v
[方法
 AAA游戏采集
 + 双屏拼接
 + RGB和5个Gbuffer
 + 400万连续帧
 + VLM评测]
   |
   v
[证据
 逆向渲染跨数据集
 泛化更好
 可控生成更强
 VLM与人工更一致]
   |
   v
[结论
 高复杂动态合成世界
 能更有效缩小域差]
增量
一句话: 在这篇论文之前,“可监督的渲染数据”基本等于干净但失真的合成集;在这篇论文之后,领域里多了一条更像真实世界、还能保留结构监督的中间路线。
核心机制
这篇论文本质上不是在发明一个特别花哨的新网络,而是在搭一个数据采集加评测闭环。
第一部分是数据采集。
作者从视觉复杂度很高的 AAA 游戏中抓取连续画面,并用一种双屏拼接的采集方案拿到同步的 RGB 视频和五个 G-buffer 通道。
你可以把它理解成:一个屏幕拿“最后渲染出来给人看的画面”,另一个屏幕拿“引擎内部知道但观众看不到的结构信息”。
关键不是单帧,而是连续视频,因为很多渲染任务真正的难点都出在时间维度上。
第二部分是数据怎么用。
对逆向渲染来说,这套数据提供了从 RGB 到场景属性分解的监督,比如几何、法线、材质这类隐变量。
对正向渲染/可控生成来说,这些 G-buffer 又能反过来作为条件输入,让模型根据几何和材质约束去生成或重风格化视频。
所以这不是单向数据集,而是一个支持 RGB -> 结构分解 和 结构 -> RGB生成 的双向工具。
第三部分是怎么评估。
因为真实世界里通常没有可靠真值,作者就引入 VLM 来判断输出结果在三个维度上是否站得住:
- 语义上有没有跑偏。
- 空间关系有没有错位。
- 时间上有没有闪烁和跳变。
这背后的思路挺务实:既然逐像素标准答案拿不到,那就退一步,评估“人会不会觉得它逻辑一致”。
[AAA游戏世界]
      |
      v
[双屏拼接采集]
      |
      v
[同步数据流]
   /                    \
  v                      v
[RGB视频]          [5个Gbuffer通道]
  |                      |
  |                      |
  v                      v
[逆向渲染训练]      [正向渲染训练]
[RGB到几何材质]     [Gbuffer加文本
                      到风格化视频]
   \                    /
    v                  v
   [跨域泛化 更强可控性
    更好时间一致性]
                 |
                 v
            [VLM评测]
      [语义 空间 时间一致]
我觉得最好的核喻是:这像在一个拍摄条件完备的影视片场里做研究。
-
AAA 游戏世界,就是那个大制作片场。
它不是空荡荡的实验室布景,而是有天气、烟雾、复杂灯光、反射、运动和拥挤物体的真实拍摄环境。 -
RGB 视频,就是最后上映给观众看的成片。
-
G-buffer,就是片场的幕后记录表。
它写着“这面墙离镜头多远”“这个表面朝哪个方向”“这块区域是什么材质”“这个像素属于哪个物体”。
观众看不到,但拍摄系统知道。 -
连续帧,就是整段镜头,而不是几张剧照。
你只有看整段,才知道前后是否穿帮。 -
逆向渲染模型,像法证团队。
它只看成片,试图倒推出幕后记录表。 -
正向渲染模型,像后期调色和美术重制团队。
它拿到幕后记录表,就可以在不毁掉场景结构的前提下改风格、改质感、改氛围。 -
VLM 评测器,像经验老到的场记。
它不一定知道物理真值,但它能看出“上一镜这个车门是红的,下一镜怎么突然黑了”“人物走位和背景结构对不上”。
这个比喻是承重的,因为它抓住了论文最本质的一点:
作者不是在说“我要一个更大的数据集”,而是在说“我要一个既保留幕后结构记录、又拥有大片级视觉复杂度的片场”。
没有这个中间地带,模型永远只能在“数据很假”和“数据没标签”之间摇摆。
关键概念
-
G-buffer: 可以把它理解成“每个像素的后台档案”。
普通 RGB 图像只告诉你这个像素长什么样。
G-buffer 会额外告诉你:它离相机多远、表面朝向哪边、可能属于什么材质、是不是同一个物体的一部分。
举个例子,两块区域在图像里都可能是灰色,但一块是湿润金属,一块是粗糙水泥。
RGB 很难直接分辨,G-buffer 就能把这类结构信息补出来。 -
域差: 就是训练世界和测试世界不是一个世界。
你在干净、静止、无遮挡的合成图上学会的本领,拿到下雨、模糊、运动快、光照乱变的真实视频里,往往立刻掉线。
这不是任务本身做不了,而是你学到的是“实验室里的视觉习惯”,不是“开放世界里的视觉规律”。 -
时间一致性: 一张图看着对,不代表视频也对。
如果一个模型在第 1 帧把地面判断成湿柏油,第 2 帧又跳成抛光石材,第 3 帧再变回去,人眼马上就会觉得假。
所以连续视频任务里,稳定比单帧漂亮更重要。
这也是为什么这篇论文强调“continuous frames”,而不是只堆单帧样本数。
框架转变
之前(主流方法):                之后(本文方法):

[干净合成世界]                    [AAA游戏世界]
       |                                |
       v                                v
[单帧或短片段]                    [长连续视频]
       |                                |
       v                                v
[RGB加规整标签]                   [RGB加丰富Gbuffer]
       |                                |
       v                                v
[在容易视觉条件上训练]            [在高复杂视觉条件上训练]
       |                                |
       v                                v
[合成域内表现好]                  [跨域泛化和可控生成更强]
一句话:从只有标签真实到标签和视觉环境都更真实,核心转变是把“视觉复杂度”本身当成监督数据的一部分。
专家评审
选题眼光: 这是真缺口,不是硬造出来的命题。
逆向渲染和条件生成这几年都在往真实开放世界走,但很多论文的数据观还停留在“只要标注准,画面假一点没关系”。
这个假设现在越来越站不住了。
所以这篇论文的位置很合理:它不是在卷一个局部指标,而是在补整个任务栈里最脆弱的一环。
方法成熟度: 更像系统工程上的巧组合,而不是理论层面的猛创新。
但这里的“工程”不是贬义。
真正聪明的地方是作者找到 AAA 游戏这个甜点区:比一般 synthetic benchmark 丰富得多,又不像真实拍摄那样几乎无法拿结构真值。
VLM 评测也是同一路数,属于“先把可用的闭环搭起来”。
当然,如果你期待的是一种全新的网络结构或损失函数革命,那这篇不是。
实验诚意: 从摘要看,实验方向是对的:
- 看跨数据集泛化。
- 看可控生成质量。
- 看 VLM 和人工评价的相关性。
这些都抓住了论文真正该证明的点。
但我会特别在意几个问题:
第一,提升到底来自数据量、视觉复杂度,还是时间连续性?
如果消融没拆开,这个故事就会显得有点混。
第二,AAA 游戏的覆盖面够不够广?
如果主要来自少数几款作品,那可能学到的是某种“游戏美术风格分布”,不一定是广义现实复杂度。
第三,VLM 评测有没有 prompt 敏感性和模型偏置问题?
这部分如果写得松,结论会打折。
写作功力: 摘要的信息密度高,但有点把多个贡献捆成一股脑往前推:数据集、采集方案、双向渲染用途、VLM 评测、应用 demo 全塞在一起。
如果全文里有一节最该重写,我会选评测协议那一节。
因为这篇论文是否能被长期引用,不只取决于数据集本身,也取决于大家会不会信这个“无真值逆向渲染评测”框架。
那部分越透明、越可复现,整篇论文就越站得住。
判决: 弱接收 — 问题抓得准,数据贡献有分量,但核心新意更偏基础设施,最终说服力要看消融和评测细节是否足够扎实。
要点总结
如果你是实践者,这篇论文里能直接“偷”的东西其实不少:
-
别只追求标注完整,还要追求视觉分布接近真实难例。
很多任务的上限不是模型不够强,而是训练数据把问题简化过头了。 -
能采连续序列,就不要只采单帧。
只要你的下游结果是视频、轨迹、交互或任何时间相关输出,时间一致性就不该事后补救,而该在数据采集阶段就设计进去。 -
把系统内部的隐变量当成监督和控制信号。
在图形学里是 G-buffer。
在别的领域里,也可能是 simulator state、游戏日志、传感器中间量、操作系统遥测。
不要只盯着输入输出两端。 -
没有真值时,别执着于单一数值指标。
把评估拆成语义、空间、时间三个维度,是个很能迁移的框架。
做视频理解、机器人、自动驾驶、世界模型时都能借。 -
AAA 游戏是一类被低估的数据中间层。
它介于“过于干净的模拟器”和“昂贵难标的真实世界”之间。
这个思路不只适合渲染,也适合 embodied AI、场景理解、模仿学习、视频生成。