Paper: 2605.00800 Authors: Pavlin G. Poličar, Andraž Pevcin, Blaž Zupan Categories: cs.LG
The Gap
Existing chart generation approaches treat the problem as prompt-to-code translation: feed an LLM tabular data, get back plotting code, hope it works. This fails because many visualization errors—overlapping labels, unreadable legends, semantically wrong chart types—only become apparent after rendering. Current chart datasets compound the problem by providing isolated artifacts: code without context, images without executable source, or questions without aligned data provenance. The field has chart generation systems and chart QA benchmarks, but no integrated pipeline that treats chart creation as an inspectable, refinable process where each artifact (code, image, description, questions) is traceable to its source data.
Problem: LLM generates code -> Render reveals failures
                                (overlapping text, wrong chart type)
                                     |
                                     v
Gap: No feedback loop from rendered output back to generation
     No datasets with [data + code + image + context + QA] aligned
                                     |
                                     v
Method: Multi-stage workflow with validation after rendering
        Retain all artifacts at each stage
                                     |
                                     v
Evidence: 1,500 charts from 74 datasets, 24 chart families
          MLLMs struggle with value extraction vs syntax (diagnostic)
                                     |
                                     v
Conclusion: Validation-driven generation produces higher-quality,
            fully-aligned chart datasets for multimodal reasoning
The Increment
One sentence: Before this paper, chart generation was a black-box prompt-to-code step with no way to catch rendering failures; after, it’s a multi-stage inspectable workflow where validation of the rendered image drives iterative refinement.
Core Mechanism
The workflow decomposes chart generation into seven sequential stages. First, dataset screening filters tabular data for suitability (sufficient rows, numeric columns, no excessive missing values). Second, plot proposal uses an LLM to suggest chart types appropriate for the data’s structure and potential analytical questions. Third, code synthesis generates executable plotting code. Fourth, rendering executes the code to produce the actual image. Fifth, validation-driven refinement checks the rendered output against criteria like label readability, legend clarity, and semantic correctness—if validation fails, the LLM revises the code and re-renders. Sixth, description generation produces natural language captions for the finalized chart. Seventh, question-answer generation creates QA pairs grounded in the chart, spanning syntax (chart type), value extraction (read a specific data point), comparison (which category is larger), and reasoning (explain a trend).
Dataset -> Screen -> Propose -> Synthesize -> Render -> Validate
  (UCI)      |         |           |            |          |
             v         v           v            v          v
          [filter]  [suggest]   [code]      [image]   [check image]
                                                           |
                                                      fail |
                                                           v
                                                      [refine code]
                                                           |
                                                      pass |
                                                           v
                                              Describe + Generate QA
                                                           |
                                                           v
                                              [chart + code + context + QA]
Think of this as a pottery studio workflow. The dataset is raw clay—you first inspect it for cracks (screening). You sketch what pot to make (proposal). You throw the pot on the wheel (code synthesis). You fire it in the kiln (rendering). Crucially, you then examine the fired pot for warping, glaze runs, or structural flaws (validation). If it’s defective, you don’t just shrug—you adjust your technique and fire a new piece (refinement loop). Only after the pot passes inspection do you write its description card and prepare questions for gallery visitors (description and QA generation). The key insight: you can’t judge a pot from the clay or the sketch alone—you must see the fired result. Similarly, you can’t judge a chart from data or code alone—you must validate the rendered image.
Key Concepts
-
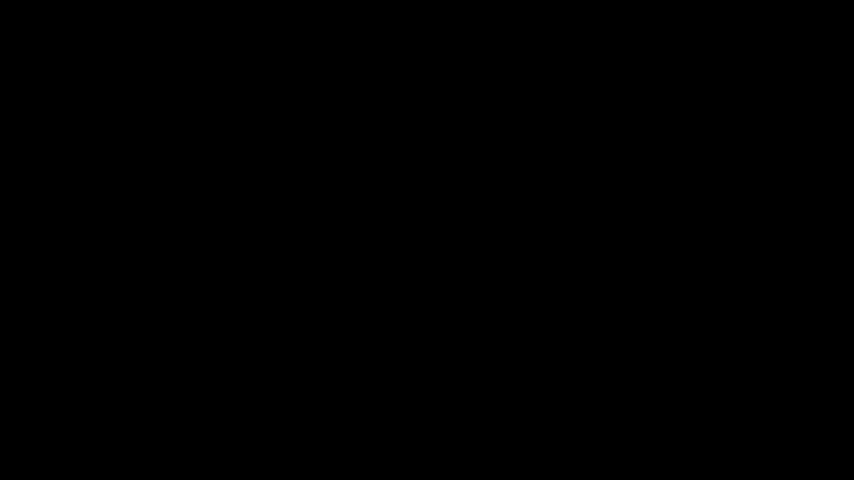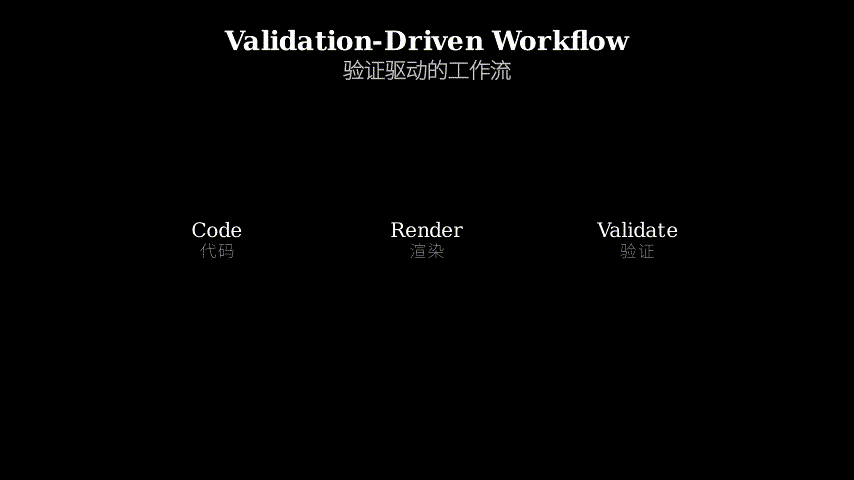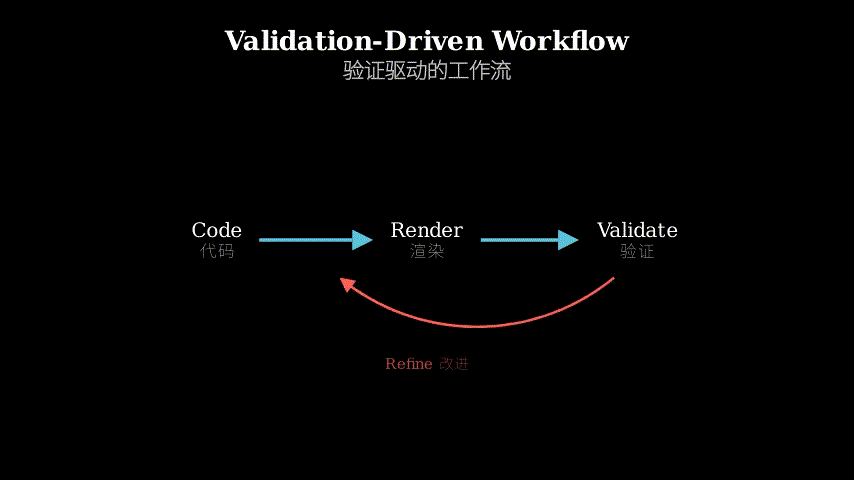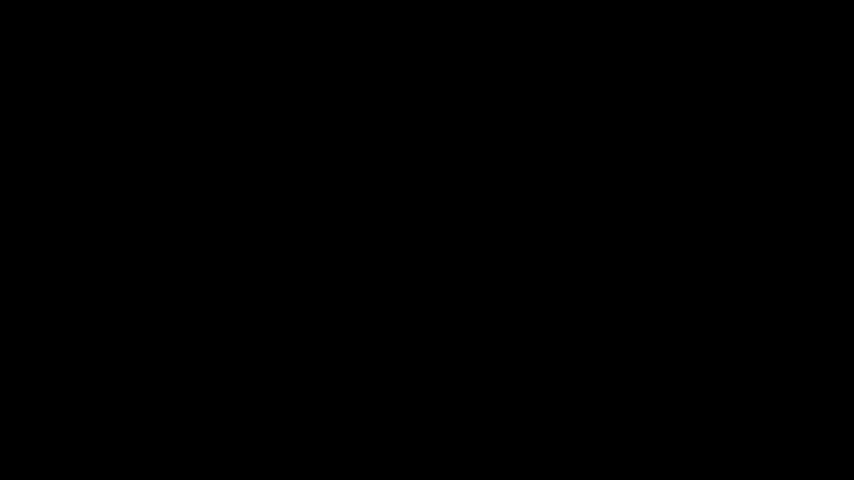
Validation-driven refinement: Most code generation systems stop after producing syntactically correct code. This workflow adds a post-rendering validation step that checks whether the output image is actually usable—are axis labels readable? Does the legend fit? Is the chart type semantically appropriate for the data? If validation fails, the system feeds the rendered image and error description back to the LLM, which revises the code. This creates a feedback loop grounded in the actual visual artifact, not just abstract code correctness. Concrete example: an LLM generates a bar chart with 50 categories, producing illegible x-axis labels. Validation detects “overlapping labels,” prompts the LLM to switch to a horizontal bar chart or reduce categories, re-renders, and checks again. Without this loop, the dataset would include a broken chart.
-
Artifact alignment: Existing chart datasets often provide images without executable code, or code without the original data context, or questions without knowing which dataset they came from. This workflow retains every intermediate artifact—the source dataset, the proposal rationale, the code (including failed attempts), the rendered image, the validation log, the description, and the QA pairs—all linked together. This alignment enables diagnostic studies: if an MLLM fails on a question, you can trace back to the data distribution, the chart design choice, and the code that produced it. It’s the difference between a museum displaying a painting with no provenance versus one that includes the artist’s sketches, correspondence, and restoration notes.
Framework Shift
Before (mainstream approach):        After (this paper):

  Data + Prompt                        Data
      |                                  |
      v                                  v
  LLM (one-shot)                     [Screen] -> [Propose]
      |                                  |           |
      v                                  v           v
  Code (hope it works)               [Synthesize] [Rationale]
      |                                  |
      v                                  v
  Image (maybe broken)               [Render]
                                         |
                                         v
                                     [Validate] <--+
                                         |         |
                                    pass | fail ---+
                                         v
                                  [Describe + QA]
                                         |
                                         v
                                  Aligned artifacts
                                  (data+code+image+QA)
From black-box generation to inspectable pipeline, the core shift is treating the rendered image as a first-class signal for refinement, not just a final output.
Expert Assessment
Problem choice: Real gap. Chart generation has been studied, but the lack of validation against rendered output is a genuine oversight—many visualization failures are invisible until you see the image. The problem sits at the intersection of code generation and multimodal reasoning, both active areas, so the timing is right.
Method maturity: Mostly engineering, not algorithmic novelty. The workflow is a sensible decomposition of the task, but each stage uses standard LLM prompting. The validation step is the clever bit—checking rendered output and feeding errors back—but it’s not a deep technical innovation, more a “why didn’t we do this before?” insight. No simpler approach is being overlooked; the method is appropriately scoped.
Experimental integrity: Baselines are fair—16 MLLMs tested on the generated QA pairs, showing clear performance gaps between question types (syntax nearly saturated, reasoning still hard). The dataset construction is transparent, with failure rates reported at each stage. One concern: the validation criteria are LLM-based, so there’s circularity (LLM validates LLM output). Human evaluation on a sample would strengthen claims. Numbers hold up, but the dataset’s utility depends on whether others adopt it.
Writing quality: The paper is clear and well-structured. The workflow description is thorough, perhaps overly detailed in places—Section 3 could be tightened. The evaluation section (Section 4) is solid but doesn’t deeply probe why certain MLLMs fail on specific question types. A failure analysis with examples would elevate the diagnostic value.
Verdict: weak accept — Solid engineering contribution with practical utility, but limited algorithmic novelty; the dataset and workflow will be useful for the community, though the validation loop is more “obvious in hindsight” than groundbreaking.
Takeaways
Practitioners building LLM-based generation systems can steal the validation-driven refinement pattern: don’t stop at code generation—render the output, check it against domain-specific criteria, and loop back if it fails. This applies beyond charts: generating LaTeX documents (render to PDF, check formatting), SQL queries (execute, validate result schema), or UI layouts (render, check accessibility). The key is identifying what can only be verified in the final artifact, not the intermediate representation.
The artifact alignment principle is also transferable: if you’re building a dataset for evaluation, retain the full provenance chain (input, intermediate steps, output, metadata). This makes the dataset debuggable and enables root-cause analysis when models fail, rather than just reporting aggregate accuracy.
论文: 2605.00800 作者: Pavlin G. Poličar, Andraž Pevcin, Blaž Zupan 分类: cs.LG
缺口
现有的图表生成方法把问题当作”提示词到代码”的翻译:给 LLM 喂表格数据,拿回绘图代码,祈祷能用。
这种做法失效是因为很多可视化错误——标签重叠、图例不可读、图表类型语义错误——只有渲染之后才能看出来。
现有的图表数据集加剧了这个问题,它们提供孤立的制品:代码没有上下文,图像没有可执行源码,或者问题没有对齐的数据来源。
该领域有图表生成系统,也有图表问答基准,但没有一个集成管线把图表创建当作可检查、可改进的过程,让每个制品(代码、图像、描述、问题)都能追溯到源数据。
问题:LLM 生成代码 -> 渲染暴露失败
                     (文字重叠、图表类型错误)
                              |
                              v
缺口:渲染输出没有反馈回生成环节
     没有 [数据+代码+图像+上下文+问答] 对齐的数据集
                              |
                              v
方法:多阶段工作流,渲染后验证
     保留每个阶段的所有制品
                              |
                              v
证据:74 个数据集生成 1,500 张图表,24 种图表类型
     MLLM 在值提取上比语法识别更吃力(诊断性)
                              |
                              v
结论:验证驱动的生成产出更高质量、完全对齐的
     图表数据集,用于多模态推理研究
增量
一句话:这篇论文之前,图表生成是黑盒的提示词到代码步骤,无法捕捉渲染失败;之后,它变成多阶段可检查工作流,渲染图像的验证驱动迭代改进。
核心机制
工作流把图表生成分解为七个顺序阶段。
第一,数据集筛选过滤表格数据的适用性(足够的行数、数值列、缺失值不过多)。
第二,图表提议用 LLM 建议适合数据结构和潜在分析问题的图表类型。
第三,代码合成生成可执行的绘图代码。
第四,渲染执行代码产出实际图像。
第五,验证驱动的改进检查渲染输出是否符合标准,比如标签可读性、图例清晰度、语义正确性——如果验证失败,LLM 修订代码并重新渲染。
第六,描述生成为最终图表产出自然语言说明。
第七,问答生成创建基于图表的问答对,涵盖语法(图表类型)、值提取(读取特定数据点)、比较(哪个类别更大)、推理(解释趋势)。
数据集 -> 筛选 -> 提议 -> 合成 -> 渲染 -> 验证
 (UCI)     |       |       |       |       |
           v       v       v       v       v
       [过滤]  [建议]  [代码]  [图像]  [检查图像]
                                            |
                                       失败 |
                                            v
                                       [改进代码]
                                            |
                                       通过 |
                                            v
                                   描述 + 生成问答
                                            |
                                            v
                                   [图表+代码+上下文+问答]
把这个想象成陶艺工作室的流程。
数据集是生泥——你先检查有没有裂纹(筛选)。
你画草图决定做什么壶(提议)。
你在转盘上拉坯(代码合成)。
你把壶放进窑里烧(渲染)。
关键来了,你检查烧好的壶有没有变形、釉面流挂、结构缺陷(验证)。
如果有瑕疵,你不会耸耸肩——你调整手法,烧新的一件(改进循环)。
只有壶通过检查后,你才写说明卡,准备给参观者的问题(描述和问答生成)。
核心洞见:你不能光看泥巴或草图就判断壶的好坏——你必须看烧出来的成品。
同样,你不能光看数据或代码就判断图表——你必须验证渲染出的图像。
关键概念
- 验证驱动的改进:大多数代码生成系统在产出语法正确的代码后就停了。
这个工作流加了一个渲染后验证步骤,检查输出图像是否真的能用——坐标轴标签可读吗?图例放得下吗?图表类型对数据语义合适吗?如果验证失败,系统把渲染图像和错误描述反馈给 LLM,LLM 修订代码。
这创建了一个基于实际视觉制品的反馈循环,而不只是抽象的代码正确性。
具体例子:LLM 生成一个有 50 个类别的柱状图,x 轴标签挤成一团看不清。
验证检测到”标签重叠”,提示 LLM 改成横向柱状图或减少类别,重新渲染,再检查一次。
没有这个循环,数据集里就会有一张坏图。
- 制品对齐:现有图表数据集常常提供图像但没有可执行代码,或者有代码但没有原始数据上下文,或者有问题但不知道来自哪个数据集。
这个工作流保留每个中间制品——源数据集、提议理由、代码(包括失败尝试)、渲染图像、验证日志、描述、问答对——全部关联在一起。
这种对齐让诊断研究成为可能:如果 MLLM 在某个问题上失败,你能追溯到数据分布、图表设计选择、产出它的代码。
这就像博物馆展示一幅画,一种是没有来源信息,另一种是附带艺术家的草图、通信记录、修复笔记。
框架转变
之前(主流方法):                之后(本文方法):

  数据 + 提示词                      数据
      |                                |
      v                                v
  LLM(一次性)                    [筛选] -> [提议]
      |                                |          |
      v                                v          v
  代码(祈祷能用)                 [合成]    [理由]
      |                                |
      v                                v
  图像(可能坏了)                 [渲染]
                                       |
                                       v
                                   [验证] <--+
                                       |      |
                                  通过 | 失败-+
                                       v
                                [描述 + 问答]
                                       |
                                       v
                                  对齐的制品
                              (数据+代码+图像+问答)
从黑盒生成到可检查管线,核心转变是把渲染图像当作改进的一等信号,而不只是最终输出。
专家评审
选题眼光:真缺口。
图表生成已经有人研究,但缺乏对渲染输出的验证是真正的疏漏——很多可视化失败在看到图像之前是隐形的。
问题处于代码生成和多模态推理的交叉点,两者都是活跃领域,所以时机合适。
方法成熟度:主要是工程,不是算法创新。
工作流是任务的合理分解,但每个阶段用的是标准 LLM 提示。
验证步骤是巧妙之处——检查渲染输出并反馈错误——但不是深层技术创新,更像是”我们怎么没早想到”的洞见。
没有被忽略的更简单方法;方法的范围恰当。
实验诚意:基线公平——16 个 MLLM 在生成的问答对上测试,显示问题类型之间的明显性能差距(语法几乎饱和,推理仍然困难)。
数据集构建透明,报告了每个阶段的失败率。
一个担忧:验证标准基于 LLM,所以有循环性(LLM 验证 LLM 输出)。
在样本上做人工评估会加强论证。
数字经得起推敲,但数据集的效用取决于其他人是否采用。
写作功力:论文清晰、结构良好。
工作流描述详尽,有些地方可能过于细致——第 3 节可以精简。
评估部分(第 4 节)扎实,但没有深入探究为什么某些 MLLM 在特定问题类型上失败。
带例子的失败分析会提升诊断价值。
判决:弱接收 — 扎实的工程贡献,有实用价值,但算法新颖性有限;数据集和工作流对社区有用,但验证循环更像是”事后看来显而易见”而非突破性。
要点总结
构建基于 LLM 的生成系统的实践者可以偷走验证驱动改进模式:不要止步于代码生成——渲染输出,根据领域特定标准检查,失败就循环回去。
这适用于图表之外:生成 LaTeX 文档(渲染成 PDF,检查格式)、SQL 查询(执行,验证结果模式)、或 UI 布局(渲染,检查无障碍性)。
关键是识别什么只能在最终制品中验证,而不是中间表示。
制品对齐原则也可迁移:如果你在构建评估数据集,保留完整的来源链(输入、中间步骤、输出、元数据)。
这让数据集可调试,当模型失败时能做根因分析,而不只是报告总体准确率。