Paper: 2604.11778 Authors: Junlin Liu, Shengnan An, Shuang Zhou, Dan Ma, Shixiong Luo, Ying Xie, Yuan Zhang, Wenling Yuan, Yifan Zhou, Xiaoyu Li Categories: cs.CL, cs.AI
The Gap
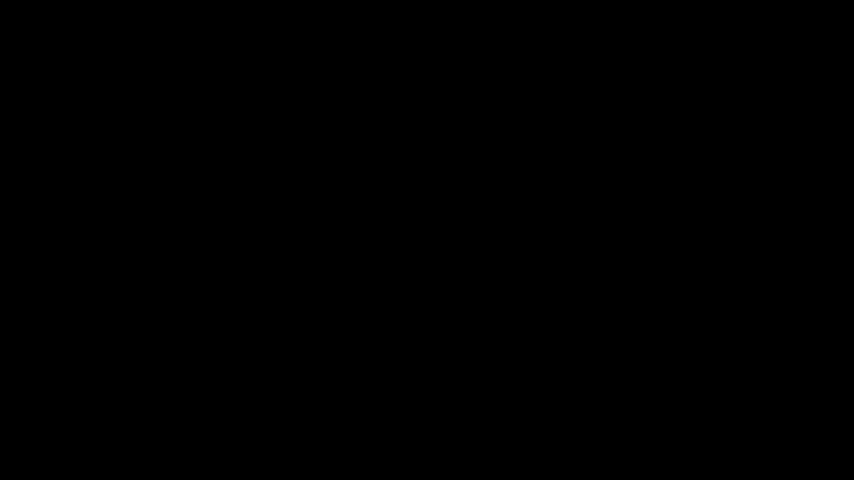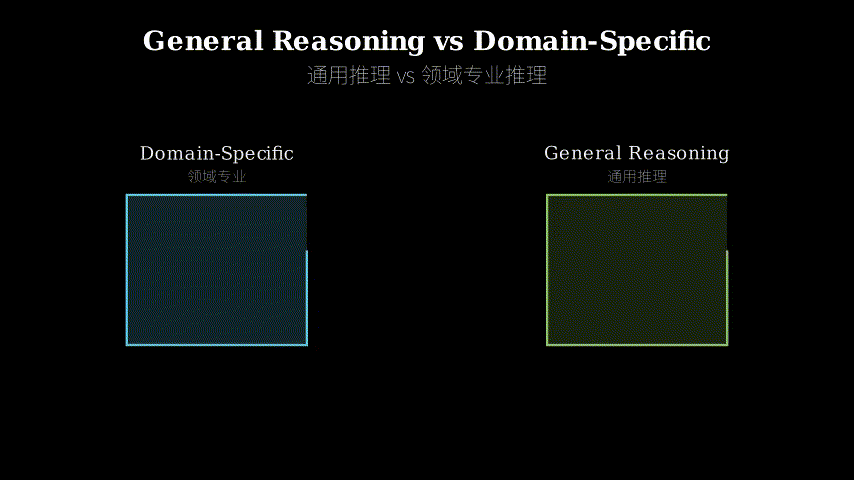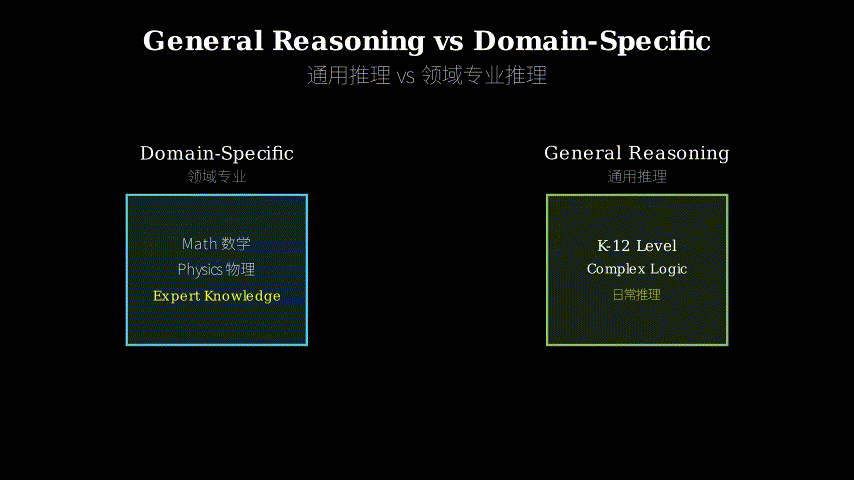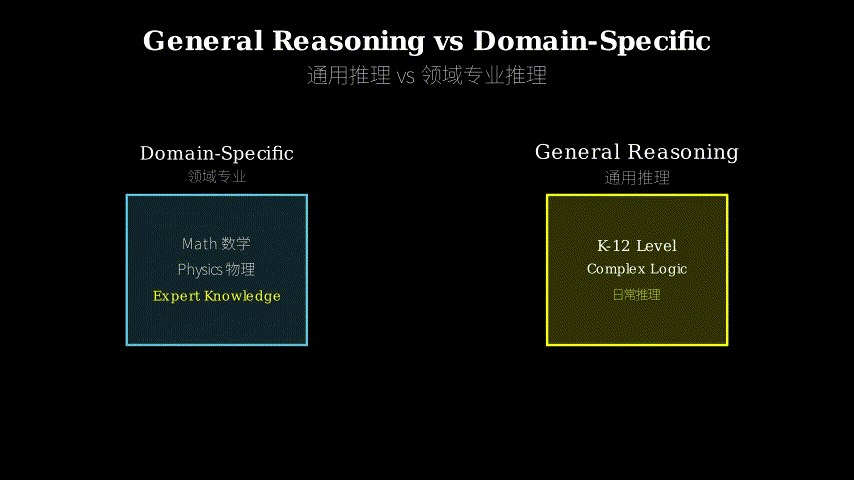
Existing LLM benchmarks like GSM8K (math) and GPQA (physics) show near-perfect performance from top models—GPT-4 hits 95%+ on these specialized tasks. But here’s the puzzle: these same models struggle with everyday reasoning that requires no expert knowledge. Prior work assumed strong domain-specific reasoning would transfer to general contexts. It doesn’t.
The problem: we’ve been measuring reasoning ability through the lens of specialized domains, where success might come from memorized patterns rather than genuine reasoning flexibility. No benchmark explicitly decouples reasoning difficulty from domain expertise.
Problem: LLMs ace specialized benchmarks but fail real-world tasks
                    |
                    v
Assumption: Domain reasoning =/= general reasoning
            (expertise masks reasoning brittleness)
                    |
                    v
Method: General365 - K-12 knowledge only, high reasoning complexity
        (365 seed + 1095 variants across 8 categories)
                    |
                    v
Evidence: Top model 62.8% vs 95%+ on domain benchmarks
          (26 models tested, consistent gap)
                    |
                    v
Conclusion: Current LLM reasoning is domain-dependent,
            not genuinely general-purpose
The Increment
One sentence: Before this paper, we thought LLMs had strong reasoning because they solved hard math problems; after, we know they’re pattern-matching specialists who struggle when expertise can’t compensate for reasoning gaps.
Core Mechanism
General365 constructs problems where reasoning complexity is high but required knowledge is deliberately constrained to K-12 level. The benchmark has three layers: 365 manually crafted seed problems spanning 8 categories (logic puzzles, spatial reasoning, constraint satisfaction, etc.), each seed spawns 2 variants with modified parameters, and problems are designed with nested logical branches, complex constraints, and semantic interference.
The evaluation pipeline is straightforward: problems are presented in natural language, models generate free-form answers, and responses are judged by both exact match and LLM-as-judge (GPT-4) for semantic correctness. The key innovation isn’t in evaluation mechanics but in problem design—each task requires multi-step reasoning chains where you can’t shortcut through memorized domain patterns.
Think of General365 as a driving test for reasoning. Domain-specific benchmarks are like testing someone on a closed track where they’ve practiced the exact route 1000 times—they might drive perfectly but you don’t know if they can handle real roads. General365 is the actual driving test: familiar traffic rules (K-12 knowledge), but novel situations requiring genuine decision-making. The test has three components: the route (seed problems), weather variations (parameter variants), and unexpected obstacles (nested constraints, semantic interference). You pass only if you can reason through unfamiliar combinations of familiar elements. A model that memorized “turn left at the oak tree” fails when the tree is replaced with a mailbox—same reasoning required, different surface features.
Key Concepts
-
Reasoning vs Knowledge Decoupling: Most benchmarks conflate these—solving a calculus problem requires both calculus knowledge AND reasoning ability. You can’t tell which one failed when the model gets it wrong. General365 fixes this by restricting knowledge to what a 12-year-old knows (basic arithmetic, simple geometry, common sense), then cranking up reasoning complexity. It’s like testing someone’s chess strategy using only pawns and kings—limited pieces, unlimited strategic depth. If they fail, it’s not because they don’t know how the pieces move.
-
Semantic Interference: This is when surface-level language patterns mislead reasoning. Example: “All birds can fly. Penguins are birds. Can penguins fly?” The linguistic pattern suggests “yes” but reasoning says “no” (the premise is flawed). General365 deliberately includes problems where naive pattern-matching produces wrong answers. It’s the reasoning equivalent of optical illusions—your first instinct is wrong, you need deliberate analysis to get it right.
-
Nested Logical Branches: Real-world reasoning rarely follows a single chain—you evaluate multiple conditions simultaneously, backtrack when constraints conflict, and maintain state across reasoning steps. A simple example: “If Alice is taller than Bob, and Bob is taller than Carol unless Carol wears heels, and today is Tuesday when Carol always wears heels, who is tallest?” You can’t solve this linearly; you need to branch, evaluate conditionals, and synthesize. Domain benchmarks often allow linear reasoning paths; General365 forces branching.
Framework Shift
Before (domain benchmarks):          After (General365):

Expert Knowledge                     K-12 Knowledge
      +                                    +
Simple Reasoning                     Complex Reasoning
      ||                                   ||
      vv                                   vv
  [Problem]                            [Problem]
      ||                                   ||
      vv                                   vv
  High Score                           Low Score
      ||                                   ||
      vv                                   vv
"Model reasons well"                 "Model pattern-matches"

Difficulty source: Knowledge         Difficulty source: Reasoning
Success metric: Domain accuracy      Success metric: Transfer ability
One sentence: From testing reasoning through expert domains (where knowledge and reasoning are entangled) to isolating reasoning by constraining knowledge (revealing that current LLMs reason weakly but memorize strongly).
Expert Assessment
Problem choice: This is a real gap, not manufactured. The field has been celebrating 95%+ scores on GSM8K while ignoring that these models fail at planning a dinner party with dietary constraints. The timing is perfect—we’re deploying LLMs for general-purpose tasks but measuring them on specialist exams. The gap sits at a critical juncture: between research benchmarks and real-world deployment.
Method maturity: Elegant in its simplicity. The core insight—decouple knowledge from reasoning—is obvious in hindsight but nobody did it systematically. The execution is solid: 365 seeds with 2 variants each provides decent coverage without being unwieldy. The 8 categories span different reasoning types (spatial, logical, constraint-based). One weakness: “K-12 knowledge” is fuzzy—what counts as common sense varies by culture and education system. They don’t rigorously define this boundary, which could lead to disputes about whether a problem is “fair.”
Experimental integrity: Testing 26 models is thorough. The 62.8% top score (vs 95%+ on domain benchmarks) is the headline finding and it’s stark enough to be believable. However, I’m skeptical of the LLM-as-judge evaluation—using GPT-4 to judge GPT-4’s answers creates circularity. They do include exact match as a sanity check, but the paper would be stronger with human evaluation on a subset. The variant problems (changing parameters) are clever for testing robustness, but 2 variants per seed feels thin—you could get lucky with parameter choices.
Writing quality: The paper is clear but conservative. The introduction spends too much time motivating why general reasoning matters (we get it). The problem categorization section is dry—they list 8 categories with brief descriptions but don’t explain the taxonomy’s design principles. The results section is where they should have dug deeper: why do models fail? What error patterns emerge? They give aggregate numbers but sparse failure analysis. Rewriting Section 4 (Results) with detailed error taxonomy and case studies would elevate this from “interesting benchmark” to “diagnostic tool.”
Verdict: Weak accept — The benchmark addresses a real gap and the results are eye-opening, but the paper feels like it stops at “look, models fail” without deeply investigating why or how to fix it.
Takeaways
For benchmark designers: The decoupling strategy is generalizable—pick any capability you want to measure, then systematically remove confounding factors. Want to test creativity? Constrain the domain to familiar concepts. Want to test robustness? Keep the task fixed, vary surface features.
For model developers: If your model scores 95% on domain benchmarks but 60% on General365, you’ve built a specialist, not a generalist. The gap suggests current training overindexes on pattern memorization. Practical fix: augment training data with reasoning chains that require branching logic and constraint satisfaction, not just domain knowledge application.
For practitioners: Don’t trust domain benchmark scores as proxies for general capability. If you’re deploying an LLM for open-ended tasks (customer support, planning, analysis), test it on General365-style problems first. The 62.8% ceiling means even top models will fail 1 in 3 reasoning tasks that a human would find straightforward.
Steal this: The variant generation strategy—take a seed problem, change parameters while preserving reasoning structure. This is cheap to implement and immediately reveals whether your model learned the reasoning pattern or memorized the specific instance.
论文: 2604.11778 作者: Junlin Liu, Shengnan An, Shuang Zhou, Dan Ma, Shixiong Luo, Ying Xie, Yuan Zhang, Wenling Yuan, Yifan Zhou, Xiaoyu Li 分类: cs.CL, cs.AI
缺口
现有的大模型基准测试如 GSM8K(数学)和 GPQA(物理)显示顶级模型接近完美表现——GPT-4 在这些专业任务上达到 95%+。
但这里有个谜题:这些模型在不需要专业知识的日常推理上却表现挣扎。
先前研究假设强大的领域推理能力会迁移到通用场景。
事实并非如此。
问题在于:我们一直通过专业领域的视角测量推理能力,而在这些领域中,成功可能来自记忆的模式而非真正的推理灵活性。
没有基准测试明确地将推理难度与领域专业知识解耦。
问题:大模型在专业基准上满分,但在现实任务中失败
                    |
                    v
假设:领域推理 =/= 通用推理
     (专业知识掩盖了推理脆弱性)
                    |
                    v
方法:General365 - 仅需中小学知识,高推理复杂度
     (365个种子题 + 1095个变体,跨8个类别)
                    |
                    v
证据:顶级模型62.8% vs 领域基准95%+
     (测试26个模型,差距一致)
                    |
                    v
结论:当前大模型推理依赖领域,
     并非真正通用
增量
一句话: 这篇论文之前,我们以为大模型推理能力强是因为它们能解难题;之后,我们知道它们是模式匹配专家,当专业知识无法弥补推理缺陷时就会挣扎。
核心机制
General365 构建的问题推理复杂度高,但所需知识刻意限制在中小学水平。
基准测试有三层:365个人工设计的种子问题,跨越8个类别(逻辑谜题、空间推理、约束满足等),每个种子生成2个修改参数的变体,问题设计包含嵌套逻辑分支、复杂约束和语义干扰。
评估流程很直接:问题以自然语言呈现,模型生成自由形式答案,回答通过精确匹配和大模型评判(GPT-4)进行语义正确性判断。
关键创新不在评估机制,而在问题设计——每个任务需要多步推理链,你无法通过记忆的领域模式走捷径。
把 General365 想象成推理能力的驾照考试。
领域基准测试就像在封闭赛道上测试某人,他们在完全相同的路线上练习了1000次——他们可能开得完美,但你不知道他们能否应对真实道路。
General365 是真正的驾驶考试:熟悉的交通规则(中小学知识),但需要真正决策的新情况。
测试有三个组成部分:路线(种子问题)、天气变化(参数变体)、意外障碍(嵌套约束、语义干扰)。
只有当你能推理出熟悉元素的陌生组合时才能通过。
记住”在橡树处左转”的模型在树被换成邮箱时就失败了——需要相同推理,但表面特征不同。
关键概念
- 推理与知识解耦: 大多数基准测试混淆了这两者——解决微积分问题既需要微积分知识也需要推理能力。
当模型答错时,你无法判断是哪个失败了。
General365 通过将知识限制在12岁孩子知道的内容(基础算术、简单几何、常识)来解决这个问题,然后提高推理复杂度。
这就像用只有兵和王的棋子测试某人的国际象棋策略——棋子有限,战略深度无限。
如果他们失败了,不是因为不知道棋子怎么走。
- 语义干扰: 这是指表面语言模式误导推理。
例子:“所有鸟都会飞。
企鹅是鸟。
企鹅会飞吗?“语言模式暗示”会”,但推理说”不会”(前提有缺陷)。
General365 刻意包含朴素模式匹配会产生错误答案的问题。
这是推理的视错觉——你的第一直觉是错的,需要刻意分析才能得到正确答案。
- 嵌套逻辑分支: 现实世界的推理很少遵循单一链条——你同时评估多个条件,在约束冲突时回溯,并在推理步骤间维护状态。
简单例子:“如果 Alice 比 Bob 高,Bob 比 Carol 高除非 Carol 穿高跟鞋,今天是周二 Carol 总是穿高跟鞋,谁最高?“你无法线性解决这个问题;需要分支、评估条件并综合。
领域基准通常允许线性推理路径;General365 强制分支。
框架转变
之前(领域基准):                之后(General365):

专业知识                          中小学知识
   +                                  +
简单推理                          复杂推理
   ||                                 ||
   vv                                 vv
[问题]                            [问题]
   ||                                 ||
   vv                                 vv
高分                              低分
   ||                                 ||
   vv                                 vv
"模型推理好"                      "模型模式匹配"

难度来源:知识                    难度来源:推理
成功指标:领域准确率              成功指标:迁移能力
一句话: 从通过专业领域测试推理(知识和推理纠缠)到通过限制知识隔离推理(揭示当前大模型推理弱但记忆强)。
专家评审
选题眼光: 这是真实缺口,不是人造的。
该领域一直在庆祝 GSM8K 上的 95%+ 分数,却忽略了这些模型在规划有饮食限制的晚宴时会失败。
时机完美——我们正在为通用任务部署大模型,但用专家考试来衡量它们。
这个缺口处于关键节点:研究基准和现实部署之间。
方法成熟度: 简洁优雅。
核心洞察——将知识与推理解耦——事后看来显而易见,但没人系统地做过。
执行扎实:365个种子题各有2个变体,提供了不错的覆盖面且不笨重。
8个类别跨越不同推理类型(空间、逻辑、基于约束)。
一个弱点:“中小学知识”是模糊的——什么算常识因文化和教育系统而异。
他们没有严格定义这个边界,可能导致关于问题是否”公平”的争议。
实验诚意: 测试26个模型很彻底。
62.8%的最高分(vs 领域基准的95%+)是标题发现,差距足够明显可信。
然而,我对大模型评判的评估持怀疑态度——用 GPT-4 评判 GPT-4 的答案产生循环性。
他们确实包含精确匹配作为合理性检查,但如果在子集上有人工评估,论文会更强。
变体问题(改变参数)对测试鲁棒性很巧妙,但每个种子2个变体感觉单薄——参数选择可能碰巧合适。
写作功力: 论文清晰但保守。
引言花太多时间论证为什么通用推理重要(我们懂了)。
问题分类部分枯燥——他们列出8个类别并简要描述,但没解释分类法的设计原则。
结果部分是他们应该深挖的地方:为什么模型失败?出现什么错误模式?他们给出总体数字但错误分析稀疏。
用详细的错误分类和案例研究重写第4节(结果)会将这篇论文从”有趣的基准”提升到”诊断工具”。
判决: 弱接收 — 基准测试解决了真实缺口,结果令人大开眼界,但论文感觉停在”看,模型失败了”,没有深入调查为什么或如何修复。
要点总结
对基准设计者: 解耦策略可推广——选择任何你想测量的能力,然后系统地移除混淆因素。
想测试创造力?将领域限制在熟悉概念。
想测试鲁棒性?保持任务固定,改变表面特征。
对模型开发者: 如果你的模型在领域基准上得95%但在 General365 上得60%,你构建的是专家,不是通才。
差距表明当前训练过度索引模式记忆。
实用修复:用需要分支逻辑和约束满足的推理链增强训练数据,而不仅仅是领域知识应用。
对实践者: 不要相信领域基准分数能代表通用能力。
如果你为开放式任务(客户支持、规划、分析)部署大模型,先在 General365 风格问题上测试。
62.8%的上限意味着即使顶级模型也会在人类觉得简单的推理任务中失败三分之一。
可偷师: 变体生成策略——取一个种子问题,改变参数同时保留推理结构。
这实现起来成本低,立即揭示你的模型是学到了推理模式还是记住了特定实例。