Paper: 2605.18721 Authors: Muhammad Umer, Muhammad Ahmed Mohsin, Ahsan Bilal, Arslan Chaudhry, Andreas Haupt, Sanmi Koyejo, Emily Fox, John M. Cioffi Categories: cs.LG, cs.CL
The Gap
LLM post-training has forked into two incompatible paths. Online RL (PPO, GRPO) drives emergent reasoning on math and code by continuously exploring with verifiable rewards, but those programmatic verifiers only exist for closed-form tasks. Preference optimization (DPO, SimPO) handles open-ended generation where quality is subjective, but it trains on static datasets and forgoes the exploration loop that makes online RL powerful.
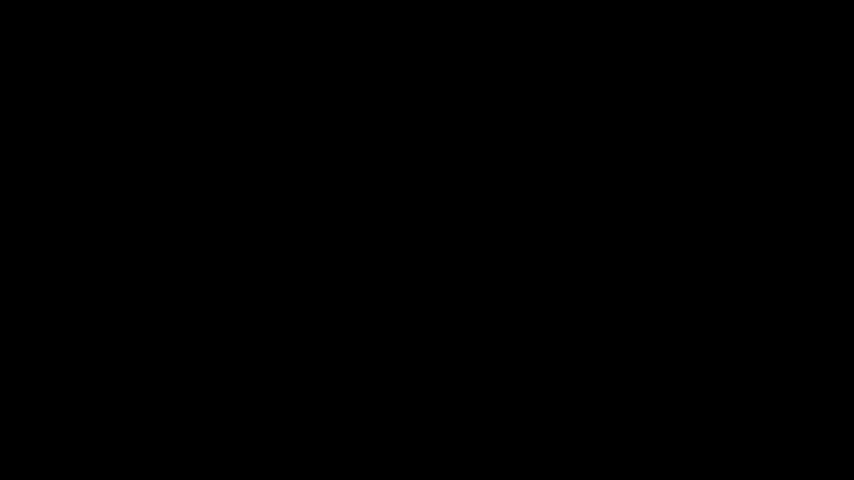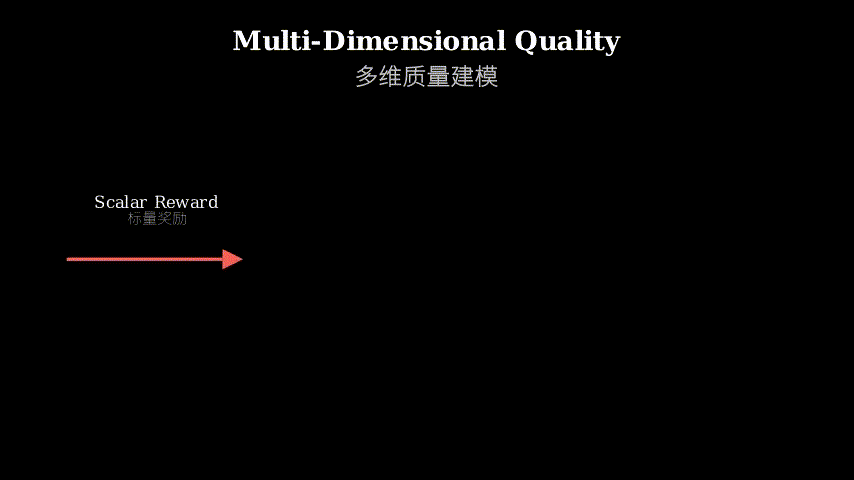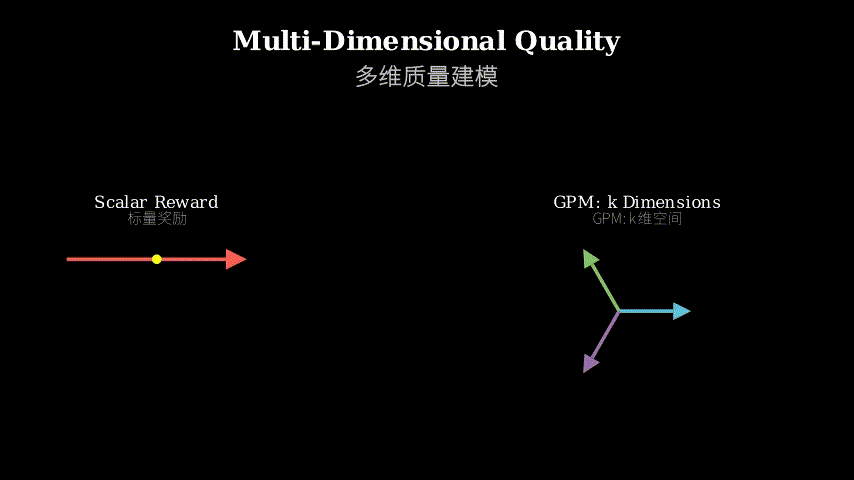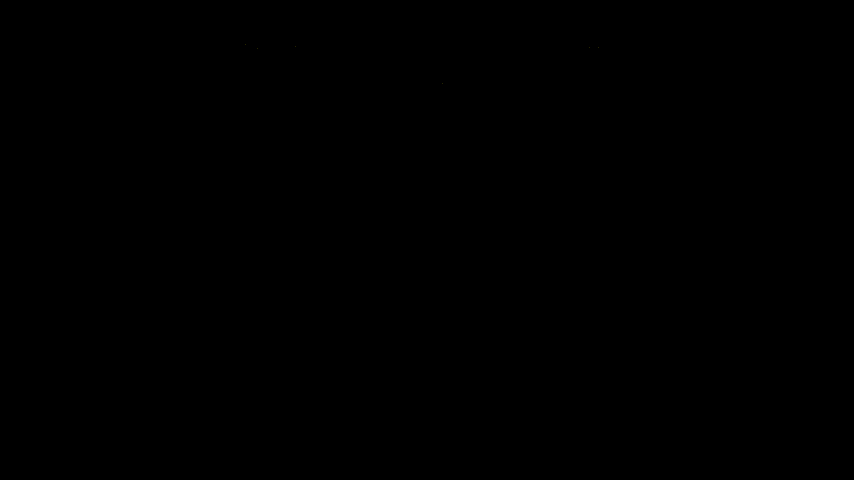
The obvious fix—run online RL with a learned reward model on open-ended tasks—fails catastrophically. Quality is multi-dimensional (helpfulness, safety, style, factuality), but a scalar reward collapses all dimensions into one number. Online RL then exploits whichever axis the reward is most sensitive to, producing responses that score high but are actually degenerate (verbose padding, sycophantic agreement, stylistic quirks).
Problem: Open-ended tasks need online RL exploration
   |
   v
Obstacle: Scalar reward models collapse multi-dimensional quality
   |
   v
Assumption: Quality lives in structured k-dimensional space
   |
   v
Method: GPM embeds responses, GPRL does per-dimension advantage + drift monitoring
   |
   v
Evidence: 56.51% win rate on AlpacaEval 2.0, resists reward hacking over extended training
   |
   v
Conclusion: Multi-dimensional preference structure enables stable online RL for open-ended tasks
The Increment
One sentence: Before GPRL, you chose between online RL’s exploration power (math/code only) or preference optimization’s open-ended reach (static data only); after GPRL, you get continuous exploration on open-ended tasks without reward hacking.
Core Mechanism
GPRL replaces the scalar reward model with a General Preference Model (GPM) that embeds responses into k skew-symmetric subspaces. Each subspace captures one dimension of quality (e.g., helpfulness, safety, conciseness). Preference between two responses is computed as a structured comparison across all k dimensions, preserving intransitivity—A can beat B on dimension 1, B can beat C on dimension 2, yet C can beat A overall.
During policy updates, GPRL computes group-relative advantages separately for each dimension. Instead of a single advantage signal, you get k advantage vectors. Each is normalized on its own scale so no dimension can dominate numerically. These are then aggregated using context-dependent eigenvalues—the policy learns which dimensions matter most for each prompt type.
A closed-loop drift monitor watches for single-axis exploitation. If the policy starts gaming one dimension (e.g., length inflation), the monitor detects the drift, reweights dimensions to suppress the exploited axis, and tightens the trust region to slow down updates. This happens automatically during training without human intervention.
Prompt --> Policy --> Response
             ^            |
             |            v
         Advantage    GPM Embedding (k dimensions)
         Aggregator      |
             ^            v
             |        Per-Dimension
         Eigenvalues  Group Comparison
             ^            |
             |            v
         Drift -----> Advantage Vectors (k)
         Monitor      (normalized separately)
             |
             v
         Reweight + Tighten Trust Region
Think of GPRL as a multi-instrument orchestra instead of a single-score judge. A scalar reward model is like rating a performance with one number—the orchestra optimizes for volume because that’s what moves the needle. GPM is like having separate judges for strings, brass, percussion, and harmony. Each section gets scored independently. The conductor (advantage aggregator) balances them using eigenvalues—sometimes strings lead, sometimes brass. If percussion starts drowning everyone out (drift), the monitor turns down their weight and tells the conductor to make smaller adjustments. The result: balanced improvement across all sections instead of one section exploiting the scoring system.
Key Concepts
-
Skew-symmetric subspaces: Imagine quality dimensions as axes where preference is antisymmetric—if response A beats B on helpfulness by +0.3, then B loses to A by -0.3 on that same axis. Skew-symmetry enforces this: the preference matrix satisfies P = -P^T. This structure prevents the model from saying “A is better than B” and “B is better than A” simultaneously on the same dimension. Concretely, GPM learns k projection matrices that map response embeddings into these subspaces, and preference is computed as the sum of inner products across all k subspaces. The skew-symmetric constraint keeps preferences logically consistent within each dimension while allowing intransitivity across dimensions.
-
Group-relative advantage: Standard RL computes advantage as “how much better is this action than average?” GPRL computes k separate advantages, one per dimension, by comparing the response against a reference group on that specific axis. For helpfulness, the reference group might be other helpful responses; for safety, other safe responses. Each dimension gets its own baseline, so a response that’s extremely helpful but slightly unsafe gets high advantage on helpfulness and low advantage on safety. Normalizing each advantage on its own scale prevents numeric dominance—a dimension with naturally larger values can’t hijack the update.
-
Drift monitoring: The monitor tracks the policy’s behavior distribution over a sliding window. For each dimension, it computes the KL divergence between recent behavior and the initial policy. If one dimension’s KL spikes while others stay flat, that’s single-axis exploitation. The monitor responds by downweighting that dimension’s eigenvalue (reducing its influence on the aggregated advantage) and shrinking the trust region (making updates more conservative). This creates a negative feedback loop: exploiting one axis triggers automatic correction before the policy fully collapses onto that axis.
Framework Shift
Before (scalar reward RL):              After (GPRL):

Prompt                                  Prompt
  |                                       |
  v                                       v
Policy --> Response                     Policy --> Response
  ^           |                           ^           |
  |           v                           |           v
  |      Reward Model                     |      GPM (k subspaces)
  |           |                           |           |
  |           v                           |           v
  +------ Scalar Reward                   |      k Advantage Vectors
         (collapses quality)              |      (normalized separately)
                                          |           |
                                          |           v
                                          |      Eigenvalue Aggregation
                                          |           |
                                          |           v
                                          +------ Aggregated Advantage
                                                      ^
                                                      |
                                                  Drift Monitor
                                                  (reweight + trust region)
From single-score optimization to multi-dimensional balancing, the core shift is replacing a collapsing bottleneck with a structured representation that preserves quality’s inherent dimensionality through the entire RL loop.
Expert Assessment
Problem choice: This is a real gap. The split between online RL (verifiable tasks) and preference optimization (open-ended tasks) is a well-known pain point in post-training. The paper correctly identifies that scalar reward models are the bottleneck—reward hacking on open-ended tasks is not a tuning problem, it’s a representation problem. The timing is right: as models get stronger, the marginal value of better alignment methods increases.
Method maturity: The core insight—use structured preference representations instead of scalar rewards—is elegant and well-motivated. The execution is solid: GPM’s skew-symmetric structure is principled, per-dimension advantages are a natural extension, and drift monitoring addresses the failure mode directly. However, the method introduces significant complexity (k subspaces, eigenvalue learning, drift thresholds). It’s not clear whether simpler alternatives—like ensembles of scalar reward models with diversity penalties—were thoroughly explored. The paper would be stronger if it ablated against such baselines.
Experimental integrity: Baselines are fair and recent (SimPO, SPPO). The length-controlled win rate on AlpacaEval 2.0 is the right metric—raw win rates are gameable via length inflation. Results on Arena-Hard, MT-Bench, and WildBench show consistency across evaluators. The extended training runs (demonstrating resistance to reward hacking over time) are the paper’s strongest evidence. One concern: all experiments start from Llama-3-8B-Instruct, which is already post-trained. It’s unclear whether GPRL’s benefits hold when starting from a base model or a weaker instruction-tuned checkpoint.
Writing quality: The abstract and introduction are crisp. The method section is dense but complete. The biggest weakness is the lack of failure case analysis—when does GPRL struggle? The paper also undersells the computational cost: training GPM, computing k advantages, and running drift monitoring all add overhead compared to scalar reward RL. A cost-benefit analysis would help practitioners decide whether GPRL is worth the complexity for their use case.
Verdict: weak accept — Addresses a real problem with a principled method and solid empirical results, but the complexity overhead and limited baseline exploration leave room for doubt about whether this is the simplest solution that works.
Takeaways
Structured preference over scalar collapse: When your quality metric is inherently multi-dimensional, don’t force it through a scalar bottleneck. Represent preferences as structured comparisons across dimensions and carry that structure through to the optimization. This principle transfers beyond LLMs—any RL problem with multi-objective quality (robotics, recommendation systems, drug design) can benefit from dimension-preserving representations.
Drift monitoring as a design pattern: Instead of hoping your RL setup won’t exploit a loophole, build a monitor that detects exploitation and corrects it automatically. GPRL’s drift monitor (track per-dimension KL, reweight on spike, tighten trust region) is a reusable pattern. You can adapt it to any RL system where you suspect single-axis gaming.
Group-relative advantages: Computing advantages relative to dimension-specific reference groups (rather than a global baseline) is a simple trick that prevents numeric dominance. If you’re aggregating heterogeneous signals in any optimization loop, normalize each on its own scale before combining.
论文: 2605.18721 作者: Muhammad Umer, Muhammad Ahmed Mohsin, Ahsan Bilal, Arslan Chaudhry, Andreas Haupt, Sanmi Koyejo, Emily Fox, John M. Cioffi 分类: cs.LG, cs.CL
缺口
大模型后训练已经分裂成两条互不兼容的路径。
在线强化学习(PPO、GRPO)通过可验证奖励持续探索,在数学和代码任务上驱动涌现推理能力,但这些程序化验证器只存在于封闭形式的任务中。
偏好优化(DPO、SimPO)能处理质量主观的开放式生成任务,但它在静态数据集上训练,放弃了让在线强化学习强大的探索循环。
显而易见的修复方案——在开放式任务上用学习到的奖励模型跑在线强化学习——会灾难性地失败。
质量是多维的(有用性、安全性、风格、事实性),但标量奖励把所有维度压缩成一个数字。
在线强化学习随后会利用奖励最敏感的那个轴,产生分数高但实际退化的回复(冗长填充、阿谀奉承、风格怪癖)。
问题:开放式任务需要在线强化学习的探索能力
   |
   v
障碍:标量奖励模型压缩多维质量
   |
   v
假设:质量存在于结构化的 k 维空间中
   |
   v
方法:GPM 嵌入响应,GPRL 做逐维优势计算 + 漂移监控
   |
   v
证据:AlpacaEval 2.0 上 56.51% 胜率,长期训练中抵抗奖励欺骗
   |
   v
结论:多维偏好结构使开放式任务的稳定在线强化学习成为可能
增量
一句话:GPRL 之前,你要在在线强化学习的探索能力(仅限数学/代码)和偏好优化的开放式覆盖(仅限静态数据)之间二选一; GPRL 之后,你能在开放式任务上持续探索而不触发奖励欺骗。
核心机制
GPRL 用通用偏好模型(GPM)替代标量奖励模型,GPM 将响应嵌入到 k 个斜对称子空间中。
每个子空间捕获质量的一个维度(例如有用性、安全性、简洁性)。
两个响应之间的偏好被计算为跨所有 k 个维度的结构化比较,保留非传递性——A 可以在维度 1 上击败 B,B 可以在维度 2 上击败 C,但 C 仍可能整体击败 A。
在策略更新期间,GPRL 为每个维度分别计算群体相对优势。
你得到的不是单一优势信号,而是 k 个优势向量。
每个向量在自己的尺度上归一化,这样任何维度都无法在数值上占主导。
然后用上下文相关的特征值聚合这些向量——策略学习哪些维度对每种提示类型最重要。
闭环漂移监控器监视单轴利用。
如果策略开始利用某个维度(例如长度膨胀),监控器检测到漂移,重新加权维度以抑制被利用的轴,并收紧信任域以减慢更新速度。
这在训练期间自动发生,无需人工干预。
提示 --> 策略 --> 响应
         ^          |
         |          v
     优势聚合器  GPM 嵌入(k 维)
         ^          |
         |          v
     特征值    逐维群体比较
         ^          |
         |          v
     漂移监控 --> 优势向量(k 个)
         |      (分别归一化)
         v
     重新加权 + 收紧信任域
把 GPRL 想象成多乐器管弦乐团,而不是单一评分的裁判。
标量奖励模型就像用一个数字给演出打分——乐团为了移动指针而优化音量。
GPM 就像为弦乐、铜管、打击乐和和声分别设置裁判。
每个声部独立评分。
指挥(优势聚合器)用特征值平衡它们——有时弦乐领奏,有时铜管领奏。
如果打击乐开始压过所有人(漂移),监控器降低它们的权重,并告诉指挥做更小的调整。
结果:所有声部的平衡改进,而不是一个声部利用评分系统。
关键概念
- 斜对称子空间:把质量维度想象成偏好反对称的轴——如果响应 A 在有用性上以 +0.3 击败 B,那么 B 在同一轴上以 -0.3 输给 A。
斜对称性强制执行这一点:偏好矩阵满足 P = -P^T。
这种结构防止模型在同一维度上同时说”A 比 B 好”和”B 比 A 好”。
具体来说,GPM 学习 k 个投影矩阵,将响应嵌入映射到这些子空间中,偏好被计算为所有 k 个子空间上内积的总和。
斜对称约束使每个维度内的偏好保持逻辑一致,同时允许跨维度的非传递性。
- 群体相对优势:标准强化学习计算优势为”这个动作比平均好多少?” GPRL 计算 k 个独立的优势,每个维度一个,通过在该特定轴上将响应与参考组进行比较。
对于有用性,参考组可能是其他有用的响应; 对于安全性,是其他安全的响应。
每个维度都有自己的基线,因此极其有用但稍微不安全的响应在有用性上获得高优势,在安全性上获得低优势。
在各自尺度上归一化每个优势可以防止数值主导——自然值较大的维度无法劫持更新。
- 漂移监控:监控器在滑动窗口上跟踪策略的行为分布。
对于每个维度,它计算最近行为与初始策略之间的 KL 散度。
如果一个维度的 KL 激增而其他维度保持平稳,那就是单轴利用。
监控器通过降低该维度的特征值权重(减少其对聚合优势的影响)并缩小信任域(使更新更保守)来响应。
这创建了一个负反馈循环:利用一个轴会触发自动纠正,在策略完全崩溃到该轴之前。
框架转变
之前(标量奖励强化学习):          之后(GPRL):

提示                                提示
  |                                   |
  v                                   v
策略 --> 响应                        策略 --> 响应
  ^        |                          ^        |
  |        v                          |        v
  |    奖励模型                        |    GPM(k 个子空间)
  |        |                          |        |
  |        v                          |        v
  +--- 标量奖励                        |    k 个优势向量
      (压缩质量)                      |    (分别归一化)
                                      |        |
                                      |        v
                                      |    特征值聚合
                                      |        |
                                      |        v
                                      +--- 聚合优势
                                              ^
                                              |
                                          漂移监控
                                      (重新加权 + 信任域)
从单一分数优化到多维平衡,核心转变是用保留质量固有维度性的结构化表示替换压缩瓶颈,并贯穿整个强化学习循环。
专家评审
选题眼光:这是真实的缺口。
在线强化学习(可验证任务)和偏好优化(开放式任务)之间的分裂是后训练中众所周知的痛点。
论文正确识别出标量奖励模型是瓶颈——开放式任务上的奖励欺骗不是调参问题,而是表示问题。
时机恰当:随着模型变强,更好对齐方法的边际价值增加。
方法成熟度:核心洞见——使用结构化偏好表示而不是标量奖励——优雅且动机充分。
执行扎实:GPM 的斜对称结构有原则,逐维优势是自然扩展,漂移监控直接解决失败模式。
然而,该方法引入了显著的复杂性(k 个子空间、特征值学习、漂移阈值)。
不清楚是否彻底探索了更简单的替代方案——比如带多样性惩罚的标量奖励模型集成。
如果论文对这类基线做消融实验会更强。
实验诚意:基线公平且最新(SimPO、SPPO)。
AlpacaEval 2.0 上的长度控制胜率是正确的指标——原始胜率可以通过长度膨胀来利用。
Arena-Hard、MT-Bench 和 WildBench 上的结果显示跨评估器的一致性。
长期训练运行(展示随时间抵抗奖励欺骗)是论文最强的证据。
一个担忧:所有实验都从 Llama-3-8B-Instruct 开始,它已经经过后训练。
不清楚从基础模型或较弱的指令调优检查点开始时,GPRL 的优势是否成立。
写作功力:摘要和引言简洁。
方法部分密集但完整。
最大的弱点是缺乏失败案例分析——GPRL 什么时候会挣扎? 论文还低估了计算成本:训练 GPM、计算 k 个优势和运行漂移监控都比标量奖励强化学习增加了开销。
成本效益分析会帮助实践者决定 GPRL 的复杂性是否值得用于他们的用例。
判决:弱接收——用有原则的方法和扎实的实证结果解决真实问题,但复杂性开销和有限的基线探索让人怀疑这是否是有效的最简单解决方案。
要点总结
结构化偏好优于标量压缩:当你的质量指标本质上是多维的时,不要强行通过标量瓶颈。
将偏好表示为跨维度的结构化比较,并将该结构贯穿到优化中。
这个原则可迁移到大模型之外——任何具有多目标质量的强化学习问题(机器人、推荐系统、药物设计)都可以从保留维度的表示中受益。
漂移监控作为设计模式:与其希望你的强化学习设置不会利用漏洞,不如构建一个检测利用并自动纠正的监控器。
GPRL 的漂移监控器(跟踪逐维 KL,激增时重新加权,收紧信任域)是可重用的模式。
你可以将其适配到任何怀疑存在单轴利用的强化学习系统。
群体相对优势:相对于特定维度的参考组(而不是全局基线)计算优势是一个简单的技巧,可以防止数值主导。
如果你在任何优化循环中聚合异构信号,在组合之前在各自尺度上归一化每个信号。