Paper: 2608.09921 Authors: Alban Puech, Matteo Mazzonelli, Tamara R. Govindasamy, Héctor Maeso-García, Thomas Tolhurst, Javad Bayazi, Ali Moeini, Naomi Simumba, Celia Cintas Categories: cs.AI
Note up front: I’m working from the abstract and the surrounding literature, not the full text. Where I describe internals below, I flag what is stated versus what I’m reconstructing.
The Gap
Neural power system solvers have been a busy corner of ML-for-science for about five years, and the literature is oddly shaped: lots of papers, almost no reusable artifacts.
Where prior work sits:
- Power flow (PF) learners — PowerFlowNet, physics-informed GNNs, unrolled Newton variants. These typically train one model per grid, or per grid family, and are evaluated on mean-squared error against a Newton-Raphson reference. MSE is a proxy; nobody dispatches a grid on MSE.
- OPF learners — DeepOPF and descendants, DC3-style constraint-completion, primal-dual learning. Fast, but feasibility is the perennial problem: a predicted operating point that violates line limits is not a solution, it’s a suggestion.
- State estimation (SE) — largely separate literature, mostly deep-unrolled weighted least squares (WLS) or robust-estimator surrogates.
- Production practice — DC approximations (DC-PF, DC-OPF), which are fast and linear but throw away voltage magnitudes and reactive power. For anything voltage-security-related, that’s the wrong tool.
So there are three structural gaps. First, task fragmentation: three model families for three problems that share the same physics and the same network. Second, no common substrate: no standard synthetic data pipeline, no shared grid representation, so cross-paper numbers are barely comparable. Third, the wrong success metric: MSE-against-solver instead of physical residuals, feasibility, and optimality gap.
GENCO’s bet is that all three collapse if you fix the representation.
  PROBLEM
  [ PF, OPF, SE solved by 3 separate model families ]
  [ no shared data pipeline; MSE-vs-solver metrics  ]
  [ production falls back to DC: no |V|, no Q       ]
        |
        v
  ASSUMPTION
  [ all three tasks = same grid graph + same AC equations ]
  [ they differ only in: which values are known,          ]
  [ which are unknown, and what objective is imposed      ]
        |
        v
  METHOD
  [ GENCO: geometric (graph) encoder over a shared        ]
  [ network representation + corrective iteration driven  ]
  [ by physics residuals; task selected by known/unknown  ]
  [ mask and objective term                               ]
  [ + GridFM Development Framework (data gen + training)  ]
  [ + released PF/OPF datasets, millions of scenarios     ]
        |
        v
  EVIDENCE
  [ PFDelta, OPFData benchmarks; Hydro-Quebec SCADA       ]
  [ PF:  ~30x vs Newton-Raphson, ~2x DC-PF runtime,       ]
  [      full AC state at DC-level P-balance residuals    ]
  [ OPF: ~85x vs IPOPT, better than DC-OPF on feasibility ]
  [ SE:  degrades gracefully where WLS fails to converge  ]
        |
        v
  CONCLUSION
  [ one solver + one framework lowers the entry barrier;  ]
  [ framed as a step toward "Grid Foundation Models"      ]
The Increment
One sentence: Before, you picked a neural solver per task and rebuilt the data pipeline yourself; after, there is one architecture that fills in whichever grid quantities are missing, plus the framework and datasets to reproduce and extend it.
Core Mechanism
The stated design has two load-bearing pieces: a shared network representation and a corrective loop (the C in GENCO). The grid becomes a heterogeneous graph — buses as nodes, branches as edges, generators and loads as attached features — and every quantity of interest (voltage magnitude, voltage angle, active and reactive injections, setpoints) lives on that graph as a per-node or per-edge slot. Crucially, each slot carries a companion flag: *known or to-be-determined. The topology of the graph is data, not architecture, which is what lets one trained model span grids of different sizes.
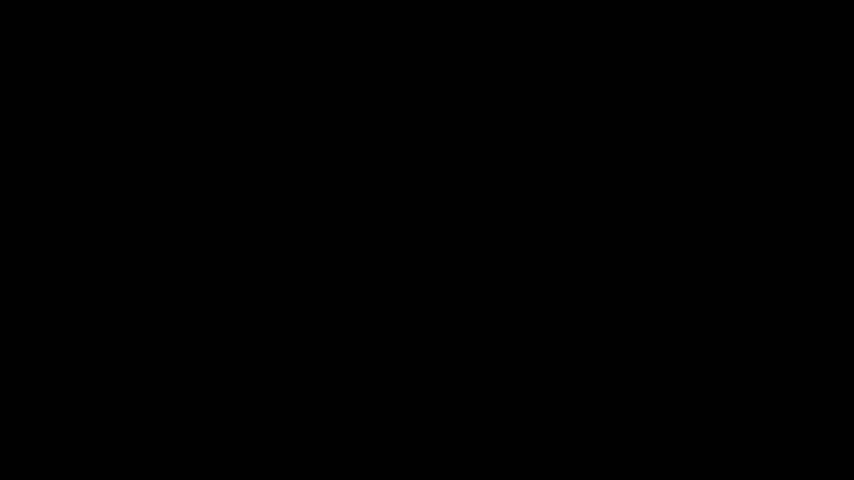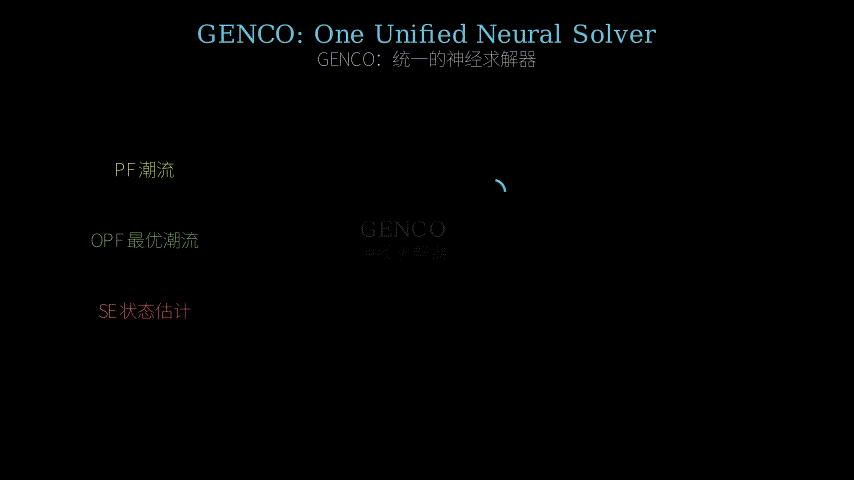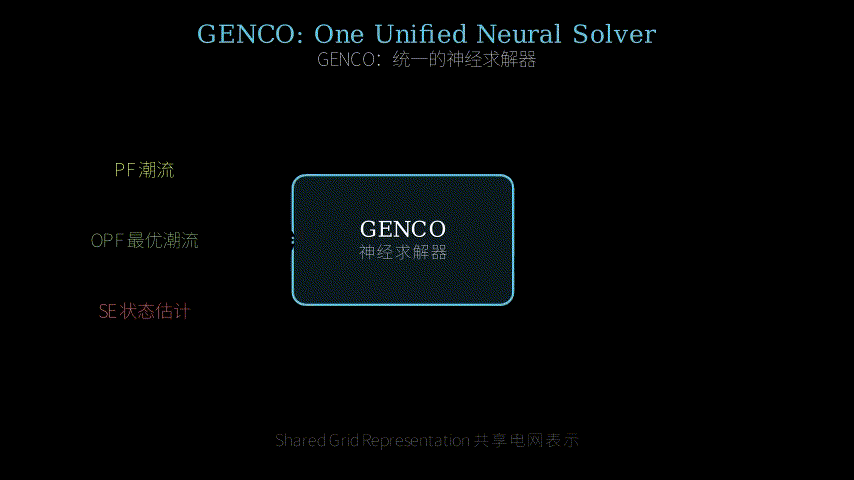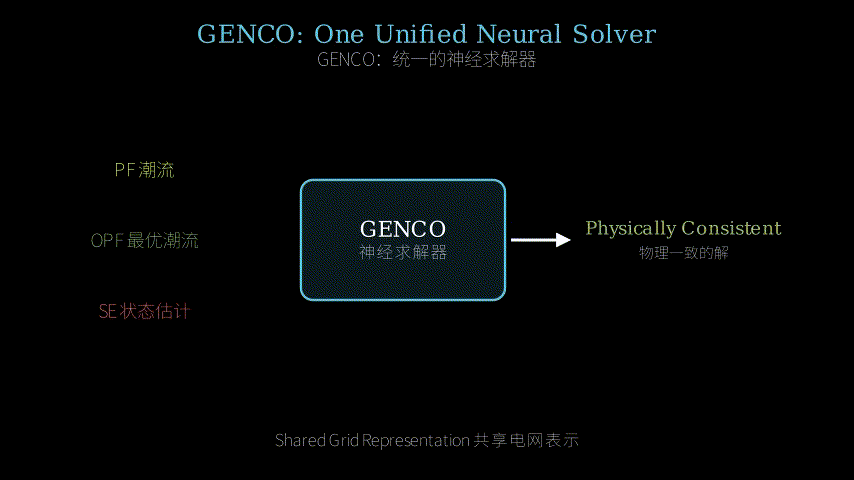
With that representation, the three tasks stop being three problems. PF: generator setpoints and loads are known, bus voltages are unknown. OPF: loads are known, setpoints are unknown, and a cost objective plus operating limits are imposed. SE: a noisy, partially redundant set of measurements is known, and the true state is unknown. Same graph, same AC equations, different pattern of filled and empty slots.
The “corrective optimizer” part is where this differs from plain regression. Rather than a single forward pass mapping inputs to outputs, the model appears to run an iterative refinement: produce a candidate state, evaluate the actual AC power-flow residuals of that candidate, feed those residuals back in as features, and emit a correction. That is a learned analogue of a Newton step — except the update direction is amortized across the training distribution instead of computed from a fresh Jacobian factorization. It explains both the physics story (residuals are measured, not hoped for) and the speed story (no repeated sparse linear solves), and it explains why the SE results are robust: an iterative corrector has no convergence criterion to fail, so it always hands back something. Whether that something is trustworthy is a separate question, and I’ll come back to it.
    grid case (any topology, any size)
            |
            v
  +---------------------------------------------+
  |  SHARED NETWORK REPRESENTATION              |
  |  nodes: buses  [ |V| th P Q ] + known-mask  |
  |  edges: lines  [ R X B ratio limits ]       |
  |  task tag: PF / OPF / SE                    |
  +---------------------------------------------+
            |
            v
  +---------------------------------------------+
  |  GEOMETRIC ENCODER (message passing)        |
  |  neighbors exchange state; permutation      |
  |  equivariant, so size is not baked in       |
  +---------------------------------------------+
            |
            v
      candidate state x_0
            |
   .--------+--------------------------.
   |        v                          |
   |  [ AC RESIDUAL CHECK ]            |  k corrective
   |  g(x) = P/Q mismatch, limits,     |  passes
   |         measurement misfit        |
   |        |                          |
   |        v                          |
   |  [ CORRECTOR: dx = f(x, g(x)) ]   |
   |        |                          |
   |        +--> x_\{i+1\} = x_i + dx  |
   '-----------------------------------'
            |
            v
   full AC state  ( |V|, theta, P, Q )
   + objective / feasibility reporting
The metaphor: think of a ship’s navigator working a paper chart.
The chart is the shared network representation — one standardized set of symbols that works for a harbor or an ocean, which is why the same navigator handles both. The blanks on the chart are the task: sometimes you know your engine settings and heading and want your position (that’s PF); sometimes you know the destination and the fuel budget and want the engine settings (OPF); sometimes you have three wobbly instrument readings and want to know where you actually are (SE). Same chart, same laws of motion, different blanks.
Dead reckoning is the neural forward pass: a fast, experienced guess that is usually close because the navigator has crossed this water a thousand times. The sextant fix is the AC residual check: it doesn’t tell you the answer, it tells you how wrong you currently are. The course correction is the corrector network, and repeating fix-then-correct a few times is the iterative loop.
Newton-Raphson, in this metaphor, is the navigator who refuses to use experience and recomputes the whole position from spherical trigonometry tables at every step — exact, slow, and occasionally unable to close the calculation at all. DC-PF is the navigator who assumes the Earth is flat and ignores altitude: fast, fine in a small bay, and structurally incapable of telling you your vertical position (voltage magnitude and reactive power). GENCO’s claim is that experienced dead reckoning plus sextant fixes gets you the full three-dimensional position at nearly flat-Earth speed.
Key Concepts
-
Same equations, different blanks. The AC power flow equations relate four quantities at every bus: voltage magnitude, voltage angle, active power, reactive power. Two are given, two are solved for — but *which two is a modeling choice, not physics. A generator bus fixes voltage and active power; a load bus fixes active and reactive power. Once you internalize this, PF, OPF, and SE look less like three algorithms and more like three fill-in-the-blank templates over one system of equations. That reframing is the paper’s actual conceptual move; the architecture follows from it.
-
The DC shortcut and what it costs. Grid operators run linearized DC power flow constantly because it’s a single linear solve. The linearization assumes voltage magnitudes are all near 1.0 per-unit and angle differences are small, which lets you drop reactive power entirely. That’s a fine approximation for asking “how much power flows down this line,” and useless for asking “will this bus’s voltage collapse.” The abstract’s most concrete claim is on exactly this axis: recover the full AC state (magnitudes and reactive power) while matching DC-PF’s active-power-balance residuals at roughly 2x DC’s runtime. If that holds, it’s a genuinely attractive operating point, because the alternative today is “cheap and blind” or “complete and slow.”
-
Residual as input, not just as loss. Most physics-informed ML adds a residual penalty to the training loss and hopes the network internalizes the constraint. Feeding the residual back in as an *input feature at inference time is different in kind: the network gets to see how wrong it currently is on this specific case and respond. That’s the difference between a student who studied the answer key and a student who checks their work. It’s the transferable trick in this paper.
Framework Shift
  Before (mainstream approach):          After (this paper):

  PF task                                    one grid graph
   [ GNN_pf ] -- trained on grid A            [ buses + edges + mask ]
   loss: MSE vs Newton                                |
                                                      v
  OPF task                                   [ geometric encoder ]
   [ DeepOPF_x ] -- grid A, fixed size                |
   loss: MSE + penalty                                v
                                             [ candidate state ]
  SE task                                            |  ^
   [ unrolled WLS net ]                              v  |
   loss: measurement fit                    [ residual check ]
                                                     |
  each: own data pipeline                            v
  each: own grid encoding                    PF / OPF / SE answer
  each: own metric                          ( task = which slots
  cross-paper comparison: hard                are empty + objective )

                                            + GridFM framework
                                            + released datasets
                                            + physics-based metrics
One sentence: from three task-specific regressors judged against a reference solver to one topology-agnostic corrector judged against the physics, the core shift is treating the task as metadata on a shared representation rather than as a separate model.
Expert Assessment
Problem choice. Real gap, and a slightly unglamorous one. The neural-solver literature genuinely does suffer from fragmented representations and non-comparable benchmarks, and the people who could use these tools — power system engineers — are not the people who can stand up a PyG training pipeline. Releasing a low-code framework plus million-scenario datasets addresses that directly, and artifacts like these tend to outlive the model they shipped with. The “step toward Grid Foundation Models” framing is where I’d push back: nothing in the abstract demonstrates the properties that make foundation models interesting — few-shot transfer to unseen task types, scaling behavior, emergent capability. Multi-task supervised learning on a shared graph encoding is a good idea, but it’s a good idea from 2019, not a foundation model. The framing will help the paper get read and will annoy careful reviewers.
Method maturity. The unification insight is clean and correct, and the residual-in-the-loop corrector is the right architecture for the problem — it’s the piece that makes the physics claims credible rather than aspirational. But the components are individually familiar: graph encoders for grids, learned corrective iteration, mask-based task conditioning. The contribution is composition and packaging, executed well. On overlooked simpler alternatives: a warm-started Newton-Raphson, where the neural net supplies only the initial guess and a classical solver does the iterations, gets you exactness plus most of the speedup and is far easier to certify. I’d want the paper to argue explicitly against that baseline, because it’s what a utility’s engineering team will propose in the first meeting.
Experimental integrity. Evaluating on PFDelta and OPFData is the right choice, and the Hydro-Québec SCADA evaluation is a real differentiator — most papers in this space never touch measured data, and real SCADA brings bad data, topology errors, and parameter drift that synthetic sets don’t. Two things I’d scrutinize. First, all speedup claims (30x over Newton-Raphson, 85x over IPOPT) are almost certainly GPU-batched neural inference against single-case CPU solvers. That’s a legitimate deployment comparison and a misleading algorithmic one; the honest version reports per-case latency at batch size one alongside throughput, and states hardware for both sides. Second, “improving feasibility over DC-OPF” is a low bar — DC-OPF solutions are frequently AC-infeasible by construction. The number that matters is feasibility versus IPOPT’s AC-optimal solution, and the optimality gap distribution’s tail, not its mean. Third, the SE claim cuts both ways: “always returns a high-quality estimate even when WLS fails to converge” is a real operational advantage, but WLS non-convergence is also a *signal — often that measurements are corrupted or the assumed topology is wrong. A solver that never announces failure needs a calibrated confidence output, or it’s replacing a loud failure with a quiet one. I’d want to see bad-data detection performance before deploying this.
Writing quality. The abstract is well-organized and unusually specific about numbers, which I appreciate. The predictable soft spots in papers shaped like this one: the architecture section will underspecify how the task mask interacts with the encoder and how many corrective iterations are used (and whether that count is tuned per task, which would complicate the runtime claims); and the limitations discussion will be thin. Rewriting a proper failure-mode section — where does GENCO produce confidently wrong states, what happens on topologies far outside the training distribution, what happens under N-1 contingencies — would do more for the paper’s credibility than another benchmark table. Papers that ship frameworks are also chronically vague about the framework’s scope; a page on what GridFM does *not cover would build trust.
Verdict: weak accept — the unification insight is sound, the artifacts are genuinely useful to the community, and the SCADA evaluation is rare and welcome; the “foundation model” framing is unearned and the speedup comparisons need hardware-parity accounting before I’d cite the numbers.
Takeaways
Concrete things worth stealing:
-
Task-as-mask conditioning. If you have several problems over the same underlying system that differ only in which variables are given and which are sought, don’t build several models — build one that reads a known/unknown mask. This generalizes far beyond grids: structural mechanics with different boundary conditions, chemical process simulation in design-mode versus operating-mode, any inverse/forward pair over shared equations.
-
Feed the residual in, not just into the loss. Physics-informed losses train the model to be right on average over the training distribution. Passing the constraint violation back in as an inference-time feature lets the model be right on *this instance. The cost is a few extra forward passes; the benefit is that your error signal is measured rather than assumed. This is the single most portable idea in the paper.
-
Report the physics residual, not the MSE against a solver. If your neural surrogate is evaluated by how closely it matches a classical solver’s output, you have capped your ambition at imitation and you’ve hidden whether your errors are physically harmful. Measure the quantity the domain actually cares about.
-
The adoption strategy is part of the contribution. A low-code framework plus released datasets is how you get domain engineers, not ML researchers, to use your work. If your target user cannot reproduce your pipeline in an afternoon, your paper’s impact is bounded by citations.
-
A solver that always answers needs a confidence signal. Treat “more robust than the classical method because it never fails to converge” as an incomplete claim until paired with calibrated uncertainty or anomaly detection. Silent failure is worse than loud failure in operational settings.
论文: 2608.09921 作者: Alban Puech, Matteo Mazzonelli, Tamara R. Govindasamy, Héctor Maeso-García, Thomas Tolhurst, Javad Bayazi, Ali Moeini, Naomi Simumba, Celia Cintas 分类: cs.AI
先说清楚:我手上是摘要和相关文献背景,不是全文。下面涉及内部结构的部分,我会区分“论文明确写了的”和“我根据摘要重建的”。
缺口
神经网络电力系统求解器这个方向热闹了大约五年,但形状很奇怪:论文很多,能复用的东西几乎没有。
先看现有工作停在哪里。
潮流(PF)学习器:PowerFlowNet、各种物理约束 GNN、把牛顿法展开成网络的变体。 通常一个电网训一个模型,评价指标是跟 Newton-Raphson 结果的均方误差。 但 MSE 只是代理指标——没有哪个调度员是按 MSE 下令的。
最优潮流(OPF)学习器:DeepOPF 及其后代、DC3 式的约束补全、原对偶学习。 快,但可行性是老大难:一个越了线路极限的运行点不是解,只是建议。
状态估计(SE):基本是另一支文献,多为展开式加权最小二乘(WLS)或鲁棒估计的代理模型。
工程现实:生产环境大量使用 DC 近似(DC-PF、DC-OPF)。 线性、极快,但代价是彻底丢掉电压幅值和无功功率。 凡是跟电压安全有关的问题,DC 就是错的工具。
所以有三个结构性缺口。 第一,任务碎片化:三类问题共享同一套物理和同一张网络,却养出三套模型家族。 第二,没有公共地基:没有标准的合成数据流水线,没有统一的电网表示,导致跨论文的数字几乎不可比。 第三,指标选错了:拿“逼近传统求解器”当目标,而不是物理残差、可行性和最优性间隙。
GENCO 的赌注是:把表示统一了,三个缺口一起塌掉。
  问题
  [ PF / OPF / SE 由三套模型家族分别解决 ]
  [ 无共享数据流水线;指标是 MSE-vs-求解器 ]
  [ 生产环境退回 DC:没有 |V|,没有 Q     ]
        |
        v
  假设
  [ 三个任务 = 同一张电网图 + 同一套交流方程 ]
  [ 差别只在:哪些量已知、哪些量待求、       ]
  [ 以及施加什么目标函数                     ]
        |
        v
  方法
  [ GENCO:统一网络表示上的几何(图)编码器 +  ]
  [ 由物理残差驱动的修正迭代;任务由         ]
  [ 已知/未知掩码 + 目标项选择               ]
  [ + GridFM 开发框架(数据生成 + 训练)     ]
  [ + 百万级 PF / OPF 场景数据集             ]
        |
        v
  证据
  [ PFDelta、OPFData 基准;魁北克水电 SCADA  ]
  [ PF : 比 Newton-Raphson 快约 30x,        ]
  [      运行时约 DC-PF 的 2x,但给出完整交流态 ]
  [ OPF: 比 IPOPT 快约 85x,可行性优于 DC-OPF ]
  [ SE : WLS 不收敛时仍能给出可用估计         ]
        |
        v
  结论
  [ 一个求解器 + 一套框架,降低入门门槛;    ]
  [ 被叙述为通向“电网基础模型”的一步        ]
增量
一句话:以前你要按任务挑模型、自己重搭数据流水线;现在有一个架构,你把缺的电网量留空,它负责填,还附带了可复现的框架和数据集。
核心机制
摘要点明的两个承重构件是统一的网络表示和修正(Corrective)机制。 电网被表示为异质图:母线是节点,线路是边,发电机和负荷作为挂载特征。 所有关心的物理量——电压幅值、相角、有功、无功、设定值——都作为槽位落在这张图上。 关键是每个槽位还带一个标记:已知,或待求。 拓扑是数据而不是架构,这才让一个模型能跨不同规模的电网。
有了这个表示,三个任务就不再是三个问题。 潮流:发电机设定值和负荷已知,母线电压待求。 最优潮流:负荷已知,设定值待求,外加成本目标和运行约束。 状态估计:一组带噪、部分冗余的量测已知,真实状态待求。 同一张图,同一套交流方程,只是填空的图案不同。
“修正优化器”这部分是它跟普通回归的分水岭。 它不是一次前向映射输入到输出,而是迭代精修:先给一个候选状态, 计算这个候选的真实交流功率残差,把残差作为特征回灌,再输出一个修正量。 这本质上是牛顿步的学习版——只是更新方向是在训练分布上摊销出来的, 而不是每步重新分解雅可比矩阵。 这同时解释了物理故事(残差是量出来的,不是祈祷来的)和速度故事(不用反复解稀疏线性方程), 也解释了为什么 SE 的鲁棒性结果好:迭代修正器没有收敛判据可失败,它永远会交出一个答案。 但那个答案是否可信,是另一个问题,后面再说。
    电网算例(任意拓扑、任意规模)
            |
            v
  +---------------------------------------------+
  |  统一网络表示                                |
  |  节点: 母线 [ |V| th P Q ] + 已知掩码        |
  |  边  : 线路 [ R X B 变比 极限 ]              |
  |  任务标签: PF / OPF / SE                     |
  +---------------------------------------------+
            |
            v
  +---------------------------------------------+
  |  几何编码器(消息传递)                      |
  |  邻居交换状态;置换等变,                    |
  |  规模不被写进架构                            |
  +---------------------------------------------+
            |
            v
      候选状态 x_0
            |
   .--------+--------------------------.
   |        v                          |
   |  [ 交流残差检查 ]                 |  k 次
   |  g(x) = P/Q 失配、约束越限、      |  修正迭代
   |         量测残差                  |
   |        |                          |
   |        v                          |
   |  [ 修正器: dx = f(x, g(x)) ]      |
   |        |                          |
   |        +--> x_\{i+1\} = x_i + dx  |
   '-----------------------------------'
            |
            v
   完整交流状态 ( |V|, theta, P, Q )
   + 目标值 / 可行性报告
核喻:一位在纸质海图上作业的船舶导航员。
海图就是统一网络表示——一套标准符号,画港湾也画大洋, 所以同一个导航员能同时应对两者。
海图上的空格就是任务。 有时你知道机舱设定和航向,要求位置(这是潮流); 有时你知道目的地和油耗预算,要求机舱设定(最优潮流); 有时你手上是三台晃动的仪表读数,要求真实位置(状态估计)。 同一张海图,同一套运动定律,只是空格不同。
**推算航法(dead reckoning)**就是神经网络的前向传播: 一次快速的经验性猜测,通常很接近,因为这片水域他走过一千遍。
六分仪定位就是交流残差检查:它不告诉你答案,只告诉你现在错了多少。
修正航向就是修正网络,而“定位—修正”重复几轮就是那个迭代循环。
在这个比喻里,Newton-Raphson 是拒绝使用经验、每一步都从球面三角函数表重算全部位置的导航员: 精确、慢、偶尔算不出来。 DC-PF 是假设地球是平的、忽略高度的导航员: 快,在小港湾里够用,但结构性地无法告诉你垂直位置(电压幅值与无功)。 GENCO 的主张是:熟练的推算航法加上六分仪校正, 能以接近“平面地球”的速度给出完整的三维位置。
关键概念
-
同一套方程,不同的空格:交流潮流方程在每个母线上关联四个量——电压幅值、相角、有功、无功。 给定两个,求解另外两个;但给定哪两个是建模选择,不是物理规定。 发电机节点固定电压和有功;负荷节点固定有功和无功。 一旦想通这点,PF、OPF、SE 就不再像三种算法,而像同一个方程组上的三张填空模板。 这个重构才是本文真正的概念动作,架构是它的推论。
-
DC 近似省了什么、赔了什么:调度中心天天跑线性化 DC 潮流,因为那只是一次线性求解。 线性化假设所有电压幅值都接近 1.0 标称值、相角差很小,于是可以把无功整个丢掉。 问“这条线路上流多少功率”,这个近似很好; 问“这个母线会不会电压崩溃”,它完全没用。 摘要里最实在的一条主张正好落在这根轴上: 恢复完整交流状态(幅值与无功),同时把有功平衡残差压到 DC-PF 同一水平,运行时约为 DC 的 2 倍。 如果站得住,这是个很有吸引力的工作点——因为今天的选项只有“便宜但盲”和“完整但慢”。
-
残差当输入,不只当损失:多数物理约束机器学习是往训练损失里加一个残差惩罚项,然后希望网络内化约束。 把残差在推理时作为输入特征回灌,是性质上的不同: 网络能看到自己在这个具体算例上错了多少,并据此反应。 这是“背过答案的学生”和“会验算的学生”之间的差别。 也是这篇论文里最可迁移的一招。
框架转变
  之前(主流方法):                     之后(本文方法):

  潮流任务                                  一张电网图
   [ GNN_pf ] -- 在电网 A 上训练             [ 母线 + 边 + 掩码 ]
   损失: MSE vs 牛顿法                              |
                                                    v
  最优潮流任务                              [ 几何编码器 ]
   [ DeepOPF_x ] -- 电网 A,固定规模                |
   损失: MSE + 惩罚项                               v
                                            [ 候选状态 ]
  状态估计任务                                     |  ^
   [ 展开式 WLS 网络 ]                             v  |
   损失: 量测拟合                            [ 残差检查 ]
                                                   |
  各自:一套数据流水线                             v
  各自:一套电网编码                       PF / OPF / SE 答案
  各自:一套指标                          ( 任务 = 哪些槽位空着
  跨论文比较:几乎做不到                     + 什么目标函数 )

                                          + GridFM 框架
                                          + 公开数据集
                                          + 基于物理的指标
一句话:从三个按任务定制、以传统求解器为标尺的回归器, 到一个与拓扑无关、以物理为标尺的修正器, 核心转变是把“任务”降格成统一表示上的元数据,而不是另立一个模型。
专家评审
选题眼光:真缺口,而且是个不太光鲜的真缺口。 神经求解器文献确实苦于表示碎片化和基准不可比, 而最需要这类工具的人——电力系统工程师——恰恰不是能自己搭起 PyG 训练流水线的人。 放出低代码框架加百万级数据集,直接命中这一点; 而且这类工件的寿命通常比它随附的模型更长。 我要顶回去的是“通向电网基础模型的一步”这个叙事: 摘要里没有任何证据展示基础模型真正有趣的性质—— 对未见任务类型的少样本迁移、规模化规律、涌现能力。 共享图编码上的多任务监督学习是个好主意,但它是 2019 年的好主意,不是基础模型。 这个包装会帮它被更多人读到,也会让认真的审稿人不舒服。
方法成熟度:统一化的洞见干净且正确,残差回灌的修正器是这个问题的对路架构—— 正是这一块让物理主张变得可信而非空喊。 但拆开看,各个部件都很熟悉:电网图编码器、学习式修正迭代、掩码式任务条件化。 贡献在于组合与打包,而且做得不错。 说到被忽略的更简单方案:热启动的 Newton-Raphson—— 神经网络只负责给初值,迭代交给传统求解器—— 能拿到精确性加上大部分加速,而且认证起来容易得多。 我希望论文明确地论证为什么不走这条路,因为这一定是电网公司工程团队第一次开会就会提的方案。
实验诚意:用 PFDelta 和 OPFData 是对的选择,而魁北克水电的 SCADA 评估是真正的差异化—— 这个方向绝大多数论文从不碰实测数据,而真实 SCADA 带着坏数据、拓扑错误、参数漂移,是合成数据给不了的。
有两点我会重点推敲。 第一,所有加速比(比牛顿法 30x、比 IPOPT 85x)几乎肯定是 GPU 批量推理对单算例 CPU 求解器。 作为部署对比它是合法的,作为算法对比它是误导的; 诚实的写法是同时报告 batch size = 1 的单算例延迟和吞吐量,并写清双方硬件。
第二,“可行性优于 DC-OPF”是很低的门槛—— DC-OPF 的解在交流意义下经常本来就不可行。 真正要看的是相对 IPOPT 交流最优解的可行性,以及最优性间隙分布的尾部,不是均值。
第三,SE 那条主张是双刃的: “WLS 不收敛时仍能给出高质量估计”是真实的运行优势, 但 WLS 不收敛本身也是信号——往往说明量测被污染,或者假设的拓扑是错的。 一个永不宣告失败的求解器,必须配一个标定过的置信度输出, 否则它只是把一次响亮的失败换成一次沉默的失败。 在部署之前我要看坏数据检测的表现。
写作功力:摘要组织得好,数字给得罕见地具体,这点值得肯定。 这种形状的论文有几个可预期的软处: 架构部分很可能没说清任务掩码如何与编码器交互、修正迭代用了几轮 (以及轮数是否按任务调过——如果是,运行时主张就复杂了); 局限性讨论多半单薄。 真正能让整篇升档的,是重写一节失效模式: GENCO 在哪里会自信地给出错误状态、面对远离训练分布的拓扑会怎样、N-1 故障场景下会怎样。 另外,发框架的论文一贯对框架边界含糊; 花一页写清 GridFM 不覆盖什么,反而能建立信任。
判决:弱接收 —— 统一化洞见成立、放出的工件对社区确有价值、SCADA 评估稀缺且可贵; 但“基础模型”的包装名不副实,加速比数字在硬件对等核算之前我不会引用。
要点总结
可以直接“偷”走的东西:
-
任务即掩码的条件化:如果你有若干问题跑在同一个底层系统上, 差别只是哪些变量已知、哪些待求,那就不要造多个模型—— 造一个会读“已知/未知掩码”的模型。 这远远超出电网范围:不同边界条件下的结构力学、 设计模式对运行模式的化工过程仿真、任何共享同一组方程的正问题/反问题对。
-
把残差灌进输入,而不只灌进损失: 物理约束损失训出的是“在训练分布上平均正确”; 把约束违反量作为推理时特征回传,让模型在当前这个算例上正确。 代价是多几次前向传播,收益是误差信号是量出来的而不是假设的。 这是本文最可移植的一招。
-
报告物理残差,不要报告对求解器的 MSE: 如果你的神经代理模型是用“多接近传统求解器输出”来评价的, 你的天花板就是模仿,而且你掩盖了误差在物理上是否有害。 去测量领域真正在意的那个量。
-
推广策略本身就是贡献的一部分: 低代码框架加公开数据集,是让领域工程师(而不是机器学习研究者)用上你工作的方式。 如果目标用户没法在一个下午内复现你的流水线,你论文的影响力上限就是引用数。
-
永远给答案的求解器需要置信度信号: 把“比传统方法鲁棒,因为它从不发散”当作一个未完成的主张, 除非配上标定的不确定性或异常检测。 在运行场景里,沉默的失败比响亮的失败更糟。