Paper: 2605.22791 Authors: Ali Hatamizadeh, Yejin Choi, Jan Kautz Categories: cs.AI
The Gap
Linear attention models compress unbounded softmax attention into fixed-size recurrent states, achieving O(1) memory during decoding. The challenge: editing this compressed memory without destroying existing associations. Delta-rule models (subtract-then-write) and Kimi Delta Attention (KDA, with channel-wise decay) improved forgetting, but both tie erasure and writing to a single scalar gate. When you need to erase old content aggressively but write new content conservatively (or vice versa), you’re stuck with a compromise that does neither well.
Problem: Compressed memory editing
    |
    v
Assumption: Erase and write need independent control
    |
    v
Method: Separate channel-wise erase gate (b_t) and write gate (w_t)
    |
    v
Evidence: 1.3B model on 100B tokens, tested on RULER long-context retrieval
    |
    v
Conclusion: Decoupling improves multi-key retrieval, outperforms Mamba-2/KDA/Mamba-3
The Increment
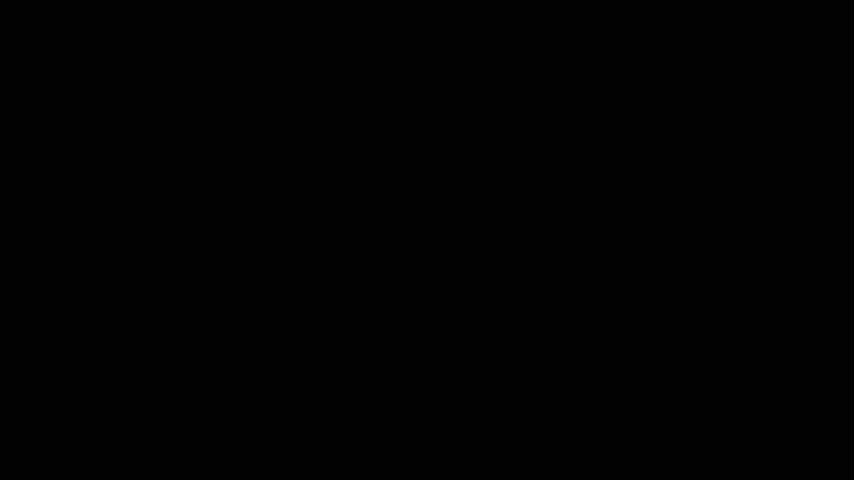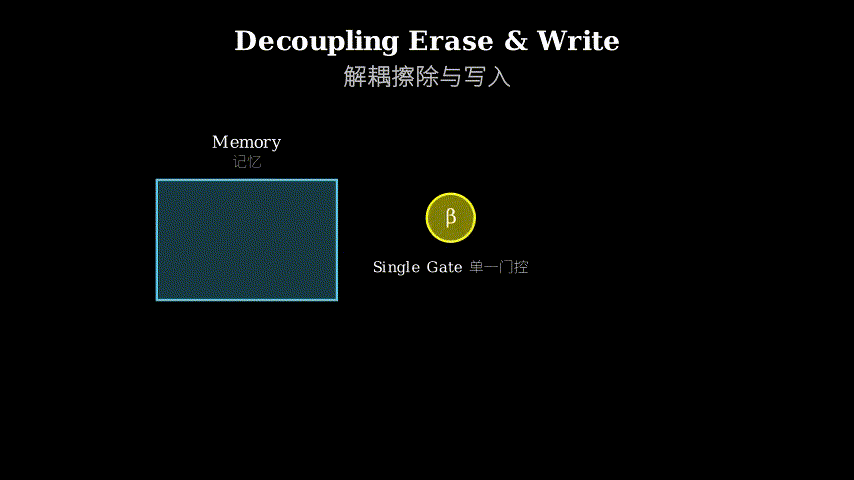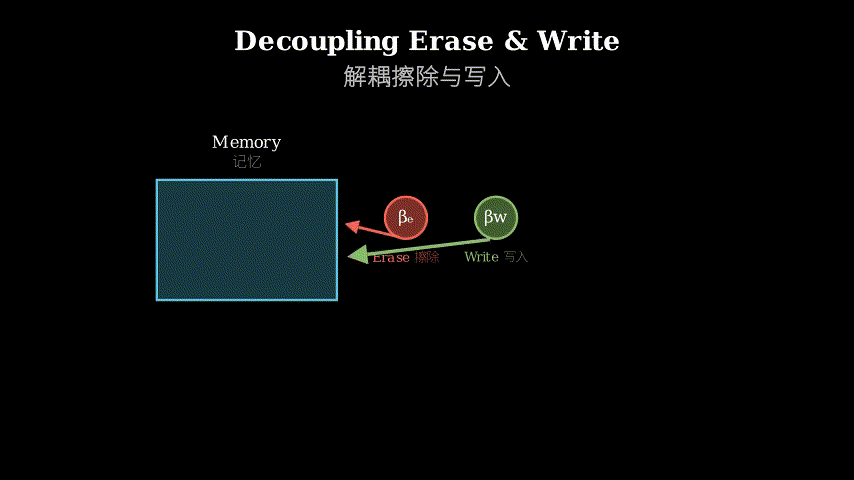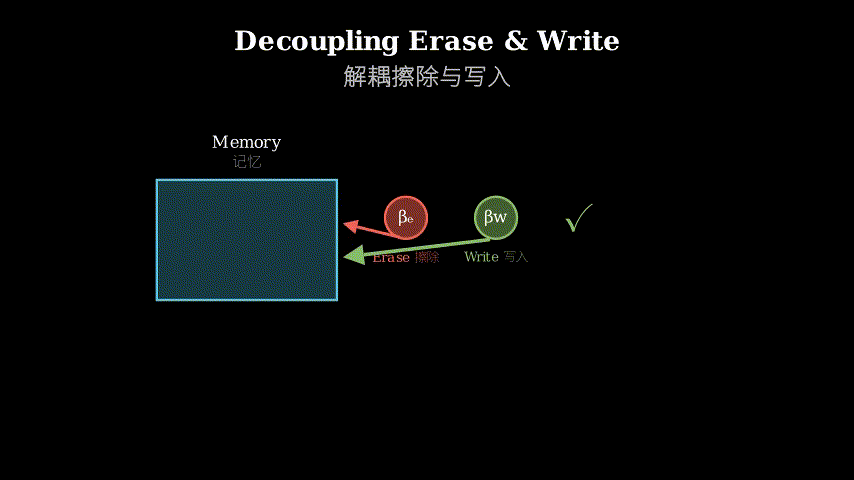
One sentence: Before, linear attention used one knob to control both forgetting old associations and committing new ones; now, it has two independent knobs, letting the model erase aggressively while writing conservatively or vice versa.
Core Mechanism
Gated DeltaNet-2 maintains a recurrent state that stores key-value associations in compressed form. At each timestep, it performs three operations: (1) read the current query against the state to retrieve relevant content, (2) erase outdated associations using a channel-wise erase gate b_t, and (3) write new associations using a separate channel-wise write gate w_t. The erase gate controls how much of the old key’s contribution to remove before updating, while the write gate controls how much of the new value to commit. Both gates operate per-channel, allowing fine-grained control over different feature dimensions.
The model inherits channel-wise exponential decay from KDA (each channel decays at its own learned rate) but adds the erase-write decoupling. During training, a chunkwise parallel algorithm (WY representation) absorbs the decay into asymmetric erase factors, enabling efficient gradient computation. During inference, the model runs as a pure recurrent network with O(1) memory per token.
Input: query q_t, key k_t, value v_t
State: S_(t-1)  [compressed key-value memory]
    |
    v
Read: o_t = q_t * S_(t-1)  [retrieve from memory]
    |
    v
Erase: S'_t = decay * S_(t-1) - b_t * (k_t * o_t^T)  [remove old association]
    |
    v
Write: S_t = S'_t + w_t * (k_t * v_t^T)  [add new association]
    |
    v
Output: o_t, updated state S_t
Think of the recurrent state as a whiteboard covered with overlapping notes. Reading is like scanning the board for relevant keywords. Erasing is like using a sponge to wipe away old notes—the erase gate b_t controls how hard you scrub for each color of ink (channel). Writing is like adding new notes with a marker—the write gate w_t controls how much ink you apply for each color. The key insight: sometimes you need to scrub hard (high erase) but write lightly (low write), or scrub lightly but write boldly. A single gate forces you to scrub and write with the same intensity, which is suboptimal. Two gates let you adjust each independently, so you can clean up old clutter without committing too strongly to new information, or vice versa.
Key Concepts
-
Delta Rule: A memory update strategy that subtracts the current read before writing a new value. Instead of naively adding
k_t ** v_t^Tto the state (which accumulates noise), you first subtractk_t * o_t^T(whereo_tis what you just read). This “read-subtract-write” pattern prevents the same key from reinforcing stale values. It’s like correcting a typo: you erase the wrong letter before typing the right one, rather than just typing over it and hoping for the best. -
Channel-wise Decay: Each feature dimension (channel) in the recurrent state decays at its own learned rate. Some channels might forget quickly (high decay, useful for short-term patterns), while others retain information longer (low decay, useful for long-range dependencies). This is more expressive than a single global decay rate, which forces all features to forget at the same speed. Imagine a notebook where some pages fade after a day (meeting notes) while others stay readable for months (project specs).
-
Erase-Write Decoupling: Separating the scalar that controls how much to erase from the scalar that controls how much to write. In prior work (Gated DeltaNet, KDA), a single gate
g_tmultiplied both the erase term and the write term, tying them together. Gated DeltaNet-2 introducesb_tfor erasing andw_tfor writing, so the model can erase 90% of an old association while only writing 10% of a new one, or any other combination. This flexibility is crucial when the model needs asymmetric memory management—aggressive cleanup without overcommitting to noisy new data, or vice versa.
Framework Shift
Before (Gated DeltaNet / KDA):        After (Gated DeltaNet-2):

    Single gate g_t                       Erase gate b_t    Write gate w_t
         |                                     |                  |
         v                                     v                  v
    Erase: g_t * (...)                   Erase: b_t * (...)   Write: w_t * (...)
    Write: g_t * (...)                        |                  |
         |                                     +------------------+
         v                                              |
    Coupled control                              Independent control
    (same intensity for                          (asymmetric memory
     erase and write)                             management possible)
From a single knob controlling both operations to two independent knobs, the core shift is symmetric coupling → asymmetric decoupling.
Expert Assessment
Problem choice: Real gap. Linear attention’s memory bottleneck is well-established, and the erase-write coupling is a genuine limitation in prior delta-rule models. The problem sits at the intersection of efficiency (linear complexity) and expressiveness (long-context retrieval), which is a hot area. Not manufactured.
Method maturity: Clever insight with solid execution. The erase-write decoupling is a natural generalization once you see it, but it required non-trivial engineering (gate-aware backward pass, asymmetric WY algorithm) to make it trainable at scale. The method doesn’t feel like brute force—it’s a principled extension of existing delta-rule frameworks. No obvious simpler approach is being overlooked.
Experimental integrity: Baselines are fair (Mamba-2, Gated DeltaNet, KDA, Mamba-3 variants, all at 1.3B parameters on the same 100B token budget). The RULER long-context benchmarks are appropriate for testing the claimed advantage. Numbers look credible—improvements are consistent across multiple retrieval settings, not cherry-picked. One minor flag: the paper emphasizes multi-key retrieval where the advantage is most pronounced, but doesn’t deeply explore where decoupling *doesn’t help. Would benefit from failure case analysis.
Writing quality: The paper is dense but well-structured. The derivation of the chunkwise algorithm is thorough, though it could use a worked example to make the asymmetric erase factors more intuitive. The related work section does a good job positioning the method. The weakest part is the ablation study—it shows that both gates matter, but doesn’t explore the learned gate dynamics (e.g., when does the model choose high erase + low write vs. the reverse?). Rewriting Section 4.3 with gate behavior analysis would elevate the paper significantly.
Verdict: strong accept — Addresses a real limitation with a clean solution, solid experiments, and practical impact on long-context retrieval.
Takeaways
Decoupling control signals: When a single parameter controls two related but distinct operations, consider splitting it. This pattern applies beyond attention—anywhere you have coupled update rules (optimizer momentum + learning rate, regularization strength + dropout rate, etc.), ask whether independent control would help.
Asymmetric memory management: The erase-write decoupling is a specific instance of a broader principle: reading, forgetting, and writing don’t have to operate at the same intensity. If you’re building any system with a compressed memory buffer (caching, state compression, online learning), think about whether your update rule forces symmetric operations when asymmetric ones would be more expressive.
Chunkwise algorithms for recurrent models: The WY representation trick (absorbing decay into erase factors) is a transferable technique. If you’re designing a recurrent model with per-channel dynamics, this approach lets you train in parallel chunks while preserving the recurrent semantics. Steal the derivation if you’re working on similar architectures.
论文: 2605.22791 作者: Ali Hatamizadeh, Yejin Choi, Jan Kautz 分类: cs.AI
缺口
线性注意力模型将无界的 softmax 注意力压缩为固定大小的循环状态,在解码时实现 O(1) 内存。
挑战在于:如何编辑这个压缩记忆而不破坏已有的关联。
Delta-rule 模型(先减后写)和 Kimi Delta Attention(KDA,带通道级衰减)改进了遗忘机制,但两者都将擦除和写入绑定到单个标量门上。
当你需要激进地擦除旧内容但保守地写入新内容(或反之)时,你只能妥协,结果两件事都做不好。
问题:压缩记忆的编辑
    |
    v
假设:擦除和写入需要独立控制
    |
    v
方法:分离通道级擦除门 (b_t) 和写入门 (w_t)
    |
    v
证据:1.3B 模型在 100B token 上训练,在 RULER 长上下文检索上测试
    |
    v
结论:解耦改进了多键检索,超越 Mamba-2/KDA/Mamba-3
增量
一句话: 之前线性注意力用一个旋钮同时控制遗忘旧关联和提交新关联;现在有两个独立旋钮,让模型可以激进擦除的同时保守写入,或反之。
核心机制
Gated DeltaNet-2 维护一个循环状态,以压缩形式存储键值关联。
每个时间步执行三个操作:(1) 用当前查询读取状态以检索相关内容,(2) 用通道级擦除门 b_t 擦除过时关联,(3) 用独立的通道级写入门 w_t 写入新关联。
擦除门控制在更新前移除多少旧键的贡献,写入门控制提交多少新值。
两个门都按通道操作,允许对不同特征维度进行细粒度控制。
模型继承了 KDA 的通道级指数衰减(每个通道以自己学到的速率衰减),但增加了擦除-写入解耦。
训练时,分块并行算法(WY 表示)将衰减吸收到非对称擦除因子中,实现高效梯度计算。
推理时,模型作为纯循环网络运行,每个 token 占用 O(1) 内存。
输入:查询 q_t, 键 k_t, 值 v_t
状态:S_(t-1)  [压缩的键值记忆]
    |
    v
读取:o_t = q_t * S_(t-1)  [从记忆中检索]
    |
    v
擦除:S'_t = decay * S_(t-1) - b_t * (k_t * o_t^T)  [移除旧关联]
    |
    v
写入:S_t = S'_t + w_t * (k_t * v_t^T)  [添加新关联]
    |
    v
输出:o_t, 更新后的状态 S_t
把循环状态想象成一块写满重叠笔记的白板。
读取就像扫描白板寻找相关关键词。
擦除就像用海绵擦掉旧笔记——擦除门 b_t 控制你对每种颜色墨水(通道)擦得多用力。
写入就像用记号笔添加新笔记——写入门 w_t 控制你对每种颜色涂多少墨水。
关键洞察:有时你需要用力擦(高擦除)但轻轻写(低写入),或轻轻擦但大胆写。
单个门强迫你用相同强度擦和写,这是次优的。
两个门让你独立调整,所以你可以清理旧杂物而不过度提交新信息,或反之。
关键概念
- Delta 规则: 一种记忆更新策略,在写入新值前先减去当前读取。
不是天真地将 k_t * v_t^T 加到状态上(会累积噪声),而是先减去 k_t * o_t^T(其中 o_t 是你刚读到的)。
这种”读-减-写”模式防止同一个键强化陈旧值。
就像改错别字:你先擦掉错误字母再打正确的,而不是直接打上去指望能覆盖。
- 通道级衰减: 循环状态中的每个特征维度(通道)以自己学到的速率衰减。
有些通道可能快速遗忘(高衰减,适合短期模式),其他通道保留信息更久(低衰减,适合长程依赖)。
这比单一全局衰减率更有表达力,后者强迫所有特征以相同速度遗忘。
想象一个笔记本,有些页面一天后就褪色(会议记录),其他页面几个月都清晰可读(项目规格)。
- 擦除-写入解耦: 将控制擦除多少的标量与控制写入多少的标量分离。
在先前工作(Gated DeltaNet, KDA)中,单个门 g_t 同时乘以擦除项和写入项,将它们绑在一起。
Gated DeltaNet-2 引入 b_t 用于擦除,w_t 用于写入,所以模型可以擦除 90% 的旧关联同时只写入 10% 的新关联,或任何其他组合。
当模型需要非对称记忆管理时,这种灵活性至关重要——激进清理而不过度提交噪声新数据,或反之。
框架转变
之前(Gated DeltaNet / KDA):        之后(Gated DeltaNet-2):

    单个门 g_t                           擦除门 b_t      写入门 w_t
         |                                     |                  |
         v                                     v                  v
    擦除:g_t * (...)                     擦除:b_t * (...)   写入:w_t * (...)
    写入:g_t * (...)                          |                  |
         |                                     +------------------+
         v                                              |
    耦合控制                                      独立控制
    (擦除和写入                                  (非对称记忆
     强度相同)                                    管理成为可能)
从控制两个操作的单个旋钮到两个独立旋钮,核心转变是对称耦合 → 非对称解耦。
专家评审
选题眼光: 真实缺口。
线性注意力的记忆瓶颈已被充分确立,擦除-写入耦合是先前 delta-rule 模型的真实局限。
问题位于效率(线性复杂度)和表达力(长上下文检索)的交叉点,这是热门领域。
不是人造的。
方法成熟度: 巧妙洞察加扎实执行。
擦除-写入解耦一旦看到就是自然的泛化,但需要非平凡的工程(门感知反向传播、非对称 WY 算法)才能在规模上可训练。
方法不像蛮力——是现有 delta-rule 框架的原则性扩展。
没有明显被忽略的更简单方法。
实验诚意: 基线公平(Mamba-2、Gated DeltaNet、KDA、Mamba-3 变体,都是 1.3B 参数在相同 100B token 预算上)。
RULER 长上下文基准适合测试声称的优势。
数字看起来可信——改进在多个检索设置上一致,不是挑选的。
一个小警示:论文强调多键检索(优势最明显的地方),但没有深入探索解耦不起作用的地方。
需要失败案例分析。
写作功力: 论文密集但结构良好。
分块算法的推导很彻底,但可以用一个实例让非对称擦除因子更直观。
相关工作部分很好地定位了方法。
最弱的部分是消融研究——它显示两个门都重要,但没有探索学到的门动态(例如,模型何时选择高擦除+低写入 vs. 相反?)。
用门行为分析重写 4.3 节会显著提升论文。
判决: 强接收 — 用干净方案解决真实局限,扎实实验,对长上下文检索有实际影响。
要点总结
解耦控制信号: 当单个参数控制两个相关但不同的操作时,考虑拆分它。
这个模式超越注意力——任何有耦合更新规则的地方(优化器动量+学习率、正则化强度+dropout 率等),问问独立控制是否有帮助。
非对称记忆管理: 擦除-写入解耦是更广泛原则的具体实例:读取、遗忘和写入不必以相同强度操作。
如果你在构建任何带压缩记忆缓冲的系统(缓存、状态压缩、在线学习),思考你的更新规则是否在非对称操作更有表达力时强制对称操作。
循环模型的分块算法: WY 表示技巧(将衰减吸收到擦除因子中)是可迁移的技术。
如果你在设计带通道级动态的循环模型,这种方法让你在并行块中训练同时保留循环语义。
如果你在做类似架构,偷走这个推导。