Paper: 2607.05369 Authors: Kaiyuan Chen, Shuangyu Xie, Letian Fu, Justin Yu, William Pacini, Sandeep Bajamahal, Hudson Kim, Jaimyn Drake, Daehwa Kim, Haoru Xue Categories: cs.RO, cs.AI, cs.CL, cs.LG
The Gap
Modern robotics has two main camps for building reliable systems. One camp, exemplified by Task and Motion Planning (TAMP) and the Robot Operating System (ROS), builds interpretable, modular programs from hand-coded skills. It’s great for “fixed automation” where everything is predictable, but it struggles with “Variational Automation” (VA) tasks—like picking differently shaped objects from a bin or opening varied handles—because its rigid graphs can’t adapt to the infinite variety of the real world. The other camp, model-free reinforcement learning (RL), learns end-to-end policies that *can adapt to variation, but they are black boxes, notoriously data-hungry, and often fail to meet the persistent, high-reliability standards of commercial and industrial settings. The gap is this chasm: how do you get the interpretability and structure of TAMP with the adaptability of model-free policies?
Problem: Rigid programs break under variation; flexible policies lack reliability and structure.
     |
     v
Assumption: Combining a structured skill library with a learning-to-plan mechanism can bridge this gap.
     |
     v
Method: GaP builds directed computation graphs from a skill library, then uses self-play in a generated simulation to optimize the graph's structure and parameters.
     |
     v
Evidence: On 8 new VA benchmarks (4 sim, 4 real), GaP significantly outperforms baselines in success rate and throughput.
     |
     v
Conclusion: Graph-as-Policy is a viable and effective framework for creating reliable, adaptable robot programs.
The Increment
One sentence: Before this paper, you had to choose between an interpretable but brittle program and an adaptable but opaque policy; after this paper, you can have a system that automatically generates, tests, and refines interpretable graph-structured policies that are both adaptable and reliable.
Core Mechanism
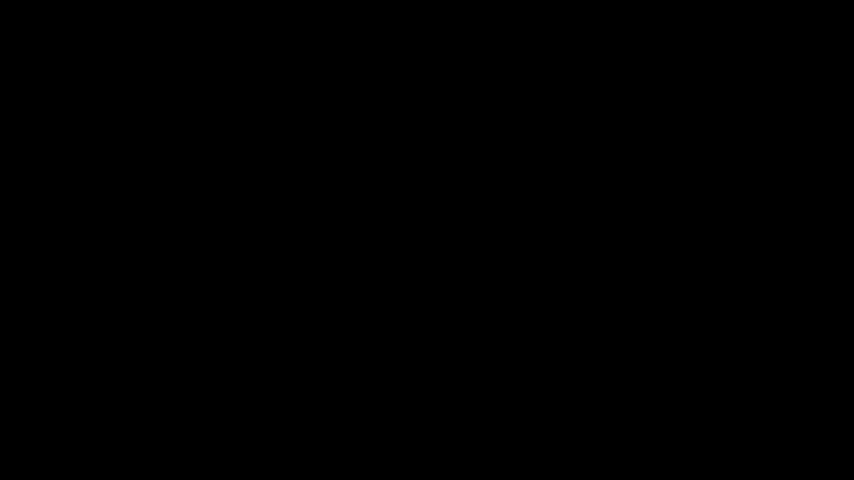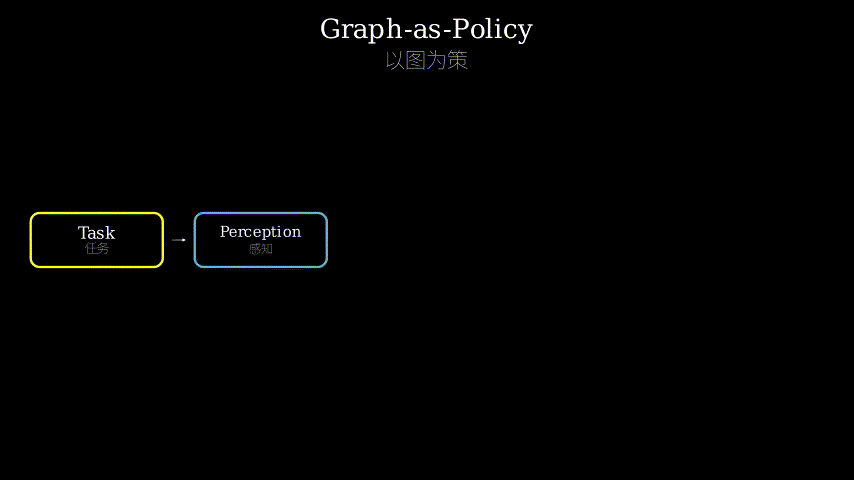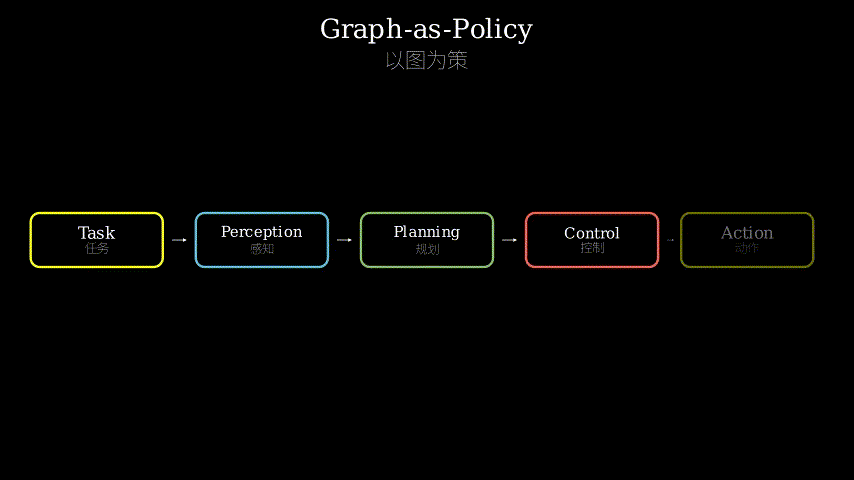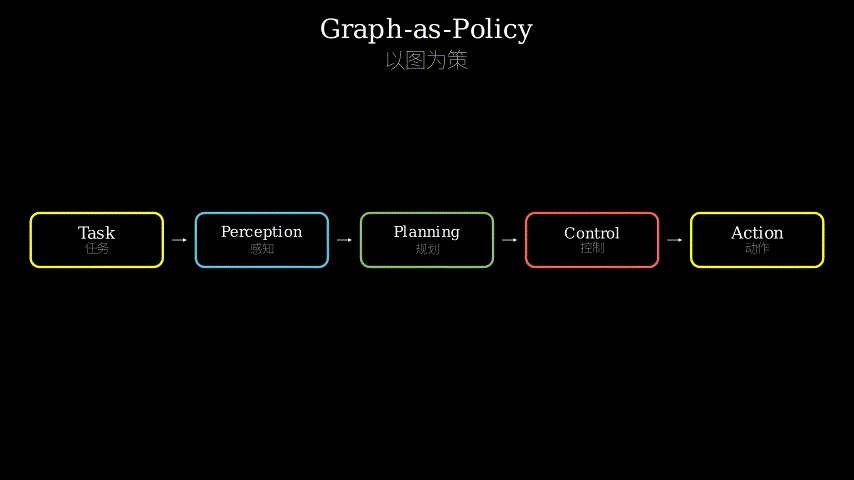
GaP operates as a multi-agent coding system, like a small team of AI programmers. Its foundation is MORSL (Modular Open Robot Skill Library), a curated library of reusable, high-quality robotic skill modules for perception, planning, and control. When given a task (e.g., “pick up the cup”), a “graph-generation agent” doesn’t write a monolithic script. Instead, it composes a directed computation graph, where each node calls a specific skill from MORSL (e.g., detect_object, plan_trajectory, execute_grip) and edges define the data and control flow between them. This is the initial, interpretable “program.”
This is where the magic happens. To handle variation, GaP doesn’t just run this program. A second “simulation-generation agent” analyzes the task and the initial graph, then procedurally generates a lightweight internal simulation environment that can instantiate many task variants (e.g., cups of different sizes, positions, orientations). A third “evaluation agent” then runs the current graph-policy across hundreds of these simulated variants in parallel, collecting success/failure data. Finally, a “refinement agent” analyzes this data and iteratively modifies the graph—adding nodes, changing parameters, or rewiring connections—to improve its overall success rate. This cycle of generate-simulate-evaluate-refine continues until the graph stabilizes.
[Task Description] --> [Graph-Gen Agent]
                             |
                             v
                      [Initial Graph-Policy]
                             |
         +-------------------+-------------------+
         |                                       |
         v                                       |
[Simulation-Gen Agent] --+                      |
         |                |                      |
         v                v                      |
   [Internal Sims]    [Eval Agent] --+           |
   (parallel, varied)      |         |           |
                           v         v           |
                     [Performance Data]          |
                           |                     |
                           v                     |
                   [Refinement Agent] ------------+
                           |
                           v
                   [Refined Graph-Policy] --> (loop back to sim gen)
Think of GaP as a high-stakes cooking competition for robot recipes. The MORSL library is your pantry, stocked with perfectly reliable basic techniques (chop, sauté, bake, plate). The graph is the recipe—a specific sequence of steps using those techniques to make a dish (the task). The problem is, you can’t just practice with one tomato; you need to make sure the recipe works with all possible tomatoes (different ripeness, size, shape). So, the simulation-generator is the competition producer, rapidly sourcing a huge variety of tomatoes (task variants) for you to practice with. You, the chef (evaluation agent), execute your recipe (graph) on each tomato variant, noting successes and failures. Finally, the refinement agent is your coach, who watches the tapes, spots that your knife angle is wrong for large tomatoes, and tells you to adjust that step in the recipe (modify the graph). You then practice again with a new batch of varied tomatoes. This iterative, simulated practice is how you end up with a single, robust recipe that works perfectly with any tomato.
Key Concepts
-
Variational Automation (VA): This is the paper’s name for a crucial category of tasks that existing systems handle poorly. Imagine a factory where a robot must pack items into boxes. In *fixed automation, every item is identical and in the same spot. In variational automation, items are similar (all cups, all boxes) but differ in exact shape, size, orientation, or position on the conveyor belt. The “variation” is the key challenge. VA tasks require a system that generalizes, not one that memorizes a single perfect execution. GaP is designed specifically for this middle ground between rigid repetition and completely unstructured environments.
-
Graph-as-Policy (GaP): This is the core architectural idea. Instead of thinking of a robot’s behavior as a single neural network (a policy) or a linear script, GaP represents it as a directed graph of modular operations. Each node is a reusable skill (a “verb” like “detect” or “plan”), and the edges define the flow of information and control. The beauty is that this representation is inherently interpretable—you can “read” the robot’s intended strategy—and it’s malleable. The learning algorithm doesn’t tweak a million weights in a black box; it restructures and re-parameterizes this explicit, human-readable graph.
Framework Shift
Before (mainstream approach):            After (this paper):

[Task] --> [Monolithic Policy (NN)]      [Task] --> [Graph Composer]
               |                                  |
               v                                  v
         [Opaque Weights]                [Directed Graph of Skills]
               |                                  |
               v                                  |
     [Direct Execution]                   [Sim Generator]
               |                                  |
               v                                  v
     (Fails on variation)                [Parallel Sim Trials]
                                                  |
                                                  v
                                          [Graph Refiner]
                                                  |
                                                  v
                                           (Robust Policy)
From learning a monolithic policy to composing and refining an interpretable computation graph, the core shift is in the unit of learning: it moves from optimizing inscrutable parameters within a fixed architecture to optimizing the explicit structure and parameters of a human-understandable program.
Expert Assessment
Problem choice: Excellent. The gap between brittle symbolic plans and unreliable black-box policies for real-world, variable tasks is a genuine and critical bottleneck for deploying robots in commercial settings. This paper squarely targets that chasm, which puts it on a very relevant trajectory in robotics.
Method maturity: Clever insight with a pragmatic, multi-agent twist. It’s essentially a form of graph-structure search guided by simulation performance. The reliance on a pre-existing, high-quality skill library (MORSL) is a strength for reliability but also a potential limitation for tasks requiring fundamentally new low-level skills. The multi-agent framing feels a bit like over-engineering the description of what is effectively a single optimization loop, but it doesn’t undermine the core idea.
Experimental integrity: The creation of 8 new VA benchmarks is a valuable contribution itself, providing a concrete testbed for the community. Comparisons against TAMP baselines (which are weak on VA) and model-free RL baselines (which are weak on reliability) seem fair. The real-world validation on 4 tasks adds significant credibility. The numbers (“significantly outperform”) are presented, but the absolute performance levels (e.g., 85% vs. 60%) and failure modes would need close inspection in the full paper.
Writing quality: The abstract is clear and sets the scene well. The description of the multi-agent harness is where the writing likely gets dense. The “simulation-generation agent” is the most novel part, and that section would benefit most from a rewrite with a clearer, more intuitive example walking through the process step-by-step. Explaining *how it generates diverse, useful simulations is key.
Verdict: strong accept — This is a smart, well-motivated synthesis of ideas from program synthesis, TAMP, and simulation-based learning that addresses a pressing practical problem with a novel and promising framework.
Takeaways
- The “Graph-as-Policy” paradigm is highly transferable. For anyone building complex, multi-step AI systems (not just robotics), representing the system’s logic as a directed graph of modular components is powerful. It enables interpretability, easier debugging, and targeted optimization. This idea could improve workflow engines, data pipelines, or even complex agent architectures.
- Self-play in procedurally generated environments is a potent recipe for robustness. The technique of automatically creating a distribution of challenge cases (the simulation generator) to test and stress-test a policy is a lesson in building reliable AI. Practitioners in any domain with variable inputs (e.g., web automation, logistics) should consider simulating their edge cases rather than just testing on real data.
- Don’t throw away your structured priors; learn over them. The paper’s success comes from starting with high-quality, human-designed skills (MORSL) and using learning to *compose and adapt them, not replace them entirely. This hybrid approach—learning the structure atop reliable components—is a powerful pattern for building trustworthy AI systems.
论文: 2607.05369 作者: Kaiyuan Chen, Shuangyu Xie, Letian Fu, Justin Yu, William Pacini, Sandeep Bajamahal, Hudson Kim, Jaimyn Drake, Daehwa Kim, Haoru Xue 分类: cs.RO, cs.AI, cs.CL, cs.LG
缺口
现代机器人学构建可靠系统主要有两个流派。一个流派以任务与运动规划和机器人操作系统为代表,通过手工编码的技能模块构建可解释的程序。 这套方法擅长处理“固定自动化”任务(一切可预测),但在面对“可变自动化”任务时举步维艰——比如从料斗中抓取形状各异的物体,或操作不同的门把手。 因为其固定的程序图无法适应真实世界无穷无尽的变化。另一个流派是无模型强化学习,它学习端到端的策略,确实能适应变化,但却是黑箱,极其依赖数据,且常常无法满足商业和工业场景下对持续、高可靠性的要求。 这中间的鸿沟就是:如何同时获得任务与运动规划的可解释性与结构性,以及无模型策略的适应性?
问题:固定程序在变化面前崩溃;灵活策略缺乏可靠性和结构。
     |
     v
假设:将结构化技能库与一种“学习如何规划”的机制相结合,可以弥合这一鸿沟。
     |
     v
方法:GaP 从技能库中构建有向计算图,然后在生成的模拟环境中通过自我博弈来优化图的结构和参数。
     |
     v
证据:在 8 个新的可变自动化基准任务(4个模拟,4个真实)上,GaP 的成功率和吞吐量显著优于基线方法。
     |
     v
结论:“以图为策”是创建可靠、可适应机器人程序的一种可行且有效的框架。
增量
一句话: 在这篇论文之前,你必须在可解释但脆弱的程序与可适应但不可靠的策略之间做出选择;在这篇论文之后,你将拥有一个可以自动生成、测试并迭代优化可解释的图结构策略的系统,它既适应变化又足够可靠。
核心机制
GaP 作为一个多智能体编码系统运行,就像一个小型的AI程序员团队。它的基础是 MORSL,一个经过筛选的、高质量的机器人技能模块库,涵盖感知、规划和控制。当接到一个任务(例如“拿起杯子”)时,“图生成智能体”不会编写一个庞大的脚本。相反,它会组合出一个有向计算图,图中每个节点调用MORSL中的一个特定技能(如检测物体、规划轨迹、执行抓取),边则定义了节点间的数据和控制流。这就是初始的、可解释的“程序”。
精彩之处在于如何处理变化。GaP 不会直接运行这个程序。第二个“模拟生成智能体”会分析任务和初始图,然后程序化地生成一个轻量级的内部模拟环境,该环境可以实例化大量任务变体(例如,不同大小、位置、朝向的杯子)。接着,第三个“评估智能体”在并行地在这些模拟变体上运行当前的图策略,收集成功/失败的数据。最后,一个“优化智能体”分析这些数据,并迭代地修改图结构——增加节点、改变参数或重新布线——以提升整体的成功率。这种“生成-模拟-评估-优化”的循环会持续进行,直到图结构稳定下来。
[任务描述] --> [图生成智能体]
                    |
                    v
             [初始图策略]
                    |
        +-----------+-----------+
        |                       |
        v                       |
[模拟生成智能体] --+           |
        |           |           |
        v           v           |
  [内部模拟环境]  [评估智能体] --+
  (并行,多样化)       |         |
                      v         v
                [性能表现数据]    |
                      |         |
                      v         |
              [优化智能体] ------+
                      |
                      v
               [优化后的图策略] --> (循环回模拟生成)
可以把GaP想象成一场为机器人食谱举办的高风险烹饪大赛。MORSL技能库就是你的食材库,储备着完美可靠的基本烹饪技法(切、炒、烤、摆盘)。图就是食谱——一个使用这些技法制作特定菜肴(任务)的精确步骤序列。问题是,你不能只用一种西红柿练习;你需要确保食谱对所有可能的西红柿(不同的熟度、大小、形状)都有效。所以,模拟生成智能体就是比赛制作人,他快速为你搜罗大量多样化的西红柿(任务变体)供你练习。你,作为主厨(评估智能体),用每个西红柿变体执行你的食谱(图),记录成功和失败。最后,优化智能体是你的教练,他观看录像,发现你的刀法对大西红柿不对,于是告诉你调整食谱中的那个步骤(修改图)。然后你再用一批新的、多样化的西红柿继续练习。正是通过这种迭代的、模拟的练习,你最终才能得到一份对任何西红柿都完美适用的稳健食谱。
关键概念
-
可变自动化: 这是论文定义的一个关键任务类别,现有系统处理得不好。想象一个工厂里,机器人必须把物品装箱。在**固定自动化中,每个物品都一模一样,位置也相同。在可变自动化*中,物品相似(都是杯子、都是盒子),但在具体形状、大小、朝向或传送带上的位置上有所不同。“变化”是核心挑战。VA任务需要能泛化的系统,而非仅仅记住一次完美执行的系统。GaP正是为这种介于严格重复和完全无结构环境之间的中间地带而设计的。
-
以图为策: 这是核心的架构理念。GaP不把机器人的行为看作一个单一的神经网络(策略)或一个线性脚本,而是将其表示为一个由模块化操作组成的有向图。每个节点是一个可复用的技能(一个“动词”,如“检测”或“规划”),边定义了信息和控制的流动。其美妙之处在于,这种表示本质上是可解释的——你可以“阅读”出机器人的预期策略——而且它是可塑的。学习算法调整的不是一个黑箱中的百万个权重,而是重组和优化这个显式的、人类可理解的图结构。
框架转变
之前(主流方法):                之后(本文方法):

[任务] --> [整体式策略 (神经网络)]   [任务] --> [图组合器]
               |                               |
               v                               v
         [不透明的权重]               [由技能构成的有向图]
               |                               |
               v                               |
     [直接执行]                        [模拟生成器]
               |                               |
               v                               v
     (在变化下失败)                    [并行模拟试验]
                                             |
                                             v
                                         [图优化器]
                                             |
                                             v
                                       (稳健的策略)
从学习一个整体式的策略到组合并优化一个可解释的计算图,核心转变在于学习的单位:它从在一个固定架构内优化难以理解的参数,转变为优化一个显式的、人类可理解的程序的结构与参数。
专家评审
选题眼光: 优秀。符号规划(脆弱)与黑箱策略(不可靠)在现实世界、多变任务之间的鸿沟,是制约机器人商业化部署的真实且关键的瓶颈。本文精准地瞄准了这一鸿沟,处于机器人学领域一个非常相关的发展轨迹上。
方法成熟度: 是巧妙的洞察与务实的多智能体方案的结合。其本质是一种由模拟性能引导的图结构搜索。依赖预先存在的、高质量的技能库(MORSL)对于可靠性是优势,但对于需要全新底层技能的任务可能也是一种限制。多智能体的描述框架有点像在过度包装一个本质上是单一优化循环的东西,但这并不削弱其核心思想的创新性。
实验诚意: 创建8个新的可变自动化基准任务本身就是一项有价值的贡献,为社区提供了具体的测试平台。与任务与运动规划基线(在可变任务上弱)和无模型强化学习基线(在可靠性上弱)的比较看起来是公平的。在4个真实任务上的验证显著增加了可信度。论文给出了“显著优于”的比较数据,但绝对性能水平(例如85% vs. 60%)和失败模式需要阅读全文才能仔细审视。
写作功力: 摘要清晰,很好地设定了场景。对多智能体框架的描述很可能是最晦涩的部分。其中,“模拟生成智能体”是最具新意的部分,那部分如果用一个更清晰、更直观的例子来分步讲解重写一遍,会极大提升整篇论文的易读性。解释清楚它是如何生成多样且有用的模拟的,这一点至关重要。
判决: 强接收 — 这是一篇针对紧迫的实际问题,通过一个新颖且有前景的框架,对程序合成、任务与运动规划和基于模拟的学习思想进行了巧妙融合的优秀论文。
要点总结
-
“以图为策”的范式高度可迁移。 对于任何构建复杂、多步骤AI系统(不仅仅是机器人)的人来说,将系统的逻辑表示为一个由模块化组件构成的有向图是非常强大的。它实现了可解释性、更易调试和针对性优化。这个想法可以改进工作流引擎、数据管道,甚至复杂的智能体架构。
-
在程序化生成的环境中自我博弈是提升稳健性的强力配方。 一种用于构建可靠AI的技术是:自动生成一个挑战案例分布(模拟生成器)来测试和压力测试策略。在任何具有可变输入的领域(如网页自动化、物流)中,从业者都应该考虑模拟他们的边缘情况,而不仅仅是用真实数据测试。
-
不要丢弃你的结构化先验知识;在此之上学习。 本文的成功源于从高质量的、人类设计的技能(MORSL)出发,并利用学习来**组合和适应*它们,而非完全取代它们。这种混合方法——在可靠组件之上学习结构——是构建可信赖AI系统的强大模式。