Paper: 2605.28816 Authors: Fangfu Liu, Kai He, Tianchang Shen, Tianshi Cao, Sanja Fidler, Yueqi Duan, Jun Gao, Igor Gilitschenski, Zian Wang, Xuanchi Ren Categories: cs.CV
The Gap
World models like Genie and GameNGen can generate interactive video from control signals, but they assume a single agent. When you need multiple players in the same environment—think multiplayer games, multi-robot coordination, or multi-agent embodied AI—existing approaches hit three walls: (1) slot-based methods (like STEVE) assign learned embeddings to agent slots, which breaks permutation symmetry and doesn’t generalize beyond the trained number of agents; (2) dense attention across all agents scales quadratically with agent count, making inference prohibitively expensive; (3) autoregressive generation is too slow for real-time interaction, requiring frame-by-frame diffusion.
Problem: Multi-agent world modeling
   |
   v
Assumption: Agents need distinct identities but symmetric treatment
   |
   +---> Method: Simplex RoPE (geometric phase encoding)
   |              + Sparse Hub Attention (linear cross-agent cost)
   |              + Causal distillation (real-time rollout)
   v
Evidence: 2->4 player generalization, 24 FPS, better controllability
   |
   v
Conclusion: Geometric encoding + sparse routing enables scalable multi-agent worlds
The Increment
One sentence: Before this paper, world models could simulate one agent at a time or multiple agents with learned slot identities that don’t generalize; after, agents get geometric identities from simplex vertices, enabling permutation-symmetric scaling from 2 to 4+ agents with linear attention cost.
Core Mechanism
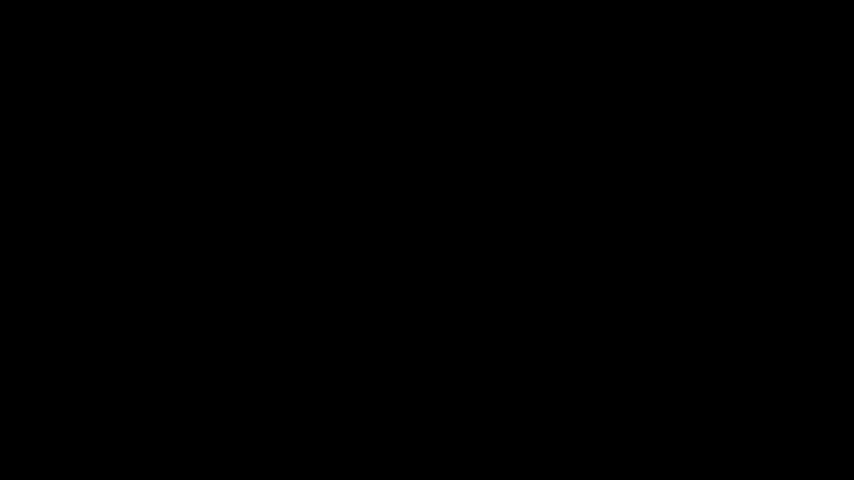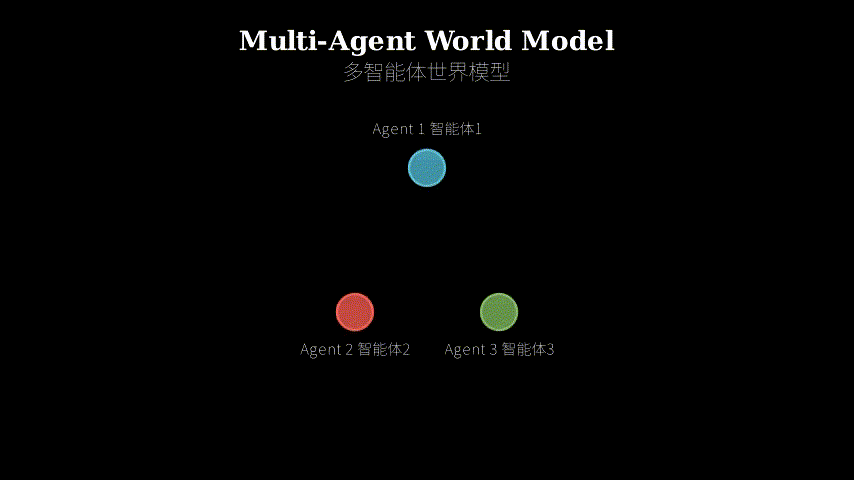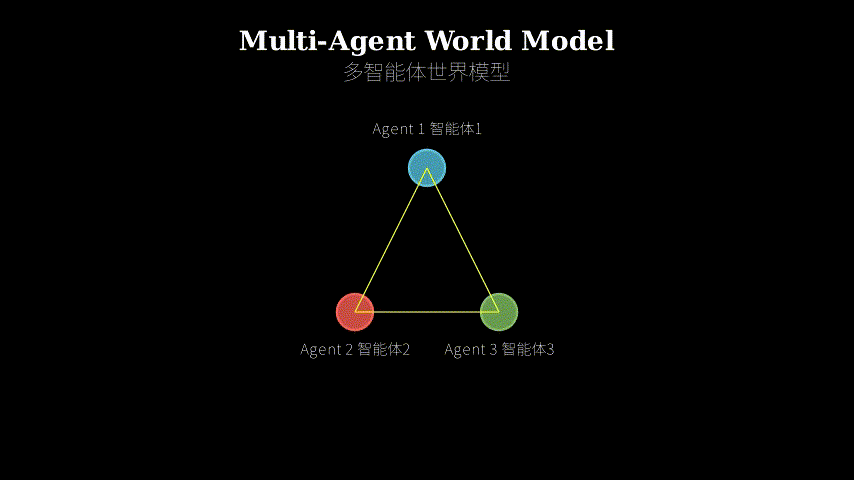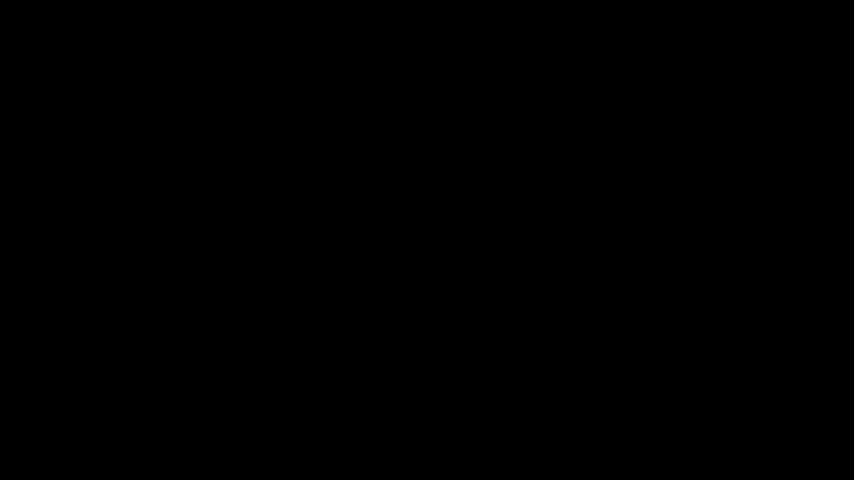
The model has three interlocking pieces. First, Simplex Rotary Agent Encoding extends 3D RoPE by placing each agent at a vertex of a regular simplex in rotary angle space—think of a triangle for 3 agents, a tetrahedron for 4. Each agent gets a unique phase offset, but all agents remain geometrically equivalent (permutation-symmetric). No learned embeddings, no fixed ordering.
Second, Sparse Hub Attention avoids all-to-all agent attention by introducing learnable hub tokens that mediate cross-agent communication. Instead of every agent attending to every other agent (O(n²) cost), each agent attends to the hubs, and hubs attend back to agents (O(n) cost). Think of hubs as switchboard operators routing messages between agents.
Third, causal distillation converts the full-context diffusion teacher into a student that generates video in temporal blocks sequentially, using KV caching to maintain consistency. The teacher sees all frames at once; the student generates frame blocks one after another, conditioned on past blocks and current actions. This enables action-responsive generation at 24 FPS instead of waiting for full diffusion rollout.
Input: Multi-agent actions A_1, A_2, ..., A_n
   |
   v
[Simplex RoPE] ---> Each agent gets geometric phase
   |                (vertices of regular simplex)
   v
[Sparse Hub Attention]
   Agent tokens <---> Hub tokens <---> Agent tokens
   (linear cost, not quadratic)
   |
   v
[Causal Student Model]
   Generate block_t | block_<t, actions_t
   (KV cache for consistency)
   |
   v
Output: Video frames with all agents controllable
Think of this as a conference call system. In a naive setup, every participant (agent) would need a direct line to every other participant—that’s O(n²) phone lines. Simplex RoPE is like giving each participant a unique extension number based on their position around a geometric table, so the system knows who’s who without needing name tags. Sparse Hub Attention is the conference bridge: instead of n² direct connections, everyone calls into a central hub (the switchboard), which routes messages. The hub doesn’t need to understand the content—it just needs to pass tokens between the right parties. Causal distillation is like switching from recording the entire meeting and editing it later (diffusion teacher) to streaming it live with a slight delay buffer (causal student with KV cache). The buffer lets you maintain coherence across time without waiting for the whole meeting to finish.
Key Concepts
-
Simplex Rotary Encoding: Standard RoPE (Rotary Position Embedding) encodes spatial positions by rotating token embeddings in angle space—like putting coordinates on a clock face. For multi-agent settings, you need to encode both spatial position and agent identity. Simplex RoPE does this by placing each agent at a vertex of a regular simplex (the n-dimensional generalization of an equilateral triangle). For 2 agents, they’re at opposite ends of a line segment (180° apart). For 3 agents, they’re at the vertices of an equilateral triangle (120° apart). For 4 agents, they’re at the vertices of a tetrahedron. This gives each agent a distinct phase offset in rotary space, but all agents remain geometrically equivalent—no agent is “special.” Crucially, this is parameter-free: no learned embeddings, so it generalizes to unseen agent counts without retraining.
-
Sparse Hub Attention: In standard multi-agent attention, every agent token attends to every other agent’s tokens, leading to O(n²) complexity in the number of agents. Sparse Hub Attention introduces a small set of learnable hub tokens (think of them as relay stations). Each agent’s tokens attend to the hubs, and the hubs attend back to all agents. This reduces cross-agent attention from quadratic to linear: instead of n agents × n agents, you have n agents × k hubs, where k is a small constant (e.g., 16). The hubs act as a bottleneck that compresses and routes information between agents, similar to how routers work in network architecture.
-
Causal Distillation for Real-Time Rollout: Diffusion models generate high-quality video but require iterative denoising over all frames, making them too slow for interactive use. The teacher model here is a full-context diffusion transformer that sees all frames at once. The student is a causal model that generates video in temporal blocks (e.g., 4 frames at a time) sequentially, conditioned on past blocks and current actions. The student is trained to match the teacher’s output distribution but operates autoregressively with KV caching—it reuses computed key-value pairs from previous blocks to maintain temporal consistency without recomputing everything. This is what enables 24 FPS generation: the student can respond to new actions in real time, while the teacher would need to regenerate the entire sequence.
Framework Shift
Before (slot-based or dense):        After (Gamma-World):

Agent 1 --[learned slot 1]--\        Agent 1 --[simplex vertex 1]--\
Agent 2 --[learned slot 2]---+--> Model    Agent 2 --[simplex vertex 2]---+--[Hub]---> Model
Agent 3 --[learned slot 3]--/        Agent 3 --[simplex vertex 3]--/
                                     Agent 4 --[simplex vertex 4]--/
- Slots don't generalize
- O(n^2) cross-agent attention       - Geometric identity (no learning)
- Frame-by-frame diffusion           - O(n) hub-mediated attention
                                     - Block-wise causal generation
From learned slot identities to geometric phase identities, the core shift is replacing learned agent representations with parameter-free geometric structure, enabling zero-shot generalization to more agents.
Expert Assessment
Problem choice: This is a real gap. Multi-agent world modeling is essential for multiplayer games, multi-robot sim-to-real, and embodied AI research, but existing methods either don’t scale (slot-based) or are computationally prohibitive (dense attention). The problem sits at the intersection of world models and multi-agent systems—both active areas, but their combination has been underexplored. The timing is right: single-agent world models (Genie, GameNGen) are maturing, and the next logical step is multi-agent settings.
Method maturity: The simplex encoding is elegant—it’s a principled geometric solution rather than a learned hack. However, the sparse hub attention feels like a standard trick from efficient transformers (perceiver-style bottlenecks), not a novel insight. The causal distillation is solid engineering but not conceptually new (it’s applying standard knowledge distillation to the temporal dimension). The real contribution is the combination: showing that geometric encoding + sparse routing + causal generation work together for multi-agent world modeling. That said, I’d want to see ablations on hub token count and simplex dimension scaling—what happens at 8 or 16 agents?
Experimental integrity: The baselines are fair (slot-based STEVE, dense attention variant). The 2→4 player generalization is impressive and well-documented. The 24 FPS claim is backed by timing measurements. However, the experiments are limited to virtual game environments (Minecraft-style, racing games). I’d want to see results on real-world multi-robot datasets or embodied AI benchmarks to assess generalization beyond synthetic domains. The video quality metrics (FVD, PSNR) are standard, but there’s no user study on perceived controllability or inter-agent consistency—those would strengthen the claims. Also, the paper doesn’t discuss failure cases: when does the model break down? What happens when agents overlap or occlude each other heavily?
Writing quality: The paper is well-structured and clearly written. The method section is dense but complete. However, the related work section undersells the connection to efficient transformers (perceiver, linformer, etc.)—the hub attention is essentially a perceiver bottleneck, and acknowledging that would help readers place the contribution. The experiments section could use a failure analysis subsection. The supplementary material is thorough, which is good, but some key ablations (e.g., hub token count) should be in the main paper.
Verdict: weak accept — Solid engineering contribution with a clever geometric encoding trick, but the novelty is more in the combination than in individual components. The 2→4 generalization is impressive, but I’d want to see scaling to 8+ agents and real-world domains before calling this a strong accept.
Takeaways
Geometric identity encoding: If you’re building any system with multiple interchangeable entities (agents, objects, modalities), consider encoding their identities geometrically rather than with learned embeddings. Simplex vertices are one option; other regular polytopes or group-theoretic structures could work too. The key insight: symmetry constraints can replace learned parameters, improving generalization.
Hub-mediated attention for multi-entity systems: When you have n entities that need to interact, don’t default to all-to-all attention. Introduce a small set of learnable hub tokens that mediate communication. This is a general pattern from efficient transformers (perceiver, linformer) that applies beyond vision—think multi-agent RL, multi-modal fusion, or any setting where you have multiple “channels” that need to exchange information.
Causal distillation for interactive generation: If you have a high-quality but slow generative model (diffusion, autoregressive transformer), you can distill it into a faster causal student that generates in blocks with KV caching. The trick is training the student to match the teacher’s distribution while operating sequentially. This is useful for any interactive application where you need to respond to user input in real time (game engines, robotics, interactive storytelling).
When to use this: If you’re building multi-agent simulations, multiplayer game engines, or multi-robot coordination systems, this architecture is worth stealing. If you’re working on single-agent tasks or non-interactive generation, the complexity isn’t justified—stick with simpler models.
论文: 2605.28816 作者: Fangfu Liu, Kai He, Tianchang Shen, Tianshi Cao, Sanja Fidler, Yueqi Duan, Jun Gao, Igor Gilitschenski, Zian Wang, Xuanchi Ren 分类: cs.CV
缺口
像 Genie 和 GameNGen 这样的世界模型可以根据控制信号生成交互式视频,但它们假设只有单个智能体。
当你需要多个玩家在同一环境中活动时——比如多人游戏、多机器人协调或多智能体具身AI——现有方法会撞上三堵墙:(1)基于槽位的方法(如 STEVE)为智能体槽位分配学习到的嵌入,这打破了排列对称性,无法泛化到训练时未见过的智能体数量;(2)所有智能体之间的密集注意力随智能体数量呈平方级增长,推理成本高得离谱;(3)自回归生成对实时交互来说太慢,需要逐帧扩散。
问题:多智能体世界建模
   |
   v
假设:智能体需要独特身份但对称处理
   |
   +---> 方法:单纯形 RoPE(几何相位编码)
   |           + 稀疏枢纽注意力(线性跨智能体成本)
   |           + 因果蒸馏(实时展开)
   v
证据:2->4 玩家泛化,24 FPS,更好的可控性
   |
   v
结论:几何编码 + 稀疏路由实现可扩展的多智能体世界
增量
一句话:这篇论文之前,世界模型一次只能模拟一个智能体,或者用学习到的槽位身份模拟多个智能体但无法泛化;之后,智能体从单纯形顶点获得几何身份,实现了排列对称的扩展,从2个智能体泛化到4个以上,注意力成本为线性。
核心机制
模型有三个互锁的部分。
首先,单纯形旋转智能体编码扩展了 3D RoPE,将每个智能体放置在旋转角度空间中正则单纯形的顶点上——想象3个智能体是三角形,4个智能体是四面体。
每个智能体获得独特的相位偏移,但所有智能体保持几何等价(排列对称)。
没有学习到的嵌入,没有固定顺序。
其次,稀疏枢纽注意力通过引入可学习的枢纽token来避免所有智能体之间的全对全注意力,这些枢纽token充当跨智能体通信的中介。
不是每个智能体都关注其他所有智能体(O(n²) 成本),而是每个智能体关注枢纽,枢纽再关注回智能体(O(n) 成本)。
把枢纽想象成在智能体之间路由消息的交换机操作员。
第三,因果蒸馏将全上下文扩散教师转换为学生,学生按时间块顺序生成视频,使用 KV 缓存来保持一致性。
教师一次看到所有帧;学生逐个生成帧块,以过去的块和当前动作为条件。
这使得动作响应式生成达到 24 FPS,而不是等待完整的扩散展开。
输入:多智能体动作 A_1, A_2, ..., A_n
   |
   v
[单纯形 RoPE] ---> 每个智能体获得几何相位
   |                (正则单纯形的顶点)
   v
[稀疏枢纽注意力]
   智能体token <---> 枢纽token <---> 智能体token
   (线性成本,非平方)
   |
   v
[因果学生模型]
   生成 block_t | block_<t, actions_t
   (KV 缓存保持一致性)
   |
   v
输出:所有智能体可控的视频帧
把这想象成一个电话会议系统。
在朴素设置中,每个参与者(智能体)都需要与其他每个参与者建立直接连线——那是 O(n²) 条电话线。
单纯形 RoPE 就像根据每个参与者在几何桌子周围的位置给他们一个独特的分机号,这样系统无需名牌就知道谁是谁。
稀疏枢纽注意力是会议桥接:不是 n² 个直接连接,而是每个人都拨入一个中央枢纽(交换机),由它路由消息。
枢纽不需要理解内容——它只需要在正确的各方之间传递token。
因果蒸馏就像从录制整个会议然后事后编辑(扩散教师)切换到带有轻微延迟缓冲的实时流式传输(带 KV 缓存的因果学生)。
缓冲区让你在时间上保持连贯性,而无需等待整个会议结束。
关键概念
- 单纯形旋转编码:标准 RoPE(旋转位置嵌入)通过在角度空间中旋转token嵌入来编码空间位置——就像把坐标放在钟面上。
对于多智能体设置,你需要同时编码空间位置和智能体身份。
单纯形 RoPE 通过将每个智能体放置在正则单纯形(等边三角形的 n 维推广)的顶点上来实现这一点。
对于2个智能体,它们在线段的两端(相隔180°)。
对于3个智能体,它们在等边三角形的顶点(相隔120°)。
对于4个智能体,它们在四面体的顶点。
这给每个智能体在旋转空间中一个独特的相位偏移,但所有智能体保持几何等价——没有智能体是”特殊的”。
关键是,这是无参数的:没有学习到的嵌入,所以它可以泛化到未见过的智能体数量而无需重新训练。
- 稀疏枢纽注意力:在标准多智能体注意力中,每个智能体token都关注其他所有智能体的token,导致智能体数量的 O(n²) 复杂度。
稀疏枢纽注意力引入一小组可学习的枢纽token(把它们想象成中继站)。
每个智能体的token关注枢纽,枢纽再关注回所有智能体。
这将跨智能体注意力从平方降低到线性:不是 n 个智能体 × n 个智能体,而是 n 个智能体 × k 个枢纽,其中 k 是一个小常数(例如16)。
枢纽充当瓶颈,压缩和路由智能体之间的信息,类似于网络架构中路由器的工作方式。
- 实时展开的因果蒸馏:扩散模型生成高质量视频,但需要对所有帧进行迭代去噪,这使得它们对交互使用来说太慢。
这里的教师模型是一个全上下文扩散transformer,一次看到所有帧。
学生是一个因果模型,按时间块(例如一次4帧)顺序生成视频,以过去的块和当前动作为条件。
学生被训练来匹配教师的输出分布,但以自回归方式运行并使用 KV 缓存——它重用先前块中计算的键值对来保持时间一致性,而无需重新计算所有内容。
这就是实现 24 FPS 生成的原因:学生可以实时响应新动作,而教师需要重新生成整个序列。
框架转变
之前(基于槽位或密集):          之后(Gamma-World):

智能体1 --[学习槽位1]--\          智能体1 --[单纯形顶点1]--\
智能体2 --[学习槽位2]---+--> 模型  智能体2 --[单纯形顶点2]---+--[枢纽]---> 模型
智能体3 --[学习槽位3]--/          智能体3 --[单纯形顶点3]--/
                                 智能体4 --[单纯形顶点4]--/
- 槽位不泛化
- O(n^2) 跨智能体注意力           - 几何身份(无学习)
- 逐帧扩散                        - O(n) 枢纽中介注意力
                                 - 块式因果生成
从学习到的槽位身份到几何相位身份,核心转变是用无参数几何结构替换学习到的智能体表示,实现对更多智能体的零样本泛化。
专家评审
选题眼光:这是一个真实的缺口。
多智能体世界建模对多人游戏、多机器人仿真到真实、具身AI研究至关重要,但现有方法要么不可扩展(基于槽位),要么计算成本高得令人望而却步(密集注意力)。
这个问题位于世界模型和多智能体系统的交叉点——两者都是活跃领域,但它们的结合探索不足。
时机恰当:单智能体世界模型(Genie、GameNGen)正在成熟,下一个合乎逻辑的步骤是多智能体设置。
方法成熟度:单纯形编码很优雅——它是一个有原则的几何解决方案,而不是学习到的技巧。
然而,稀疏枢纽注意力感觉像是高效transformer的标准技巧(perceiver风格的瓶颈),不是新颖的洞见。
因果蒸馏是扎实的工程,但在概念上不新(它是将标准知识蒸馏应用于时间维度)。
真正的贡献是组合:展示几何编码 + 稀疏路由 + 因果生成一起工作用于多智能体世界建模。
话虽如此,我想看到关于枢纽token数量和单纯形维度扩展的消融实验——在8或16个智能体时会发生什么?
实验诚意:基线是公平的(基于槽位的 STEVE,密集注意力变体)。
2→4 玩家泛化令人印象深刻且有充分记录。
24 FPS 的声明有时间测量支持。
然而,实验仅限于虚拟游戏环境(Minecraft风格、赛车游戏)。
我想看到在真实世界多机器人数据集或具身AI基准上的结果,以评估超越合成领域的泛化能力。
视频质量指标(FVD、PSNR)是标准的,但没有关于感知可控性或智能体间一致性的用户研究——这些会加强声明。
此外,论文没有讨论失败案例:模型何时崩溃?
当智能体重叠或严重遮挡彼此时会发生什么?
写作功力:论文结构良好,写作清晰。
方法部分密集但完整。
然而,相关工作部分低估了与高效transformer(perceiver、linformer等)的联系——枢纽注意力本质上是一个 perceiver 瓶颈,承认这一点会帮助读者定位贡献。
实验部分可以使用失败分析小节。
补充材料很详尽,这很好,但一些关键消融(例如枢纽token数量)应该在主论文中。
判决:弱接收 — 扎实的工程贡献,带有巧妙的几何编码技巧,但新颖性更多在于组合而非单个组件。
2→4 泛化令人印象深刻,但我想看到扩展到8+智能体和真实世界领域,然后才能称之为强接收。
要点总结
几何身份编码:如果你正在构建任何具有多个可互换实体(智能体、对象、模态)的系统,考虑用几何方式而不是学习到的嵌入来编码它们的身份。
单纯形顶点是一个选项;其他正则多面体或群论结构也可以工作。
关键洞见:对称性约束可以替换学习到的参数,改善泛化。
多实体系统的枢纽中介注意力:当你有 n 个需要交互的实体时,不要默认使用全对全注意力。
引入一小组可学习的枢纽token来中介通信。
这是来自高效transformer(perceiver、linformer)的通用模式,适用于视觉之外——想想多智能体强化学习、多模态融合,或任何你有多个需要交换信息的”通道”的设置。
交互生成的因果蒸馏:如果你有一个高质量但缓慢的生成模型(扩散、自回归transformer),你可以将其蒸馏成一个更快的因果学生,该学生使用 KV 缓存按块生成。
技巧是训练学生匹配教师的分布,同时按顺序操作。
这对任何需要实时响应用户输入的交互应用都很有用(游戏引擎、机器人、交互式叙事)。
何时使用:如果你正在构建多智能体模拟、多人游戏引擎或多机器人协调系统,这个架构值得借鉴。
如果你在做单智能体任务或非交互生成,复杂性不值得——坚持使用更简单的模型。