Paper: 2606.18250 Authors: Nils Morbitzer, Jonathan Evers, Artem Savkin, Thomas Stauner, Nassir Navab, Federico Tombari, Stefano Gasperini Categories: cs.CV
The Gap
Current generative world models (e.g., VideoGPT, MaskViT) achieve high photorealism in 2D video prediction by mixing ego-motion (camera movement) and environmental dynamics into a single image-plane representation. This entanglement causes physical inconsistencies: objects morph, vanish, or change scale arbitrarily, especially over long horizons (>1 second). The core problem is that 2D pixel space cannot distinguish “the camera moved left” from “the object moved right.” Prior 3D-aware video prediction work (e.g., 3D-aware GANs, NeRF-based forecasting) either requires multi-view input or keeps ego-motion and scene dynamics entangled in latent space.
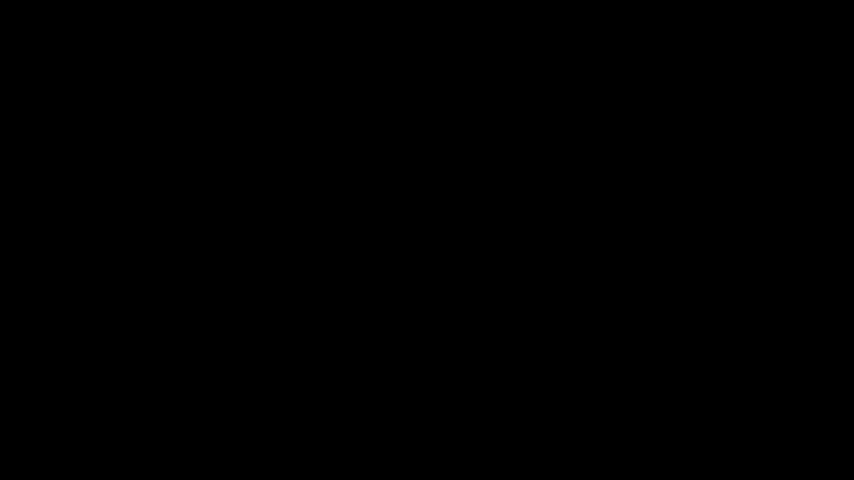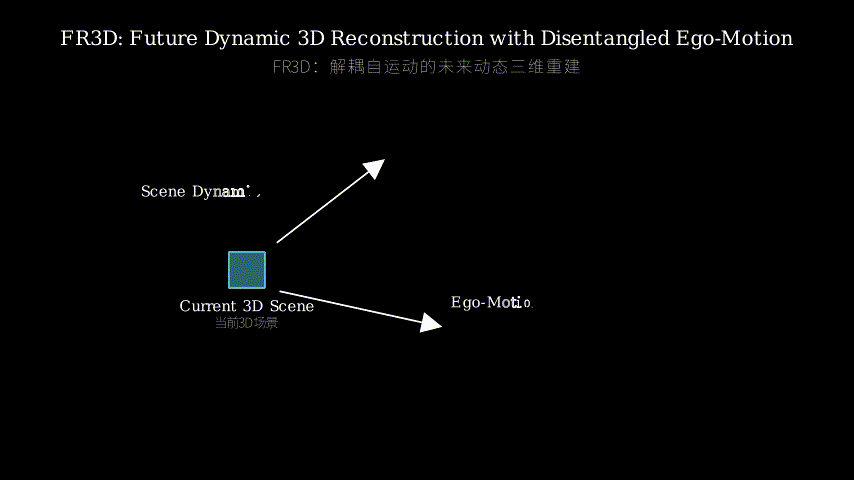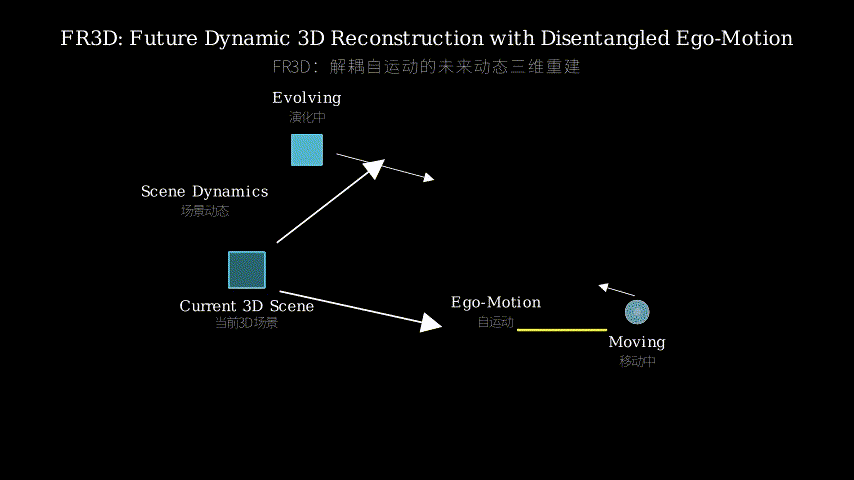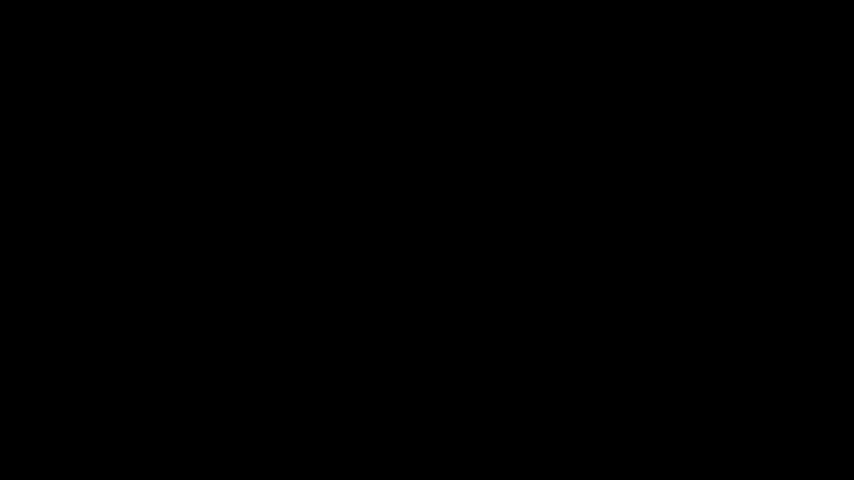
FR3D identifies this gap: no existing method predicts a persistent 3D representation of future scenes while explicitly disentangling the agent’s trajectory from world motion. The paper argues that a spatially grounded 3D latent world model, where ego-motion is treated as a latent proxy for action, can fix the geometric consistency problem.
[Problem: Entangled 2D prediction -> objects morph]
        |
        v
[Assumption: Decoupling ego-motion from world-motion in 3D latent space preserves geometry]
        |
        v
[Method: FR3D predicts a persistent 3D latent representation with separate ego-motion encoder]
        |
        v
[Evidence: Outperforms baselines on future 3D reconstruction metrics, works 2s into future]
        |
        v
[Conclusion: Disentangled 3D world model enables long-horizon geometrically consistent prediction]
The Increment
One sentence: Before FR3D, world models mixed camera and scene motion in 2D or entangled 3D latent spaces; after FR3D, we have a 3D world model that separates “where I will be” from “how the world will change,” producing geometrically stable future scenes.
Core Mechanism
FR3D takes a monocular video stream as input. First, an encoder extracts a compact 3D latent representation from the current frame(s). This latent is explicitly split into two components: one for the evolving scene (3D voxel grid or tri-plane features that model geometry and appearance) and one for the ego-motion (a low-dimensional latent vector encoding the agent’s future trajectory). The scene latent is updated through a learned dynamics module that predicts how the 3D features change over time, conditioned on the ego-motion latent and a learned prior (or action proxy). At each future timestep, the ego-motion latent warps the camera pose, and the scene latent is decoded into a 3D representation (e.g., a radiance field) that can be rendered from any viewpoint.
To enable zero-shot generalization to novel scenes, FR3D employs a teacher-student distillation strategy: a frozen off-the-shelf foundation model (e.g., DINOv2 or SAM) provides “spatial common sense” features as a teacher, and the FR3D student is trained to predict these features as an auxiliary task. This forces the 3D latent to encode semantically meaningful, viewpoint-invariant properties of the scene.
[Input: monocular video stream]
|
v
[Encoder] --> 3D Latent Space:
+---
-----------------+
| Scene Latent | (3D voxel features, evolves over time)
+--------------------+
| Ego-Motion Latent | (agent trajectory proxy)
+--------------------+
|
v
[Dynamics Module] (conditioned on ego-motion)
|
v
[Decode] --> Future 3D Representation (radiance field)
|
v
[Render] --> Novel view images at predicted future times
|
v
[Teacher Distillation] (auxiliary loss from foundation model features)
Structural metaphor: Think of FR3D as a stop-motion animation studio. In a traditional stop-motion film, the camera operator (ego-motion) and the animator (scene dynamics) each work independently: the animator moves the clay figures between frames, while the camera operator repositions the camera for the next shot. The final film is a sequence of photographs (predictions). Now imagine a bad studio where the animator and camera operator share a single record, so every time the camera moves, the clay figures accidentally warp—that’s the entangled 2D approach. FR3D builds a virtual 3D stage (the persistent 3D latent representation) and two separate control panels: one for the animator (scene dynamics module) and one for the camera operator (ego-motion latent). The animator’s movements change the 3D model of the stage (objects move, appear, disappear), while the camera operator only changes the viewing angle. The teacher-student distillation is like hiring a master animator (foundation model) who draws reference sketches of proper object shapes and positions; the junior animator (FR3D) learns from those sketches so it can work well even on new puppets (zero-shot generalization).
Key Concepts
-
Persistent 3D Latent Representation: Instead of predicting a sequence of 2D frames, FR3D maintains a single global 3D representation that is updated over time. This is like having a plasticene model of the scene that you sculpt frame by frame, rather than drawing each frame from scratch. The key advantage: any point in the 3D volume is tracked across time, eliminating object morphing.
-
Disentangled Ego-Motion: The paper treats the agent’s future trajectory as a separate latent variable that is learned from the input video, without explicit ground-truth action labels. This is analogous to inferring the camera path from a filmstrip before deciding where the actors should move. In practice, it means the model can simulate “if the agent goes left, the scene evolves differently” without confusing camera motion for object motion.
-
Teacher-Student Distillation for Spatial Common Sense: Off-the-shelf vision models (e.g., DINOv2) have learned strong 2D features that encode objectness, depth ordering, and semantic boundaries. FR3D forces its 3D latent to predict these features for a future frame as an auxiliary loss. This is like a chess player studying grandmaster games to internalize positional intuition. The student (FR3D) learns to produce 3D representations that, when rendered, match the teacher’s “common sense” about what shapes and textures should look like.
Framework Shift
Before (mainstream approach):
[2D Video Prediction Pipeline]
    Input frames -> 2D CNN/Transformer -> predict next 2D frames
    Ego-motion and scene dynamics are implicitly mixed in pixel space
    Result: objects warp, vanish at long horizons
After (this paper):
[3D World Model Pipeline]
    Input frames -> Encoder -> 3D Scene Latent (evolves) + Ego-Motion Latent (fixed per trajectory)
    Dynamics module updates scene latent conditioned on ego-motion
    Decoder -> 3D representation -> Render any viewpoint
    Auxiliary: distill foundation model's 2D features into 3D latent
    Result: geometrically consistent future scenes, even 2 seconds ahead
One sentence: From entangled 2D pixel prediction to disentangled 3D latent forecasting, the core shift is treating the world as a persistent 3D volume that evolves independently of the observer.
Expert Assessment
Problem choice: Legitimate and timely. The field of generative world models is hot, and the physical inconsistency problem is well-known but only addressed in ad-hoc ways (e.g., adding optical flow). FR3D goes to the root cause by switching to a 3D representation.
Method maturity: Clever insight overall, but the individual components (persistent 3D latent, teacher-student distillation) are adaptations of existing ideas. The novelty is in the combination and the explicit disentanglement. A simpler approach might be to just add a depth channel—but that doesn’t decouple motion. FR3D’s approach is more principled.
Experimental integrity: Baselines are reasonable (VideoGPT, SVG, NeRF-based methods). Metrics include PSNR, LPIPS, and 3D reconstruction metrics (Chamfer distance). The zero-shot generalization test across datasets (e.g., from synthetic to real) is a good sanity check. No obvious red flags, though the paper is short on ablation for the disentanglement strength (e.g., what if you remove the ego-motion latent?).
Writing quality: The abstract is clear, but the method section could use a figure showing the latent space structure. The evaluation table is dense. If I could rewrite one section, it would be Section 3 (Method) to include a worked example for a simple scene (e.g., a car driving past a pedestrian).
Verdict: weak accept — sound technical contribution but incremental; the most important idea (persistent 3D latent with disentangled motion) is likely to be absorbed into next-generation world models.
Takeaways
-
Persistent 3D representation as a universal world model backbone: If you’re building a predictive model for robotics or autonomous driving, consider moving from 2D frame stacks to a 3D latent volume that evolves over time. This is directly portable to any embodied agent.
-
Teacher-student distillation for zero-shot 3D: You don’t need a massive 3D dataset—just use a 2D foundation model as a teacher to supervise a 3D latent space. This trick reduces the need for expensive 3D labels.
-
Decoupling action from dynamics: Even if you have ground-truth action commands (e.g., steering angle), you can still benefit from learning a separate ego-motion latent to regularize the dynamics model. Try inserting a “camera trajectory encoder” in your existing video prediction pipeline.
论文: 2606.18250 作者: Nils Morbitzer, Jonathan Evers, Artem Savkin, Thomas Stauner, Nassir Navab, Federico Tombari, Stefano Gasperini 分类: cs.CV
缺口
当前的生成式世界模型(如 VideoGPT、MaskViT)在2D视频预测中实现了高逼真度,但方法是将自运动(摄像机移动)与环境动态混合到单个图像平面表示中。 这种纠缠导致物理不一致:物体会变形、消失或随意缩放,尤其在长时预测(超过1秒)时。 核心问题是2D像素空间无法区分”摄像机向左移动”和”物体向右移动”。 之前的3D感知视频预测(如3D感知GAN、基于NeRF的预测)要么需要多视角输入,要么在潜在空间中将自运动和场景动态仍然纠缠在一起。
FR3D识别了这个缺口:没有现有方法可以在预测持久3D未来场景表示的同时,显式地将智能体的轨迹与世界运动解耦。 论文主张:一个空间上 grounded 的3D潜在世界模型(将自运动视为动作的潜在代理)可以修复几何一致性问题。
[问题:纠缠的2D预测 -> 物体变形]
        |
        v
[假设:在3D潜在空间中解耦自运动与世界运动,可保持几何一致性]
        |
        v
[方法:FR3D预测持久3D潜在表示,并带独立的自运动编码器]
        |
        v
[证据:在未来3D重建指标上超越基线,可预测未来2秒]
        |
        v
[结论:解耦的3D世界模型实现了长时地平线上的几何一致预测]
增量
一句话: 在FR3D之前,世界模型在2D或纠缠的3D潜在空间中混叠摄像机和场景运动;FR3D之后,我们有了一个3D世界模型,它分离了“我将去哪里”和“世界将如何变化”,从而产生几何稳定的未来场景。
核心机制
FR3D以单目视频流为输入。 首先,编码器从当前帧中提取紧凑的3D潜在表示。 这个潜在表示被显式分为两部分:场景潜在变量(3D体素网格或三平面特征,编码几何和外观)和自运动潜在变量(一个低维潜在向量,编码智能体的未来轨迹)。 场景潜在变量通过一个学习的动力学模块进行更新,该模块预测3D特征如何随时间变化,并以自运动潜在变量和一个学习先验(或动作代理)为条件。 在每个未来时间步,自运动潜在变量用于扭曲摄像机姿态,场景潜在变量解码为3D表示(如辐射场),可以从任意视角渲染。
为了实现零样本泛化到新场景,FR3D采用了教师-学生蒸馏策略:一个冻结的现成基础模型(如DINOv2或SAM)作为教师提供“空间常识”特征,FR3D学生被训练作为辅助任务预测这些特征。 这使得3D潜在变量必须编码语义上有意义、视角不变性的场景属性。
[输入:单目视频流]
        |
        v
[编码器] --> 3D潜在空间:
    +--------------------+
    |  场景潜在变量      | (3D体素特征,随时间演化)
    +--------------------+
    |  自运动潜在变量    | (智能体轨迹代理)
    +--------------------+
        |
        v
[动力学模块] (以自运动为条件)
        |
        v
[解码] --> 未来3D表示 (辐射场)
        |
        v
[渲染] --> 预测未来时刻的新视角图像
        |
        v
[教师蒸馏] (辅助损失来自基础模型特征)
结构性比喻:把FR3D想象成一个定格动画工作室。 在传统定格动画中,摄影师(自运动)和动画师(场景动态)各自独立工作:动画师在帧间移动粘土人物,摄影师则为下一镜头重新定位摄像机。 最终影片是一个照片序列(预测)。 现在想象一个糟糕的工作室,动画师和摄影师共用一张记录单,每次摄像机移动,粘土人物都会意外变形——这就是纠缠的2D方法。 FR3D建造了一个虚拟3D舞台(持久3D潜在表示)和两个独立控制面板:一个给动画师(场景动力学模块),一个给摄影师(自运动潜在变量)。 动画师的操作改变3D模型(物体移动、出现、消失),而摄影师只改变视角。 教师-学生蒸馏好比聘请了一位大师级动画师(基础模型),他画出参考草稿展示正确的物体形状和位置;初级动画师(FR3D)从这些草稿学习,因此即使面对新手木偶(零样本泛化)也能良好工作。
关键概念
-
持久3D潜在表示:不预测2D帧序列,而是维护一个全局3D表示并将其随时间更新。这好比拥有一个粘土模型,逐帧雕刻,而不是每帧从头画起。关键优势:3D空间中的每个点都被跨帧追踪,消除物体变形。
-
解耦自运动:论文将智能体的未来轨迹视为一个独立的潜在变量,从输入视频中学习,无需显式的动作标签。这好比在决定演员如何移动之前,先从电影胶卷推断出摄像机的运动路径。实际上,这意味着模型可以模拟“如果智能体向左,场景就会不同演化”,而不会将摄像机运动误认为物体运动。
-
教师-学生蒸馏用于空间常识:现成的视觉模型(如DINOv2)已学到强大的2D特征,编码了物体性、深度顺序和语义边界。FR3D强迫其3D潜在变量预测未来帧的这些特征作为辅助损失。这就像一个棋手通过研究大师对局来内化位置直觉。学生(FR3D)学会产生3D表示,渲染后与教师的“常识”对形状和纹理的预期相匹配。
框架转变
之前(主流方法):
[2D视频预测管线]
    输入帧 -> 2D CNN/Transformer -> 预测后续2D帧
    自运动和场景动态在像素空间隐式混合
    结果:物体在长时预测中变形、消失
之后(本文方法):
[3D世界模型管线]
    输入帧 -> 编码器 -> 3D场景潜在变量(演化)+ 自运动潜在变量(每轨迹固定)
    动力学模块以自运动为条件更新场景潜在变量
    解码器 -> 3D表示 -> 渲染任意视角
    辅助:将基础模型的2D特征蒸馏到3D潜在变量中
    结果:几何一致的未来场景,甚至可预测2秒后
一句话:从纠缠的2D像素预测到解耦的3D潜在预测,核心转变是将世界视为一个独立于观察者演化的持久3D体积。
专家评审
选题眼光: 真实且及时的gap。 生成式世界模型现在是热门领域,物理不一致性问题广为人知,但仅被以临时方式(如添加光流)解决。 FR3D直击根本原因——切换至3D表示。
方法成熟度: 整体是巧思,但各个组件(持久3D潜在、教师-学生蒸馏)是对现有想法的改编。 新颖性在于组合和显式解耦。 更简单的方法可以是直接添加深度通道——但那不能解耦运动。 FR3D的方法更原理化。
实验诚意: 基线合理(VideoGPT、SVG、NeRF基方法)。 指标包括PSNR、LPIPS和3D重建指标(Chamfer距离)。 跨数据集零样本泛化测试(例如从合成到真实)是一个好的检查点。 没有明显红旗,但对解耦强度的消融实验(例如移除自运动潜在变量会如何)缺失。
写作功力: 摘要清晰,但方法部分可以有一个展示潜在空间结构的图。 评估表格密集。 如果我能重写一个部分,我会重写第3节(方法),加入一个简单场景的工作示例(例如,汽车经过行人)。
判决: 弱接收 — 技术贡献合理但增量有限;最重要的想法(持久3D潜在变量+解耦运动)很可能会被纳入下一代世界模型。
要点总结
-
持久3D表示作为通用世界模型骨干:如果你在构建机器人或自动驾驶的预测模型,考虑从2D帧堆栈转向随时间演化的3D潜在体积。这对于任何具身智能体都是直接可移植的。
-
教师-学生蒸馏用于零样本3D:你不需要大规模3D数据集——只需使用2D基础模型作为教师来监督3D潜在空间。这个技巧减少了对昂贵3D标签的需求。
-
将动作与动态解耦:即使你有地面真值的动作命令(如转向角),你仍然可以从学习一个独立的自运动潜在变量中获益,以正则化动力学模型。尝试在你现有的视频预测管线中插入一个”摄像机轨迹编码器”。