Paper: 2608.09893 Authors: Congfeng Cao, Pengyu Zhang, Jelke Bloem Categories: cs.AI, cs.CL
The Gap
Everyone shipping a frontier model in the last year has converged on the same product decision: one model, two modes. Qwen3 has /think and /no_think. Claude has extended thinking toggles. DeepSeek-R1 lineage models got merged back into chat checkpoints. The engineering motivation is obvious — you don’t want to pay for 8,000 reasoning tokens to answer “what’s 2+2”, and you don’t want to serve two sets of weights.
But look at how those systems were actually built. The technical reports say things like “we mixed thinking and non-thinking data in stage 3 of post-training” and then move on. The mixing ratio is a footnote. The ordering — do you teach the model to reason first and then teach it to be terse, or the reverse, or both at once — is usually not mentioned at all. It is treated as a plumbing detail, chosen by internal ablation that never gets published.
That’s the gap this paper walks into. Not “can we build a hybrid model” (solved, repeatedly) but “what actually happens inside the training when you do.” The specific unknowns: (1) is the interaction between the two modes symmetric — does adding thinking data hurt non-thinking as much as the reverse? (2) does the schedule (sequential vs. mixed) change the trade-off, and is there one best schedule? (3) can you put a number on the tension, so a practitioner can predict the cost of adding terse data?
The prior work they’re pushing against falls into three buckets. Chain-of-thought / long-reasoning distillation work (s1, LIMO, the R1-distill family) optimizes purely for reasoning accuracy and doesn’t care about token economy. Efficiency-oriented work (adaptive reasoning, budget forcing, router-based approaches) tries to decide when to think, but usually assumes the two capabilities are already there and doesn’t study how they were trained together. Multi-task / catastrophic-forgetting literature has the right tools (task interference, replay ratios) but hasn’t been pointed at this specific pair of modes, where the two “tasks” share the same inputs and the same correct answers — only the output length and structure differ.
   PROBLEM
   [ Hybrid think/no-think models are shipped everywhere,
     but ratio and schedule are undocumented folklore ]
                    |
                    v
   ASSUMPTION
   [ The two modes are not independent skills;
     they compete for the same output distribution ]
                    |
                    v
   METHOD
   [ Fusion Bench: grid over data ratio R = think:no-think
     x 3 schedules (think-first / no-think-first / mixed)
     on math SFT, evaluate both modes separately ]
                    |
        +-----------+-----------+
        v                       v
   EVIDENCE A               EVIDENCE B
   [ Asymmetry:            [ Schedule x ratio
     more no-think           interaction: best
     -> think acc drops;     schedule flips as
     reverse effect          R changes ]
     much weaker ]
        |                       |
        +-----------+-----------+
                    v
   QUANTIFY
   [ Negative correlation coefficient between
     no-think supervision volume and think acc ]
                    |
                    v
   CONCLUSION
   [ TMF is a trade-off, not a free lunch.
     Pick ratio first, then schedule to match. ]
The Increment
One sentence: Before this paper, the think/no-think mixing ratio was a hyperparameter people tuned privately and reported as a single number; after it, we have a public benchmark showing the interaction is *asymmetric — terse supervision damages reasoning more than reasoning supervision damages terseness — and that the best training schedule depends on the ratio you chose.
Core Mechanism
The “method” here is really an experimental apparatus, so let me describe it as one. The setup starts from a base instruction model and a math corpus where each problem has two supervision targets: a long chain-of-thought trace ending in the answer, and a direct short answer with minimal or no intermediate steps. Crucially the questions overlap — the same problem can appear in both forms. Mode selection at inference is controlled the way production systems do it: a system-prompt flag or special token that conditions the model’s output style.
The two knobs. The data ratio R is the proportion of thinking to non-thinking examples in the SFT mixture — they sweep several points from thinking-heavy to non-thinking-heavy. The training schedule is the temporal arrangement of that same data: think-first-then-no-think (sequential), no-think-first-then-think (reverse sequential), and fully interleaved/shuffled (mixed). The key design point is that ratio and schedule are crossed, so total data volume is held roughly constant while you vary *what fraction and in what order. Then each resulting checkpoint is evaluated twice — once with the thinking flag on, once off — on held-out math benchmarks, giving two accuracy numbers per cell of the grid.
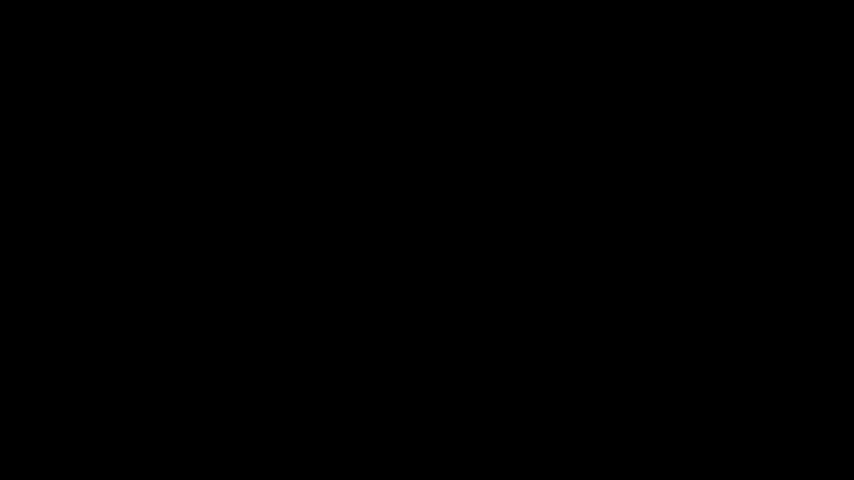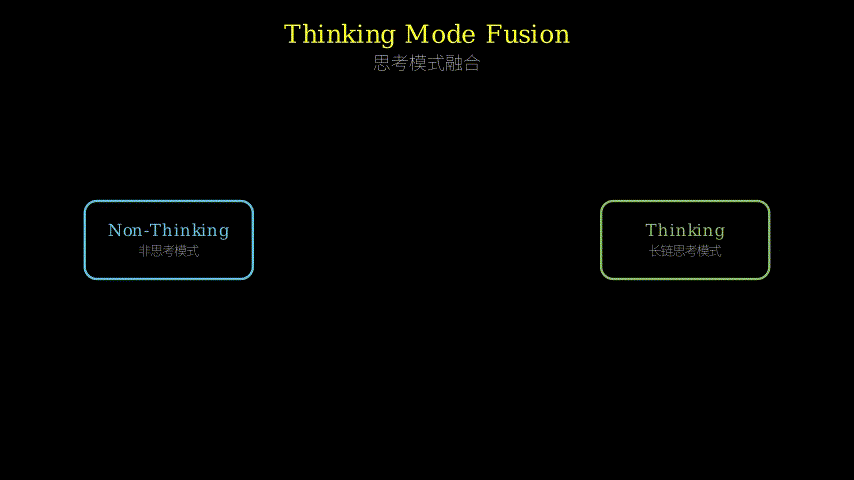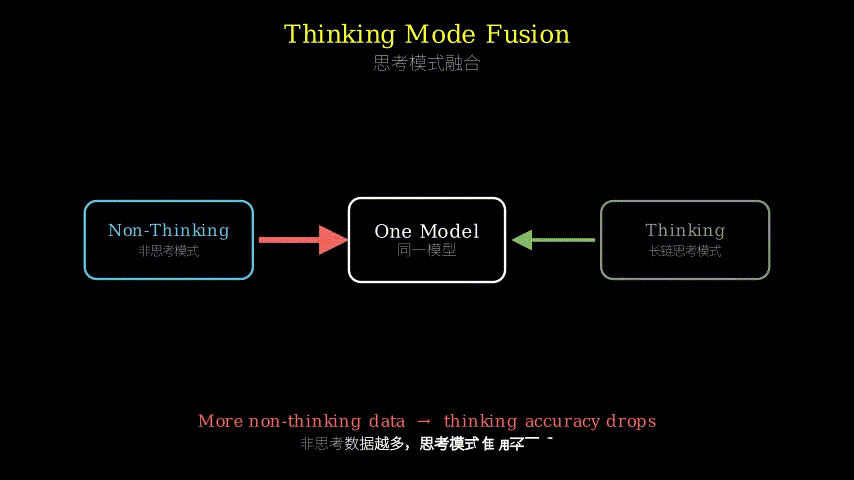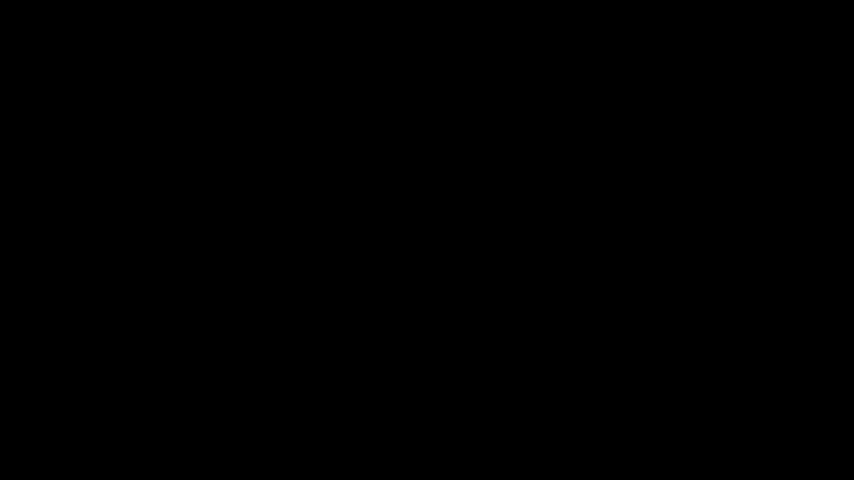
What comes out is a response surface rather than a single winner. The dominant finding is asymmetry: as you push R toward non-thinking, thinking-mode accuracy degrades monotonically, while non-thinking accuracy is comparatively robust to how much thinking data you add. In other words, the two modes are not symmetric neighbors sharing a house — one is a bully. Sequential schedules behave differently from mixed depending on where you sit on the ratio axis, which is why “just shuffle everything” isn’t a universal answer. Finally they fit the relationship between non-thinking supervision volume and thinking accuracy and report it as a negative correlation, turning folklore into a slope you can plan around.
                    SAME MATH QUESTIONS
                            |
            +---------------+---------------+
            v                               v
    [ long CoT target ]              [ short answer target ]
    "let me work it out.              "42"
     step 1... step n.
     answer: 42"
            |                               |
            +-------- ratio R ------+-------+
                                    |
                    +---------------+---------------+
                    |               |               |
                    v               v               v
             SCHEDULE A       SCHEDULE B      SCHEDULE C
             [think][no]      [no][think]     [ mixed ]
                    |               |               |
                    +---------------+---------------+
                                    |
                                    v
                          ONE SET OF WEIGHTS
                       (mode flag in system prompt)
                                    |
                    +---------------+---------------+
                    v                               v
              eval flag=ON                    eval flag=OFF
              think accuracy                  no-think accuracy
                    |                               |
                    +---------------+---------------+
                                    v
                       RESPONSE SURFACE over (R, schedule)
                       ~ asymmetric: think acc is the
                         fragile axis
The metaphor: think of a bilingual child raised by two parents who speak different dialects of the same language.
The questions are the world — the same objects, same facts, same truths to talk about. Parent A speaks in full elaborate sentences with explicit reasoning (“well, if we have four apples and we take two, and two is half of four, then…”). Parent B speaks in clipped answers (“two”). Both are correct about the world; they differ only in output form. The data ratio is how many hours a week the child spends with each parent. The schedule is whether the child lives with A for the first five years then moves to B, or the reverse, or bounces between houses daily.
Now the finding becomes intuitive. Clipped speech is a simpler, lower-cost policy — it’s an attractor. Every hour with Parent B teaches the child not just “how to be brief” but implicitly “elaboration is unnecessary here,” and that lesson bleeds into the elaborate register. Meanwhile hours with Parent A don’t damage brevity much, because a child who can explain can still say “two” when asked. That’s the asymmetry: brevity is contagious, elaboration is not. And the schedule matters because recency matters — whoever the child lived with last shapes the default register, which is why the winning order depends on how lopsided the hours were in the first place. If you barely spent time with A at all, you’d better have spent it last.
Key Concepts
-
Thinking Mode Fusion (TMF): Suppose you have two models — one that always writes out long reasoning, one that always answers in a sentence. Serving both means double the GPU memory and a router in front. TMF is the trick of putting both behaviors into *one set of weights and selecting between them with a flag in the prompt, the way a single actor plays two characters depending on the stage direction. The model learns a conditional policy: “if flag says think, produce a long trace; else produce the answer.” The catch, which this paper is entirely about, is that the actor’s two characters leak into each other during rehearsal.
-
Asymmetric mode interference: In multi-task learning you usually assume interference is roughly mutual — task A hurts B, B hurts A, and you balance them. Here it isn’t. Concretely: going from a thinking-heavy mixture to a non-thinking-heavy one costs you real points on math accuracy in thinking mode, but the reverse move barely moves non-thinking performance. Intuition for why: a short-answer target is, from a token-prediction standpoint, an instruction to *stop early. Gradient signal that says “the answer comes right after the question” is directly at war with the long-horizon habit that reasoning requires. But signal that says “elaborate” doesn’t forbid brevity — it’s an added capability, not a subtracted one. So the ratio dial is not symmetric: pushing it one way is cheap, the other way is expensive.
-
Schedule x ratio interaction: The point that saves this from being a one-line paper. It’s tempting to ask “what’s the best training order?” and expect one answer. Instead the answer changes sign depending on the mixture. If thinking data is scarce, putting it last (so it’s the most recent thing the model learned) protects it; if thinking data dominates, interleaving avoids the model drifting into always-elaborate mode. Analogy: whether you should study your weakest subject first or last depends on how much total time you gave it. There is no schedule you can recommend without knowing the ratio — which is exactly why publishing a single ratio number, as the big tech reports do, is insufficient information for anyone to reproduce.
Framework Shift
Before (mainstream approach):        After (this paper):

  [ think data ]                       ratio axis R
        \                          thin <-----------> thick
         \                       +---+---+---+---+---+
          v                    A | . | . | * | + | + |   A = think-first
   [ mix at ratio r ]            +---+---+---+---+---+   B = no-think-first
          |                    B | + | * | . | . | . |   C = mixed
          ^                      +---+---+---+---+---+
         /                     C | . | + | + | * | . |
        /                        +---+---+---+---+---+
  [ no-think data ]
        |                        * = best cell, moves with R
        v                        no single winning row
   [ one model ]
        |                        plus: measured slope
        v                        d(think acc) / d(no-think vol) < 0
   "works! ship it"              and |slope| >> reverse direction
   r reported as a footnote      => cost of terseness is quantified
One sentence: from “mix the two modes at some ratio and ship the model that works” to “the two modes are in measurable, asymmetric competition, so ratio and schedule must be chosen jointly and the reasoning side is the one you’ll pay for.”
Expert Assessment
Problem choice: Real gap, and a slightly embarrassing one for the field. Hybrid-mode models are the default product shape now, and the recipe details genuinely are undocumented — every lab has an internal ablation table that never ships. Somebody should publish that table. The framing is also correctly positioned: it treats this as a task-interference problem rather than an efficiency problem, which is the more useful lens and connects to a large existing literature. The risk is that the finding is *unsurprising. “Training on short answers makes your model answer short” is something most practitioners would guess. The value is in the asymmetry being measured and in the schedule interaction, which is genuinely less predictable. Whether that’s enough increment depends on how much you value converting folklore into numbers — I’d argue reasonably high, because right now people are guessing.
Method maturity: Honestly, brute force — and that’s mostly fine, because this is a measurement paper, not a method paper. The grid over (ratio, schedule) is the obvious design and the right one. What’s missing is any mechanistic follow-through. The abstract stops at “we quantify a negative correlation,” which is a correlational statement about a training curve, not an explanation. The obvious cheap extensions are conspicuously absent from the abstract: is the degradation a length-distribution collapse (does thinking mode simply produce shorter traces as R shifts, and is the accuracy drop fully explained by truncated reasoning)? Does per-mode loss weighting or LoRA-style parameter separation dissolve the trade-off? Does the asymmetry survive at RL stage, or is it an SFT artifact? Any one of those would turn a descriptive finding into a causal one. Also, “negative correlation” over a handful of ratio points is a weak statistical object — I’d want to know how many points, with what seed variance.
Experimental integrity: Can’t fully judge from the abstract, and that itself is a flag — the abstract names no base models, no benchmarks, no scale range. For a paper whose entire contribution is empirical, that’s a lot of load-bearing detail deferred. The things I’d check first: (1) is this one base model or several? A ratio finding on a single 7B checkpoint is a case study, not a law, and mode interference plausibly weakens with scale as capacity frees up. (2) Is data volume truly held constant across cells, or does the thinking-heavy arm see more *tokens (long traces!) and thus more compute? Token-matched vs. example-matched is a real confound here, and the direction of the bias would favor exactly the finding they report. (3) Math-only. Math is the domain where reasoning helps most, so it’s the domain where the trade-off should look worst — plausible that the asymmetry is milder in code or general chat. Releasing code and data is a genuine plus and makes these checkable, which counts for something.
Writing quality: The abstract is structurally clean but does the classic empirical-paper thing of announcing findings without their magnitudes — “reduces the accuracy,” “modulate this trade-off,” “negative correlation” with no numbers anywhere. A reader can’t tell if this is a 2-point effect or a 20-point effect, and those imply completely different engineering decisions. The section that would elevate the paper most is a mechanism/diagnostics section: put the thinking-mode output length distribution next to the accuracy curve, show whether errors are reasoning failures or premature termination, and the paper goes from “here’s a table” to “here’s why.” Second-best fix: a practitioner-facing recipe box — given your target ratio, here’s the schedule — stated crisply enough that someone can act on it without reading the grid.
Verdict: weak accept — a real, underdocumented question answered with a sound if unglamorous grid study, valuable mainly as a public benchmark and a calibration on how much terseness costs reasoning; held back by a single-domain setup, an unclear compute/token-matching story, and stopping at correlation where a mechanism was within reach.
Takeaways
Things you can actually use:
Treat brevity as an intrusive capability, not a neutral one. The transferable framing: when two output styles share the same inputs, the *shorter one is an attractor and will leak into the longer one. This should change how you mix data anywhere you have a terse mode and a verbose mode in one model — structured JSON output vs. free-form explanation, summarization vs. full report, terse code vs. commented code. Budget your ratio asymmetrically: protect the expensive behavior, because the cheap behavior defends itself.
Recency is a lever you already have and probably aren’t using. The schedule finding says: whichever capability is scarce in your mixture, put it *last. That’s free — no architecture change, no extra data, just reordering your SFT shards. Worth an ablation on your own pipeline the next time you fuse behaviors.
Never report a mixing ratio without the schedule. The interaction result means a ratio number alone is not reproducible information. If you write a tech report, state both. If you read one that states only the ratio, know that you cannot replicate it.
A diagnostic to steal. Always evaluate *both modes on the same held-out set after fusion, and track thinking-mode output length alongside accuracy. Most teams eval the mode they care about and spot-check the other. The interference here is exactly the kind of regression that per-mode eval catches and aggregate eval hides.
And one honest caveat: the headline number is domain-specific. Don’t import their optimal ratio into your non-math setting — import the *method of finding it, which is a 3x5-ish grid and a weekend of GPU time.
论文: 2608.09893 作者: Congfeng Cao, Pengyu Zhang, Jelke Bloem 分类: cs.AI, cs.CL
缺口
过去一年发布旗舰模型的团队,几乎都做了同一个产品决策:一套权重,两种模式。
Qwen3 有 /think 和 /no_think,Claude 有扩展思考开关,DeepSeek-R1 系的推理能力最终也被合回了对话版本。
动机很朴素:回答「2+2 等于几」不该烧掉八千个思考 token,而且没人愿意同时部署两份权重。
但看看这些系统实际是怎么造出来的。 技术报告里往往只有一句「我们在后训练第三阶段混入了思考与非思考数据」,然后就翻过去了。 混合比例是个脚注。 训练顺序——先教推理再教简答,还是反过来,还是从头混着——常常压根没提。 这被当成管道细节,靠内部消融实验拍板,而那张表永远不会公开。
这篇论文钻的就是这个洞。 不是「能不能做出双模式模型」(这个已经反复被解决了),而是「你这么训练的时候,模型内部到底发生了什么」。 具体的未知量有三个:(1)两种模式的相互干扰是对称的吗——加思考数据伤非思考,和加非思考数据伤思考,代价一样吗? (2)训练顺序(顺序训练 vs 混合训练)会改变这个权衡吗,存在一个通用最优顺序吗? (3)能不能给这个张力标个数,让工程师能预估「多加一批简答数据」的成本?
它要顶的前人工作分三类。 长链推理蒸馏这一路(s1、LIMO、R1-distill 系列)只优化推理准确率,不管 token 经济性。 效率导向这一路(自适应推理、budget forcing、路由方案)研究「何时该思考」,但通常假设两种能力已经存在,不研究它们是怎么一起被训出来的。 多任务学习与灾难性遗忘这一路有对的工具(任务干扰、回放比例),但没人把它对准这一对特殊的「任务」——两个任务的输入相同、正确答案也相同,只有输出的长度和结构不同。
   问题
   [ 双模式模型满街跑,但配比与训练顺序
     全是没有文档的口口相传 ]
                    |
                    v
   假设
   [ 两种模式不是独立技能,
     它们在争夺同一个输出分布 ]
                    |
                    v
   方法
   [ Fusion Bench: 数据配比 R = 思考:非思考
     x 3 种训练顺序(先思考 / 先简答 / 混合)
     数学 SFT,两种模式分别评测 ]
                    |
        +-----------+-----------+
        v                       v
   证据 A                   证据 B
   [ 不对称性:             [ 顺序 x 配比
     简答数据越多            存在交互: 最优
     -> 思考准确率降;        顺序随 R 变化
     反向效应弱得多 ]        而翻转 ]
        |                       |
        +-----------+-----------+
                    v
   量化
   [ 简答监督量 与 思考准确率
     之间的负相关系数 ]
                    |
                    v
   结论
   [ TMF 是权衡,不是免费午餐。
     先定配比,再配顺序。 ]
增量
一句话:这篇之前,思考/非思考的混合比例是各家私下调、只在报告里写一个数字的超参;这篇之后,我们有了一个公开基准,证明这个干扰是不对称的——简答监督对推理的伤害远大于反向——而且最优训练顺序取决于你选的配比。
核心机制
这里的「方法」本质是一套实验装置,我就照装置来讲。 起点是一个基础指令模型,加一份数学语料,每道题配两种监督目标:一条完整的长链推理(末尾给答案),和一个几乎没有中间步骤的直接答案。 关键在于题目是重叠的——同一道题可以以两种形态出现。 推理时的模式选择用的就是生产系统那套做法:system prompt 里的开关或特殊 token,条件化模型的输出风格。
两个旋钮。 数据配比 R 是 SFT 混合数据里思考样本与非思考样本的比例,他们从「思考为主」扫到「简答为主」取了若干点。 训练顺序是同一批数据在时间上的排列方式:先思考后简答(顺序)、先简答后思考(反向顺序)、完全打散交错(混合)。 设计上的要点是配比与顺序做了交叉,总数据量大致固定,变化的只是多少比例和什么顺序。 然后每个 checkpoint 评两遍——开思考开关一遍,关一遍——在留出的数学基准上跑,网格的每个格子得到两个准确率。
出来的结果是一张响应曲面,而不是一个赢家。 主结论是不对称:R 越往非思考方向推,思考模式准确率单调下降;而非思考准确率对「加多少思考数据」相对不敏感。 换句话说,两种模式不是和睦合租的邻居——其中一个是恶霸。 顺序训练与混合训练的优劣,取决于你在配比轴上处于哪个位置,所以「全部打散就完事」并不是通用答案。 最后他们把简答监督量与思考准确率的关系拟合成一个负相关,把口口相传变成了一条你可以据此做规划的斜率。
                    同一批数学题
                            |
            +---------------+---------------+
            v                               v
    [ 长链推理目标 ]                  [ 简答目标 ]
    "我来算一下:                      "42"
     第一步... 第 n 步.
     答案: 42"
            |                               |
            +------- 配比 R -------+--------+
                                   |
                    +--------------+---------------+
                    |              |               |
                    v              v               v
              顺序 A          顺序 B           顺序 C
             [思考][简答]    [简答][思考]      [ 混合 ]
                    |              |               |
                    +--------------+---------------+
                                   |
                                   v
                          一套权重
                    (模式开关放在 system prompt)
                                   |
                    +--------------+---------------+
                    v                              v
              开关 = ON                       开关 = OFF
              思考准确率                       简答准确率
                    |                              |
                    +--------------+---------------+
                                   v
                    (R, 顺序) 上的响应曲面
                    ~ 不对称: 思考准确率是脆弱的那一轴
核喻:把它想成一个孩子,被两位说同一种语言不同方言的家长带大。
题目就是这个世界——同样的物件、同样的事实、同样要谈论的真相。 家长 A 说话是完整铺陈的长句,把推理过程说透(「嗯,如果有四个苹果,拿走两个,而二是四的一半,那么……」)。 家长 B 只给短促的答案(「两个」)。 两位对世界的描述都正确,差别只在输出形式。 数据配比就是孩子每周分别和哪位家长待多少小时。 训练顺序就是:孩子是前五年跟 A 住、之后搬去 B,还是反过来,还是每天两边跑。
这样一来结论就直觉了。 短促表达是一种更简单、代价更低的策略——它是个吸引子。 每一小时跟 B 相处,教的不只是「怎么说简短」,还隐含地教了「这里不需要铺陈」,而这个教训会渗进铺陈那套语域里。 反过来,跟 A 相处的时间对简洁伤害不大,因为一个会解释的孩子,被问到时照样能只说「两个」。 这就是不对称:简洁会传染,铺陈不会。 而顺序之所以重要,是因为近因重要——孩子最后跟谁住,就决定了默认语域,这也解释了为什么最优顺序取决于两边时长本来有多悬殊。 如果你几乎没陪 A 待过,那你最好是最后才陪的。
关键概念
-
思考模式融合(TMF):假设你手上有两个模型,一个永远长篇推理,一个永远一句话作答。同时上线意味着双倍显存,前面还得挂个路由。TMF 就是把两种行为塞进一套权重,用 prompt 里的开关来切换——像一个演员按舞台提示扮两个角色。模型学的是一个条件策略:「开关说思考,就产出长推理;否则直接给答案。」问题恰恰是本文的全部主题:排练期间,这位演员的两个角色会互相串戏。
-
不对称的模式干扰:多任务学习里通常假定干扰大体互相:A 伤 B,B 也伤 A,你去做平衡。这里不是。具体说:从「思考为主」的混合改成「简答为主」,思考模式下的数学准确率会掉掉实打实的分;反向操作却几乎不动非思考的表现。为什么?从 token 预测的角度看,一个简答目标其实是一条「提前停下」的指令。「答案紧跟在问题后面」这个梯度信号,与推理所需的长程习惯是直接对立的。但「要铺陈」这个信号并不禁止简洁——它是能力的增项,不是减项。所以配比这个旋钮是不对称的:往一边拧便宜,往另一边拧很贵。
-
顺序 x 配比 的交互:正是这一点让本文不至于是一句话的结论。人们很容易问「哪种训练顺序最好」并期待一个答案。结果这个答案会随混合比例变号。思考数据稀少时,把它放在最后(成为模型最近学到的东西)能保护它;思考数据占主导时,交错混合能避免模型漂向「永远铺陈」。类比:你该先复习还是最后复习最弱的科目,取决于你总共给了它多少时间。也就是说,不知道配比就无法推荐顺序——这恰恰说明大厂技术报告里只给一个配比数字,对任何想复现的人来说信息是不完整的。
框架转变
之前(主流方法):                之后(本文方法):

  [ 思考数据 ]                      配比轴 R
        \                       薄 <-----------> 厚
         \                    +---+---+---+---+---+
          v                 A | . | . | * | + | + |   A = 先思考
   [ 按比例 r 混合 ]           +---+---+---+---+---+   B = 先简答
          |                 B | + | * | . | . | . |   C = 混合
          ^                   +---+---+---+---+---+
         /                  C | . | + | + | * | . |
        /                     +---+---+---+---+---+
  [ 简答数据 ]
        |                     * = 最优格子, 随 R 移动
        v                     不存在通吃的某一行
   [ 一个模型 ]
        |                     另加: 实测斜率
        v                     d(思考准确率) / d(简答数据量) < 0
   "能用! 发版"                 且 |斜率| >> 反方向
   r 只在脚注里写个数           => 简洁的代价被量化了
一句话:从「按某个比例把两种模式混起来,能跑就发版」,到「两种模式处于可测量的、不对称的竞争关系,配比与顺序必须联合选择,而要付代价的那一侧是推理」。
专家评审
选题眼光:真缺口,而且对整个领域来说有点尴尬。 双模式如今已是默认的产品形态,配方细节却确实没有文档——每家实验室都有一张永不出门的内部消融表。 总得有人把这张表发出来。 框架定位也对:它把问题当作任务干扰问题而非效率问题来处理,这是更有用的透镜,也接得上一大片既有文献。 风险在于结论不令人意外。 「用简答数据训练,模型就会答得短」是多数从业者能猜到的。 价值在于不对称性被测量出来了,以及顺序交互这一点确实不那么好猜。 这算不算足够的增量,取决于你多看重「把口口相传变成数字」——我倾向于评价偏高,因为现在大家确实在瞎猜。
方法成熟度:说实话是蛮力——但基本没问题,因为这是测量型论文,不是方法型论文。 (配比 x 顺序)的网格是最显然、也是对的设计。 缺的是机制层面的追问。 摘要停在「我们量化了一个负相关」,这是关于训练曲线的相关性陈述,不是解释。 几个便宜的延伸在摘要里明显缺席:这个下降是不是长度分布塌缩(随着 R 移动,思考模式是不是单纯产出了更短的推理,准确率下降能否被「推理被截断」完全解释)? 按模式加权 loss、或者 LoRA 式的参数分离,能不能把这个权衡化解掉? 这个不对称在 RL 阶段还成立吗,还是只是 SFT 的产物? 任意一条都能把描述性发现推成因果性发现。 另外,在少数几个配比点上谈「负相关」,统计上是个很弱的对象——我想知道点数是多少、seed 方差多大。
实验诚意:从摘要判断不了,而这本身就是个警示——摘要里没有基础模型名、没有评测集、没有规模范围。 对一篇全部贡献都是实证的论文,这是相当多的承重细节被推后了。 我会优先查三件事:(1)是一个基础模型还是多个? 单个 7B checkpoint 上的配比结论是案例研究,不是规律,而且模式干扰很可能随规模增大而减弱(容量腾出来了)。 (2)各格子的数据量真的对齐了吗,还是「思考为主」那一臂其实见了更多token(长推理啊!)从而吃了更多算力? token 对齐 vs 样本对齐在这里是个实打实的混淆项,而偏差方向恰好会支持他们报告的结论。 (3)只有数学。 数学恰恰是推理增益最大的领域,也就是这个权衡会显得最糟的领域;在代码或通用对话里不对称性可能温和得多。 公开代码和数据是真加分,让上述检查变得可做,这点值得肯定。
写作功力:摘要结构干净,但犯了实证论文的经典毛病:宣布结论却不给量级。 「降低了准确率」「调节这个权衡」「负相关」——全文找不到一个数。 读者无法判断这是 2 个点的效应还是 20 个点的效应,而这两者对应完全不同的工程决策。 最能提升整篇论文的一节是机制/诊断:把思考模式的输出长度分布和准确率曲线并排放,展示错误究竟是推理失败还是提前终止——论文就从「这是一张表」变成「这是为什么」。 次优的补法是一个面向工程师的配方框:给定你的目标配比,用哪个顺序,说得干脆到不看网格也能照做。
判决:弱接收 —— 一个真实且缺乏文档的问题,用一套扎实但不炫的网格实验回答了,主要价值在于公开基准与「简洁对推理收多少税」的校准;受限于单一领域、算力/token 对齐说不清、以及在机制唾手可得时停在了相关性。
要点总结
真能拿走用的东西:
把「简洁」当作侵入性能力,而不是中性能力。 可迁移的框架是:当两种输出风格共享同样的输入时,短的那个是吸引子,会渗进长的那个。 这应该改变你在任何「一个模型里既有简洁模式又有详尽模式」场景下的数据混合方式——结构化 JSON 输出 vs 自由解释、摘要 vs 完整报告、精简代码 vs 带注释代码。 配比要不对称地做预算:保护贵的那个行为,因为便宜的那个会自我防卫。
近因是你手上已有、但大概没在用的杠杆。 顺序那条结论翻译过来是:混合数据里哪种能力稀缺,就把它放最后。 这是免费的——不改架构、不加数据,只是重排 SFT 分片顺序。 下次做行为融合时,值得在自己的流水线上做一次消融。
报告混合比例时,永远带上训练顺序。 交互结论意味着一个孤立的配比数字不是可复现的信息。 你写技术报告,就把两者都写上;你读到只给配比的报告,就知道那是复现不了的。
一个可以偷的诊断习惯。 融合之后,务必在同一个留出集上评测两种模式,并且把思考模式的输出长度和准确率放在一起追踪。 多数团队只评自己在意的那个模式,另一个抽查一下。 这里的干扰恰恰是「按模式分开评测能抓住、聚合评测会掩盖」的那类退化。
还有一个诚实的告诫:头条数字是领域相关的。 不要把他们的最优配比直接搬到非数学场景——搬走的应该是找到它的方法,也就是一个大约 3x5 的网格加一个周末的 GPU 时间。