Paper: 2605.12497 Authors: Bokang Yang, Xinyi Sun, Kaituo Feng, Xingping Dong, Dongming Wu, Xiangyu Yue Categories: cs.CV
The Gap
Existing visual grounding and segmentation systems assume the target object’s identity is either directly visible in the image or already encoded in the model’s frozen knowledge. You point at a photo and say “find the red car” — the system knows what “red” and “car” mean, and the car is right there. This works for common objects and straightforward descriptions.
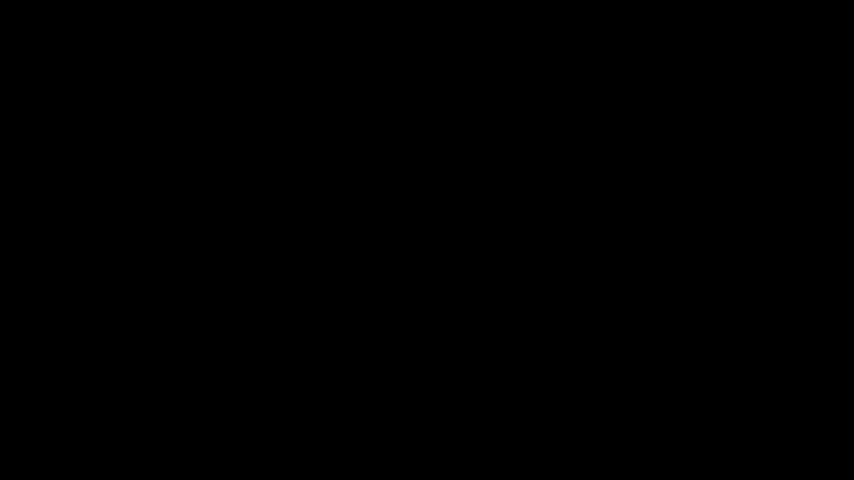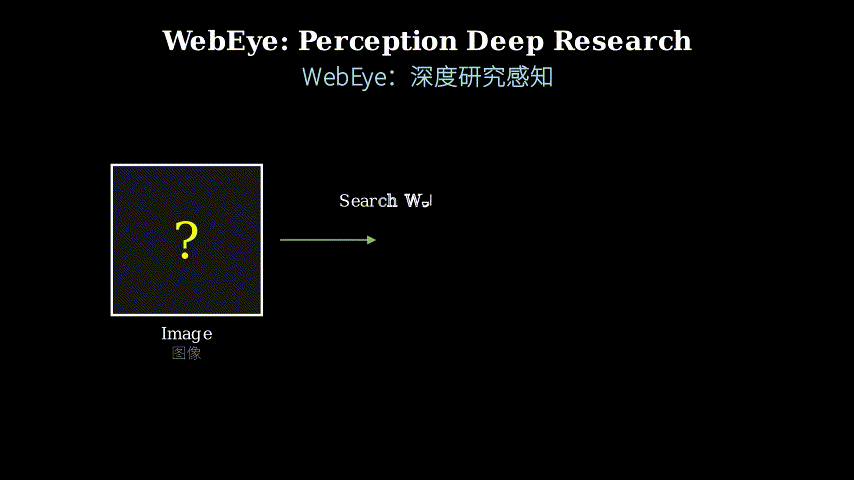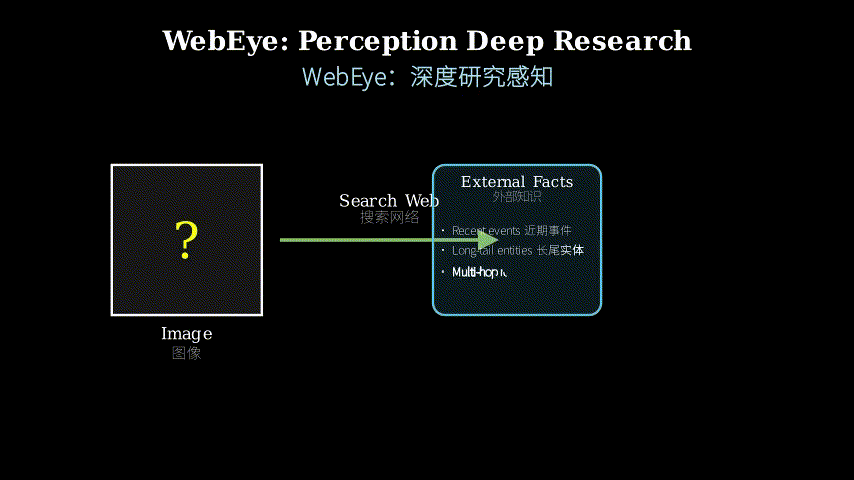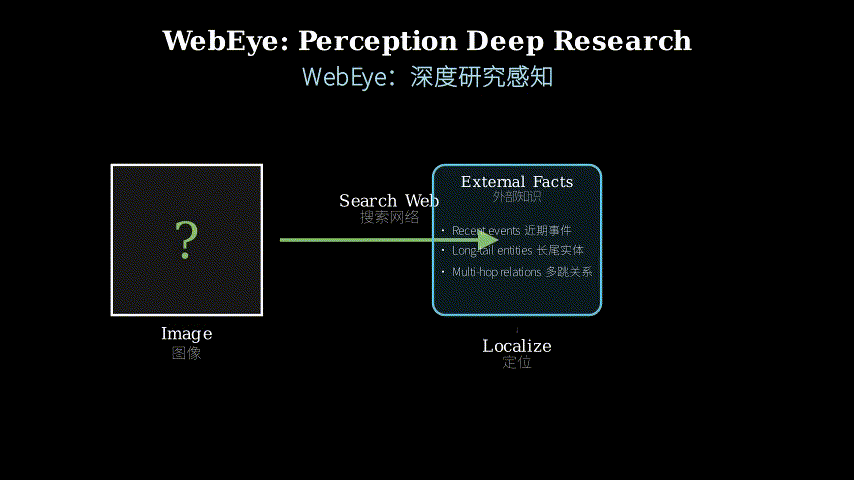
But what if you ask “find the company logo whose CEO just resigned yesterday”? The decisive evidence isn’t in the pixels. The model needs to first search the web for recent news, resolve which company that is, learn what their logo looks like, then return to the image and locate it. Prior work in referring expression comprehension, open-vocabulary detection, and visual question answering all operate within the closed-world assumption: everything needed to identify the target is either in the image or in pre-trained weights. They don’t handle knowledge-intensive queries requiring external fact retrieval, temporal reasoning about recent events, or multi-hop inference chains.
Problem: "Find X in this image"
   |
   v
Existing assumption:           This paper's reality:
X is visible + known    vs.    X requires external resolution
   |                              |
   v                              v
Direct perception              Search -> Resolve -> Perceive
   |                              |
   v                              v
Works for common objects       Handles knowledge-intensive queries
The Increment
One sentence: Before this paper, visual perception stopped at the image boundary; after it, perception can reach through the web to resolve hidden identities before grounding them in pixels.
Core Mechanism
WebEye introduces two components: a benchmark and a method. The benchmark, called WebEyes (plural), contains 120 images with 473 annotated objects where identification requires external knowledge — things like “the flag of the country that won the most recent World Cup” or “the logo of the company mentioned in today’s tech news.” Each query comes with verifiable evidence chains, precise bounding boxes or segmentation masks, and three task formulations: Search-based Grounding (output a box), Search-based Segmentation (output a mask), and Search-based VQA (output a grounded answer).
The method, Pixel-Searcher, is an agentic workflow with three stages. First, evidence acquisition: given a query and image, it decomposes the query into search-friendly sub-questions, retrieves web documents, and extracts relevant facts. Second, identity resolution: it synthesizes the retrieved evidence to determine what the target actually is (e.g., “Argentina won the 2022 World Cup, so the target is the Argentine flag”). Third, visual instance binding: it takes the resolved identity back to the image and uses a vision-language model to localize the corresponding object via box, mask, or answer generation.
Input: Image + Query ("Find the logo of X's parent company")
   |
   +---> [Evidence Acquisition]
   |        |
   |        +-> Decompose query into sub-questions
   |        +-> Web search for each sub-question
   |        +-> Extract relevant facts from documents
   |        |
   |        v
   |     Retrieved facts: "X was acquired by Y in 2023"
   |
   +---> [Identity Resolution]
   |        |
   |        +-> Synthesize facts into target identity
   |        |
   |        v
   |     Resolved identity: "Y's logo"
   |
   +---> [Visual Instance Binding]
            |
            +-> Locate "Y's logo" in image
            +-> Generate box / mask / answer
            |
            v
         Output: Grounded result
Think of Pixel-Searcher as a detective solving a case. The query is a cryptic clue (“find the person who owns the car parked outside the building where the suspect works”). A regular vision system is like a detective who only looks at the crime scene photo — if the answer isn’t visible, they’re stuck. Pixel-Searcher is a detective who can leave the photo, go to the library (web search), read through files (evidence acquisition), piece together the story (identity resolution), then return to the photo with the answer in hand (visual binding). The evidence acquisition stage is the library research — gathering scattered facts. Identity resolution is the “aha” moment when the facts click into a coherent answer. Visual binding is returning to the crime scene photo and pointing at the right person. The key insight: you can’t skip the library trip. The photo alone doesn’t contain enough information.
Key Concepts
-
Perception Deep Research: Traditional visual perception assumes the target’s identity is self-evident from the image or model knowledge. Perception Deep Research formalizes the setting where identifying the target requires external fact retrieval and reasoning before perception can proceed. It’s the difference between “find the red car” (identity is given) and “find the car owned by the person who won yesterday’s lottery” (identity must be resolved externally first). The “deep research” part means the system must autonomously navigate knowledge sources, synthesize multi-hop inferences, and handle temporal or long-tail entities that weren’t in the training data.
-
Agentic Search-to-Pixel Workflow: Instead of end-to-end neural models that try to learn everything, this approach treats the problem as a multi-stage pipeline where each stage uses specialized tools. “Agentic” means the system makes decisions about what to search, how to decompose queries, and when it has enough evidence — it’s not just a fixed sequence of operations. The workflow explicitly separates knowledge acquisition (search) from visual grounding (pixels), allowing each to use its best tools: search engines and LLMs for knowledge, vision models for localization. This modularity also makes failures interpretable: you can see whether the system failed because it couldn’t find the right web page, misunderstood the evidence, or couldn’t locate the object in the image.
Framework Shift
Before (closed-world perception):        After (open-world perception):

Query: "Find X"                          Query: "Find X"
    |                                        |
    v                                        v
Image + Model knowledge                  Image + Model + Web
    |                                        |
    |                                        +---> Search engine
    |                                        |
    |                                        +---> Evidence synthesis
    |                                        |
    v                                        v
Direct grounding                         Resolved identity -> Grounding
    |                                        |
    v                                        v
Box / Mask / Answer                      Box / Mask / Answer

Assumption: X is visible                 Assumption: X may be hidden
Failure mode: Unknown objects            Failure mode: Bad evidence or binding
From closed-world to open-world, the core shift is making perception conditional on external knowledge resolution rather than assuming all necessary information is pre-encoded.
Expert Assessment
Problem choice: This is a real gap, not manufactured. The authors correctly identify that most vision benchmarks test recognition of things the model has seen before or can infer from visual context alone. Real-world applications — monitoring news events in images, identifying entities from recent developments, grounding references that require domain knowledge — routinely hit this limitation. The problem sits at the intersection of vision and language, where recent work has focused on scaling up pre-training or adding more modalities, but hasn’t seriously tackled the open-world knowledge bottleneck. The timing is right: search-augmented generation is maturing in NLP, and this paper asks the natural next question for vision.
Method maturity: Pixel-Searcher is more of a well-engineered pipeline than a novel algorithmic contribution. The three-stage decomposition (search, resolve, bind) is sensible but not surprising — it’s the obvious way to structure the problem once you’ve decided to use external search. The agentic aspect (query decomposition, iterative search) relies on existing LLM capabilities rather than introducing new mechanisms. That said, the engineering is non-trivial: getting search, evidence extraction, and visual grounding to cooperate reliably is harder than it looks. The method’s value is in demonstrating that this pipeline works and in establishing a baseline for future work. A simpler approach might skip the explicit identity resolution stage and directly feed retrieved documents to a vision-language model, but the authors’ ablations suggest the structured pipeline helps.
Experimental integrity: The benchmark design is careful. The authors manually curated queries requiring external knowledge and verified that evidence chains are traceable. The 120 images and 473 objects are small by modern standards, but the focus is on hard cases rather than scale. The three task views (grounding, segmentation, VQA) provide good coverage of how this problem manifests in practice. Baselines include recent vision-language models (GPT-4V, Gemini) and open-source alternatives, which is fair. The failure analysis is honest: they break down errors into evidence acquisition (search failed), identity resolution (wrong inference), and visual binding (couldn’t locate the object), showing that all three stages contribute to failures. One weakness: the paper doesn’t compare against a simpler baseline that just concatenates all retrieved documents and feeds them to a VLM without the structured resolution stage. This would help isolate the value of the agentic workflow.
Writing quality: The abstract and introduction are clear, but the method section is dense and could benefit from more examples walking through the full pipeline on a single query. The benchmark description is thorough, but the statistics (120 images, 473 objects, 645 QA pairs, 1,927 task samples) are presented without enough context — it’s hard to assess whether this scale is sufficient without seeing the diversity of query types. The related work section does a good job positioning the paper but could be more concise. The failure analysis in the experiments is the strongest part of the writing — it’s specific and actionable. If I were revising, I’d expand the method section with a detailed walkthrough and compress the related work.
Verdict: weak accept — Solid problem formulation and a useful benchmark, but the method is more engineering than insight, and the experimental scale is limited.
Takeaways
The key transferable idea is staged resolution with explicit intermediate representations. Instead of asking a model to do everything end-to-end (understand the query, search, reason, ground), break the task into stages where each stage produces a concrete intermediate output (retrieved facts, resolved identity, grounded box). This makes the system debuggable and lets you swap in better components as they become available. For practitioners building systems that need to combine retrieval and perception, the lesson is: don’t try to train a single model to do both — use a pipeline where retrieval and reasoning happen in language space, then hand off a resolved target to the vision model.
Another takeaway: benchmark design for knowledge-intensive tasks. The authors’ approach — manually curating hard cases, annotating evidence chains, providing multiple task views — is a template for building benchmarks in other domains where external knowledge is required. If you’re working on a problem where the model needs to “look things up,” this paper shows how to structure a benchmark that tests that capability rather than just memorization.
论文: 2605.12497 作者: Bokang Yang, Xinyi Sun, Kaituo Feng, Xingping Dong, Dongming Wu, Xiangyu Yue 分类: cs.CV
缺口
现有的视觉定位和分割系统假设目标物体的身份要么直接可见于图像中,要么已经编码在模型的冻结知识里。
你指着一张照片说”找到红色的车”——系统知道”红色”和”车”是什么意思,而且车就在那里。
这对常见物体和直白描述有效。
但如果你问”找到CEO昨天刚辞职的那家公司的logo”呢?
决定性证据不在像素里。
模型需要先搜索网络获取最新新闻,解析出是哪家公司,了解他们的logo长什么样,然后回到图像中定位它。
此前在指代表达理解、开放词汇检测和视觉问答方面的工作都在封闭世界假设下运行:识别目标所需的一切要么在图像中,要么在预训练权重里。
它们不处理需要外部事实检索、关于近期事件的时序推理或多跳推理链的知识密集型查询。
问题:"在这张图里找到X"
   |
   v
现有假设:                    本文的现实:
X可见且已知          vs.      X需要外部解析
   |                            |
   v                            v
直接感知                      搜索 -> 解析 -> 感知
   |                            |
   v                            v
适用于常见物体                处理知识密集型查询
增量
一句话:这篇论文之前,视觉感知止步于图像边界;
之后,感知可以穿透网络去解析隐藏的身份,然后再将其定位到像素上。
核心机制
WebEye引入两个组件:一个基准和一个方法。
基准叫WebEyes(复数),包含120张图像和473个标注物体,这些物体的识别需要外部知识——比如”最近一届世界杯冠军国的国旗”或”今天科技新闻中提到的公司的logo”。
每个查询都配有可验证的证据链、精确的边界框或分割掩码,以及三种任务形式:基于搜索的定位(输出框)、基于搜索的分割(输出掩码)和基于搜索的VQA(输出定位答案)。
方法叫Pixel-Searcher,是一个三阶段的智能体工作流。
第一阶段,证据获取:给定查询和图像,它将查询分解为适合搜索的子问题,检索网络文档,提取相关事实。
第二阶段,身份解析:它综合检索到的证据来确定目标实际是什么(例如”阿根廷赢得了2022年世界杯,所以目标是阿根廷国旗”)。
第三阶段,视觉实例绑定:它将解析出的身份带回图像,使用视觉-语言模型通过框、掩码或答案生成来定位相应物体。
输入:图像 + 查询("找到X的母公司的logo")
   |
   +---> [证据获取]
   |        |
   |        +-> 将查询分解为子问题
   |        +-> 对每个子问题进行网络搜索
   |        +-> 从文档中提取相关事实
   |        |
   |        v
   |     检索到的事实:"X在2023年被Y收购"
   |
   +---> [身份解析]
   |        |
   |        +-> 将事实综合为目标身份
   |        |
   |        v
   |     解析出的身份:"Y的logo"
   |
   +---> [视觉实例绑定]
            |
            +-> 在图像中定位"Y的logo"
            +-> 生成框 / 掩码 / 答案
            |
            v
         输出:定位结果
把Pixel-Searcher想象成一个破案的侦探。
查询是一条隐晦的线索(“找到在嫌疑人工作的大楼外停车的那辆车的主人”)。
常规视觉系统就像只看犯罪现场照片的侦探——如果答案不可见,他们就卡住了。
Pixel-Searcher是一个可以离开照片、去图书馆(网络搜索)、翻阅档案(证据获取)、拼凑故事(身份解析)、然后带着答案回到照片(视觉绑定)的侦探。
证据获取阶段是图书馆调研——收集零散的事实。
身份解析是事实拼成连贯答案的”顿悟”时刻。
视觉绑定是回到犯罪现场照片并指向正确的人。
关键洞察:你不能跳过图书馆之行。
照片本身不包含足够的信息。
关键概念
- 感知深度研究(Perception Deep Research):传统视觉感知假设目标的身份从图像或模型知识中就能自明。
感知深度研究形式化了这样一种设定:识别目标需要先进行外部事实检索和推理,然后感知才能进行。
这是”找到红色的车”(身份已给定)和”找到昨天中彩票的人拥有的车”(身份必须先从外部解析)之间的区别。
“深度研究”部分意味着系统必须自主导航知识源、综合多跳推理、处理训练数据中没有的时序或长尾实体。
- 智能体式搜索到像素工作流(Agentic Search-to-Pixel Workflow):不是试图学习一切的端到端神经模型,这种方法将问题视为多阶段流水线,每个阶段使用专门的工具。
“智能体式”意味着系统对搜索什么、如何分解查询、何时有足够证据做出决策——它不只是固定的操作序列。
工作流明确分离知识获取(搜索)和视觉定位(像素),允许各自使用最佳工具:搜索引擎和LLM用于知识,视觉模型用于定位。
这种模块化也使失败可解释:你可以看到系统是因为找不到正确的网页、误解了证据,还是无法在图像中定位物体而失败。
框架转变
之前(封闭世界感知):              之后(开放世界感知):

查询:"找到X"                       查询:"找到X"
    |                                   |
    v                                   v
图像 + 模型知识                      图像 + 模型 + 网络
    |                                   |
    |                                   +---> 搜索引擎
    |                                   |
    |                                   +---> 证据综合
    |                                   |
    v                                   v
直接定位                             解析身份 -> 定位
    |                                   |
    v                                   v
框 / 掩码 / 答案                     框 / 掩码 / 答案

假设:X可见                          假设:X可能隐藏
失败模式:未知物体                   失败模式:证据或绑定错误
从封闭世界到开放世界,核心转变是让感知以外部知识解析为条件,而不是假设所有必要信息都已预编码。
专家评审
选题眼光:这是真缺口,不是人造的。
作者正确识别出大多数视觉基准测试的是模型之前见过的东西或仅从视觉上下文就能推断的东西的识别。
现实世界应用——监控图像中的新闻事件、识别来自最新发展的实体、定位需要领域知识的引用——经常碰到这个限制。
这个问题位于视觉和语言的交叉点,最近的工作集中在扩大预训练规模或添加更多模态,但没有认真解决开放世界知识瓶颈。
时机合适:搜索增强生成在NLP中正在成熟,这篇论文为视觉提出了自然的下一个问题。
方法成熟度:Pixel-Searcher更像是一个精心设计的流水线,而不是新颖的算法贡献。
三阶段分解(搜索、解析、绑定)合理但不令人惊讶——一旦你决定使用外部搜索,这是构建问题的显而易见方式。
智能体方面(查询分解、迭代搜索)依赖现有的LLM能力,而不是引入新机制。
话虽如此,工程并非微不足道:让搜索、证据提取和视觉定位可靠地协作比看起来更难。
该方法的价值在于证明这个流水线有效,并为未来工作建立基线。
更简单的方法可能跳过显式的身份解析阶段,直接将检索到的文档馈送给视觉-语言模型,但作者的消融实验表明结构化流水线有帮助。
实验诚意:基准设计很仔细。
作者手动策划了需要外部知识的查询,并验证了证据链是可追溯的。
120张图像和473个物体按现代标准来说很小,但重点是困难案例而不是规模。
三种任务视图(定位、分割、VQA)很好地覆盖了这个问题在实践中的表现形式。
基线包括最近的视觉-语言模型(GPT-4V、Gemini)和开源替代品,这是公平的。
失败分析是诚实的:他们将错误分解为证据获取(搜索失败)、身份解析(错误推理)和视觉绑定(无法定位物体),表明所有三个阶段都对失败有贡献。
一个弱点:论文没有与更简单的基线比较,即只是连接所有检索到的文档并将它们馈送给VLM而不进行结构化解析阶段。
这将有助于隔离智能体工作流的价值。
写作功力:摘要和引言清晰,但方法部分密集,可以从更多示例中受益,这些示例在单个查询上走完整个流水线。
基准描述很详尽,但统计数据(120张图像、473个物体、645个QA对、1927个任务样本)呈现时没有足够的上下文——在没有看到查询类型的多样性的情况下,很难评估这个规模是否足够。
相关工作部分在定位论文方面做得很好,但可以更简洁。
实验中的失败分析是写作最强的部分——它具体且可操作。
如果我修订,我会用详细的演练扩展方法部分,并压缩相关工作。
判决:弱接收 — 扎实的问题形式化和有用的基准,但方法更多是工程而非洞察,实验规模有限。
要点总结
关键的可迁移想法是带有显式中间表示的分阶段解析。
不要要求模型端到端地做所有事情(理解查询、搜索、推理、定位),而是将任务分解为阶段,每个阶段产生具体的中间输出(检索到的事实、解析出的身份、定位的框)。
这使系统可调试,并让你在更好的组件可用时替换它们。
对于构建需要结合检索和感知的系统的实践者,教训是:不要试图训练单个模型同时做两件事——使用流水线,其中检索和推理发生在语言空间,然后将解析出的目标交给视觉模型。
另一个要点:知识密集型任务的基准设计。
作者的方法——手动策划困难案例、标注证据链、提供多种任务视图——是在其他需要外部知识的领域构建基准的模板。
如果你正在处理模型需要”查找东西”的问题,这篇论文展示了如何构建测试该能力而不仅仅是记忆的基准。