Paper: 2604.09459 Authors: Chenchen Zhang Categories: cs.CL
The Gap
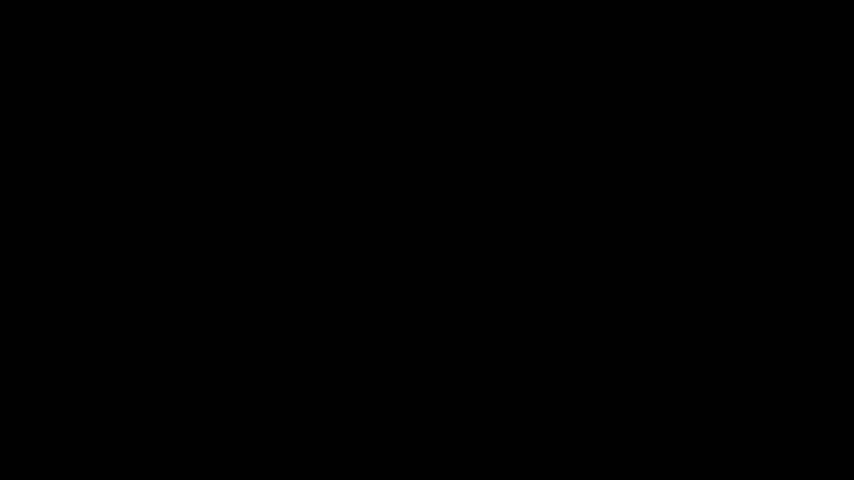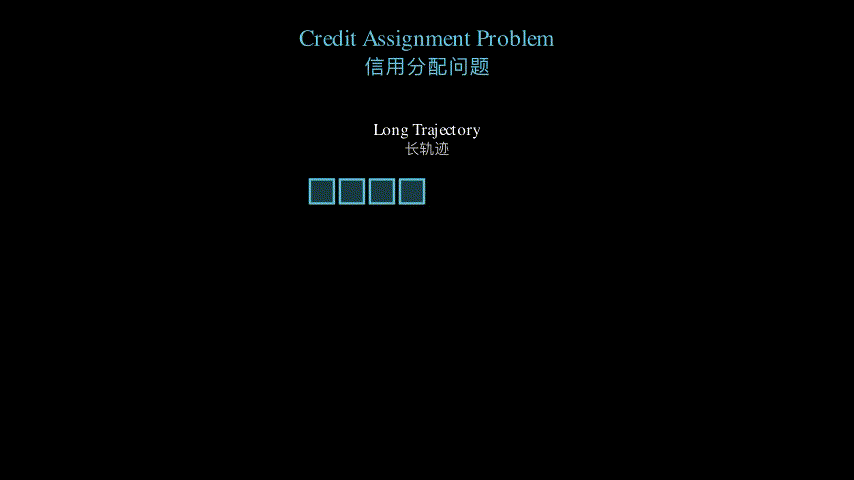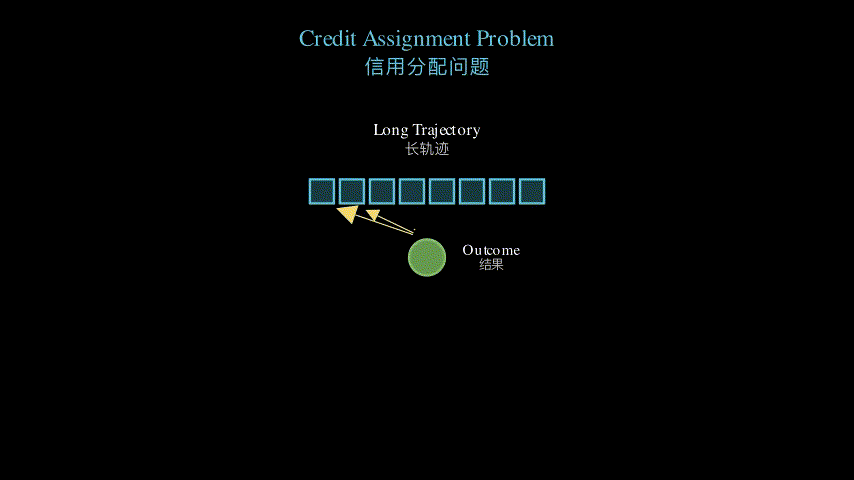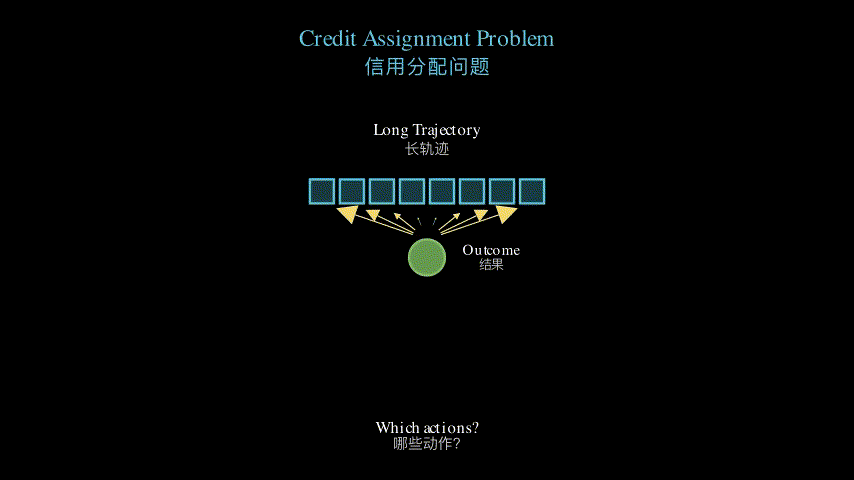
RL for LLMs has hit a wall: we can generate outcome-level rewards (right or wrong answer), but we can’t figure out which decisions in a 500-token reasoning chain or 100-turn agent interaction actually caused that outcome. Prior work treated this as a single problem — but it’s not. A reasoning chain is deterministic and self-contained; an agent navigates a stochastic environment with partial observability and compounding uncertainty. Existing credit assignment methods (mostly from classical RL or imitation learning) were built for neither regime. The field has been applying 2010-era techniques to 2024 problems and calling it done.
Classical RL (short horizon)
        |
        v
    Sparse Reward Problem
        |
        +---> Reasoning RL (deterministic, 500-30K tokens)
        |     [Process rewards emerging, but still immature]
        |
        +---> Agentic RL (stochastic, 100K-1M tokens)
              [Existing methods fail; new approaches needed]
The Increment
One sentence: Before this paper, credit assignment in LLM RL was a scattered collection of ad-hoc fixes; after, it’s a structured landscape with clear methodological families, diagnostic tools, and a decision tree for practitioners.
Core Mechanism
This isn’t a new algorithm — it’s a taxonomy and diagnostic framework. Zhang surveyed 47 papers and organized them along two axes: granularity (what gets credit: tokens, segments, steps, turns, multi-agent?) and methodology (how: Monte Carlo rollouts, temporal difference, learned critics, game theory, information theory?). The key insight is that reasoning and agentic RL require *different credit assignment strategies because their causal structures are fundamentally different.
For reasoning RL, the problem is: “Which tokens in this chain-of-thought mattered?” Process reward models (PRMs) and group comparison methods are maturing here — they work because the trajectory is deterministic and you can replay it.
For agentic RL, the problem is: “Which turn’s decision caused this outcome, given that the environment is stochastic and I only see partial state?” Here, new methods are emerging: hindsight counterfactual analysis (rewrite history to make the outcome inevitable), privileged asymmetric critics (give the critic information the agent doesn’t have), and turn-level MDP reformulations (break the 100-turn episode into smaller MDPs).
Reasoning RL:                    Agentic RL:
Deterministic chain              Stochastic environment
    |                                |
    v                                v
Process Reward Models         Hindsight Counterfactuals
Group Comparison              Privileged Critics
    |                         Turn-level MDPs
    v                                |
Mature, converging                   v
                              Genuinely novel methods
The paper also contributes three reusable artifacts: (1) a machine-readable inventory of all 47 papers with taxonomy labels and evidence levels, (2) a reporting checklist to catch methodological gaps in future work, and (3) a benchmark protocol spec with a method selection decision tree.
Structural metaphor: Think of credit assignment like a detective investigating a crime. In reasoning RL, the crime scene is frozen — you can replay it frame-by-frame, interview witnesses (process rewards), and reconstruct exactly what happened. In agentic RL, the crime scene is a live city — witnesses are unreliable (partial observability), events cascade unpredictably (stochasticity), and by the time you know a crime occurred, you’ve forgotten which street corner mattered. So you need different investigative tools: for reasoning, forensics (PRMs); for agentic, informants with special access (privileged critics) or rewriting the narrative (hindsight counterfactuals).
Key Concepts
-
Credit Assignment Problem: In RL with sparse rewards, you know the final outcome but not which intermediate actions caused it. With 100K tokens, this is like asking “which word made the difference?” — the signal is too delayed and noisy. The core challenge: how to propagate reward information backward through a long trajectory when you only observe the endpoint.
-
Hindsight Counterfactual Analysis: Imagine you took action A, the environment did X, and you failed. Now imagine: “What if I had taken action B instead? Would X still happen?” If yes, then A wasn’t the problem — something else was. This reweights credit by asking “which actions were actually causal?” It’s powerful for agentic RL because it handles stochasticity: you’re not pretending the environment is deterministic, you’re asking which actions would have mattered *given the actual randomness that occurred.
-
Privileged Asymmetric Critics: A critic is a neural network that estimates “how good is this state?” Normally, the critic sees what the agent sees. But what if you give the critic access to information the agent doesn’t have — like the true environment state, or future outcomes? This breaks the symmetry: the critic can learn a better value function, and the agent learns from that signal. It’s “privileged” because the critic has unfair information; it’s “asymmetric” because agent and critic have different observability.
Framework Shift
Before (mainstream approach):        After (this paper):
One problem: "credit assignment"     Two problems: reasoning vs agentic
    |                                    |
    v                                    v
Apply classical RL methods          Reasoning: process rewards
(temporal difference, etc.)         Agentic: hindsight + privileged critics
    |                                    |
    v                                    v
Mediocre results on both            Specialized methods for each
Core shift: From treating credit assignment as a single, domain-agnostic problem to recognizing that *the causal structure of the task determines which methods work. Deterministic chains need different tools than stochastic environments.
Expert Assessment
Problem choice: This is a *real gap, and it’s urgent. LLM RL is moving from reasoning (o1-style) to agents (Claude with tools), and the field has no principled way to assign credit in the agent regime. The paper correctly identifies that existing methods don’t transfer. However, the framing as “two regimes” is slightly artificial — there’s a spectrum, and some tasks (like code generation with environment feedback) sit in between. Still, the binary framing is pedagogically useful and mostly holds.
Method maturity: This is a survey, not a novel algorithm, so “method maturity” is about the survey’s rigor. Zhang organized 47 papers into a 2D taxonomy — clean, but not deep. The taxonomy is useful for navigation, but it doesn’t explain *why certain methods work in certain regimes. The decision tree is helpful but feels like a first draft; it needs validation on held-out tasks. The reporting checklist is the strongest contribution — it’s concrete and will catch sloppy papers.
Experimental integrity: There’s no new experimental work here, so this doesn’t apply directly. But the paper’s synthesis of existing results is honest: it doesn’t oversell the maturity of reasoning RL methods or pretend agentic methods are solved. The evidence levels (how rigorously each paper validated its claims) are tracked, which is good practice.
Writing quality: The abstract is dense but clear. The taxonomy section is well-structured. Where the paper could improve: the “structural metaphor” section (if it exists) could be more vivid — the detective analogy I used above isn’t in the paper, and it should be. Also, the paper would benefit from a “failure modes” section: which credit assignment methods fail catastrophically on which task types? That’s missing.
Verdict: Strong accept — This is exactly the kind of survey the field needs right now. It’s not groundbreaking, but it’s timely, well-organized, and provides reusable tools (the inventory, checklist, decision tree). It will become a reference paper for anyone building RL systems for LLMs.
Takeaways
-
If you’re building reasoning RL: Process reward models are the way forward. The paper suggests they’re maturing; invest in scaling them rather than chasing exotic credit assignment schemes.
-
If you’re building agentic RL: Don’t use classical temporal difference methods directly. The paper flags hindsight counterfactual analysis and privileged critics as genuinely new approaches — these are worth prototyping. The turn-level MDP reformulation is also interesting: instead of one 100-turn MDP, break it into 100 single-turn MDPs with learned transition models.
-
If you’re publishing RL papers: Use the reporting checklist. It will force you to be explicit about what you’re measuring and why. The paper identifies systematic gaps in how the field reports results — fixing this will make future comparisons possible.
-
For practitioners: Use the decision tree. It’s a heuristic, but it’s better than guessing. The paper also provides a machine-readable inventory — if you’re implementing a new method, you can query it to find similar prior work and avoid reinventing wheels.
-
Conceptual takeaway: The shift from reasoning to agentic RL isn’t just a scaling problem — it’s a *structural problem. Your credit assignment method must match the causal structure of your task. This principle transfers beyond LLMs: any RL system with long horizons and stochasticity will face similar tradeoffs.
论文: 2604.09459 作者: Chenchen Zhang 分类: cs.CL
缺口
LLM强化学习遇到了瓶颈:我们能生成结果级奖励(答案对或错),但无法确定一条500词的推理链或100轮智能体交互中的哪些决策导致了这个结果。
之前的工作把这当作一个问题——但它不是。 推理链是确定性的、自洽的;智能体在随机环境中导航,面对部分可观测性和复合不确定性。 现有的信用分配方法(多数来自经典RL或模仿学习)都不是为这两种情况设计的。 该领域一直在用2010年代的技术处理2024年的问题。
经典RL(短视野)
        |
        v
    稀疏奖励问题
        |
        +---> 推理RL(确定性,500-30K词)
        |     [过程奖励出现,但仍不成熟]
        |
        +---> 智能体RL(随机性,100K-1M词)
              [现有方法失效;需要新方法]
增量
一句话: 这篇论文之前,LLM RL中的信用分配是零散的临时修补;之后,它成为一个结构化的景观,有清晰的方法族系、诊断工具和实践者决策树。
核心机制
这不是一个新算法——而是一个分类法和诊断框架。 Zhang调查了47篇论文,沿两个轴组织它们:粒度(谁获得信用:词、段、步、轮、多智能体?)和方法论(如何:蒙特卡洛、时间差分、学习评论家、博弈论、信息论?)。 关键洞察是推理RL和智能体RL需要不同的信用分配策略,因为它们的因果结构根本不同。
对于推理RL,问题是:“这条思维链中哪些词很重要?” 过程奖励模型(PRM)和组比较方法在这里成熟——它们有效是因为轨迹是确定性的,你可以重放它。
对于智能体RL,问题是:“给定环境是随机的且我只看到部分状态,哪一轮的决策导致了这个结果?” 这里新方法正在出现:后见反事实分析(改写历史使结果不可避免)、特权非对称评论家(给评论家智能体没有的信息)、轮级MDP重构(把100轮情节分解成更小的MDP)。
推理RL:                         智能体RL:
确定性链                         随机环境
    |                                |
    v                                v
过程奖励模型                    后见反事实
组比较                          特权评论家
    |                           轮级MDP
    v                                |
成熟、收敛                           v
                              真正新颖的方法
论文还贡献了三个可复用的资源: (1)所有47篇论文的机器可读清单,带分类标签和证据等级; (2)一份报告检查清单,用于捕捉未来工作中的方法论缺口; (3)一份基准协议规范,包含任务族系、元数据要求和受控分岔任务,附带方法选择决策树。
结构性比喻:把信用分配想象成侦探调查犯罪。 在推理RL中,犯罪现场被冻结了——你可以逐帧重放、采访证人(过程奖励)、精确重建发生了什么。 在智能体RL中,犯罪现场是一座活城市——证人不可靠(部分可观测性)、事件不可预测地级联(随机性),当你知道犯罪发生时,已经忘记了哪个街角很重要。 所以你需要不同的调查工具:对于推理,法医学(PRM);对于智能体,有特殊渠道的线人(特权评论家)或改写叙事(后见反事实)。
关键概念
-
信用分配问题:在稀疏奖励RL中,你知道最终结果但不知道哪些中间行动导致了它。 有100K个词时,这就像问”哪个词产生了差异?“——信号太延迟、太嘈杂。 核心挑战:当你只观察终点时,如何通过长轨迹向后传播奖励信息。
-
后见反事实分析:想象你采取了行动A,环境做了X,你失败了。 现在想象:“如果我采取了行动B呢?X仍会发生吗?” 如果是,那么A不是问题——别的东西是。 这通过问”哪些行动真正有因果关系?“来重新加权信用。 它对智能体RL很强大,因为它处理随机性:你不是假装环境是确定性的,而是问哪些行动在给定实际发生的随机性下会重要。
-
特权非对称评论家:评论家是估计”这个状态有多好?“的神经网络。 通常,评论家看到智能体看到的东西。 但如果你给评论家访问智能体没有的信息呢——比如真实环境状态或未来结果? 这打破了对称性:评论家能学到更好的价值函数,智能体从那个信号学习。 它是”特权的”因为评论家有不公平的信息;它是”非对称的”因为智能体和评论家有不同的可观测性。
框架转变
之前(主流方法):                之后(本文方法):
一个问题:"信用分配"              两个问题:推理 vs 智能体
    |                                    |
    v                                    v
应用经典RL方法                    推理:过程奖励
(时间差分等)                    智能体:后见+特权评论家
    |                                    |
    v                                    v
两个领域结果平庸                  每个领域的专门方法
核心转变:从把信用分配当作单一、领域无关的问题,转变为认识到**任务的因果结构决定了哪些方法有效*。 确定性链需要不同的工具,而不是随机环境。
专家评审
选题眼光:这是一个**真实的*缺口,而且很紧迫。 LLM RL正从推理(o1风格)转向智能体(带工具的Claude),该领域没有原则性的方法在智能体体制中分配信用。 论文正确地指出现有方法不能转移。 然而,将其框架为”两个体制”略显人工——存在一个谱系,某些任务(如带环境反馈的代码生成)介于两者之间。 不过,二元框架在教学上有用,大体成立。
方法成熟度:这是一份综述,不是新算法,所以”方法成熟度”是关于综述的严谨性。 Zhang把47篇论文组织成2D分类法——简洁,但不深入。 分类法对导航有用,但不解释为什么某些方法在某些体制中有效。 决策树有帮助但感觉像初稿;它需要在保留任务上验证。 报告检查清单是最强的贡献——它很具体,会捕捉草率的论文。
实验诚意:这里没有新的实验工作,所以这不直接适用。 但论文对现有结果的综合是诚实的:它不过度宣传推理RL方法的成熟度,也不假装智能体方法已解决。 证据等级(每篇论文验证其声明的严谨程度)被追踪,这是好的实践。
写作功力:摘要密集但清晰。 分类法部分结构良好。 论文可以改进的地方:结构性比喻部分(如果存在)可以更生动——我上面用的侦探比喻不在论文中,但应该在。 另外,论文会受益于”失败模式”部分:哪些信用分配方法在哪些任务类型上灾难性地失效? 这缺失了。
判决:强接收 — 这正是该领域现在需要的那种综述。 它不是突破性的,但它及时、组织良好、提供可复用工具(清单、检查清单、决策树)。 它将成为任何构建LLM RL系统的人的参考论文。
要点总结
-
如果你在构建推理RL:过程奖励模型是前进的方向。 论文表明它们在成熟;投资于扩展它们,而不是追逐奇异的信用分配方案。
-
如果你在构建智能体RL:不要直接使用经典时间差分方法。 论文标记后见反事实分析和特权评论家为真正新颖的方法——这些值得原型化。 轮级MDP重构也很有趣:不是一个100轮MDP,而是100个单轮MDP,带学习的转移模型。
-
如果你在发表RL论文:使用报告检查清单。 它会强制你明确说明你在测量什么以及为什么。 论文指出该领域在如何报告结果上的系统性缺口——修复这个会使未来的比较成为可能。
-
对于实践者:使用决策树。 它是启发式的,但比猜测好。 论文还提供了机器可读清单——如果你在实现新方法,可以查询它找到类似的先前工作,避免重新发明轮子。
-
概念收获:从推理到智能体RL的转变不仅仅是扩展问题——它是一个**结构性*问题。 你的信用分配方法必须匹配你任务的因果结构。 这个原则超越LLM转移:任何有长视野和随机性的RL系统都会面临类似的权衡。