Paper: 2603.02194 Authors: Mateus Karvat, Bram Adams, Sidney Givigi Categories: cs.CV, cs.LG, cs.RO, cs.SE
The Gap
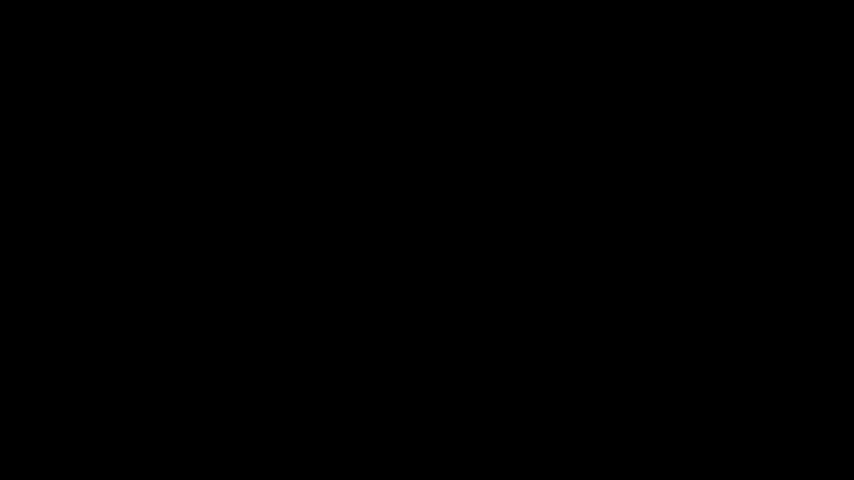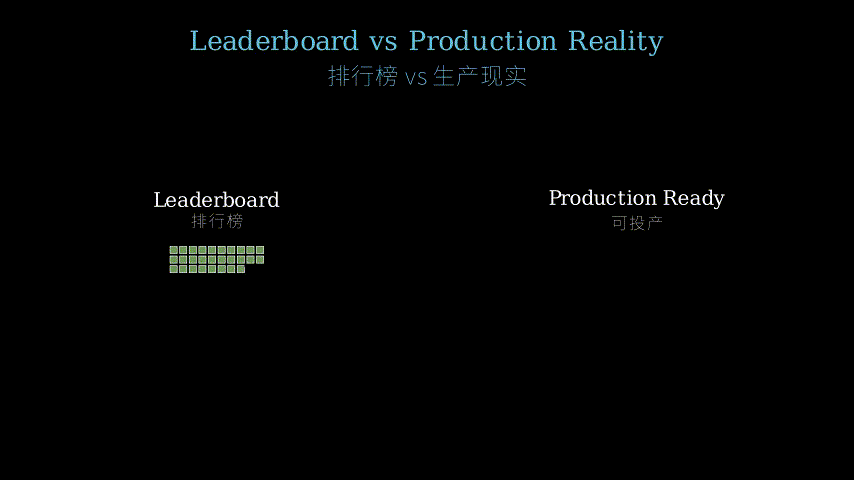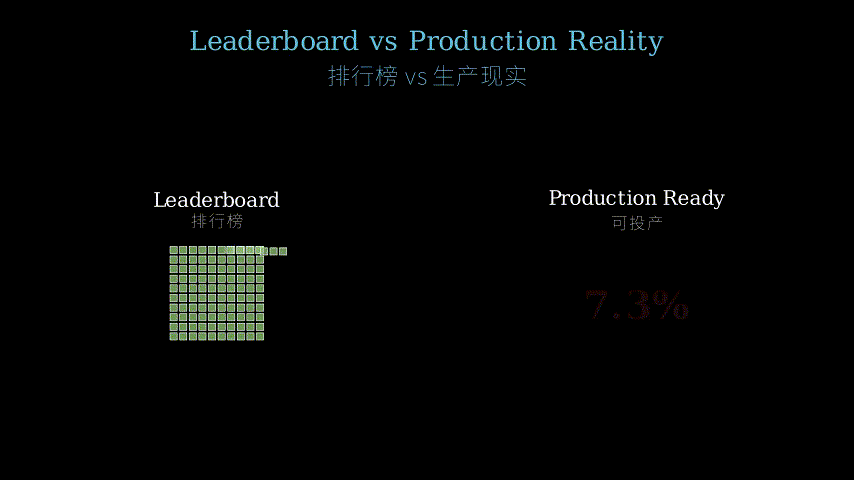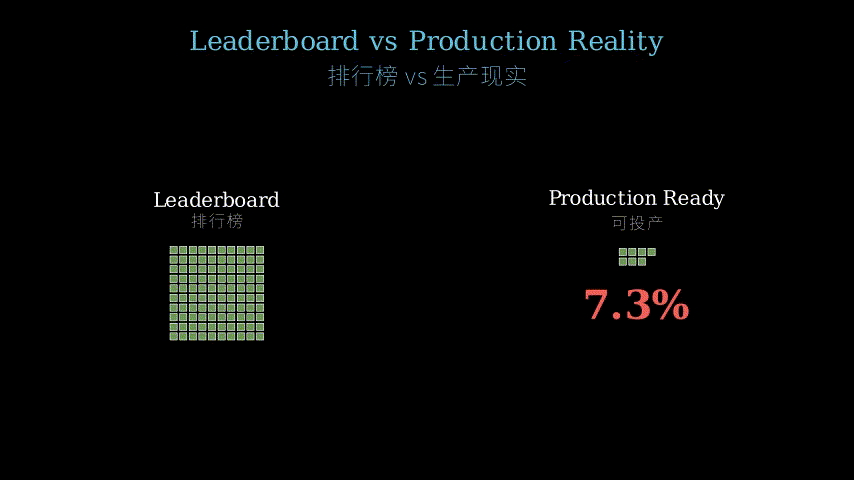
The AV perception field has a dirty secret: we’ve been optimizing for the wrong metric. Researchers chase leaderboard rankings on KITTI and NuScenes by squeezing out every 0.1% mAP improvement, but nobody’s checking if the code can actually survive contact with production. The field treats perception as a pure ML problem—train model, publish paper, move on. Meanwhile, automotive safety standards like ISO 26262 demand code that won’t kill people, and there’s zero overlap between “state-of-the-art accuracy” and “won’t crash when deployed.”
Prior work evaluated perception models exclusively on detection metrics (precision, recall, mAP). Code quality? Maintainability? Security vulnerabilities? Not even on the radar. This creates a chasm: research code optimized for benchmark performance versus production systems that need to pass safety certification, handle edge cases, and be maintained by teams who didn’t write the original research prototype.
Research Reality                Production Requirements
     |                                  |
     v                                  v
Leaderboard      <---GAP--->      Safety-Critical
Performance                        Deployable Code
     |                                  |
     v                                  v
mAP, Recall      <---???--->      Zero Critical Bugs
F1 Score                          Security Hardened
                                  Maintainable
     |                                  |
     +----------------------------------+
                      |
                      v
              This Paper's Path:
              Measure the gap
              Quantify the mess
              Provide guidelines
The Increment
One sentence: Before this paper, we assumed top leaderboard models were deployment-ready; after, we know 93% fail basic production criteria and exactly which five security issues cause 80% of problems.
Core Mechanism
The authors built a three-layer diagnostic pipeline to X-ray 178 repositories from KITTI and NuScenes leaderboards. First layer: Pylint scans for code errors—syntax issues, undefined variables, import failures, the stuff that breaks at runtime. Second layer: Bandit hunts security vulnerabilities—hardcoded credentials, unsafe deserialization, SQL injection risks. Third layer: Radon measures maintainability through cyclomatic complexity and code metrics.
They didn’t just run tools and dump numbers. They defined “production-ready” as zero critical errors AND zero high-severity security issues—a surprisingly low bar that 93% of repos still failed. Then they correlated code quality with development practices: does the repo use CI/CD? How many contributors? How active is maintenance? This revealed that CI/CD adoption strongly predicts better maintainability scores.
The security analysis went deeper: they found issue concentration—five vulnerability types account for 80% of all security problems. This Pareto distribution meant they could write targeted guidelines that address the bulk of issues without boiling the ocean.
Input: 178 Repos from Leaderboards
         |
         v
    +----+----+----+
    |    |    |    |
    v    v    v    v
 Pylint Bandit Radon Metadata
 (errors) (sec) (maint) (CI/CD)
    |    |    |    |
    +----+----+----+
         |
         v
  Aggregate Metrics
         |
    +----+----+
    |         |
    v         v
Production  Correlation
Readiness   Analysis
 (7.3%)    (CI/CD effect)
    |         |
    +----+----+
         |
         v
   Guidelines
  (Top 5 issues)
Think of this like a health screening for code. Most medical checkups don’t test for every possible disease—they run a standard panel that catches 80% of common issues. The authors designed their “standard panel” for AV perception code: three tools that together reveal whether code is healthy enough for production. Pylint is the blood test (basic functionality), Bandit is the cancer screening (hidden dangers), and Radon is the fitness assessment (can this code survive long-term maintenance?).
The key insight: they didn’t try to fix every repo. Instead, they diagnosed the population to find patterns. Just like epidemiology identifies that five risk factors cause most heart disease, they identified five security issues causing most vulnerabilities. Now you can vaccinate against the common threats instead of treating each patient individually.
Key Concepts
-
Production Readiness (as defined here): Not “enterprise-grade architecture” or “follows all best practices”—just the bare minimum: code that runs without critical errors and doesn’t have obvious security holes. Think of it as the difference between “this car passes safety inspection” versus “this car is luxurious.” The paper sets the bar at safety inspection level, and 93% of research code still fails. A critical error might be calling a function that doesn’t exist, or a high-severity vulnerability might be hardcoding an API key in the source. These aren’t nitpicks—they’re showstoppers for deployment.
-
Static Analysis: Reading code without running it, like a grammar checker for programming. Pylint catches errors by parsing the code and checking if variables are defined before use, if imports exist, if function calls match signatures. Bandit looks for patterns known to be dangerous—like using
eval()on user input or storing passwords in plain text. The beauty: you get safety guarantees without needing test data or execution environments. The limitation: can’t catch logic bugs or runtime-only issues. -
Cyclomatic Complexity: Count how many different paths execution can take through your code. A function with no if-statements or loops has complexity 1 (one path). Add an if-statement, now there are 2 paths. Add a loop with a break condition, more paths. High complexity means more places for bugs to hide and harder maintenance. Radon measures this automatically. A complexity over 10 is a yellow flag; over 20 is a red flag. Most research code doesn’t track this at all.
Framework Shift
Before (mainstream approach):        After (this paper):

Research Cycle:                      Research + Deployment Cycle:

  Train Model                          Train Model
      |                                    |
      v                                    v
  Benchmark Test                       Benchmark Test
      |                                    |
      v                                    v
  Leaderboard                          Code Quality Scan
      |                                    |
      v                                +---+---+
  Publish Paper                       |       |
      |                               v       v
      v                            Pass?    Fail?
  [Done]                              |       |
                                      v       v
                                  Deploy  Fix+Retry

Evaluation:                          Evaluation:
mAP, F1, Recall                      mAP + Errors + Security + Maintainability
From “accuracy is everything” to “accuracy is table stakes, now let’s talk about whether this code can survive production,” the core shift is adding a quality gate between research and deployment.
Expert Assessment
Problem choice: This is a real gap, not manufactured. The field has genuinely ignored code quality while chasing benchmark numbers. It sits at a critical inflection point—AV systems are moving from research to production, and the mismatch between research practices and safety standards is becoming a bottleneck. The timing is perfect: enough deployed systems exist to make this urgent, but not so many that the lesson has been learned the hard way.
Method maturity: This is straightforward empirical work—run existing tools, aggregate results, find patterns. No clever algorithmic insights, but that’s appropriate here. The value is in asking the question and doing the legwork, not inventing new analysis techniques. A simpler approach would be sampling fewer repos, but 178 is a reasonable population size for statistical validity. The CI/CD correlation analysis is a nice touch that goes beyond just reporting problems.
Experimental integrity: The baselines are fair—they’re using standard, well-established static analysis tools (Pylint, Bandit, Radon). The 7.3% production-readiness number is stark but defensible given their criteria. One concern: the definition of “production-ready” is binary (zero critical errors), which might be too harsh. A repo with one critical error that’s trivial to fix gets lumped with repos that are fundamentally broken. The paper would be stronger with a severity-weighted score. The security concentration finding (top 5 issues = 80%) is compelling and passes the smell test.
Writing quality: The paper front-loads the shocking statistic (7.3%) effectively, but the guidelines section feels rushed. They identify the top five security issues but don’t deeply explain why these specific patterns are so common in perception code. A case study walking through one repo’s journey from “research prototype” to “production-ready” would make the abstract findings concrete. The related work section is thin—more engagement with software engineering research on ML systems would strengthen positioning.
Verdict: weak accept — Addresses a real problem with solid empirical work, but the analysis could go deeper and the guidelines need more development to be truly actionable.
Takeaways
If you’re building any ML system that might see production, steal this three-tool diagnostic: Pylint for errors, Bandit for security, Radon for maintainability. Run them in CI/CD from day one, not as an afterthought. The paper’s finding that CI/CD correlates with better code quality isn’t surprising, but it’s evidence you can show to managers who think “we’ll clean it up later.”
The security concentration insight transfers directly: in any codebase, a small number of issue types cause most problems. Don’t try to fix everything—profile your vulnerabilities, find the top five, write guidelines for those, and you’ve addressed 80% of the risk. This Pareto principle applies beyond AV perception to any domain.
For researchers: if you’re releasing code with a paper, run these three tools before publishing. It takes an hour and prevents your repo from becoming a cautionary tale in the next empirical study. The gap between “runs on my machine” and “someone else can use this” is smaller than you think, but only if you measure it.
The broader lesson: leaderboard metrics are necessary but not sufficient. Whatever your field’s equivalent of mAP is, it’s probably hiding quality problems that matter for real-world use. This paper’s framework—define minimal production criteria, measure gap, identify concentrated issues, provide targeted guidelines—works for any research-to-production transition.
论文: 2603.02194 作者: Mateus Karvat, Bram Adams, Sidney Givigi 分类: cs.CV, cs.LG, cs.RO, cs.SE
缺口
自动驾驶感知领域有个不能说的秘密:我们一直在优化错误的指标。 研究者在KITTI和NuScenes排行榜上追逐每0.1%的mAP提升,却没人检查代码能否在生产环境存活。 这个领域把感知当作纯机器学习问题——训练模型、发论文、继续前进。 与此同时,汽车安全标准如ISO 26262要求代码不能害死人,而”最先进的精度”和”部署后不会崩溃”之间毫无交集。
以往工作只用检测指标(精确率、召回率、mAP)评估感知模型。 代码质量?可维护性?安全漏洞?根本不在考虑范围内。 这造成了鸿沟:为基准性能优化的研究代码,对比需要通过安全认证、处理边缘情况、由没写过原型的团队维护的生产系统。
研究现实                生产要求
    |                       |
    v                       v
排行榜      <---鸿沟--->   安全关键
性能                       可部署代码
    |                       |
    v                       v
mAP、召回   <---???--->   零严重错误
F1分数                     安全加固
                           可维护
    |                       |
    +----------------------+
             |
             v
      本文的路径:
      测量鸿沟
      量化混乱
      提供指南
增量
一句话: 这篇论文之前,我们以为排行榜顶级模型可以直接部署。 之后,我们知道93%无法通过基本生产标准,并且确切知道哪五个安全问题导致80%的麻烦。
核心机制
作者构建了三层诊断流水线,对KITTI和NuScenes排行榜的178个代码库做X光扫描。 第一层:Pylint扫描代码错误——语法问题、未定义变量、导入失败,那些运行时会崩溃的东西。 第二层:Bandit搜寻安全漏洞——硬编码凭证、不安全的反序列化、SQL注入风险。 第三层:Radon通过圈复杂度和代码指标测量可维护性。
他们不只是跑工具然后倾倒数字。 他们定义”生产就绪”为零严重错误且零高危安全问题——一个低得惊人的标准,93%的代码库仍然失败。 然后他们关联代码质量与开发实践:代码库用CI/CD吗?有多少贡献者?维护有多活跃?这揭示了CI/CD采用强烈预测更好的可维护性分数。
安全分析更深入:他们发现问题集中——五种漏洞类型占所有安全问题的80%。 这种帕累托分布意味着他们可以写针对性指南,解决大部分问题而不用大海捞针。
输入: 排行榜178个代码库
         |
         v
    +----+----+----+
    |    |    |    |
    v    v    v    v
 Pylint Bandit Radon 元数据
 (错误) (安全)(维护)(CI/CD)
    |    |    |    |
    +----+----+----+
         |
         v
   聚合指标
         |
    +----+----+
    |         |
    v         v
生产就绪  相关性分析
 (7.3%)  (CI/CD效应)
    |         |
    +----+----+
         |
         v
    指南
 (前5问题)
把这想象成代码的健康筛查。 大多数体检不测试每种可能的疾病——它们运行标准套餐,捕获80%的常见问题。 作者为自动驾驶感知代码设计了”标准套餐”:三个工具一起揭示代码是否足够健康投产。 Pylint是血液检测(基本功能),Bandit是癌症筛查(隐藏危险),Radon是体能评估(这代码能否长期维护?)。
关键洞察:他们没试图修复每个代码库。 相反,他们诊断群体以发现模式。 就像流行病学识别出五个风险因素导致大多数心脏病,他们识别出五个安全问题导致大多数漏洞。 现在你可以针对常见威胁接种疫苗,而不是逐个治疗患者。
关键概念
-
生产就绪(本文定义): 不是”企业级架构”或”遵循所有最佳实践”——只是最低限度:代码运行时没有严重错误,没有明显安全漏洞。 想象成”这车通过安全检查”和”这车很豪华”的区别。 论文把标准设在安全检查级别,93%的研究代码仍然失败。 严重错误可能是调用不存在的函数,高危漏洞可能是在源码里硬编码API密钥。 这些不是吹毛求疵——它们是部署的拦路虎。
-
静态分析: 不运行代码就阅读它,像编程的语法检查器。 Pylint通过解析代码检查变量是否在使用前定义、导入是否存在、函数调用是否匹配签名来捕获错误。 Bandit寻找已知危险的模式——比如对用户输入使用
eval()或明文存储密码。 优点:不需要测试数据或执行环境就能获得安全保证。 局限:无法捕获逻辑错误或仅运行时出现的问题。 -
圈复杂度: 计算执行可以通过代码走多少条不同路径。 没有if语句或循环的函数复杂度为1(一条路径)。 加个if语句,现在有2条路径。 加个带中断条件的循环,更多路径。 高复杂度意味着更多藏bug的地方和更难维护。 Radon自动测量这个。 复杂度超过10是黄色警告。 超过20是红色警告。 大多数研究代码根本不跟踪这个。
框架转变
之前(主流方法):                之后(本文方法):

研究循环:                      研究+部署循环:

  训练模型                         训练模型
      |                                |
      v                                v
  基准测试                         基准测试
      |                                |
      v                                v
  排行榜                           代码质量扫描
      |                                |
      v                            +---+---+
  发表论文                        |       |
      |                           v       v
      v                        通过?   失败?
  [完成]                          |       |
                                  v       v
                              部署    修复+重试

评估:                            评估:
mAP、F1、召回                    mAP + 错误 + 安全 + 可维护性
从”精度就是一切”到”精度是入场券,现在谈谈这代码能否在生产环境存活”,核心转变是在研究和部署之间加了质量关卡。
专家评审
选题眼光: 这是真缺口,不是人造的。 这个领域在追逐基准数字时确实忽略了代码质量。 它处于关键拐点——自动驾驶系统正从研究走向生产,研究实践与安全标准之间的不匹配正成为瓶颈。 时机完美:已有足够部署系统让这个问题紧迫,但还没多到用惨痛教训学会这课。
方法成熟度: 这是直接的实证工作——运行现有工具、聚合结果、发现模式。 没有巧妙的算法洞察,但这里恰当。 价值在于提出问题并做苦力活,而非发明新分析技术。 更简单的方法是采样更少代码库,但178是统计有效性的合理群体规模。 CI/CD相关性分析是个好点缀,超越了单纯报告问题。
实验诚意: 基线公平——他们用标准的、成熟的静态分析工具(Pylint、Bandit、Radon)。 7.3%生产就绪数字很刺眼但根据他们的标准站得住脚。 一个担忧:“生产就绪”的定义是二元的(零严重错误),可能太苛刻。 一个有一个容易修复的严重错误的代码库,被归入根本坏掉的代码库。 论文如果有严重性加权分数会更强。 安全集中发现(前5问题=80%)令人信服,通过了嗅觉测试。
写作功力: 论文有效地前置了震撼统计(7.3%),但指南部分感觉仓促。 他们识别了前五个安全问题,但没深入解释为何这些特定模式在感知代码中如此常见。 一个案例研究,走过一个代码库从”研究原型”到”生产就绪”的旅程,会让抽象发现具体化。 相关工作部分单薄——更多与机器学习系统软件工程研究的交锋会加强定位。
判决: 弱接收 — 用扎实实证工作解决真问题,但分析可以更深,指南需要更多发展才真正可操作。
要点总结
如果你在构建任何可能投产的机器学习系统,偷走这个三工具诊断:Pylint查错误,Bandit查安全,Radon查可维护性。 从第一天就在CI/CD里运行它们,不要事后补救。 论文发现CI/CD与更好代码质量相关不令人惊讶,但这是你可以展示给认为”我们以后再清理”的管理者的证据。
安全集中洞察直接迁移:在任何代码库,少数问题类型导致大多数麻烦。 不要试图修复一切——剖析你的漏洞,找到前五个,为它们写指南,你就解决了80%的风险。 这个帕累托原则适用于自动驾驶感知之外的任何领域。
对研究者:如果你随论文发布代码,发表前运行这三个工具。 花一小时,防止你的代码库成为下一个实证研究的警示故事。 “在我机器上跑”和”别人能用这个”之间的鸿沟比你想的小,但前提是你测量它。
更广泛的教训:排行榜指标必要但不充分。 无论你领域的mAP等价物是什么,它可能在隐藏对现实世界使用重要的质量问题。 本文框架——定义最小生产标准、测量鸿沟、识别集中问题、提供针对性指南——适用于任何研究到生产的转变。