Paper: 2606.19334
Authors: Denis Peskoff, Joe Barrow, Christopher Vu, Diag Davenport
Categories: cs.CL, cs.CY, cs.LG
The Gap
Existing legal AI research has built powerful tools for federal and state-level law—statutory texts, court opinions, and regulations—but has almost entirely ignored the local layer of governance. Municipal and county ordinances govern zoning, housing, business licensing, noise, animal control, and countless other everyday matters. Yet these texts are scattered across dozens of vendor platforms (Municode, American Legal Publishing, etc.) designed exclusively for human browsing. No machine-readable corpus exists for local ordinances at scale, so computational analyses of this crucial legal layer have been impossible.
Gap: fragmented, non-machine-readable local law → no large-scale analysis possible.
+------------------------------------------+
| Problem: local codes locked in vendor     |
| sites, not machine-readable at scale      |
+------------------------------------------+
    |
    v
+------------------------------------------+
| Assumption: OCR + scraping can cover      |
| most publicly available codes reliably    |
+------------------------------------------+
    |
    v
+------------------------------------------+
| Method: scrape vendor sites, apply OCR,   |
| harmonize to county level, release corpus |
+------------------------------------------+
    |
    v
+------------------------------------------+
| Evidence: 9,239 municipal/county codes;   |
| 2,309 counties covered; classifiers work  |
+------------------------------------------+
    |
    v
+------------------------------------------+
| Conclusion: local law is now accessible   |
| for AI research at scale                 |
+------------------------------------------+
The Increment
One sentence: Before LOCUS, local ordinances were essentially invisible to computational legal research; after LOCUS, a corpus of 9,239 codes with county-harmonized access exists, along with classifiers for previously unstudied dimensions like opacity and paternalism.
Core Mechanism
The pipeline has two main stages: corpus construction and classifier training.
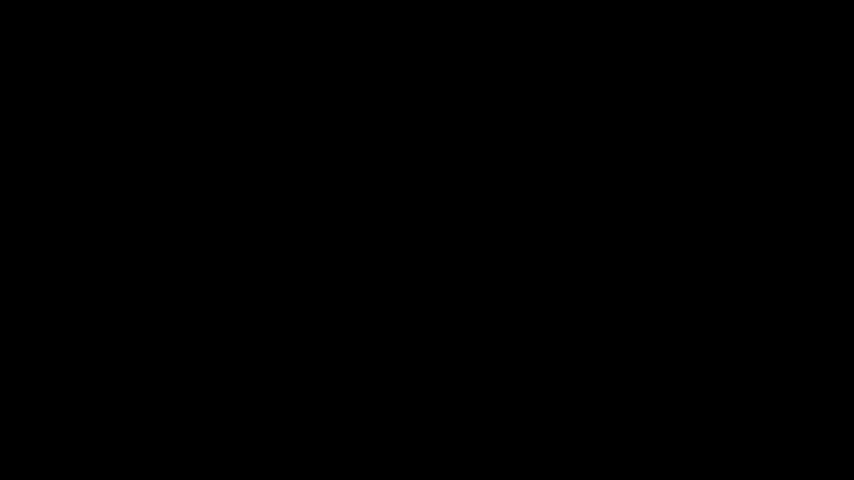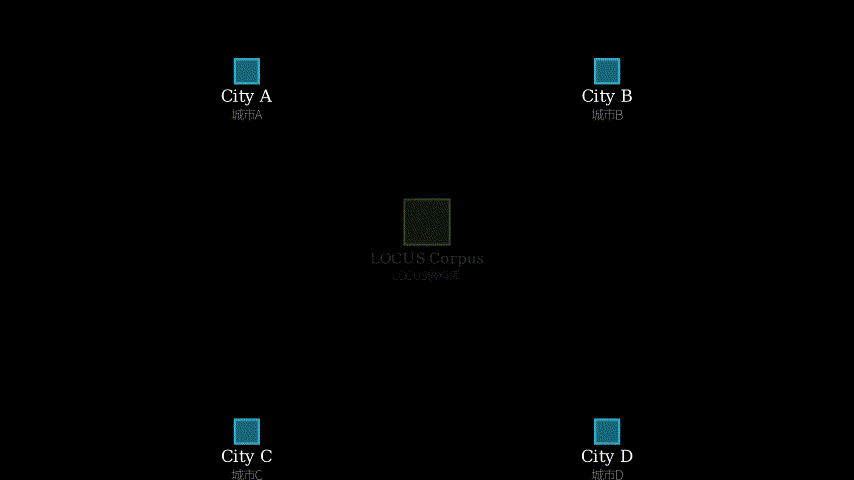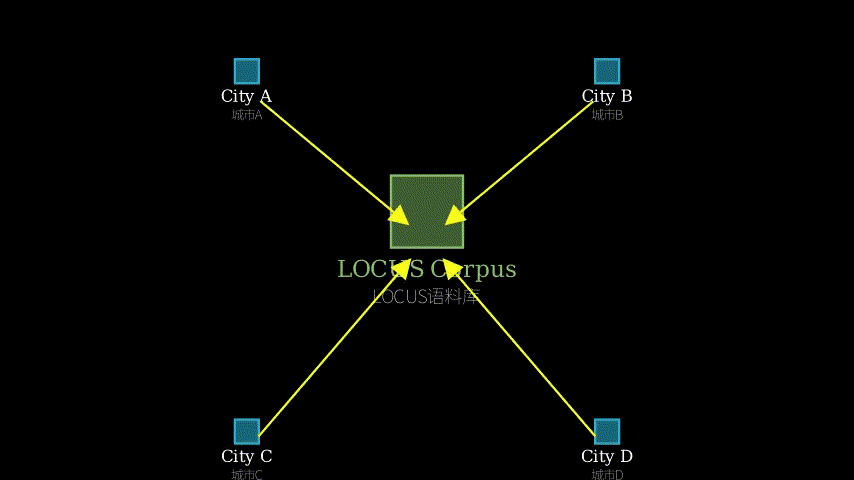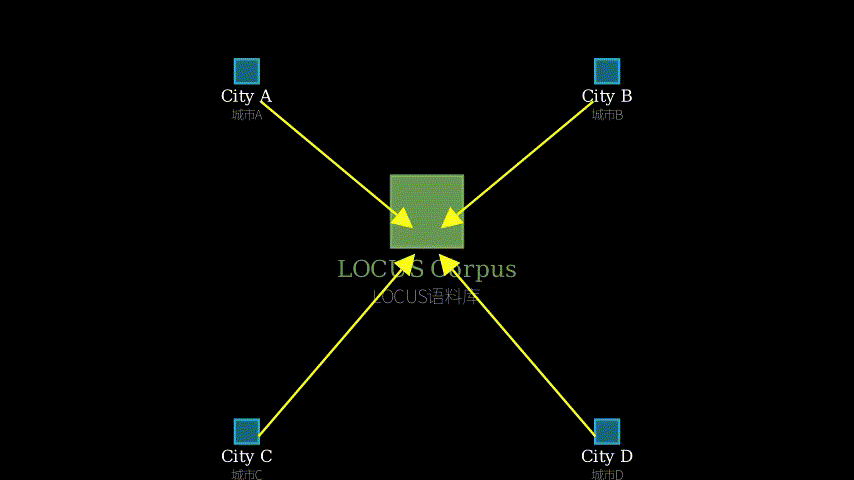
Corpus construction begins by identifying available ordinance codes across publisher platforms (Municode, American Legal, General Code, etc.). The authors wrote custom scrapers for each platform, handling everything from HTML tables to PDF images. Because many older codes exist only as scanned documents, they apply a standard OCR pipeline (Tesseract with language-specific fine-tuning) to extract machine-readable text. The raw output is then cleaned: removing headers/footers, normalizing whitespace, and discarding non-legal boilerplate. Finally, they map each municipality to its county using US Census geographic data, creating a “county-harmonized” access layer that aggregates ordinances for the largest 2,309 counties (covering ~90% of the US population).
Classifier training uses a ModernBERT model fine-tuned on manually labeled samples from the corpus. Two classification tasks are introduced: opacity (how hard is the text for a layperson to understand) and paternalism (how much does the law restrict individual choice for the person’s own good). A third scorer estimates the topic of each ordinance (zoning, noise, etc.). These classifiers enable large-scale analysis of legal language patterns that were previously infeasible.
            +---------------------------+
            | Vendor Platforms          |
            | (Municode, AmerLegal,..) |
            +---------------------------+
                       |
                       v
            +---------------------------+
            | Custom Scrapers (per plat)|
            | HTML, PDF, scanned images |
            +---------------------------+
                       |
                       v
            +---------------------------+
            | OCR pipeline (Tesseract)  |
            | + text cleaning           |
            +---------------------------+
                       |
                       v
            +---------------------------+
            | Raw Corpus (9,239 codes) |
            +---------------------------+
                       |
                       v
            +---------------------------+
            | County Harmonization      |
            | (municipality -> county)  |
            +---------------------------+
                       |
            +----------+----------+
            |                     |
            v                     v
    +---------------+     +----------------+
    | Access Layer   |     | Classification |
    | (2,309 counties)|     | (ModernBERT)  |
    +---------------+     | opacity,       |
                          | paternalism,   |
                          | topic          |
                          +----------------+
Structural metaphor: Think of LOCUS like a universal restaurant menu aggregator for a sprawling metropolitan area. Previously, each neighborhood restaurant (municipality) had its own menu (ordinance) written in different formats—some hand-written on paper (scanned PDFs), some typed on a website (HTML), some even illegible due to bad photocopies. These menus were posted on different delivery apps (vendor platforms) with no consistency. LOCUS is the equivalent of a new service that sends crawlers to every corner of the city, takes photos of every menu, runs them through an OCR system (a waiter who can read the smudged handwriting), and standardizes them into a uniform digital format. Then it adds a crucial layer: it sorts all menus by delivery zone (county). Now a researcher can say “show me all restaurant policies in the Los Angeles county zone” and instantly get the aggregated, machine-readable text. The classifiers (opacity, paternalism) are like automated food critics that can scan the entire menu collection and flag every dish as “confusing description” or “overly restrictive portion size.”
Key Concepts
-
OCR for Legal Documents: Optical character recognition converts scanned images of text into machine-readable strings. For older ordinances—often printed in small fonts on yellowed paper—standard OCR tools struggle. The authors use Tesseract with custom post-processing (e.g., removing repeated footers, fixing misrecognized legal symbols like §). Example: a 1980s zoning code scanned as a TIFF image becomes raw text output like “Sec. 10-4. Permitted uses: single-family dwellings” after OCR cleanup.
-
County-Harmonized Access Layer: Because a single county may contain dozens of municipalities, raw city-level data is messy for regional studies. LOCUS groups all codes under their county, using the county’s FIPS code as key. This allows a researcher to say “analyze all housing ordinances in counties with population > 500k” and get a unified dataset. Example: All city codes within Los Angeles County (L.A., Long Beach, Glendale, etc.) are bundled under a single county entry.
-
Legal Opacity and Paternalism: Opacity measures how difficult an ordinance is for an ordinary citizen to understand—shorter sentences, simpler words, clear structure mean lower opacity. Paternalism measures the degree to which a law restricts individual behavior for the person’s own welfare (e.g., mandatory seatbelt laws vs. noise curfews). These are novel annotation dimensions for legal AI; prior work focused on jurisdiction or topic classification. Example: An ordinance saying “No person shall operate a sound-producing device at a volume exceeding 65 decibels between 10 p.m. and 7 a.m.” is low opacity (clear) and medium paternalism (restricts behavior but for community good, not individual).
Framework Shift
The mainstream approach to legal AI research has been to work with well-curated corpora of federal and state law (e.g., CourtListener, Caselaw Access Project, State Statutes). This paper shifts the practice by demonstrating that local law can be systematically collected and analyzed at scale, and that the county level serves as a natural organizing unit.
Before (mainstream approach):        After (this paper):
+-----------------+                 +----------------------+
| Federal/State    |                 | Federal/State         |
| law corpora      |                 | law corpora           |
+-----------------+                 +----------------------+
        |                                    |         +
        v                                    |         |
[analysis limited to                       [analysis extends]
 upper layers]                             [to local ordinances]
                                           |         +
                                           v         v
                                    +----------------------+
                                    | LOCUS corpus         |
                                    | 9,239 codes          |
                                    | county-harmonized    |
                                    +----------------------+
                                            |
                                            v
                                    [opacity, paternalism,
                                     topic analysis at scale]
One sentence: From ignoring local law to systematically including it, the core shift is building a scalable, reproducible pipeline for ordinances, with county-level access enabling new types of legal analysis.
Expert Assessment
Problem choice: Real gap, and a smart one. Local ordinances affect people’s daily lives more than federal law in many domains (where to park, what you can build, noise limits), yet they are almost absent from legal AI. The authors correctly identified that the fragmentation was a data infrastructure problem, not a methodological one.
Method maturity: Mostly engineering brute force—scraping hundreds of thousands of documents is hard work, not a clever algorithm. The OCR pipeline is standard but robustly applied. The classifier training is straightforward fine-tuning. There are simpler approaches (e.g., using existing commercial legal databases) but they are not publicly accessible, so this is a necessary effort. I’d call it solid applied work, not method innovation.
Experimental integrity: No baselines are reported for the classification tasks because they are new—there’s nothing to compare against. That’s honest but makes it hard to gauge absolute quality. The manual annotation for opacity and paternalism is subjective; inter-annotator agreement would strengthen the paper. No mention of error analysis for OCR (e.g., how many codes failed completely). The coverage claim “nearly all publicly available” is plausible but not verified against an independent list. One red flag: the release is “available to researchers” but not truly open; the terms of access might limit reproducibility.
Writing quality: Clear overall, but the classifier section feels rushed. The definitions of opacity and paternalism are hand-wavy, and the reader is left wondering “how do you actually label an ordinance as paternalistic?” The paper would benefit from examples of high opacity vs. low opacity texts, and a discussion of edge cases. The metaphor-heavy explanation of the pipeline works well for the abstract.
Verdict: Weak accept — the corpus fills a genuine need and enables new research, but the paper’s novelty is primarily in data collection rather than method or insight. It’s worth attention for anyone working on legal AI or computational legal studies, but not a must-read for the general ML community.
Takeaways
- Reusable scraping + OCR pipeline for diverse document formats: If you need to collect legal texts from vendor-locked platforms, the pattern of custom scrapers per source, OCR for scanned documents, and cleaning steps can be directly adapted.
- County as a natural unit for legal analysis: Federal and state get all the attention, but counties are the level at which many policies (zoning, health, business licenses) are actually implemented. Researchers should consider county-harmonized datasets for local policy studies.
- Practical classifier for legal text simplicity: The opacity classifier, while preliminary, could be used to flag hard-to-read ordinances for reform. Local governments often want to make their laws more accessible—this gives a metric to guide that effort.
- Limitation acknowledged: The corpus is not fully open; the access model should be examined if you plan to build on it. Also, static since 2023 (version v1) — ordinances change, so updating is an open problem.
论文: 2606.19334
作者: Denis Peskoff, Joe Barrow, Christopher Vu, Diag Davenport
分类: cs.CL, cs.CY, cs.LG
缺口
现有的法律AI研究在联邦和州级法律——成文法、司法意见、行政法规——上取得了重大进展,但几乎完全忽略了地方治理层。市政和县级法规管制着分区、住房、商业许可、噪音、动物管理等日常事务。然而这些文本散落在数十个供应商平台(Municode、American Legal Publishing等)上,这些平台仅为人眼浏览而设计。尚无机器可读的法规语料库可用于大规模分析,因此对这一关键法律层的计算分析一直不可能。
缺口:碎片化、非机器可读的地方法律 → 无法进行大规模分析。
+------------------------------------------+
| 问题:地方法规被困在供应商网站,           |
| 无法大规模机器读取                         |
+------------------------------------------+
    |
    v
+------------------------------------------+
| 假设:OCR + 爬取可以可靠覆盖大部分         |
| 公开可用的法规                             |
+------------------------------------------+
    |
    v
+------------------------------------------+
| 方法:爬取供应商网站,应用OCR,             |
| 统一到县级,发布语料库                     |
+------------------------------------------+
    |
    v
+------------------------------------------+
| 证据:9,239个市/县级法规;                 |
| 2,309个县被覆盖;分类器有效                |
+------------------------------------------+
    |
    v
+------------------------------------------+
| 结论:地方法律现在可以大规模用于            |
| AI研究                                     |
+------------------------------------------+
增量
一句话: 在LOCUS之前,地方法规对计算性法律研究来说几乎不可见;在LOCUS之后,一个包含9,239套法规、支持县级访问的语料库诞生了,并配有用于分析法律模糊性和家长主义等此前未研究过的维度的分类器。
核心机制
管道分为两个主要阶段:语料库构建和分类器训练。
语料库构建从识别各发布平台(Municode、American Legal、General Code等)上的可用法规代码开始。作者为每个平台编写了自定义爬虫,处理从HTML表格到PDF图像的各种格式。由于许多旧法规仅以扫描件形式存在,他们应用标准OCR流程(Tesseract配合语言特定微调)提取机器可读文本。原始输出经过清洗:移除页眉页脚、标准化空格、丢弃非法律性的样板内容。最后,使用美国人口普查的地理数据将每个城市映射到其所属县,创建一个”县级统一”的访问层,覆盖最大的2,309个县(约占美国人口的90%)。
分类器训练使用在语料库中手动标注样本上微调的ModernBERT模型。引入了两个分类任务:模糊性(文本对普通人来说有多难理解)和家长主义(法律在多大程度上为了个人自身利益限制个人选择)。第三个评分器估计每部法规的主题(分区、噪音等)。这些分类器使得以前不可行的大规模法律语言模式分析成为可能。
            +---------------------------+
            | 供应商平台                  |
            | (Municode, AmerLegal,...) |
            +---------------------------+
                       |
                       v
            +---------------------------+
            | 自定义爬虫(每个平台不同)    |
            | HTML, PDF, 扫描图像        |
            +---------------------------+
                       |
                       v
            +---------------------------+
            | OCR流程 (Tesseract)       |
            | + 文本清洗                 |
            +---------------------------+
                       |
                       v
            +---------------------------+
            | 原始语料 (9,239套法规)    |
            +---------------------------+
                       |
                       v
            +---------------------------+
            | 县级统一                   |
            | (城市 -> 县)              |
            +---------------------------+
                       |
            +----------+----------+
            |                     |
            v                     v
    +---------------+     +----------------+
    | 访问层         |     | 分类器         |
    | (2,309个县)   |     | (ModernBERT)  |
    +---------------+     | 模糊性,        |
                          | 家长主义,       |
                          | 主题            |
                          +----------------+
结构比喻:把LOCUS想象成一个大城市里的万能餐厅菜单聚合器。以前,每家社区餐厅(城市)都有自己的菜单(法规),写法各不相同——有的手写在纸上(扫描的PDF),有的打印在网站页面上(HTML),有的甚至因为复印模糊难以辨认。这些菜单发布在不同的外卖APP上(供应商平台),毫无一致性。LOCUS就像一项新服务:派爬虫到城市的每个角落,给每份菜单拍照,通过一个OCR系统(看得清潦草字迹的服务员)识别,并标准化成统一的数字格式。然后添加关键一步:按配送区域(县)对所有菜单分类。现在研究人员可以说”显示洛杉矶县区域内所有餐厅的政策”,立刻得到聚合的、机器可读的文本。分类器(模糊性、家长主义)就像自动化的美食评论家,可以扫描整个菜单集合并把每道菜标注为”描述令人困惑”或”份量限制过度”。
关键概念
-
法律文档的OCR:光学字符识别将扫描图像中的文字转换为机器可读字符串。对于较旧的法规——通常以很小的字体印刷在泛黄的纸张上——标准OCR工具有困难。作者使用Tesseract配合自定义后处理(例如移除重复的页脚、修正误识别的法律符号如§)。例如,1980年代的分区法规扫描为TIFF图像,经过OCR清洗后变成像”Sec. 10-4. 允许用途:独户住宅”这样的原始文本输出。
-
县级统一访问层:因为一个县可能包含数十个城市,原始的市级数据对于区域研究来说太杂乱。LOCUS将所有法规归到其所在的县下,使用县的FIPS代码作为键。这让研究人员可以说”分析人口超过50万的县中的所有住房法规”,得到一个统一数据集。例如,洛杉矶县内所有城市法规(洛杉矶、长滩、格伦代尔等)都被捆绑在一个县级条目下。
-
法律模糊性与家长主义:模糊性衡量一部法规对于普通市民来说有多难理解——句子越短、词汇越简单、结构越清晰,模糊性越低。家长主义衡量法律在多大程度上为了个人自身福祉而限制个人行为(例如强制安全带法 vs. 噪音宵禁)。这些是法律AI中全新的标注维度;此前的研究只关注管辖权或主题分类。例子:一部法规说”任何人不得在晚上10点到早上7点之间以超过65分贝的音量操作发声设备”,其模糊性低(清晰),家长主义中等(限制行为但为了社区利益,而非个人利益)。
框架转变
主流法律AI研究的方法是使用联邦和州级法律的精心策划语料库(如CourtListener、Caselaw Access Project、州法规)。这篇论文通过证明地方法律可以系统性地大规模收集和分析,并且县级是自然的组织单元,转变了实践。
之前(主流方法):                之后(本文方法):
+-----------------+              +----------------------+
| 联邦/州级        |              | 联邦/州级             |
| 法律语料库       |              | 法律语料库            |
+-----------------+              +----------------------+
        |                                   |         +
        v                                   |         |
[分析仅限于上层]                           [分析扩展到]
                                           [地方法规]
                                            |         +
                                            v         v
                                     +----------------------+
                                     | LOCUS语料库          |
                                     | 9,239套法规          |
                                     | 县级统一              |
                                     +----------------------+
                                             |
                                             v
                                     [模糊性、家长主义、
                                      主题规模分析]
一句话: 从忽视地方法律到系统性地纳入,核心转变是构建了一个可扩展、可复现的法规采集管道,并通过县级访问支持新的法律分析类型。
专家评审
选题眼光:真实缺口,而且很聪明。地方法规在许多领域(哪里能停车、能盖什么、噪音限制)比联邦法更直接影响人们的日常生活,却在法律AI中几乎缺席。作者正确地识别出碎片化是数据基础设施问题,而非方法论问题。
方法成熟度:主要是工程上的蛮力——爬取几十万份文档是辛苦活,不是巧妙的算法。OCR流程标准但应用扎实。分类器训练是直接的微调。存在更简单的方法(例如使用现有的商业法律数据库),但它们并非公开可访问,因此这是必要的努力。我认为是扎实的应用工作,而非方法创新。
实验诚意:由于分类任务是全新的,没有可对比的基线——这很诚实,但也让绝对质量的评估变得困难。模糊性和家长主义的手动标注是主观的;标注者间一致性本可以增强论文可信度。没有对OCR进行错误分析(例如多少法规完全失败)。覆盖范围声称”几乎所有公开可用的”是合理的,但未根据独立列表验证。一个警示:语料库”可供研究人员使用”,但并非真正开放;访问条款可能限制可复现性。
写作功力:整体清晰,但分类器部分显得仓促。模糊性和家长主义的定义有些模糊,读者会想知道”你怎么实际标注一部法规为家长主义?“论文如果能提供高模糊性 vs 低模糊性的文本示例,并讨论边缘情况,会更好。管道的比喻式解释有效,但论文本身可以更紧凑。
判决:弱接收——语料库填补了真实需求并启发了新研究,但论文的创新主要集中在数据收集,而非方法或洞察。对于从事法律AI或计算性法律研究的人来说值得关注,但对通用ML社区并非必读。
要点总结
- 可复用的爬取+OCR管道:如果你需要从供应商锁定的平台收集法律文本,为每个来源编写自定义爬虫、对扫描件使用OCR、进行清洗的框架可以直接迁移。
- 县级作为法律分析的自然单元:联邦和州级得到大量关注,但县是许多政策(分区、健康、商业许可)实际实施的层面。研究人员应考虑使用县级统一的数据集进行地方政策研究。
- 法律文本简洁性的实用分类器:尽管是初步的,模糊性分类器可用于标记难以理解的法规以便改革。地方政府常希望使法律更易懂——这提供了一个指导改革的指标。
- 已知局限:语料库并非完全开放;如果你计划在此基础上构建,应检查访问模式。此外,v1版本自2023年静态保存——法规会变化,如何更新仍是一个开放问题。