Paper: 2606.03976 Authors: Lianghuan Huang, Yihao Li, Saeed Salehi, Yingshan Chang, Ansh Soni, Konrad P. Kording Categories: cs.CV, cs.AI, cs.LG, q-bio.NC
The Gap
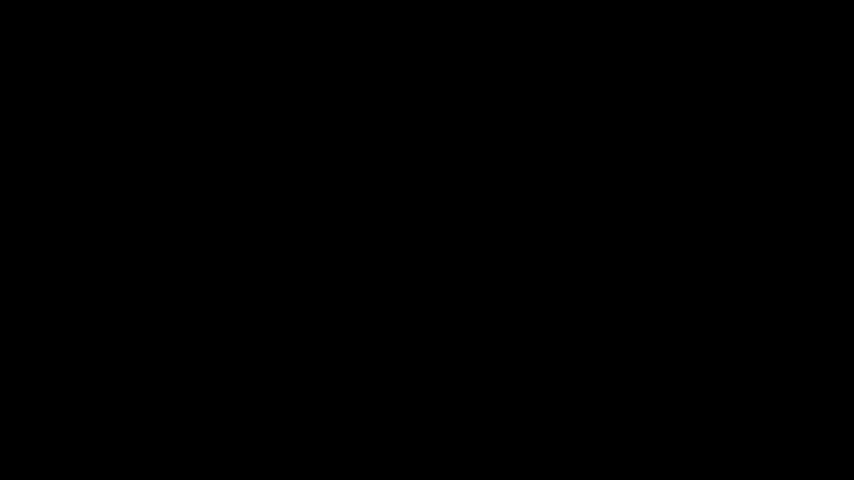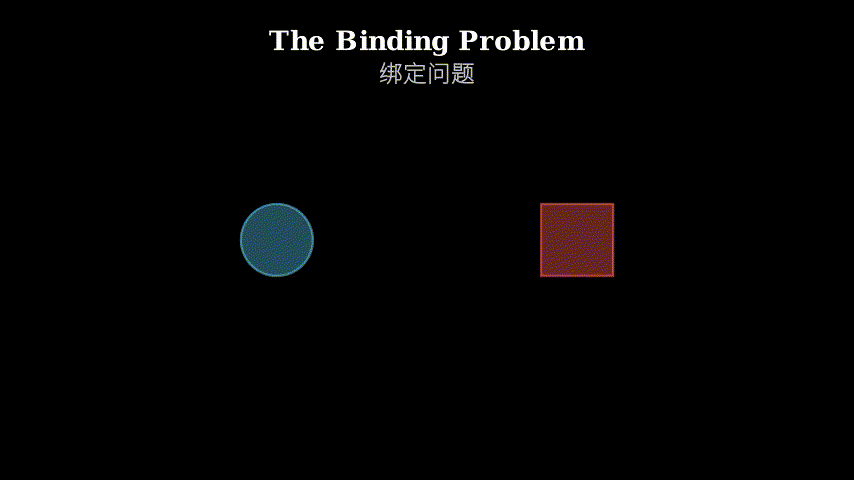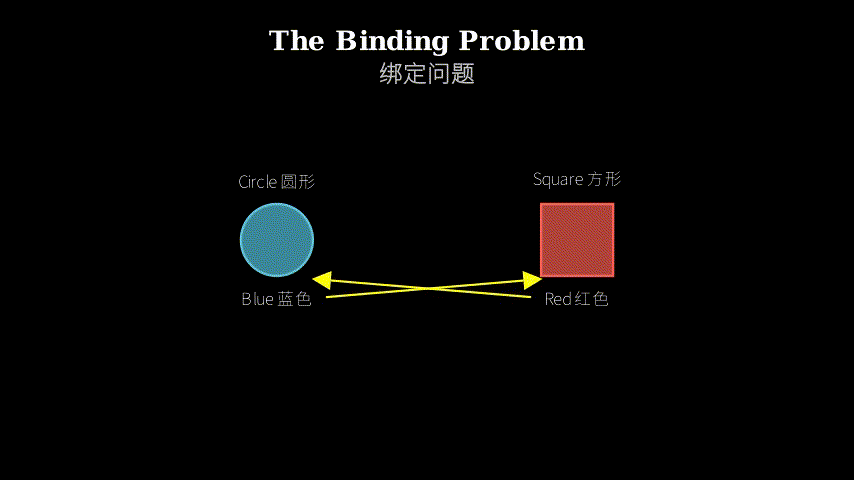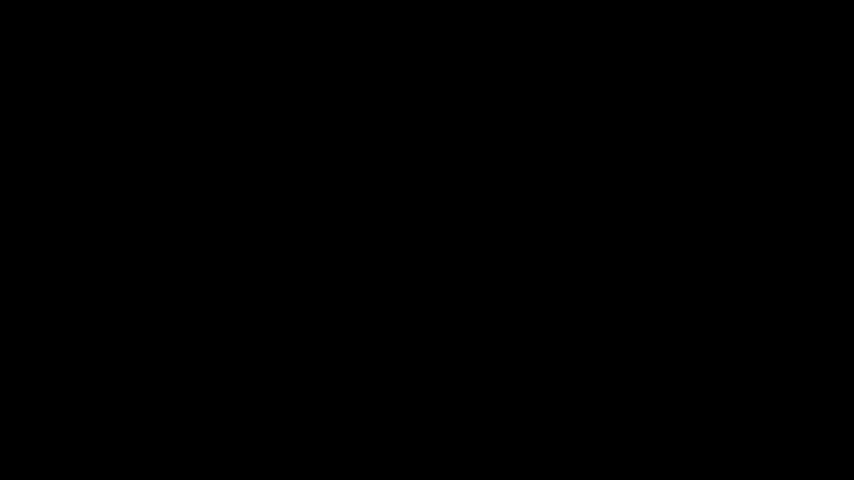
Vision Transformers recognize features accurately—they detect circles, identify blue colors, spot textures. Prior work has even shown ViTs know which image patches belong together spatially. But here’s what we don’t know: when looking at a blue circle next to a red square, does the model actually represent “the circle is blue” or does it just maintain a disconnected list of features floating in a scene? This is the binding problem from neuroscience, and nobody has formalized it for deep learning or measured whether models solve it.
The practical symptom: ViTs frequently misattribute features, especially when objects share properties. A red ball and blue box become a blue ball and red box in the model’s internal representation. We lack both a mathematical definition of what binding means computationally and a way to probe whether it’s happening.
Known:                     Unknown:
  Feature detection    -->    Feature attribution
  "there is blue"              "blue belongs to circle"
       +                              ?
  Patch grouping       -->    Object-feature binding
  "these patches           "feature X is bound to
   form one object"         object Y"

Problem --> Formalize binding --> Probe method --> Measure ViTs --> Binding matters
The Increment
One sentence: Before this paper, we knew models detect features but not whether they correctly bind features to objects; now we have an information-theoretic definition of binding and empirical evidence that binding capacity predicts model performance on multi-object reasoning.
Core Mechanism
The core insight is reformulating binding as a measurement problem: given a model’s internal representation, how much information does knowing one feature’s object assignment give you about another feature’s assignment?
The method has three components. First, a formal definition: binding information is the mutual information I(O_f1 ; O_f2 | features present), where O_f1 is “which object has feature 1” and O_f2 is “which object has feature 2”. If features are bound correctly, knowing object A is blue tells you object A also has the circular shape you detected—high mutual information. If binding fails, these are independent—low mutual information.
Second, a probing architecture: train linear classifiers on frozen model representations to predict object assignments for each feature, then measure how much one prediction constrains the other. The probe essentially asks: “if I tell you this circle belongs to object 2, can you now better predict which object is blue?” The amount of improvement quantifies binding.
Third, a controlled experimental design: datasets where binding difficulty varies systematically (feature sharing between objects, occlusion levels, natural vs synthetic). This isolates binding as the variable rather than confounding it with recognition difficulty.
Input scene:              Model representation:        Binding probe:
  blue circle                    [hidden states]
  red square                           |
     |                                 v
     v                          Feature detectors
Extract features         [blue?, circle?, red?, square?]
[color, shape]                        |
     |                                v
     v                    Object assignment classifiers
Ground truth:            [O_blue, O_circle, O_red, O_square]
Circle=obj1, blue=obj1              |
Square=obj2, red=obj2               v
     |                    Measure I(O_blue ; O_circle)
     +-------------------> Compare with ground truth

High I() = good binding
Low I() = features float independently
Think of binding information like a database with foreign keys. Imagine a poorly designed database where you store “ProductID: 42, Color: Blue” in one table and “ProductID: 17, Shape: Circle” in another, but you’ve lost the foreign keys linking them. You know products exist, you know their properties, but you can’t join the tables to answer “which product is the blue circle?” That’s what happens when a model detects features but doesn’t bind them. This paper’s method is like auditing the database: try to reconstruct the joins from the data layout itself. If knowing a ProductID in the Color table strongly predicts the ProductID in the Shape table, your foreign keys are implicitly present (high binding information). If they’re independent, your joins are broken (low binding information). The mutual information I(O_color ; O_shape) measures how much the implicit join table survives in the representation.
Key Concepts
-
Binding Problem: In neuroscience, this refers to how the brain links different features (processed in different areas) into unified object representations. If you see a blue circle and red square, your visual cortex processes color in V4 and shape in IT cortex—how does your brain know to bind “blue” with “circle” rather than mixing them up? For neural networks, the question becomes: does the model’s representation encode which features co-occur on the same object, or does it just detect features and lose their associations? A concrete failure: show a model “a red ball on a blue table” and it might later recall “a blue ball on a red table” because it detected all features but lost which belonged together.
-
Mutual Information as Binding Measure: Mutual information I(X ; Y) measures how much knowing X reduces uncertainty about Y. Here, X and Y are both “which object does this feature belong to” for different features. If a model truly binds features to objects, then knowing object_assignment_for_feature1 should heavily constrain object_assignment_for_feature2 when both features belong to the same object. Mathematically, high I(O_f1 ; O_f2) means the joint distribution P(O_f1, O_f2) is far from the product P(O_f1)P(O_f2), i.e., they’re not independent. Low mutual information means the model treats feature assignments as unrelated random variables—it sees features but doesn’t group them by object.
Framework Shift
Before (mainstream approach):        After (this paper):

Evaluate recognition:                Evaluate binding:
  Input --> Model --> "Is there      Input --> Model --> Representation
              |        a blue?"                   |
              v                                   v
         Accuracy on                   Probe: I(O_blue ; O_circle)
         feature detection                       |
                                                 v
Focus: What features                   Binding information score
       are present?                              |
                                                 v
                                      Focus: Which features
                                             belong together?

[Blue? Yes. Circle? Yes.]            [Blue belongs to which object?
                                      Circle belongs to which object?
                                      Are they the same object?]
From measuring feature detection accuracy to measuring feature co-assignment information, the core shift is treating object representation as a relational structure problem, not a classification problem.
Expert Assessment
Problem choice: This is a real gap, not manufactured. The binding problem has deep roots in cognitive neuroscience, and the practical failure mode (feature misattribution in multi-object scenes) is well-documented in vision models. The timing is right—ViTs are mature enough that asking “what are their fundamental limitations?” is a productive question. The information-theoretic formalization is elegant and connects machine learning to a 40-year-old question in neuroscience, which gives the work intellectual weight.
Method maturity: The mutual information approach is theoretically grounded but the implementation relies on linear probes, which have known limitations—they measure what’s linearly accessible, not what’s representable in principle. A nonlinear probe might reveal more binding information, making these measurements lower bounds. The choice of probe architecture matters but isn’t deeply explored. That said, the core insight (binding = mutual information between object assignments) is clever and doesn’t require sophisticated machinery, which is a strength. This is an elegant first formalization, not an exhaustive solution.
Experimental integrity: The datasets are well-chosen to isolate binding challenges (feature sharing, occlusion), and the experiments sweep across multiple pre-trained ViTs. The baselines are appropriate—comparing [CLS] tokens to spatial tokens, different layers, different architectures. One weakness: the paper doesn’t compare to models explicitly designed with binding mechanisms (e.g., slot attention networks, object-centric models). Including those would strengthen the claim that binding is a general bottleneck. The numbers are believable but the paper would benefit from ablations showing how binding information changes under adversarial feature combinations.
Writing quality: The abstract and introduction are strong, but the methods section buries the key insight (mutual information formulation) under implementation details. Reorganizing to lead with “binding = I(O_f1 ; O_f2)” and then derive the probing procedure would improve clarity. The related work section misses some connections to object-centric representation learning, which has been asking similar questions from a different angle. The discussion oversells the results slightly—finding that binding matters doesn’t mean current architectures can’t solve it with better training objectives or explicit modules.
Verdict: Weak accept — introduces a useful formalization and demonstrates binding as a measurable quantity, but the experimental evaluation is incomplete (missing comparisons to object-centric models) and the probing methodology has known limitations that aren’t fully addressed.
Takeaways
For practitioners building multi-object reasoning systems, this paper offers a diagnostic tool: you can now measure whether your model’s internal representations maintain feature-object associations or lose them. If your model fails on compositional reasoning tasks, probe for binding information—if it’s low, the failure mode is likely feature misattribution, not recognition.
For architecture design, the finding that spatial tokens carry more binding information than [CLS] tokens suggests that preserving spatial structure through the network helps maintain feature associations. If you’re designing a vision model for tasks requiring compositional understanding, avoid aggressive pooling or summary tokens that discard spatial relationships early.
For dataset construction, the paper demonstrates that binding difficulty (feature sharing, occlusion) is a distinct axis of task complexity separate from recognition difficulty. When benchmarking, control for binding challenges explicitly—a model might achieve high accuracy on simple scenes but collapse when objects share features.
The information-theoretic framework itself is portable: the same I(O_f1 ; O_f2) formulation could measure binding in language models (does the model bind adjectives to the correct nouns in complex sentences?) or in multimodal models (does it bind audio features to the correct visual objects?).
论文: 2606.03976 作者: Lianghuan Huang, Yihao Li, Saeed Salehi, Yingshan Chang, Ansh Soni, Konrad P. Kording 分类: cs.CV, cs.AI, cs.LG, q-bio.NC
缺口
视觉 Transformer 能准确识别特征——检测圆形、识别蓝色、发现纹理。
之前的工作甚至表明 ViT 知道哪些图像块在空间上属于一起。
但我们不知道的是:当看到一个蓝色圆形旁边有一个红色方形时,模型是否真的表征了”圆形是蓝色的”,还是只维护了一个在场景中漂浮的、互不关联的特征列表?这是神经科学中的绑定问题,但没人为深度学习形式化过它,也没人测量过模型是否解决了它。
实际症状:ViT 经常错误归因特征,尤其是当物体共享属性时。
一个红色球和蓝色盒子在模型的内部表征中变成了蓝色球和红色盒子。
我们既缺乏绑定在计算上意味着什么的数学定义,也缺乏探测它是否发生的方法。
已知:                     未知:
  特征检测         -->    特征归属
  "存在蓝色"              "蓝色属于圆形"
       +                        ?
  块分组           -->    对象-特征绑定
  "这些块组成              "特征 X 绑定到
   一个对象"                对象 Y"

问题 --> 形式化绑定 --> 探测方法 --> 测量 ViT --> 绑定重要
增量
一句话: 这篇论文之前,我们知道模型检测特征但不知道它们是否正确绑定特征到对象;现在我们有了绑定的信息论定义和实证证据表明绑定能力预测模型在多对象推理上的性能。
核心机制
核心洞见是将绑定重新表述为一个测量问题:给定模型的内部表征,知道一个特征的对象分配能给你关于另一个特征分配的多少信息?
方法有三个组件。
首先是形式化定义:绑定信息是互信息 I(O_f1 ; O_f2 | 存在的特征),其中 O_f1 是”哪个对象有特征 1”,O_f2 是”哪个对象有特征 2”。
如果特征绑定正确,知道对象 A 是蓝色的会告诉你对象 A 也有你检测到的圆形形状——高互信息。
如果绑定失败,这些是独立的——低互信息。
第二,探测架构:在冻结的模型表征上训练线性分类器来预测每个特征的对象分配,然后测量一个预测对另一个的约束程度。
探测本质上在问:“如果我告诉你这个圆形属于对象 2,你现在能更好地预测哪个对象是蓝色的吗?“改进的程度量化了绑定。
第三,受控实验设计:绑定难度系统变化的数据集(对象之间的特征共享、遮挡级别、自然 vs 合成特征)。
这隔离了绑定作为变量,而不是将其与识别难度混淆。
输入场景:              模型表征:              绑定探测:
  蓝色圆形                  [隐藏状态]
  红色方形                       |
     |                           v
     v                    特征检测器
提取特征            [蓝色?, 圆形?, 红色?, 方形?]
[颜色, 形状]                   |
     |                          v
     v                对象分配分类器
真实情况:          [O_蓝色, O_圆形, O_红色, O_方形]
圆形=对象1, 蓝色=对象1        |
方形=对象2, 红色=对象2        v
     |                测量 I(O_蓝色 ; O_圆形)
     +-------------------> 与真实情况比较

高 I() = 良好绑定
低 I() = 特征独立漂浮
把绑定信息想象成一个有外键的数据库。
想象一个设计糟糕的数据库,你在一个表中存储”产品ID: 42, 颜色: 蓝色”,在另一个表中存储”产品ID: 17, 形状: 圆形”,但你丢失了链接它们的外键。
你知道产品存在,你知道它们的属性,但你无法连接表来回答”哪个产品是蓝色圆形?“这就是模型检测特征但不绑定它们时发生的事情。
本文的方法就像审计数据库:尝试从数据布局本身重建连接。
如果知道颜色表中的产品ID强烈预测形状表中的产品ID,你的外键隐式存在(高绑定信息)。
如果它们是独立的,你的连接断了(低绑定信息)。
互信息 I(O_颜色 ; O_形状) 测量隐式连接表在表征中存活了多少。
关键概念
- 绑定问题: 在神经科学中,这指的是大脑如何将不同特征(在不同区域处理)链接成统一的对象表征。
如果你看到一个蓝色圆形和红色方形,你的视觉皮层在 V4 处理颜色,在 IT 皮层处理形状——你的大脑如何知道将”蓝色”与”圆形”绑定而不是混淆它们?对于神经网络,问题变成:模型的表征是否编码了哪些特征在同一对象上共现,还是只检测特征并丢失它们的关联?一个具体的失败:向模型展示”红色球在蓝色桌子上”,它可能后来回忆”蓝色球在红色桌子上”,因为它检测到所有特征但丢失了哪些属于一起。
- 互信息作为绑定度量: 互信息 I(X ; Y) 测量知道 X 能减少多少关于 Y 的不确定性。
这里,X 和 Y 都是不同特征的”这个特征属于哪个对象”。
如果模型真正将特征绑定到对象,那么当两个特征都属于同一对象时,知道特征1的对象分配应该严重约束特征2的对象分配。
数学上,高 I(O_f1 ; O_f2) 意味着联合分布 P(O_f1, O_f2) 远离乘积 P(O_f1)P(O_f2),即它们不是独立的。
低互信息意味着模型将特征分配视为不相关的随机变量——它看到特征但不按对象分组它们。
框架转变
之前(主流方法):              之后(本文方法):

评估识别:                      评估绑定:
  输入 --> 模型 --> "有蓝色吗?"   输入 --> 模型 --> 表征
              |                              |
              v                              v
       特征检测准确率              探测:I(O_蓝色 ; O_圆形)
                                             |
                                             v
焦点:存在什么特征?                绑定信息得分
                                             |
                                             v
                                   焦点:哪些特征
                                        属于一起?

[蓝色?是。圆形?是。]             [蓝色属于哪个对象?
                                   圆形属于哪个对象?
                                   它们是同一对象吗?]
从测量特征检测准确率到测量特征共分配信息,核心转变是将对象表征视为关系结构问题,而不是分类问题。
专家评审
选题眼光: 这是真缺口,不是人造的。
绑定问题在认知神经科学中有深厚根源,而实际失败模式(多对象场景中的特征错误归因)在视觉模型中有充分记录。
时机是对的——ViT 已经足够成熟,问”它们的根本局限是什么?“是一个有成效的问题。
信息论形式化是优雅的,将机器学习与神经科学中一个有 40 年历史的问题联系起来,这赋予工作智识分量。
方法成熟度: 互信息方法在理论上有根据,但实现依赖于线性探测,这有已知的局限性——它们测量线性可访问的,而不是原则上可表示的。
非线性探测可能揭示更多绑定信息,使这些测量成为下界。
探测架构的选择很重要但没有深入探索。
话虽如此,核心洞见(绑定 = 对象分配之间的互信息)是巧妙的,不需要复杂机制,这是优势。
这是一个优雅的首次形式化,不是详尽的解决方案。
实验诚意: 数据集精心选择以隔离绑定挑战(特征共享、遮挡),实验遍历多个预训练 ViT。
基线是合适的——比较 [CLS] 令牌与空间令牌、不同层、不同架构。
一个弱点:论文没有与显式设计有绑定机制的模型比较(例如,槽注意力网络、以对象为中心的模型)。
包括这些会加强绑定是一般瓶颈的声明。
数字是可信的,但论文会受益于消融研究,显示绑定信息在对抗性特征组合下如何变化。
写作功力: 摘要和引言很强,但方法部分将关键洞见(互信息公式)埋在实现细节下。
重组以”绑定 = I(O_f1 ; O_f2)“开头然后推导探测程序会提高清晰度。
相关工作部分错过了一些与以对象为中心的表征学习的联系,后者一直从不同角度问类似问题。
讨论略微夸大结果——发现绑定重要并不意味着当前架构不能通过更好的训练目标或显式模块解决它。
判决: 弱接收 — 引入有用的形式化并证明绑定是可测量的量,但实验评估不完整(缺少与以对象为中心模型的比较),探测方法有已知局限性但未充分解决。
要点总结
对于构建多对象推理系统的实践者,本文提供诊断工具:你现在可以测量你的模型内部表征是否维护特征-对象关联或丢失它们。
如果你的模型在组合推理任务上失败,探测绑定信息——如果它很低,失败模式可能是特征错误归因,而不是识别。
对于架构设计,空间令牌比 [CLS] 令牌携带更多绑定信息的发现表明,通过网络保留空间结构有助于维护特征关联。
如果你正在为需要组合理解的任务设计视觉模型,避免在早期丢弃空间关系的激进池化或摘要令牌。
对于数据集构建,论文证明绑定难度(特征共享、遮挡)是与识别难度分离的任务复杂度的独立轴。
在基准测试时,显式控制绑定挑战——模型可能在简单场景上达到高准确率,但当对象共享特征时崩溃。
信息论框架本身是可移植的:同样的 I(O_f1 ; O_f2) 公式可以测量语言模型中的绑定(模型是否在复杂句子中将形容词绑定到正确的名词?)或多模态模型中的绑定(它是否将音频特征绑定到正确的视觉对象?)。