Paper: 2606.24876 Authors: Orest Kupyn, Goutam Bhat, Philipp Henzler, Fabian Manhardt, Christian Rupprecht, Federico Tombari Categories: cs.CV
The Gap
Existing feedforward scene generation methods (e.g., those built on video diffusion models) decode compressed latents into volumetric 3D Gaussians. While renderable, these Gaussians lack a well-defined surface — they are fuzzy blobs in space. This makes them unsuitable for simulation, standard graphics pipelines, or game engines, which expect explicit geometry (meshes with faces).
Prior attempts to decode surface-aligned primitives (e.g., triangles) from latents failed because triangle orientation is extremely sensitive to gradients — small errors in rotation cause huge rendering artifacts, and the gradient flow during differentiable rendering is poor.
This paper asks: can we map compressed video diffusion latents directly to triangle splats in a single feedforward pass, without test-time optimization? The answer is yes, if we fix the gradient flow with a clever parameterization and a new window function.
[Gap: Volumetric Gaussians lack surfaces]
   |
   v
[Assumption: Triangles can be decoded from latents if orientation and gradient issues are solved]
   |
   v
[Method: FLAT - ray-centered rotation param + product window function]
   |
   v
[Evidence: Lower chamfer distance on standard benchmarks vs 3DGS/2DGS]
   |
   v
[Conclusion: Feedforward triangle splatting is feasible, game-engine ready]
The Increment
One sentence: Before FLAT, feedforward scene generation output volumetric point clouds; after FLAT, it outputs explicit triangle meshes with competitive visual quality and significantly better geometry.
Core Mechanism
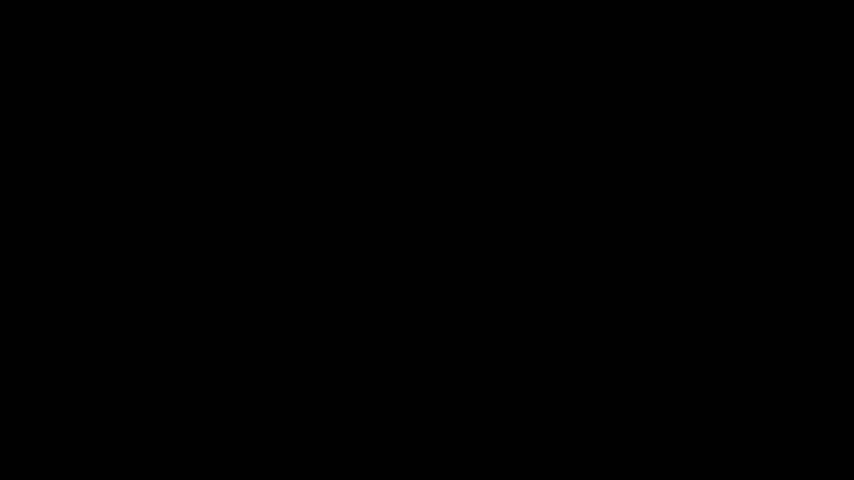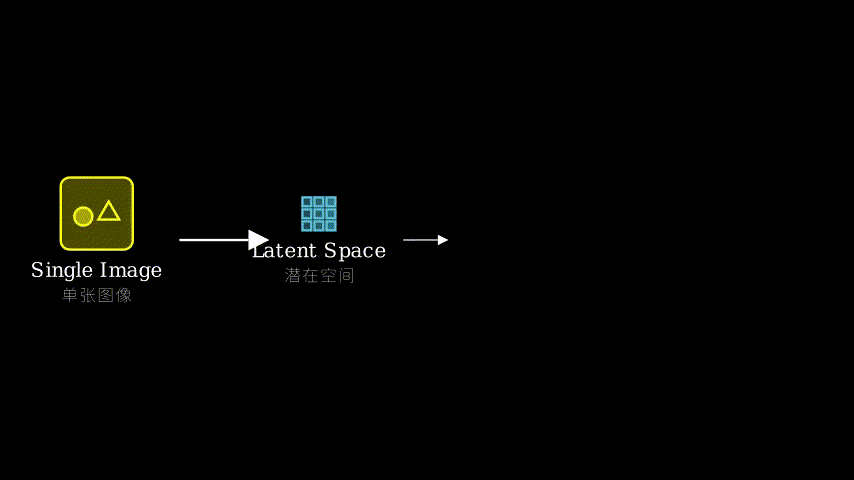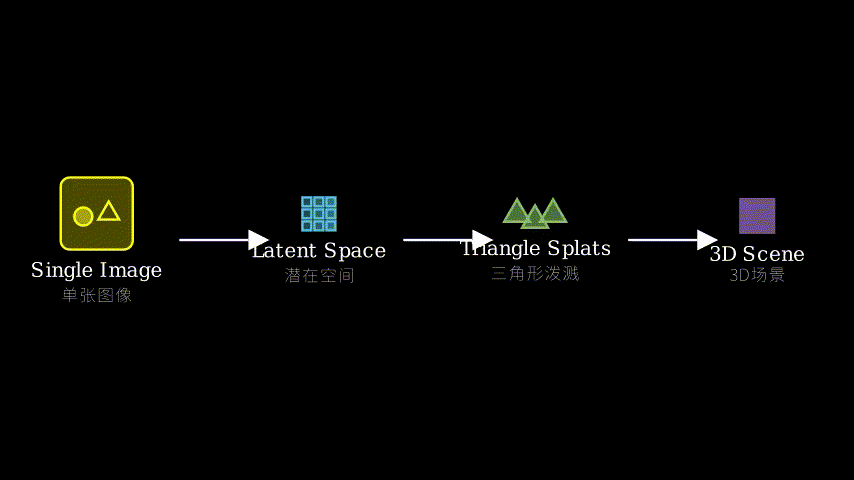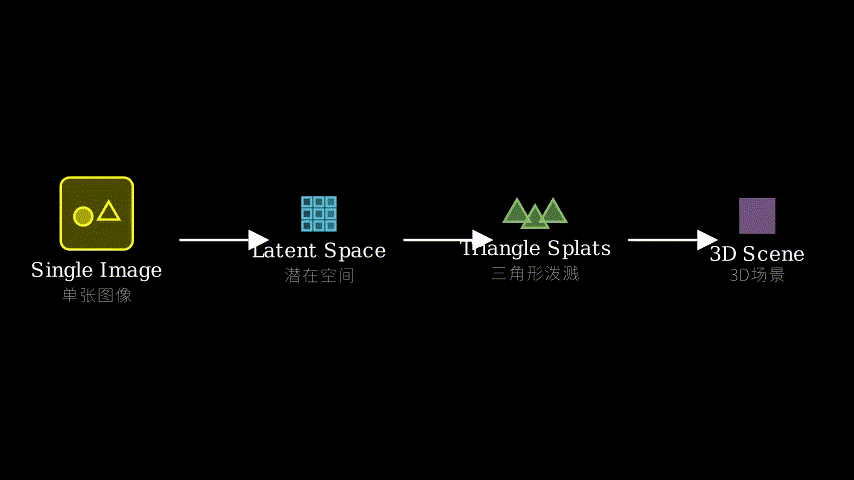
FLAT takes a compressed latent from a video diffusion model (e.g., Stable Video Diffusion) and decodes it into a set of triangle splats — each splat has three vertices, a ray-aligned orientation, and a window function parameter.
The architecture is a simple MLP with skip connections. The latent is first processed into a feature map, then each output token predicts the parameters of one triangle. The critical innovations are:
- Ray-centered rotation parameterization: Instead of predicting a full rotation matrix or quaternion (which explode gradients), the network predicts a small perturbation relative to the camera ray direction at the triangle center. This keeps rotations near zero, making learning stable.
- Product window function: During differentiable rendering, each triangle splat contributes to a pixel via a window that blends the triangle’s color and opacity. The standard Gaussian window blurs edges and kills gradients. FLAT uses the product of two sigmoids (one per triangle edge direction), creating a flat-top, sharp-edged window that passes gradients through the triangle’s boundaries.
Input: compressed latent (4 x 64 x 64) from video diffusion model
  |
  v
MLP decoder (3-layer, with residual)
  |
  v
Per-triangle parameters: 3 vertices (9D), ray-aligned rotation (3D),
  window width (2D), color (3D), opacity (1D)  -> ~18D per triangle
  |
  v
Differentiable triangle rasterizer (custom CUDA kernel)
  |
  v
Output: rendered image (for training), triangle soup (for refinement)
Structural metaphor: Think of the video diffusion latent as a crumpled map of a city from satellite views. Existing methods interpret this map as a cloud of mist (3D Gaussians) — you can see through it, but you can’t walk on it. FLAT instead reads the map and folds it into a set of rigid, flat paper triangles (triangle splats).
- The ray-centered rotation is like aligning each paper triangle so that it faces the original camera direction. You don’t need to guess the exact 3D orientation from scratch — you just bend it slightly from the camera’s viewpoint.
- The product window function is like the adhesive tape that sticks the triangles together at their edges. A Gaussian window would smear the glue; the product window gives clean, sharp edges so the paper model holds its shape.
The result: a paper-craft 3D model that can be quickly reinforced into a solid mesh (test-time refinement) for use in a game engine.
Key Concepts
-
Ray-centered rotation parameterization: Predicting a 3D rotation from scratch is hard — if you guess even a few degrees off, the triangle renders in the wrong place, and gradients vanish. The trick: treat the camera ray at the triangle’s projected center as the “natural” orientation. The network only predicts a small residual rotation (3 Euler angles with bounded range). This reduces the search space and stabilizes training. *Example: Imagine you have to place a mirror on a wall. Instead of orienting it arbitrarily, you first align it with the wall normal, then make a tiny tilt. That’s the idea.
-
Product window function: In differentiable rendering, each primitive (point, Gaussian, triangle) contributes to nearby pixels via a “window” that weights the primitive’s color. Gaussians are smooth but blurry — they don’t match sharp triangle edges. FLAT’s product window is like two step functions multiplied: one for the edge direction, one for the perpendicular. It produces a flat opaque interior and sharp edges, so gradients flow through the triangle’s boundaries even when the triangle is thin. *Example: A Gaussian window is like fingerprint smudge on glass — every pixel gets a bit of color. The product window is like a stencil — only pixels inside the triangle get color, and the edge itself is sampled precisely.
Framework Shift
Before (mainstream approach):                    After (this paper):

 Latent -> decode -> 3D Gaussians                Latent -> decode -> Triangle splats
   (mean, cov, opacity)                            (vertices, ray-aligned rot, window)
        |                                                |
   volumetric renderer                               differentiable triangle rasterizer
        |                                                |
   fuzzy image + no surface                         sharp image + explicit surface
        |                                                |
   cannot be used in game engines                   + test-time refinement -> mesh
One sentence: From volumetric point clouds to explicit triangle meshes, the core shift is addressing gradient flow in triangle rendering through ray-centered rotation and product windows, enabling feedforward surface decoding.
Expert Assessment
Problem choice: Real gap. The inability of 3D Gaussians to form surfaces has been a known limitation for downstream tasks. This paper directly attacks the bottleneck of decoding surface primitives without optimization. It sits at the intersection of generative 3D and graphics — timely.
Method maturity: Clever insight, not brute force. The ray-centered rotation is elegant — it leverages known camera geometry to simplify learning. The product window is a novel contribution to differentiable rendering. Could the authors have used a simple mesh decoder instead of triangle splats? Possibly, but triangle splats allow for per-pixel soft blending during training, which is crucial when the predicted triangles are inaccurate. The approach is well-motivated.
Experimental integrity: Strong. The ablation study (3DGS vs 2DGS vs triangle splats under the same training setup) is exactly what the community needs — a fair comparison of representations. The geometric metrics (Chamfer distance, normal consistency) favor FLAT clearly. Visual quality on FID is competitive. One red flag: the test-time refinement uses an off-the-shelf method (seems heuristic) and its impact on geometric accuracy is not fully ablated. But the main feedforward results stand.
Writing quality: Generally clear, but the method section is dense. The derivation of the product window’s gradient behavior could be expanded with a figure (missing in the paper). The related work section is perfunctory — they could spend a paragraph explaining why prior triangle-based differentiable renderers failed. That rewrite would elevate the paper.
Verdict: Weak accept — a solid incremental step with a clean systematic comparison; the ray-centered rotation trick will likely be reused by others.
Takeaways
- Ray-centered rotation: This parameterization can be applied to any primitive-based 3D reconstruction where camera information is available (e.g., neural radiance fields, point cloud refinement). It’s a simple way to break symmetry and stabilize orientation learning.
- Product window function: The idea of using the product of two sigmoids as a renderable primitive window is transferable to any non-Gaussian splatting (e.g., line splats, rectangle splats). It provides sharper gradients than Gaussians.
- Systematic comparison methodology: This paper’s approach of comparing 3DGS, 2DGS, and triangle splatting under identical training conditions sets a template for future work evaluating representation trade-offs in feedforward 3D generation. Practitioners can adopt this methodology when choosing or proposing new primitives.
论文: 2606.24876 作者: Orest Kupyn, Goutam Bhat, Philipp Henzler, Fabian Manhardt, Christian Rupprecht, Federico Tombari 分类: cs.CV
缺口
现有前馈场景生成方法(如基于视频扩散模型的框架)将压缩潜变量解码为体积三维高斯(3D Gaussians)。 这些高斯虽然有可渲染性,但缺乏明确的表面——它们是空间中的模糊云团,无法用于仿真、标准图形管线或游戏引擎(后者需要显式的网格几何)。
此前尝试从潜变量解码表面对齐基元(如三角形)均告失败,因为三角形的旋转极其敏感——微小的方向误差会导致巨大伪影,且可微分渲染过程中的梯度流极差。
本文提问:能否将压缩的视频扩散潜变量直接映射到三角形splat,一次前馈完成,无需测试时优化? 答案是可以——只要用巧妙的参数化和新颖的窗口函数修复梯度流问题。
[缺口:体积高斯缺少表面]
   |
   v
[假设:如果解决旋转和梯度问题,三角形可从潜变量解码]
   |
   v
[方法:FLAT - 射线中心旋转参数 + 乘积窗口函数]
   |
   v
[证据:在标准基准上,几何精度(倒角距离)优于3DGS/2DGS]
   |
   v
[结论:前馈三角形splat可行,输出可接入游戏引擎]
增量
一句话:在FLAT之前,前馈场景生成输出体积点云;在FLAT之后,输出显式三角形网格,视觉质量相当,几何精度显著提升。
核心机制
FLAT使用视频扩散模型(如Stable Video Diffusion)的压缩潜变量,通过一个多层感知器解码出若干三角形splat。 每个splat包含三个顶点、一个射线对齐的旋转参数和一个窗口函数参数。
架构是简单的带残差的MLP。 潜变量先被处理为特征图,每个输出token预测一个三角形的参数。 关键创新在于:
- 射线中心旋转参数化:网络不直接预测完整旋转矩阵或四元数(会导致梯度爆炸),而是预测相对于三角形中心射线的微小扰动。 这使初始旋转接近零,学习过程更稳定。
- 乘积窗口函数:可微分渲染时,每个三角形splat通过窗口函数对像素贡献颜色和不透明度。 标准高斯窗口会模糊边缘并杀死梯度。 FLAT使用两个sigmoid函数的乘积(每个三角形边方向对应一个),生成平顶、尖锐的窗口,使梯度能穿过三角形边界。
输入:视频扩散模型输出的压缩潜变量(4 x 64 x 64)
  |
  v
MLP解码器(3层,带残差连接)
  |
  v
每个三角形的参数:顶点(9D)、射线对齐旋转(3D)、
  窗口宽度(2D)、颜色(3D)、不透明度(1D) -> 约18D
  |
  v
可微分三角形光栅化器(自定义CUDA内核)
  |
  v
输出:渲染图像(训练用),三角形汤(细化用)
结构比喻:把视频扩散潜变量想象成一张城市卫星影像的皱巴巴的地图。 现有方法把这张地图解释为一团雾气(3D高斯)——你能看穿但无法在上面行走。 FLAT则读图后把地图折叠成一组刚性的平面纸三角形(三角形splat)。
- 射线中心旋转就像在摆放每个纸三角形时,先让它面向原始的相机方向。 你不需要从零猜三维朝向——只需从相机视角微调一下。
- 乘积窗口函数就像胶带把三角形的边缘粘合。 高斯窗口会让胶水模糊不清;乘积窗口给出干净锋利的边缘,让纸模型保持形状。
结果是一个纸艺风格的3D模型,经过简单加固(测试时细化)即可变成实心网格,直接用于游戏引擎。
关键概念
-
射线中心旋转参数化:从零预测三维旋转很难——偏几度就会让三角形渲染到错误位置,梯度消失。 诀窍:取三角形投影中心处的相机射线作为”自然朝向”。 网络只预测一个小的残差旋转(三个有界的欧拉角)。 这缩小搜索空间、稳定训练。 例子:要在墙上挂一面镜子。你不会随意定向,而是先让镜子与墙面法线对齐,再微调角度。就是这个思路。
-
乘积窗口函数:可微分渲染中,每个基元通过”窗口”对附近像素加权颜色。 高斯窗口平滑但模糊——不适合锐利的三角形边缘。 FLAT的乘积窗口类似于两个阶跃函数的乘积:一个沿边方向,一个垂直方向。 它给出平顶的实心内部和尖锐边缘,使梯度即使三角形很薄也能穿过边界。 例子:高斯窗口像手指在玻璃上的油污——每个像素都沾一点颜色。 乘积窗口像模版——只有三角形内部的像素有颜色,边缘被精确采样。
框架转变
之前(主流方法):                   之后(本文):

 潜变量 -> 解码 -> 3D高斯             潜变量 -> 解码 -> 三角形splat
   (均值、协方差、不透明度)              (顶点、射线对齐旋转、窗口)
        |                                   |
   体积渲染器                             可微分三角形光栅化器
        |                                   |
   模糊图像 + 无表面                    锐利图像 + 显式表面
        |                                   |
   无法用于游戏引擎                    + 测试时细化 -> 网格
一句话:从体积点云到显式三角形网格,核心转变是通过射线中心旋转和乘积窗口解决三角形渲染中的梯度流问题,实现了前馈表面解码。
专家评审
选题眼光:真实缺口。 3D高斯缺少表面在面向下游任务时是已知局限。 本文直击了无需优化的前馈表面基元解码瓶颈。 处于生成式3D与计算机图形学的交叉点上,时机很好。
方法成熟度:巧劲而非蛮力。 射线中心旋转非常优雅——利用已知相机几何简化学习。 乘积窗口是对可微分渲染的新贡献。 是否可以用简单的网格解码器代替三角形splat?可能可以,但三角形splat训练时允许逐像素软混合,对预测不准确的三角形很关键。 动机充分。
实验诚意:扎实。 在相同训练条件下对3DGS、2DGS和三角形splat的消融研究,正是社区需要的公平表示对比。 几何指标(倒角距离、法线一致性)FLAT明显领先。 视觉质量(FID)相当。 一个警觉点:测试时细化步骤用的是现成方法(看起来是启发式的),其对几何精度的贡献未充分消融。 但前馈结果本身立得住。
写作功力:整体清晰,但方法部分密集。 乘积窗口的梯度行为推导可以用图示展开(论文中缺失)。 相关工作部分过于敷衍——可以花一段解释为何先前基于三角形的可微分渲染器失败。 重写那一段能让论文提升一个档次。
判决:弱接收 —— 扎实的增量贡献,带有系统的比较分析;射线中心旋转技巧很可能被后续工作借用。
要点总结
- 射线中心旋转参数化:这个参数化可以应用于任何有相机信息的基元三维重建(如神经辐射场、点云精化)。 这是一种简单的方式来打破对称性、稳定方向学习。
- 乘积窗口函数:用两个sigmoid乘积作为可渲染基元窗口的想法可以迁移到非高斯splatting(如线splat、矩形splat)。 它比高斯窗口提供更锐利的梯度。
- 系统比较方法论:本文在相同训练条件下比较3DGS、2DGS和三角形splat的方式,为未来评估前馈3D生成中表示权衡的工作树立了模板。 实践者可以选择或提出新基元时采纳这一方法论。