Paper: 2607.18171 Authors: Krish Agarwal, Zhuoming Chen, Yanyuan Qin, Zhenyu Gu, Atri Rudra, Beidi Chen Categories: cs.LG
The Gap
Real-time multimodal applications—voice agents, interactive video generation, multimodal LLMs—compose heterogeneous models into pipelines. Deploying these pipelines efficiently requires making application-specific decisions: where to place each model component, how to stream data, and how to parallelize work within and across models.
Existing serving systems like vLLM and TensorRT-LLM are optimized for single-model serving, not multi-model pipeline orchestration. Auto-parallelism compilers like Alpa and FlexFlow commit to limited transformation strategies and assume fixed workload patterns. The result: achieving high performance on a new multimodal application still requires a human expert to hand-craft an efficient implementation—a process that is slow, brittle, and doesn’t transfer across hardware platforms.
FlashRT fills this gap by introducing an agent harness that automates the journey from “it works” to “it works fast.”
Problem: Deploying multimodal pipelines requires
         application-specific optimization decisions
    |
    v
Existing systems: Fixed transformations, single-model focus,
                  static workload assumptions
    |
    v
Manual optimization: Slow, brittle, hardware-specific,
                     requires deep expertise per application
    |
    v
FlashRT approach: Agent-driven iterative optimization
                  with measurement-gated verification
    |
    v
Result: Automatic transformation from reference code to
        optimized deployment (70x latency reduction)
The Increment
One sentence: Before this paper, optimizing a new multimodal pipeline required a human expert spending days or weeks on hand-crafted implementations; after this paper, a coding agent can automatically discover and apply optimizations, often outperforming expert-written code.
Core Mechanism
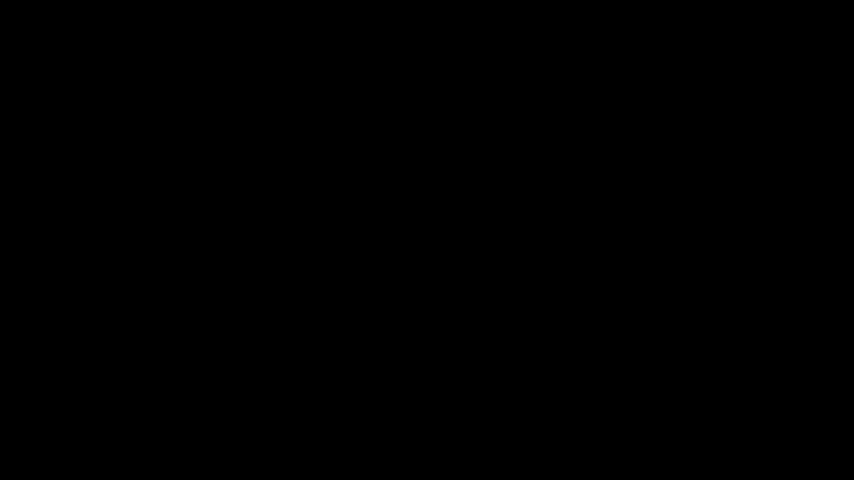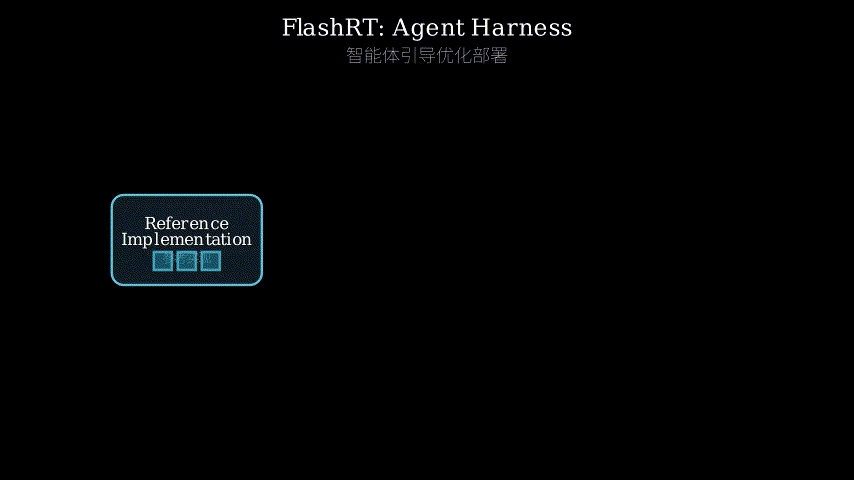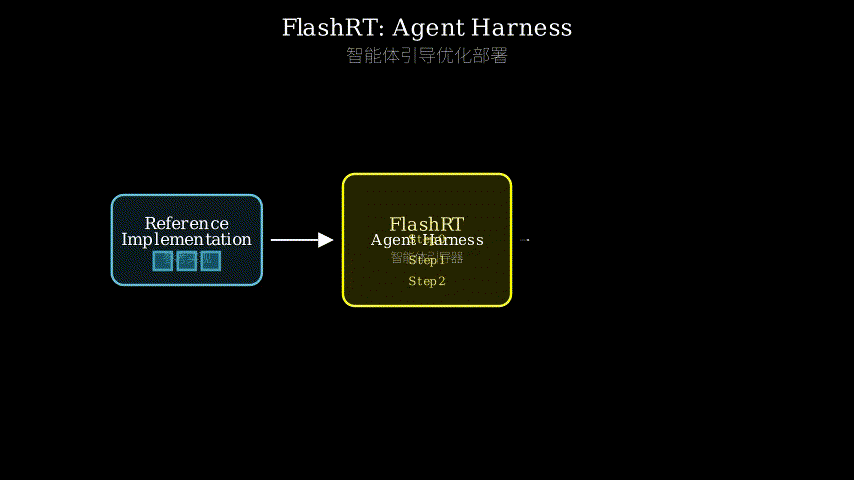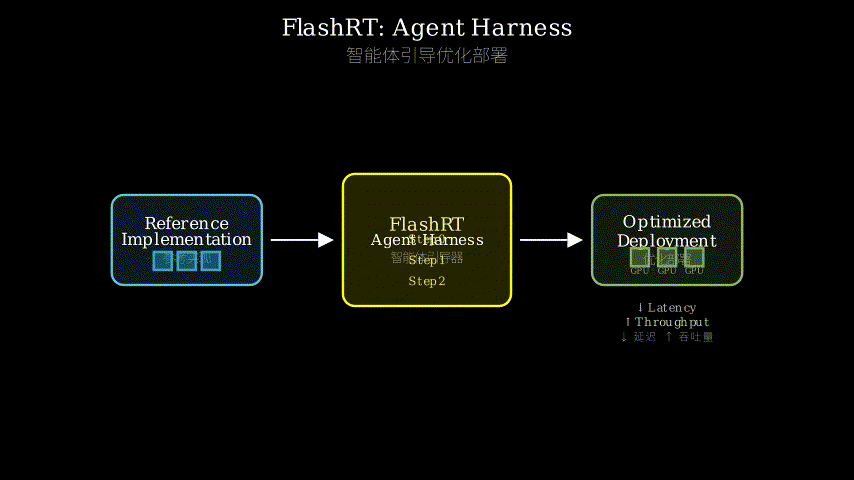
FlashRT operates as a “chain-of-program” harness that directs a generic coding agent (like Claude or GPT-4) through a structured multi-pass optimization process. The system doesn’t try to be intelligent itself—it provides the scaffolding that makes an AI coding agent effective at deployment optimization.
The process begins when a developer provides a simple reference implementation. FlashRT first asks the agent to transform this code into an intermediate representation (IR) that explicitly captures data dependencies between pipeline stages and scopes persistent state (like KV caches or model weights). This IR is validated through a sequential interpreter to ensure semantic correctness. Then, static analysis identifies candidate transformations—opportunities for parallelism, batching, streaming, or hardware-specific optimizations.
The key innovation is the measurement-gated optimization loop: for each candidate transformation, the agent iteratively implements it, verifies correctness, and benchmarks the result. If a transformation improves the target metric (latency, throughput, or a weighted combination), it’s kept; otherwise, it’s rolled back. This loop continues until no further improvements are found or a hardware budget is exhausted.
Reference Implementation (developer-written)
    |
    v
+-----------------------------+
| Agent: Lift to IR           |
| (capture dependencies,      |
|  persistent-state scopes)   |
+-----------------------------+
    |
    v
+-----------------------------+
| Sequential Interpreter      |
| (validate semantic          |
|  correctness of IR)         |
+-----------------------------+
    |
    v
+-----------------------------+
| Static Analysis             |
| (identify candidate         |
|  transformations)           |
+-----------------------------+
    |
    v
+-------------------------------------------+
| Measurement-Gated Optimization Loop       |
|                                           |
|  for each candidate:                      |
|    + implement transformation             |
|    + verify correctness                   |
|    + benchmark on target hardware         |
|    + keep if metric improves, else revert |
+-------------------------------------------+
    |
    v
Optimized Deployment (across N GPUs)
Structural metaphor: Think of FlashRT as a master chef training system. You hand it a recipe written by a home cook—something that produces the right dish but slowly and messily. The system doesn’t just memorize the recipe. First, it has the trainee (the agent) break the recipe into an annotated flowchart: which steps depend on which, which ingredients must stay warm (persistent state), which tasks can happen simultaneously. A supervisor (the interpreter) watches the trainee follow the flowchart step-by-step to verify it still produces the correct dish. Then a food scientist (static analysis) marks opportunities: “these two chopping tasks could happen on two cutting boards at once,” “this sauce could be made in a bigger batch.” Finally, the trainee experiments with each change in an actual kitchen (real hardware), timing each attempt. If a change speeds things up without ruining the dish, it sticks. If not, it’s reverted. After dozens of experiments, the home cook’s recipe has been transformed into a restaurant kitchen workflow optimized for that specific kitchen’s equipment—without ever needing a Michelin-starred chef to rewrite it from scratch.
Key Concepts
-
Chain-of-program paradigm: Instead of asking an AI agent to optimize code in one shot (which fails for complex deployment decisions), FlashRT breaks the optimization into discrete, verifiable steps. Each step is a “program” the agent executes: lift to IR, validate, analyze, transform, benchmark. The key insight is that complex optimization is decomposable into agent-executable steps with clear success criteria. Think of it like giving someone directions by landmarks rather than compass bearings—each step has a visible checkpoint.
-
Measurement-gated optimization: Every proposed transformation must pass through a gate: actual benchmarking on real hardware. This prevents the agent from pursuing theoretically sound but practically harmful optimizations. It’s the difference between a chess player who calculates moves in their head versus one who plays out variations on a physical board. The board doesn’t lie. If the measured latency goes up, the transformation is rejected regardless of how elegant the reasoning was.
-
Persistent-state scoping: In multimodal pipelines, some state persists across requests (model weights, KV caches) while other state is transient (per-request activations). The IR explicitly tags which state is persistent, enabling the agent to make informed decisions about memory placement and data movement. Without this, the agent might optimize for computation while accidentally creating a memory bottleneck. It’s like knowing which tools stay on the workbench versus which ingredients get used up—informed by that knowledge, you can plan your workspace layout much more efficiently.
Framework Shift
Before (mainstream approach):        After (this paper):

Hand-written optimized code          Simple reference code
     |                                    |
     v                                    v
Expert spends days/weeks             Agent harness guides
tuning per application               automated transformation
     |                                    |
     v                                    v
Hardcoded to one hardware            Measurement-gated loop
configuration                        discovers optimal config
     |                                    |
     v                                    v
Brittle, doesn't transfer            Port across hardware
                                     (NVIDIA, AMD) with
                                     re-optimization
From human-expert-driven optimization to agent-driven measurement-gated optimization, the core shift is that deployment optimization becomes a search process with verifiable checkpoints rather than an artisanal craft requiring deep systems expertise.
Expert Assessment
Problem choice: This is a genuine and important gap. The explosion of multimodal applications has outpaced our ability to optimize their deployments. Every new voice agent or video generation pipeline requires weeks of expert tuning. The problem is real and growing—good problem selection.
Method maturity: The “chain-of-program” approach is clever rather than brute-force. Using an agent harness to structure the optimization process—rather than building a custom compiler—is pragmatic and composable. However, the reliance on the quality of the underlying coding agent is a potential fragility. As agents improve, FlashRT gets better automatically, but this also means the paper’s results are partly a function of Claude/GPT-4’s capabilities, not just the harness design. There may be simpler heuristic-based approaches for common transformations that are being overlooked in favor of agent generality.
Experimental integrity: The baselines are fair—comparing against expert-optimized implementations (vLLM-Omni) on both NVIDIA and AMD hardware. The 70x latency reduction is striking and appears to come from pipeline-level optimizations (streaming, placement) that single-model serving systems miss. The cross-hardware results (B200 vs MI355X) add credibility. One concern: the paper focuses on specific application types (video world models, multimodal LLMs). It’s unclear how well this generalizes to truly novel pipeline architectures. The agent’s effectiveness likely correlates with how many similar optimizations it’s seen in training data.
Writing quality: The paper is well-structured and the “chain-of-program” framing is clear. However, the failure mode analysis is thin—when does the agent get stuck? What kinds of transformations does it miss? The ablation on agent quality (what happens with weaker agents?) would strengthen the argument significantly. Section on the IR could benefit from a more formal specification rather than examples alone.
Verdict: weak accept — The problem is real, the approach is novel and practical, and the results are strong. But the heavy reliance on opaque agent capabilities and limited failure analysis prevent a strong accept. This is a paper that will be influential if the agent-driven optimization paradigm catches on, but the contribution is as much a framing insight as a technical one.
Takeaways
-
Structure your optimization as a verifiable pipeline for AI agents: The “chain-of-program” pattern—decompose complex optimization into discrete steps with clear success criteria—is directly transferable to any domain where you want an agent to optimize something. Don’t ask agents to “make it fast”; ask them to “transform X, verify, benchmark, keep or revert.”
-
Measurement-gated optimization beats theoretical reasoning: When using agents for systems optimization, always gate proposed changes on actual measurements. This prevents agents from pursuing elegant but harmful transformations. The pattern is: implement, measure, decide. Apply this to any automated code improvement workflow.
-
Intermediate representations as agent scaffolding: Having an agent first lift code into a structured IR (with explicit dependencies and state scoping) dramatically improves downstream optimization quality. If you’re building agent-driven code transformation tools, invest in the IR design—it’s the foundation that makes everything else work.
-
Agent harnesses may outpace custom compilers: Rather than building increasingly complex optimizing compilers, consider building structured scaffolding that guides general-purpose agents. As agents improve, your system improves automatically. This is a paradigm shift worth watching.
论文: 2607.18171 作者: Krish Agarwal, Zhuoming Chen, Yanyuan Qin, Zhenyu Gu, Atri Rudra, Beidi Chen 分类: cs.LG
缺口
实时多模态应用——语音助手、交互式视频生成、多模态大模型——由多个异构模型组合成流水线。 高效部署这些流水线需要做出应用特定的决策:每个模型组件放在哪、如何流式传输数据、 以及如何在模型内部和模型之间进行并行化。
现有的推理服务系统(如 vLLM、TensorRT-LLM)针对单模型推理优化,不擅长多模型流水线编排。 自动并行编译器(如 Alpa、FlexFlow)只能做有限的变换,且假设工作负载模式固定。 结果是:要在新的多模态应用上获得高性能,仍然需要人类专家手工编写高效实现—— 这个过程缓慢、脆弱,且无法跨硬件平台迁移。
FlashRT 填补了这个缺口,引入了一个智能体框架,自动化从”能跑”到”跑得快”的全过程。
问题:部署多模态流水线需要应用特定的优化决策
    |
    v
现有系统:固定变换策略、单模型聚焦、静态工作负载假设
    |
    v
手工优化:缓慢、脆弱、硬件特定、每个应用都需要深度专业知识
    |
    v
FlashRT 方案:智能体驱动的迭代优化 + 实测门控验证
    |
    v
结果:自动将参考代码转化为优化部署(延迟降低 70 倍)
增量
一句话: 这篇论文之前,优化新的多模态流水线需要人类专家花数天甚至数周进行手工调优; 这篇论文之后,编程智能体可以自动发现并应用优化策略,其效果常常超越专家手写代码。
核心机制
FlashRT 作为一个”程序链”框架运作,引导通用编程智能体(如 Claude 或 GPT-4) 通过结构化的多轮优化过程。系统本身不试图变得”聪明”——它提供脚手架, 让 AI 编程智能体在部署优化任务上变得有效。
当开发者提供一个简单的参考实现后,FlashRT 首先要求智能体将其转换为中间表示(IR), 显式捕获流水线各阶段之间的数据依赖关系,并标记持久状态的作用域 (如 KV 缓存或模型权重)。这个 IR 通过顺序解释器验证语义正确性。 然后,静态分析识别候选变换——并行化、批处理、流式传输或硬件特定优化的机会。
关键创新在于”实测门控优化循环”:对每个候选变换,智能体迭代地实现它、验证正确性、 并在实际硬件上跑基准测试。如果变换改善了目标指标(延迟、吞吐量或加权组合), 就保留;否则就回滚。这个循环持续到没有进一步改善或硬件预算耗尽。
参考实现(开发者编写)
    |
    v
+-------------------------------+
| 智能体:提升为 IR             |
| (捕获依赖关系、              |
|  持久状态作用域)             |
+-------------------------------+
    |
    v
+-------------------------------+
| 顺序解释器                    |
| (验证 IR 的语义正确性)      |
+-------------------------------+
    |
    v
+-------------------------------+
| 静态分析                      |
| (识别候选变换)              |
+-------------------------------+
    |
    v
+--------------------------------------------+
| 实测门控优化循环                             |
|                                            |
|  对每个候选变换:                            |
|    + 实现变换                               |
|    + 验证正确性                             |
|    + 在目标硬件上跑基准测试                  |
|    + 指标改善则保留,否则回滚                |
+--------------------------------------------+
    |
    v
优化后的部署方案(跨 N 块 GPU)
核喻:把 FlashRT 想象成一个大厨培训系统。你交给它一份家庭厨师写的菜谱—— 做出来的菜是对的,但又慢又乱。系统不会直接背下菜谱,而是让学员(智能体) 先把菜谱拆解成标注流程图:哪些步骤依赖哪些步骤、哪些食材必须保持温热(持久状态)、 哪些任务可以同时进行。一个督导员(解释器)在旁边看着学员逐步执行流程图, 确认菜还是做对了。然后一位食品科学家(静态分析)标记机会: “这两道切菜工序可以在两块砧板上同时进行”,“这个酱汁可以一次做一大份”。 最后,学员在真正的厨房里(实际硬件)对每项改动进行实验并计时。 如果某项改动加快了速度且没毁掉菜,就保留;否则就撤回。 经过几十轮实验后,家庭厨师的菜谱已经被转化成了针对那间厨房设备优化的餐厅后厨工作流—— 自始至终都不需要米其林大厨从头重写。
关键概念
-
程序链范式(Chain-of-program):不是要求 AI 智能体一步到位优化代码 (这在复杂部署决策上会失败),而是把优化拆解为离散的、可验证的步骤。 每一步都是智能体执行的一个”程序”:提升为 IR、验证、分析、变换、基准测试。 核心洞见是:复杂优化可以被分解为带明确成功标准的、可由智能体执行的步骤。 这就像用地标而非罗盘方位给人指路——每一步都有一个可见的检查点。
-
实测门控优化(Measurement-gated optimization):每个提议的变换都必须通过一道关卡: 在真实硬件上进行实际基准测试。这防止了智能体追求理论上合理但实际有害的优化。 这就像一个在脑子里算棋的棋手和一个在实体棋盘上摆棋的棋手之间的区别。 棋盘不会骗人。如果测出来的延迟增加了,变换就会被拒绝,不管推理过程多么精妙。
-
持久状态作用域(Persistent-state scoping):在多模态流水线中, 有些状态跨请求持久存在(模型权重、KV 缓存),而有些状态是临时的(单次请求的激活值)。 IR 显式标记哪些状态是持久的,使智能体能做出关于内存放置和数据移动的知情决策。 没有这个信息,智能体可能在优化计算的同时意外造成内存瓶颈。 这就像知道哪些工具放在工作台上、哪些食材会被用完—— 有了这个知识,你就能更高效地规划工作空间布局。
框架转变
之前(主流方法):                 之后(本文方法):

手写优化代码                      简单的参考代码
     |                                 |
     v                                 v
专家花数天/数周                   智能体框架引导
针对每个应用调优                  自动化变换过程
     |                                 |
     v                                 v
硬编码到单一硬件                  实测门控循环
配置                              发现最优配置
     |                                 |
     v                                 v
脆弱、无法迁移                    可跨硬件(NVIDIA、AMD)
                                  重新优化
从人类专家驱动的优化到智能体驱动的实测门控优化,核心转变是: 部署优化从一种需要深度系统专业知识的手艺,变成了一种带有可验证检查点的搜索过程。
专家评审
选题眼光:这是一个真实且重要的缺口。多模态应用的爆发已经超出了我们优化其部署的能力。 每个新的语音助手或视频生成流水线都需要数周的专家调优。问题真实且在增长——选题不错。
方法成熟度:“程序链”方法是巧妙的而非蛮力的。使用智能体框架来结构化优化过程—— 而非构建自定义编译器——是务实且可组合的。 然而,对底层编程智能体能力的依赖是一个潜在的脆弱点。 随着智能体进步,FlashRT 自动变得更好,但这也意味着论文的结果部分取决于 Claude/GPT-4 的能力,而不仅仅是框架设计。 对于常见变换,可能存在被忽略的更简单的启发式方法。
实验诚意:基线是公平的——与专家优化的实现(vLLM-Omni)在 NVIDIA 和 AMD 硬件上对比。 70 倍延迟降低令人瞩目,且来自流水线级优化(流式传输、放置), 而单模型推理服务系统会错过这些。跨硬件结果(B200 vs MI355X)增加了可信度。 一个担忧:论文聚焦于特定应用类型(视频世界模型、多模态大模型)。 尚不清楚这在真正新颖的流水线架构上推广得如何。 智能体的有效性可能与其训练数据中见过多少类似优化相关。
写作功力:论文结构清晰,“程序链”框架阐述到位。 然而,失败模式分析较薄——智能体什么时候会卡住?它会错过哪类变换? 关于智能体质量的消融实验(用更弱的智能体会怎样?)会显著增强论证。 IR 那一节可以从更多例子改为更正式的规范说明。
判决:弱接收 —— 问题真实,方法新颖且实用,结果强劲。 但对不透明的智能体能力的重度依赖以及有限的失败分析阻止了强接收。 如果智能体驱动的优化范式流行起来,这篇论文将具有影响力, 但贡献更多是框架性洞见而非纯技术突破。
要点总结
-
将优化结构化为 AI 智能体的可验证流水线:“程序链”模式——将复杂优化分解为 带明确成功标准的离散步骤——可直接迁移到任何你想让智能体优化的领域。 不要让智能体”让它变快”;让它”变换 X、验证、基准测试、保留或回滚”。
-
实测门控优化胜过理论推理:用智能体做系统优化时,一定要用实际测量来门控提议的变更。 这防止智能体追求精巧但有害的变换。模式是:实现、测量、决策。 将此应用到任何自动代码改进工作流中。
-
中间表示作为智能体脚手架:让智能体先将代码提升到结构化 IR (带显式依赖和状态作用域)能显著改善下游优化质量。 如果你在构建智能体驱动的代码转换工具,请投资 IR 设计—— 它是使其他一切工作的基础。
-
智能体框架可能超越自定义编译器:与其构建越来越复杂的优化编译器, 不如考虑构建结构化脚手架来引导通用智能体。随着智能体进步,你的系统自动进步。 这是一个值得关注的范式转变。