Paper: 2605.22779 Authors: Huanchi Wang, Zihang Huang, Yifang Tian, Kristina Dzeparoska, Hans-Arno Jacobsen, Alberto Leon-Garcia Categories: cs.SE, cs.LG
The Gap
Existing log anomaly detectors work at session or window level—they flag a batch of 50-200 log lines and tell you “something’s wrong in here.” Operators then manually grep through routine messages to find the actual culprit. Message-level detection would pinpoint the exact line, but three obstacles block the path: (1) the same template (“disk read failed”) appears in both normal retries and catastrophic failures, (2) failures come from heterogeneous subsystems (network, storage, compute) requiring different reasoning, and (3) labeling millions of individual lines is prohibitively expensive. Recent LLM-based detectors can reason over log semantics but cost too much to run on every line in production.
Problem: Session-level detection buries signal in noise
   |
   v
Assumption: Message-level needs semantic reasoning + subsystem awareness
   |
   v
Method: Use LLM once offline to partition templates into failure domains,
        then train lightweight domain experts for online inference
   |
   v
Evidence: BGL F1=98.16 with K=100 labels (76x reduction), 86.3% unseen detection
   |
   v
Conclusion: Offline LLM guidance + online lightweight experts = practical message-level detection
The Increment
One sentence: Before FAME, you either paid LLM costs per line or settled for coarse session-level alerts; after FAME, you get message-level precision with lightweight models by using the LLM once to design the expert architecture.
Core Mechanism
FAME operates in two phases. Offline, you sample at most K lines per event template (e.g., “Node <*> failed”), feed them to an LLM with failure context, and get back binary labels (normal/anomaly) plus representative examples. The LLM then proposes a partition of all templates into failure domains—clusters like “network errors,” “disk failures,” “memory issues.” A certification step validates this partition: if templates in the same domain have inconsistent labels or semantics, the partition is rejected and the LLM tries again.
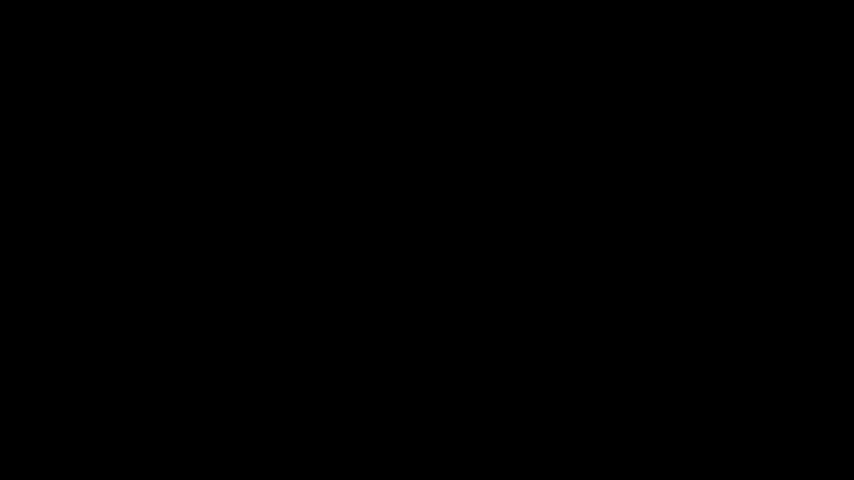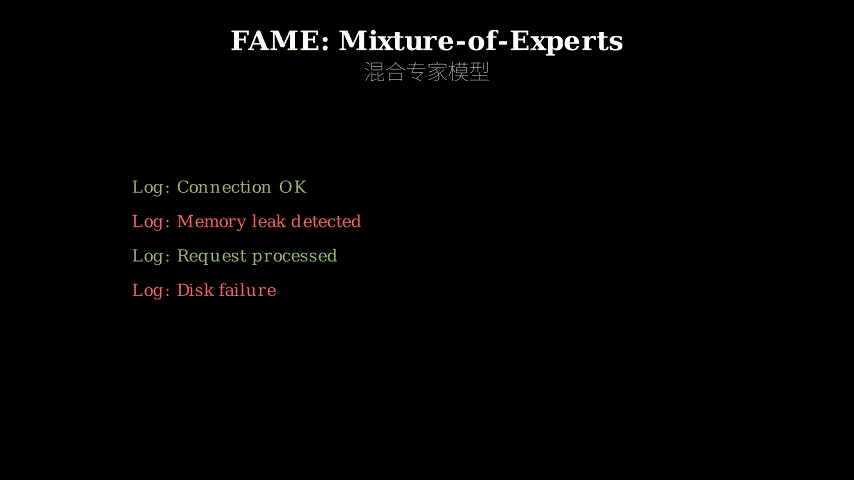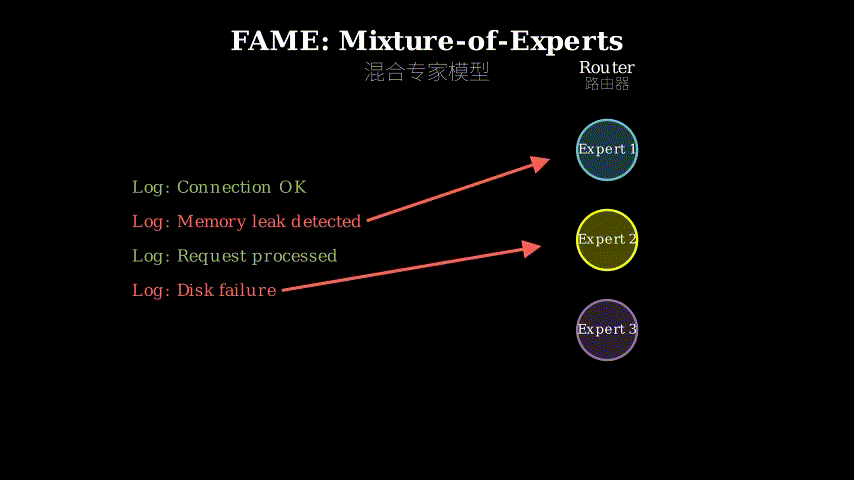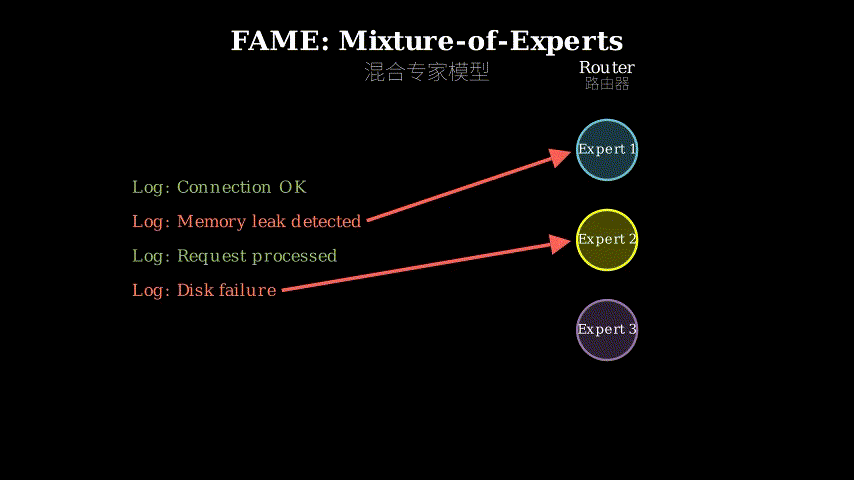
Once certified, FAME trains a router and domain-specific expert models. The router is a lightweight classifier that reads a log line’s embedding and predicts which failure domain it belongs to. Each expert is a small neural network specialized for one domain. At inference time, a new log line hits the router, gets routed to the appropriate expert, and receives both an anomaly score and a failure-domain label. The entire pipeline runs on-premise with no LLM calls.
Offline Phase:
  Templates --> Sample K lines --> LLM annotates --> Binary labels + examples
       |                                                      |
       +------------------------------------------------------+
       |
       v
  LLM proposes domain partition --> Certification (validate consistency)
       |
       v
  Train router + domain experts

Online Phase:
  Log line --> Embedding --> Router --> Expert_domain --> [Anomaly score, Domain label]
Think of FAME as a hospital triage system designed by a veteran doctor. The doctor (LLM) examines a few cases from each symptom type, writes diagnostic guidelines, and organizes symptoms into departments (cardiology, neurology, orthopedics). Then junior doctors (lightweight experts) staff each department. When a patient arrives, a nurse (router) reads their chart and sends them to the right department. The veteran doctor never sees patients again—their expertise is baked into the department structure and guidelines. If the department assignments don’t make clinical sense (e.g., chest pain and broken bones in the same unit), the veteran redesigns the layout before opening the hospital.
Key Concepts
-
Event Template: A log line like “Disk read error on /dev/sda1 at 14:32
” gets parsed into a template “Disk read error on<**>at<*>” where<*>marks variable fields. The template captures the message type; the variables hold instance-specific data. The same template can appear in both normal operations (transient retry) and failures (disk dying). This ambiguity is why session-level detectors struggle—they can’t distinguish context from structure alone. -
Failure Domain: A semantic cluster of templates that share root causes or subsystem origins. For example, templates like “Network timeout,” “Connection refused,” and “Packet loss detected” belong to a “network” domain, while “Out of memory,” “Malloc failed,” and “Swap exhausted” form a “memory” domain. The key insight: anomalies within a domain follow similar patterns, so a specialized expert can learn them efficiently. Cross-domain experts would dilute signal with irrelevant features.
-
Certification Step: After the LLM proposes a domain partition, FAME checks whether templates in each domain have consistent labels and semantics. If domain D contains both mostly-normal and mostly-anomalous templates, or if templates have unrelated failure modes, certification fails. The LLM must revise the partition. This prevents the router from learning meaningless groupings and ensures each expert has a coherent learning task. It’s a sanity check before committing compute to training.
Framework Shift
Before (session-level detection):        After (FAME):

  [Log lines] --> Window aggregation     [Log line] --> Router --> Expert_net
      |              |                        |              |
      v              v                        v              v
  Feature vector --> Detector            Embedding      Anomaly score
      |                                       +
      v                                   Domain label
  Session-level alert
  (inspect 50-200 lines manually)        Message-level alert
                                         (exact line identified)
From batch-level flags to message-level precision, the core shift is using an LLM once to architect the detector rather than running it continuously.
Expert Assessment
Problem choice: Real gap. Session-level detection genuinely frustrates operators—I’ve watched SREs grep through hundreds of lines per alert. Message-level detection is a natural next step, and the label-efficiency angle addresses the practical blocker (annotation cost). The problem sits at the intersection of systems reliability and ML efficiency, which is timely given LLM deployment costs.
Method maturity: Clever use of LLM as a one-time architect rather than a runtime component. The certification step is the key innovation—without it, the LLM’s partition could be arbitrary. The mixture-of-experts framing is standard, but the offline LLM guidance + online lightweight inference is a smart tradeoff. One concern: the method assumes failure domains are discoverable from templates alone. In practice, some anomalies emerge from interaction patterns across subsystems, which template clustering might miss.
Experimental integrity: Baselines are fair (DeepLog, LogRobust, PLELog). The K=100 annotation budget is realistic. BGL and Thunderbird are standard benchmarks, though both are from HPC systems—generalization to cloud microservices or edge devices is unproven. The 86.3% unseen EventID detection is impressive but raises a question: what characterizes the 13.7% that fail? The paper doesn’t analyze failure modes. The Thunderbird result (F1=99.95, perfect recall) seems almost too good—worth checking if the dataset has label leakage or is unusually clean.
Writing quality: The abstract and intro are crisp. Section 3 (method) buries the certification step in a subsection—it should be elevated since it’s the core contribution. The related work section is thorough but reads like a literature dump; cutting it by 30% would improve flow. Figure 2 (architecture diagram) is clear, but Figure 4 (certification example) is hard to parse without reading the caption three times.
Verdict: weak accept — Solves a real problem with a practical method, but experimental scope is narrow (HPC logs only) and the certification step needs deeper analysis of when it succeeds vs. fails.
Takeaways
Steal the offline-online split: Use an expensive model once to design the architecture (partition the problem, generate training data, propose structure), then train cheap models for deployment. This pattern applies beyond logs—think network traffic classification, sensor anomaly detection, or document routing.
Certification as a design primitive: Before training a multi-model system, validate that the problem decomposition makes sense. If your router sends semantically unrelated inputs to the same expert, you’re training on noise. Add a programmatic check that rejects bad partitions early.
K-shot annotation per template: Instead of labeling uniformly across the dataset, sample K examples per category (template, user segment, event type). This gives you coverage of the decision boundary without drowning in redundant labels. Works when within-category variance is low.
论文: 2605.22779 作者: Huanchi Wang, Zihang Huang, Yifang Tian, Kristina Dzeparoska, Hans-Arno Jacobsen, Alberto Leon-Garcia 分类: cs.SE, cs.LG
缺口
现有日志异常检测器工作在会话或窗口级别——它们标记一批50-200条日志行,告诉你”这里面有问题”。
运维人员随后手动grep常规消息来找真正的罪魁祸首。
消息级检测能精准定位到具体行,但三个障碍挡住了路:(1) 同一个模板(“磁盘读取失败”)既出现在正常重试中也出现在灾难性故障中,(2) 故障来自异构子系统(网络、存储、计算)需要不同的推理,(3) 标注数百万条单独的行成本高得离谱。
最近的基于LLM的检测器能对日志语义推理,但在生产环境对每一行运行成本太高。
问题:会话级检测把信号埋在噪声里
   |
   v
假设:消息级需要语义推理 + 子系统感知
   |
   v
方法:离线使用LLM一次将模板划分为故障域,
      然后训练轻量域专家用于在线推理
   |
   v
证据:BGL上F1=98.16,K=100标签(减少76倍),未见检测率86.3%
   |
   v
结论:离线LLM指导 + 在线轻量专家 = 实用的消息级检测
增量
一句话: FAME之前,你要么为每行付LLM成本,要么接受粗粒度的会话级警报;FAME之后,你通过使用LLM一次来设计专家架构,用轻量模型获得消息级精度。
核心机制
FAME分两个阶段运行。
离线阶段,你对每个事件模板(如”节点 <*> 失败”)最多采样K行,连同故障上下文喂给LLM,得到二元标签(正常/异常)加代表性样例。
然后LLM提出一个将所有模板划分为故障域的方案——像”网络错误”、“磁盘故障”、“内存问题”这样的簇。
认证步骤验证这个划分:如果同一域中的模板有不一致的标签或语义,划分被拒绝,LLM重试。
一旦认证通过,FAME训练一个路由器和特定域的专家模型。
路由器是一个轻量分类器,读取日志行的嵌入并预测它属于哪个故障域。
每个专家是一个专门针对一个域的小型神经网络。
推理时,新日志行打到路由器,被路由到合适的专家,收到异常分数和故障域标签。
整个流水线在本地运行,无需LLM调用。
离线阶段:
  模板 --> 采样K行 --> LLM标注 --> 二元标签 + 样例
       |                                    |
       +------------------------------------+
       |
       v
  LLM提出域划分 --> 认证(验证一致性)
       |
       v
  训练路由器 + 域专家

在线阶段:
  日志行 --> 嵌入 --> 路由器 --> 专家_域 --> [异常分数, 域标签]
把FAME想象成由资深医生设计的医院分诊系统。
医生(LLM)检查每种症状类型的几个病例,写诊断指南,把症状组织成科室(心脏科、神经科、骨科)。
然后初级医生(轻量专家)配置到各科室。
病人到达时,护士(路由器)读病历把他们送到对的科室。
资深医生再也不见病人——他们的专业知识烘焙进了科室结构和指南。
如果科室分配在临床上说不通(比如胸痛和骨折在同一个单元),资深医生在开业前重新设计布局。
关键概念
- 事件模板: 像”Disk read error on /dev/sda1 at 14:32:05”这样的日志行被解析成模板”Disk read error on
<**>at<*>”,其中<*>标记可变字段。
模板捕获消息类型;变量持有实例特定数据。
同一模板既能出现在正常操作中(瞬态重试)也能出现在故障中(磁盘挂掉)。
这种歧义是会话级检测器挣扎的原因——它们无法仅从结构区分上下文。
- 故障域: 共享根因或子系统来源的模板的语义簇。
例如,“Network timeout”、“Connection refused”、“Packet loss detected”这些模板属于”网络”域,而”Out of memory”、“Malloc failed”、“Swap exhausted”形成”内存”域。
关键洞察:域内的异常遵循相似模式,所以专门的专家能高效学习它们。
跨域专家会用无关特征稀释信号。
- 认证步骤: LLM提出域划分后,FAME检查每个域中的模板是否有一致的标签和语义。
如果域D同时包含大部分正常和大部分异常的模板,或者模板有不相关的故障模式,认证失败。
LLM必须修订划分。
这防止路由器学习无意义的分组,确保每个专家有连贯的学习任务。
这是在投入计算训练前的合理性检查。
框架转变
之前(会话级检测):                之后(FAME):

  [日志行] --> 窗口聚合                [日志行] --> 路由器 --> 专家_网络
      |           |                        |              |
      v           v                        v              v
  特征向量 --> 检测器                   嵌入          异常分数
      |                                       +
      v                                   域标签
  会话级警报
  (手动检查50-200行)                    消息级警报
                                        (精确行已识别)
从批级标记到消息级精度,核心转变是使用LLM一次来架构检测器而非持续运行它。
专家评审
选题眼光: 真缺口。
会话级检测确实让运维人员沮丧——我见过SRE每个警报grep数百行。
消息级检测是自然的下一步,标注效率角度解决了实际阻碍(标注成本)。
问题位于系统可靠性和ML效率的交叉点,考虑到LLM部署成本,这很及时。
方法成熟度: 巧妙地将LLM用作一次性架构师而非运行时组件。
认证步骤是关键创新——没有它,LLM的划分可能是任意的。
混合专家框架是标准的,但离线LLM指导 + 在线轻量推理是聪明的权衡。
一个担忧:方法假设故障域可以仅从模板发现。
实际上,一些异常从跨子系统的交互模式中浮现,模板聚类可能会错过。
实验诚意: 基线公平(DeepLog、LogRobust、PLELog)。
K=100标注预算现实。
BGL和Thunderbird是标准基准,尽管两者都来自HPC系统——泛化到云微服务或边缘设备未经证明。
86.3%的未见EventID检测令人印象深刻,但引发一个问题:失败的13.7%有什么特征?论文没分析失败模式。
Thunderbird结果(F1=99.95,完美召回)似乎好得过头——值得检查数据集是否有标签泄漏或异常干净。
写作功力: 摘要和引言简洁。
第3节(方法)把认证步骤埋在子节里——它应该被提升,因为它是核心贡献。
相关工作部分详尽但读起来像文献倾倒;削减30%会改善流畅度。
图2(架构图)清晰,但图4(认证示例)不读三遍标题难以解析。
判决: 弱接收 — 用实用方法解决真问题,但实验范围窄(仅HPC日志),认证步骤需要更深入分析何时成功vs失败。
要点总结
偷走离线-在线分离: 使用昂贵模型一次来设计架构(划分问题、生成训练数据、提出结构),然后训练便宜模型用于部署。
这个模式适用于日志之外——想想网络流量分类、传感器异常检测或文档路由。
认证作为设计原语: 训练多模型系统前,验证问题分解是否合理。
如果你的路由器把语义无关的输入送到同一个专家,你在噪声上训练。
添加程序化检查,早期拒绝坏划分。
每模板K-shot标注: 不在数据集上均匀标注,而是每个类别(模板、用户段、事件类型)采样K个样例。
这在不淹没于冗余标签的情况下给你决策边界的覆盖。
当类别内方差低时有效。