Paper: 2604.26881 Authors: Minghe Wang, Trever Schirmer, Mohammadreza Malekabbasi, David Bermbach Categories: cs.DC, cs.LG
The Gap
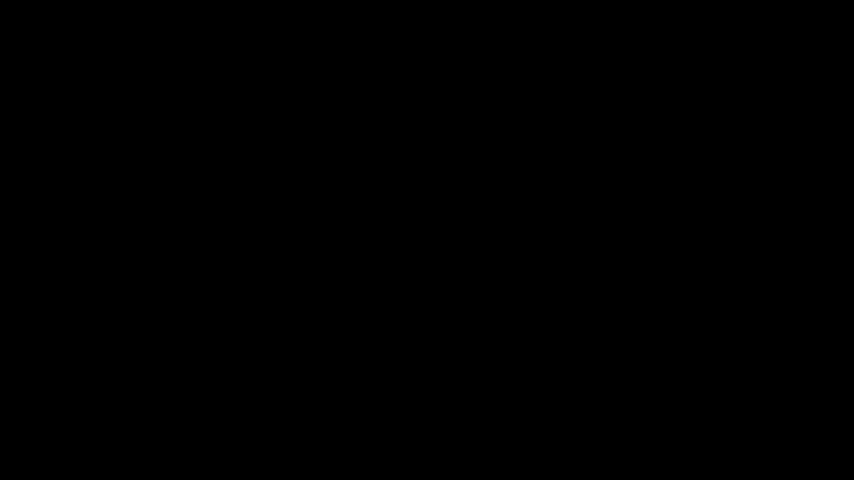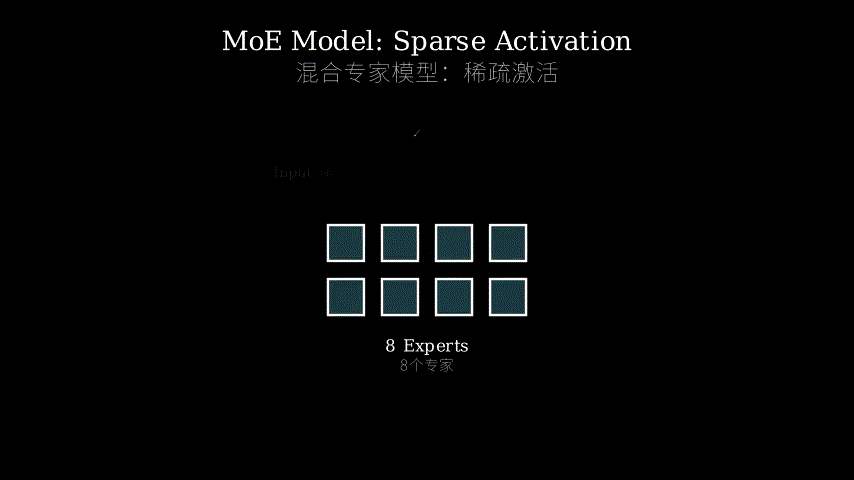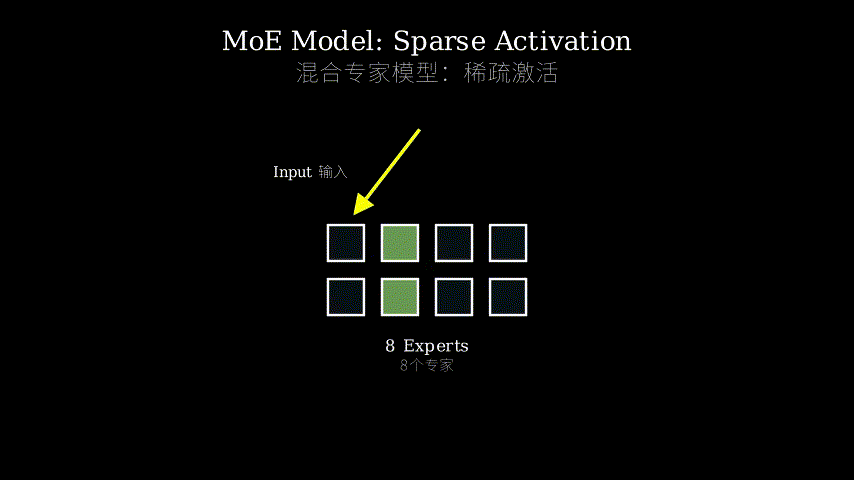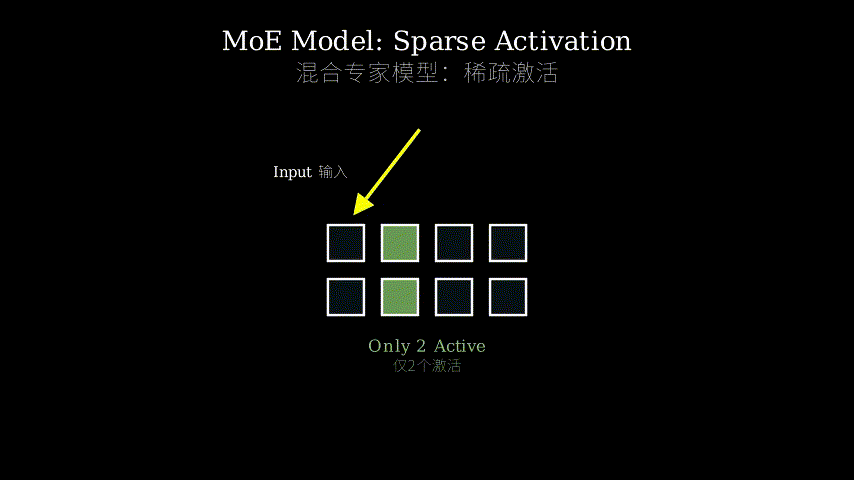
Mixture-of-Experts (MoE) models activate only a small subset of experts per input—say 2 out of 64—but traditional deployments keep all experts loaded in memory. This creates massive resource waste: you provision for 64 experts but use 2 at a time. In multi-tenant scenarios where different users trigger different experts, the waste compounds. Prior work (DeepSpeed-MoE, Tutel, MegaBlocks) optimizes expert parallelism and routing but assumes all experts stay resident. No one has seriously questioned the “all experts in memory” assumption for serving workloads.
Problem: MoE models waste memory
         (provision 64 experts, use 2)
            |
            v
Assumption: FaaS scale-to-zero can match
            MoE's sparse activation pattern
            |
            v
Method: Deploy each expert as stateless
        FaaS function + router as gateway
            |
            v
Evidence: 67% resource reduction on
          Qwen1.5-MoE-2.7B workload
            |
            v
Conclusion: Serverless MoE viable for
            multi-tenant edge deployment
The Increment
One sentence: Before this paper, MoE serving meant keeping all experts in memory; after, you can deploy experts as on-demand functions that scale to zero between requests.
Core Mechanism
FaaSMoE splits MoE into two planes. The control plane runs a lightweight router that receives input tokens, computes expert routing scores, and dispatches requests to the appropriate expert functions. The execution plane consists of expert models deployed as stateless FaaS functions—each function loads its expert weights on cold start, processes the routed tokens, and returns hidden states back to the router. The router aggregates expert outputs and passes them to the next layer.
The key design choice is expert granularity. You can deploy one expert per function (fine-grained) for maximum elasticity, or pack multiple experts into one function (coarse-grained) to amortize cold start overhead. FaaSMoE makes this configurable: a “granularity factor” k means each function hosts k experts. When k=1, you get per-expert scaling; when k equals total experts, you’re back to monolithic deployment.
Think of it like a restaurant kitchen during off-peak hours. Traditional MoE is keeping all stations staffed even when orders are sparse—the grill, the fryer, the salad station all have cooks standing by. FaaSMoE is calling in cooks only when orders arrive for their station. The expeditor (router) reads each ticket, calls the relevant cook (expert function), and assembles the dish (aggregates outputs). If you’re worried about call-in time, you can assign each cook multiple stations (higher granularity k) so fewer calls are needed, trading some idle time for faster response.
Key Concepts
-
Expert Activation Sparsity: In MoE models, each input token is routed to a small subset of experts—typically 1-2 out of 8-64 total experts. The router computes a score for each expert and picks the top-k. This means 95%+ of experts sit idle for any given token, yet traditional deployments keep them all loaded. FaaSMoE exploits this sparsity: if an expert isn’t being called, it doesn’t consume resources.
-
Cold Start Amortization: FaaS functions have cold start latency—the first invocation loads the model into memory. For small experts (~100MB), this takes 1-2 seconds. FaaSMoE mitigates this by (1) keeping frequently-used experts warm through request patterns, and (2) allowing multiple experts per function so one cold start loads several experts at once. The paper shows that with granularity k=4, cold starts drop to ~15% of requests under realistic workloads.
-
Multi-Tenant Resource Sharing: When multiple users share an MoE deployment, their requests trigger different expert subsets. User A’s queries might favor experts 1, 5, 12; User B’s favor 3, 8, 15. Traditional deployments provision for the union of all experts across all users. FaaSMoE provisions only for the active working set at any moment—if User A and B’s requests don’t overlap in time, their expert functions don’t overlap in memory.
Framework Shift
Before (monolithic MoE):              After (FaaSMoE):

[Input] --> [Router]                  [Input] --> [Router/Gateway]
              |                                      |
              v                                      v
    +-------------------+               +-------------------------+
    | All 64 Experts    |               | FaaS Platform           |
    | Loaded in Memory  |               |   Expert-1 (cold)       |
    |                   |               |   Expert-5 (warm) <--+  |
    | Expert-1  Expert-2|               |   Expert-12 (cold)    |  |
    | Expert-3  Expert-4|               |   ...                 |  |
    | ...       ...     |               +-------------------------+
    | Expert-63 Expert-64               Only invoked experts
    +-------------------+               consume resources
    Always consuming
    full memory footprint
From static provisioning to demand-driven allocation, the core shift is treating experts as ephemeral compute rather than persistent state.
Expert Assessment
Problem choice: Real gap. Multi-tenant MoE serving is an emerging pain point as these models move from research to production. The memory waste is measurable and the serverless angle is underexplored. However, the problem is somewhat narrow—it matters most for edge deployments and smaller MoE models where cold start overhead is tolerable.
Method maturity: Straightforward engineering rather than algorithmic novelty. The insight is architectural: recognizing that MoE’s sparse activation pattern maps naturally to FaaS’s scale-to-zero model. The granularity knob is practical but not surprising. The paper doesn’t address harder questions like expert placement optimization or predictive warming strategies.
Experimental integrity: Baselines are fair but limited. They compare against full-model deployment and show 67% resource reduction, which is believable given the activation sparsity. However, they only test one model (Qwen1.5-MoE-2.7B) and one FaaS platform (OpenFaaS). No comparison against other MoE serving systems like DeepSpeed or Tutel in multi-tenant mode. The workload is synthetic—real production traffic patterns might behave differently. Cold start numbers (1-2s) are measured but not deeply analyzed.
Writing quality: The paper is clear but shallow. Section 3 (design) reads like a system description rather than a design rationale—why these choices over alternatives? Section 4 (evaluation) reports numbers without much interpretation. The related work section misses recent MoE serving papers from late 2023. If they rewrote Section 5 (discussion) to include failure modes, cost analysis, and comparison with expert caching strategies, the paper would be much stronger.
Verdict: weak accept — Solid systems work addressing a real problem, but limited scope and shallow evaluation prevent it from being a strong contribution.
Takeaways
The core idea transfers beyond MoE: any model with sparse activation (conditional computation, early exit, dynamic depth) can benefit from function-based deployment. The granularity knob is worth stealing—it’s a simple way to trade elasticity for overhead in any disaggregated system.
For practitioners: if you’re serving MoE models with bursty multi-tenant traffic and can tolerate 1-2s cold starts, this architecture cuts your memory bill significantly. If you need sub-100ms latency or serve a single high-throughput tenant, stick with traditional deployment.
The paper also hints at a broader pattern: as models grow more modular (MoE, retrieval-augmented, tool-using), serverless primitives become more applicable. The challenge is managing the control plane overhead—routing, aggregation, state management—which this paper doesn’t fully solve.
论文: 2604.26881 作者: Minghe Wang, Trever Schirmer, Mohammadreza Malekabbasi, David Bermbach 分类: cs.DC, cs.LG
缺口
混合专家(MoE)模型每次输入只激活一小部分专家——比如64个专家中的2个——但传统部署方式把所有专家都加载在内存里。
这造成巨大的资源浪费:你为64个专家配置资源,但每次只用2个。
在多租户场景下,不同用户触发不同专家,浪费进一步加剧。
此前的工作(DeepSpeed-MoE、Tutel、MegaBlocks)优化了专家并行和路由,但都假设所有专家常驻内存。
没人认真质疑过”所有专家必须在内存”这个前提。
问题:MoE模型浪费内存
     (配置64个专家,用2个)
            |
            v
假设:FaaS的零缩放能匹配
      MoE的稀疏激活模式
            |
            v
方法:每个专家部署为无状态
      FaaS函数 + 路由器作网关
            |
            v
证据:Qwen1.5-MoE-2.7B负载下
      资源减少67%
            |
            v
结论:无服务器MoE可用于
      多租户边缘部署
增量
一句话: 这篇论文之前,MoE服务意味着所有专家常驻内存;之后,你可以把专家部署为按需调用、请求间隙缩放到零的函数。
核心机制
FaaSMoE把MoE拆成两个平面。
控制平面运行一个轻量级路由器,接收输入token,计算专家路由分数,把请求分发给相应的专家函数。
执行平面由部署为无状态FaaS函数的专家模型组成——每个函数在冷启动时加载专家权重,处理路由来的token,把隐藏状态返回给路由器。
路由器聚合专家输出,传给下一层。
关键设计选择是专家粒度。
你可以每个函数部署一个专家(细粒度)以获得最大弹性,或者把多个专家打包进一个函数(粗粒度)来分摊冷启动开销。
FaaSMoE让这个可配置:粒度因子k意味着每个函数托管k个专家。
k=1时,你得到按专家缩放;k等于总专家数时,你回到单体部署。
把它想象成非高峰时段的餐厅厨房。
传统MoE是所有工作站都配人,即使订单稀疏——烤架、油炸锅、沙拉台都有厨师待命。
FaaSMoE是只在订单到达时才叫相应工作站的厨师。
传菜员(路由器)读每张单,叫相关厨师(专家函数),组装菜品(聚合输出)。
如果你担心叫人时间,可以让每个厨师负责多个工作站(更高的粒度k),这样需要的呼叫更少,用一些空闲时间换更快响应。
关键概念
- 专家激活稀疏性: 在MoE模型中,每个输入token被路由到一小部分专家——通常是8-64个总专家中的1-2个。
路由器为每个专家计算分数,选择top-k。
这意味着对任何给定token,95%以上的专家处于空闲,但传统部署把它们全部加载。
FaaSMoE利用这种稀疏性:如果一个专家没被调用,它就不消耗资源。
- 冷启动分摊: FaaS函数有冷启动延迟——首次调用要把模型加载进内存。
对小专家(~100MB),这需要1-2秒。
FaaSMoE通过两种方式缓解:(1)通过请求模式保持常用专家温热,(2)允许每个函数多个专家,这样一次冷启动加载多个专家。
论文显示在粒度k=4时,实际负载下冷启动降到约15%的请求。
- 多租户资源共享: 当多个用户共享一个MoE部署时,他们的请求触发不同的专家子集。
用户A的查询可能偏好专家1、5、12;用户B偏好3、8、15。
传统部署为所有用户的所有专家的并集配置资源。
FaaSMoE只为任何时刻的活跃工作集配置——如果用户A和B的请求在时间上不重叠,他们的专家函数在内存中也不重叠。
框架转变
之前(单体MoE):                  之后(FaaSMoE):

[输入] --> [路由器]                [输入] --> [路由器/网关]
              |                                  |
              v                                  v
    +-------------------+           +-------------------------+
    | 全部64个专家      |           | FaaS平台                |
    | 加载在内存中      |           |   专家-1 (冷)           |
    |                   |           |   专家-5 (温) <--+      |
    | 专家-1  专家-2    |           |   专家-12 (冷)   |      |
    | 专家-3  专家-4    |           |   ...            |      |
    | ...     ...       |           +-------------------------+
    | 专家-63 专家-64   |           只有被调用的专家
    +-------------------+           消耗资源
    始终消耗
    完整内存占用
从静态配置到需求驱动分配,核心转变是把专家当作临时计算而非持久状态。
专家评审
选题眼光: 真实缺口。
多租户MoE服务是这些模型从研究走向生产时的新痛点。
内存浪费可测量,无服务器角度探索不足。
但问题有点窄——主要对边缘部署和较小MoE模型有意义,那里冷启动开销可容忍。
方法成熟度: 直接的工程而非算法创新。
洞察是架构层面的:认识到MoE的稀疏激活模式自然映射到FaaS的零缩放模型。
粒度旋钮实用但不意外。
论文没解决更难的问题,比如专家放置优化或预测性预热策略。
实验诚意: 基线公平但有限。
他们与全模型部署对比,显示67%资源减少,考虑到激活稀疏性这是可信的。
但只测试了一个模型(Qwen1.5-MoE-2.7B)和一个FaaS平台(OpenFaaS)。
没有与其他MoE服务系统(如DeepSpeed或Tutel)在多租户模式下的对比。
负载是合成的——真实生产流量模式可能表现不同。
冷启动数字(1-2秒)测量了但没深入分析。
写作功力: 论文清晰但浅薄。
第3节(设计)读起来像系统描述而非设计理由——为什么这些选择而非替代方案?第4节(评估)报告数字但缺少解读。
相关工作部分漏掉了2023年底的最新MoE服务论文。
如果他们重写第5节(讨论)加入失效模式、成本分析、与专家缓存策略的对比,论文会强得多。
判决: 弱接收 — 解决真实问题的扎实系统工作,但有限的范围和浅薄的评估阻止它成为强贡献。
要点总结
核心想法可迁移到MoE之外:任何稀疏激活的模型(条件计算、早退出、动态深度)都能从基于函数的部署中受益。
粒度旋钮值得借鉴——它是在任何解耦系统中用弹性换开销的简单方法。
对实践者:如果你在服务有突发多租户流量的MoE模型,能容忍1-2秒冷启动,这个架构能显著削减内存账单。
如果你需要亚100毫秒延迟或服务单个高吞吐租户,坚持传统部署。
论文还暗示了一个更广泛的模式:随着模型变得更模块化(MoE、检索增强、工具使用),无服务器原语变得更适用。
挑战在于管理控制平面开销——路由、聚合、状态管理——这篇论文没完全解决。