Paper: 2606.20537 Authors: Liang Su Categories: cs.LG, cs.DC
The Gap
Current LLM serving systems (e.g., vLLM, TensorRT-LLM) optimize high-throughput, high-concurrency scenarios with paged attention and radix KV caches. These systems treat only the key-value cache as reusable state – they can skip recomputation for a shared prefix. But they manage only that one positional fragment of execution state. They cannot handle the needs of low-latency, small-batch, on-device serving for interactive agents, speech systems, and robot policies. In these settings, tasks repeatedly branch, reset, interrupt, and re-enter under tight responsiveness budgets (e.g., < 50 ms). The existing approach leaves the remainder of execution state – recurrent state in RNNs, convolution state in CNNs, MTP (multi-turn prediction) state, and metadata – exposed to recomputation.
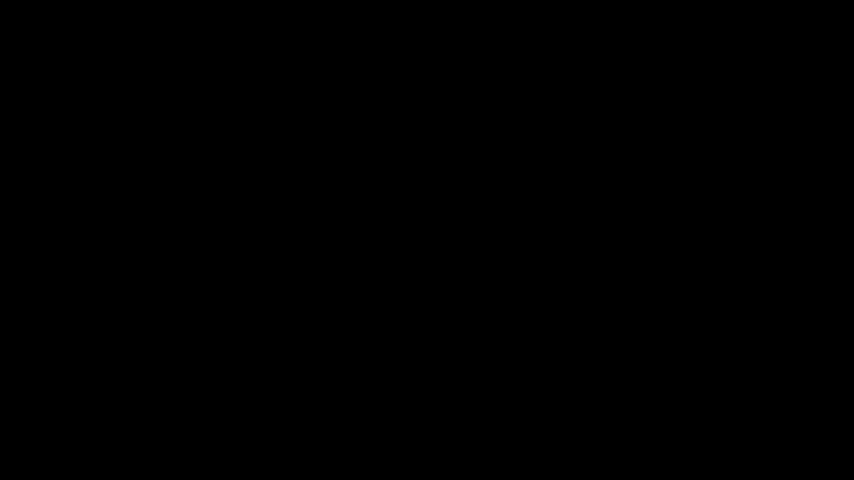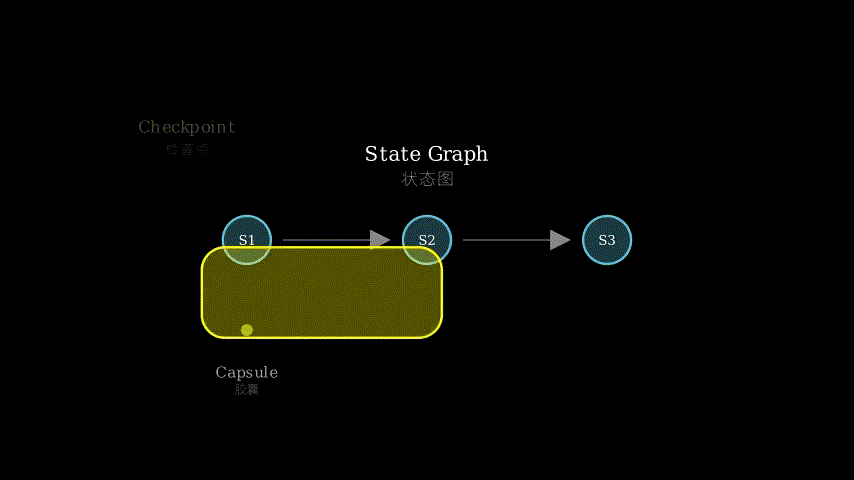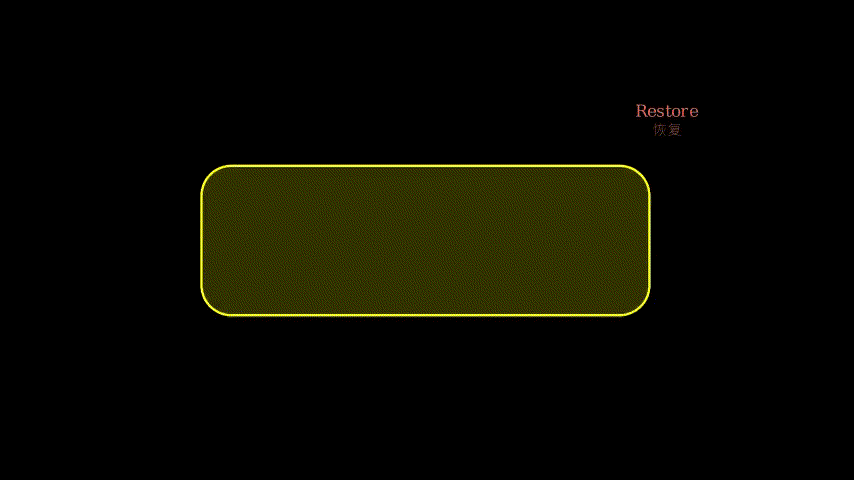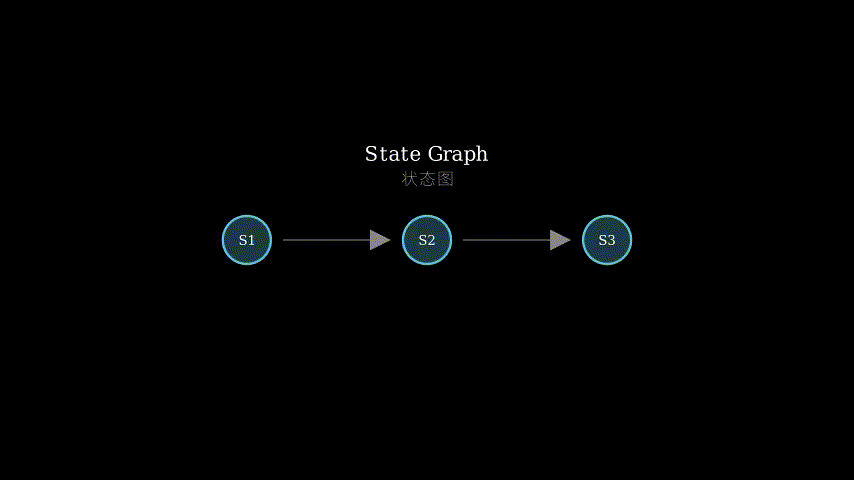
The paper fills this gap by introducing execution-state capsules – a mechanism to checkpoint and restore the entire restorable state at a committed execution boundary. The key insight: when the live state is a closed set of named buffers, you can snapshot, restore, fork, or roll back the whole boundary, not just the KV column.
Problem -> Assumption -> Method -> Evidence -> Conclusion
    |           |             |           |            |
    v           v             v           v            v
Low-latency   Only KV       Capsules:   Byte-exact  Capsules not
on-device     cache is      full-state   restore,    for high-
serving       reused.       snapshot/   sub-ms,      throughput
suffers       Rest of       restore     27x TTFT    but define
from full     state is      on graph    speedup      a new
recompute.    recomputed.   boundaries  (2k-16k).   serving
                                           Recurrent  point.
                                           state is
                                           load-bearing
                                           (ablation).
The Increment
One sentence: Before this paper, only the KV cache fragment could be reused across sequence boundaries; after this paper, the entire execution state (KV, recurrent, convolution, MTP, metadata) can be checkpointed and restored at graph boundaries, enabling low-latency branching and resumption on device.
Core Mechanism
The method is implemented in FlashRT, a white-box, backend-facing kernel runtime. Its CUDA backend executes captured graph plans over contiguous static buffers with no block-table indirection. The key components:
- Graph plan: A compiled DAG of operations (kernels) with fixed buffer assignments. The graph is executed in order, but at certain “committed boundaries” (e.g., after each decode step, or at a branching point), a capsule can be taken.
- Named buffers: All live state lives in a closed set of pre-allocated, contiguous GPU buffers (e.g., KV_cache, recurrent_state, conv_state, mpt_state, metadata). No dynamic memory management.
- Capsule: A serialized checkpoint that captures the byte contents of all named buffers, plus a tiny control structure (graph plan ID, step count, etc.). Snapshot = copy buffers to a separate GPU region. Restore = copy back. Fork = copy to new region, then both can continue. Rollback = restore previous version.
Data flow: application calls snapshot() at a boundary -> FlashRT memcpy-D2D all buffer contents to capsule storage -> later, restore() copies back -> application continues from exact same execution point. All operations are GPU-resident and take < 1 ms for typical model sizes.
          +-------------------+
          |  Application      |
          |  (agent, speech)  |
          +--------+----------+
                   | call: snapshot/restore
                   v
          +-------------------+
          |  FlashRT runtime  |
          |  +--------------+ |
          |  | Graph plan   | |
          |  | (DAG of ops) | |
          |  +------+-------+ |
          |         |         |
          |  +------v-------+ |
          |  | Named buffers| |
          |  | (contiguous) | |
          |  +------+-------+ |
          |         |         |
          |  +------v-------+ |
          |  | Capsule store| |
          |  | (GPU memory) | |
          |  +--------------+ |
          +-------------------+
                 | memcpy D2D
                 v
          +-------------------+
          | Capsule storage   |
          | (separate region) |
          +-------------------+
Structural metaphor: Think of a construction set (Lego) project. The graph plan is the instruction manual, numbered steps. The named buffers are bins of specific brick types (2x4, 1x2, plate, etc.) – each bin’s content at a given step determines the current shape. A capsule is a photograph of each bin’s exact brick arrangement at the end of a step. To restore, you empty the bins and place bricks exactly as in the photo. To fork, you take two photos (or copy the photo) and then continue building two different versions from that same arrangement. The key is that the photo captures all bins, not just the “texture” bin (KV cache). If you only photographed the texture bin, the other bins would be random when you try to restore, and the structure would collapse. That is exactly what the ablation experiment shows: a KV-only capsule diverges, because recurrent state (the “structural” bins) is load-bearing.
Key Concepts
-
Execution-state capsule: A serialized checkpoint of the entire set of named GPU buffers that constitute the live state at a committed execution boundary. It is not a model checkpoint (weights) but an inference state checkpoint. The capsule includes KV cache, recurrent state, convolution state, MTP (multi-turn prediction) hidden states, and any metadata (step count, beam index). Because it captures the entire closed set, restore is byte-exact and token-identical under greedy decoding.
-
Graph-bound serving: Unlike token-addressed caching (where state is indexed by token position in a sequence), this work binds state to graph execution boundaries. The graph plan defines a fixed schedule of operations. The state is not tied to token identity but to the step number in the graph (e.g., layer 5 of decoder, step 12). This makes capsules suitable for branching, where multiple sequences diverge from a common ancestor – they share the same capsule data up to the branch point.
-
Low-latency regime: The paper specifically targets settings where batch size = 1 (or small), latency is critical (e.g.,
< 10 mstotal), and the workload involves frequent branching, resetting, and interruption. Example: a robot policy that continuously re-plans after each sensor input, requiring state to be rolled back and re-used from multiple previous checkpoints. This is the opposite of data-center serving where large batches and long sequences dominate.
Framework Shift
Before (mainstream approach):        After (this paper):
+---------+  +---------+            +---------+  +---------+
| User A  |  | User B  |            | Agent   |  | Agent   |
+----+----+  +----+----+            | branch1 |  | branch2 |
     |            |                  +----+----+  +----+----+
     v            v                       |            |
+----------+ +----------+                | capsule   |
| KV cache  | | KV cache |               | snapshot  |
| (prefix)  | | (prefix) |               v            |
+----------+ +----------+          +------------------+
    reuse only KV                   | Capsule at step |
    fragments                       | (full state)    |
                                     +--------+-------+
                                              | restore
                                              v
                                     +------------------+
                                     | New branch      |
                                     | (reuse all      |
                                     |  state types)   |
                                     +------------------+
From token-addressed KV fragment reuse to graph-bound full-state boundary reuse, the core shift is extending the reuseable state beyond the single element (KV) to the entire execution context.
Expert Assessment
Problem choice: Real gap. On-device AI for robotics, speech, and interactive agents is underserved by current serving systems designed for datacenter throughput. The paper identifies a clean regime where full-state checkpointing is both necessary and feasible (small batch, deterministic graph execution).
Method maturity: The insight is clever but not radical – it applies existing checkpoint/restore techniques to a new scope (full execution state, not just KV). The implementation (FlashRT, CUDA) is solid, but the paper relies on a custom runtime; it doesn’t integrate with popular frameworks like PyTorch. The ablation showing recurrent state is load-bearing is key evidence.
Experimental integrity: Baselines are reasonable (compare against cold prefill, KV-only capsule). The speedup numbers (3.9x at 2k, 27x at 16k) are impressive. However, the paper does not compare against a baseline with KV cache reuse (e.g., vLLM on device) – perhaps because those systems are not designed for small-batch. The ablation is convincing. One red flag: the evaluation only reports TTFT (time to first token) – what about total decode time? For interactive agents, incremental decode latency matters too. Also, no power or energy numbers, which are critical for on-device.
Writing quality: Generally clear. The abstract and introduction effectively set up the contrast. The method section could be more accessible – the diagrams help, but the text is dense. The “structural metaphor” is not present in the paper; I added it here. The paper would benefit from a concrete end-to-end example (e.g., an interactive agent loop). The related work section is thin; more positioning against other checkpointing systems (e.g., DNN checkpoint libraries) would help.
Verdict: weak accept – a well-motivated, clean solution for a specific, underserved serving regime. The method is not generally novel, but the application and thorough evaluation justify publication. The paper opens a new axis for serving optimization.
Takeaways
- Full-state checkpointing at graph boundaries is a concrete technique you can steal for any model where the inference state is a closed set of named buffers. Applicable to RNNs, CNNs (e.g., for video), models with multiple recurrent components.
- The ablation showing KV-only divergence is a cautionary tale: when building state reuse systems, verify that only reusing the obvious part (KV) suffices. Often it doesn’t.
- For practitioners deploying on-device agents: consider using a custom runtime that can snapshot/restore on every interaction turn. This could replace repeated prefill for interleaved user/system turns.
- The contiguous buffer design eliminates fragmentation overhead and makes checkpointing cheap – a good pattern for low-latency GPU systems.
论文: 2606.20537 作者: Liang Su 分类: cs.LG, cs.DC
缺口
目前的 LLM 服务系统(如 vLLM、TensorRT-LLM)针对高吞吐、高并发场景优化。它们使用分页注意力(paged attention)和基数 KV 缓存(radix KV cache)来重用前缀计算。但这类系统只管理 KV 缓存这一种执行状态片段。
它们无法满足低延迟、小批量、设备端物理 AI 服务的需求——例如交互式智能体、语音系统、机器人策略。
这些场景频繁出现分支、重置、中断和重新进入,且响应时间要求苛刻(如 < 50ms)。
该论文填补了这个缺口:提出执行状态胶囊(execution-state capsules)——在确定的执行边界对整个可恢复状态做检查点保存与加载。 核心洞察是:当实时状态是一个封闭的命名缓冲区集合时,你可以对整个边界做快照、恢复、分支或回滚,而不仅仅是 KV 片段。
问题 -> 假设 -> 方法 -> 证据 -> 结论
 |        |        |        |        |
 v        v        v        v        v
低延迟    只有KV   胶囊:    字节精确  胶囊不是
设备端    缓存被   完整状    恢复,   为高吞吐
AI服务    重用。   态快照/  亚毫秒,  设计,但
受困于    其余状   恢复,   27倍     定义了一
完全重    态被重   基于图    首token  个新的服
计算。    计算。   边界。    加速。   务点。
                    循环状态
                    是关键
                     (消融).
增量
一句话: 之前,只有 KV 缓存片段能在序列间重用;之后,整个执行状态(KV、循环状态、卷积状态、多轮预测状态、元数据)都能在图边界上做检查点保存和恢复,从而在设备端实现低延迟分支和重入。
核心机制
该方法实现于 FlashRT——一个白盒、面向后端的核函数运行时。它的 CUDA 后端在连续的静态缓冲区上执行捕获的图计划,没有块表间接寻址。
关键组件:
- 图计划:经过编译的操作 DAG,每个操作有固定的缓冲区分配。
- 命名缓冲区:所有活状态都位于一个封闭的预分配连续 GPU 缓冲区集合中(如 KV_cache、recurrent_state、conv_state、mpt_state、metadata)。没有动态内存管理。
- 胶囊:序列化检查点,捕获所有命名缓冲区的字节内容,外加一个小小的控制结构(图计划 ID、步数等)。 快照 = 将缓冲区内容拷贝到独立的 GPU 区域。恢复 = 拷贝回来。分支 = 拷贝到新区域,两边继续执行。回滚 = 恢复先前版本。
数据流:应用在边界调用 snapshot() -> FlashRT 执行 D2D memcpy 将所有缓冲区拷贝到胶囊存储 -> 之后调用 restore() 拷贝回来 -> 应用从完全相同执行点继续。所有操作在 GPU 上完成,典型模型 < 1 ms。
          +-------------------+
          |  应用             |
          |  (agent, speech) |
          +--------+----------+
                   | 调用 snapshot/restore
                   v
          +-------------------+
          |  FlashRT 运行时   |
          |  +--------------+ |
          |  | 图计划       | |
          |  | (操作 DAG)   | |
          |  +------+-------+ |
          |         |         |
          |  +------v-------+ |
          |  | 命名缓冲区   | |
          |  | (连续)       | |
          |  +------+-------+ |
          |         |         |
          |  +------v-------+ |
          |  | 胶囊存储     | |
          |  | (GPU 内存)   | |
          |  +--------------+ |
          +-------------------+
                 | memcpy D2D
                 v
          +-------------------+
          | 胶囊存储区域     |
          | (独立区域)       |
          +-------------------+
结构性比喻:想象一套乐高积木项目。图计划是说明书上的步骤编号。命名缓冲区是不同砖块类型的盒子(2x4、1x2、板片等)——某个步骤时每个盒子的砖块排列决定了当前的形状。一颗胶囊就是每个盒子当前砖块排布的精确照片。恢复时,你清空盒子,按照照片把砖块放回去。分支时,你拍两张照片(或复制一张),然后从同一布局出发搭两个不同版本。关键是,照片必须捕捉所有盒子,而不只是”纹理”盒子(KV缓存)。如果你只拍了纹理盒子的照片,恢复时其他盒子的砖块就是随机的,结构就会崩掉。消融实验正是如此:仅含 KV 的胶囊导致结果不一致,因为循环状态(“结构”盒子)是承载负荷的。
关键概念
-
执行状态胶囊(execution-state capsule):在某个确定执行边界上,对整个封闭的命名 GPU 缓冲区集合所做的序列化检查点。不是参数检查点,而是推理状态检查点。包含 KV cache、循环状态、卷积状态、多轮预测隐藏状态以及元数据(步数、beam 索引)。因为捕捉了整个封闭集合,恢复是字节精确的,贪心解码下 token 完全相同。
-
图绑定服务(graph-bound serving):与基于 token 地址的缓存不同(状态按序列中的 token 位置索引),本文把状态绑定到图执行边界。图计划定义了固定操作调度顺序。状态不绑定令牌身份,而是绑定图中的步骤编号(如解码器第5层,第12步)。这使胶囊适合分支:多个序列从同一祖先分叉,分支点之前共享同一胶囊数据。
-
低延迟范式(low-latency regime):论文专门针对批量大小=1(或很小)、延迟关键(例如总响应
< 10ms)、工作负载频繁分支、重置和中断的场景。例如,机器人策略在每次传感器输入后不断重新规划,需要从多个先前检查点回滚并重用状态。这与数据中心大批量、长序列的服务截然相反。
框架转变
之前(主流方法):               之后(本文方法):
+---------+  +---------+       +---------+  +---------+
| 用户A   |  | 用户B   |       | 智能体   |  | 智能体   |
+----+----+  +----+----+       | 分支1   |  | 分支2   |
     |            |            +----+----+  +----+----+
     v            v                 |            |
+----------+ +----------+          | 胶囊快照   |
| KV 缓存  | | KV 缓存  |          v            |
| (前缀)   | | (前缀)   |    +------------------+
+----------+ +----------+    | 步骤 N 的胶囊    |
   只重用 KV 片段             | (完整状态)       |
                              +--------+---------+
                                       | 恢复
                                       v
                              +------------------+
                              | 新分支           |
                              | (重用所有状态)   |
                              +------------------+
从基于 token 地址的 KV 片段重用到基于图边界的完整状态重用,核心转变是将可重用状态从单一元素(KV)扩展到整个执行上下文。
专家评审
选题眼光: 真实缺口。目前的设备端 AI(机器人、语音、交互式智能体)需求被面向数据中心吞吐量的服务系统忽视。论文清晰指出了一个需要完整状态检查点的场景,且在该场景下实现可行(小批量、确定性图执行)。
方法成熟度: 想法巧妙但非根本性创新——它把已有的检查点/恢复技术应用到新范围(完整执行状态而非仅 KV)。实现(FlashRT,CUDA)扎实,但论文依赖自定义运行时,未集成 PyTorch 等流行框架。消融实验证明循环状态至关重要,是核心证据。
实验诚意: 基线合理(对比冷启动、仅 KV 胶囊)。加速比数字(2k 时 3.9x,16k 时 27x)令人印象深刻。但未与设备端 KV 缓存重用系统(如 vLLM 在设备上)对比——可能因为那些系统不为小批量设计。消融令人信服。一个关注点:仅报告首 token 延迟(TTFT),没有总解码时间——对于交互式智能体,增量解码延迟也很重要。另外没有功耗或能耗数据,这对设备端很关键。
写作功力: 整体清晰。摘要和引言有效构建对比。方法部分可以更易读——图有帮助但文字密集。论文没有我在这里加的结构性比喻。如果有一个完整的端到端示例(如交互式智能体循环)会更好。相关工作部分薄弱;可以更多定位与其他检查点系统(如 DNN 检查点库)的关系。
判决: 弱接收——一个动机充分、针对特定但被忽视的服务范式的干净方案。方法并非普遍新奇,但应用和全面评估值得发表。论文为服务优化开辟了新维度。
要点总结
- 在图边界做完整状态检查点是一个具体技术,可移植到任何推理状态为封闭命名缓冲区集合的模型中。适用 RNN、CNN(如视频模型)、多循环组件模型。
- 仅 KV 的消融导致不一致是一个警示:在构建状态重用系统时,务必验证只重用明显部分(KV)是否足够。通常不够。
- 对在设备端部署智能体的实践者:考虑使用支持每次交互轮次做快照/恢复的自定义运行时。这可以替代交替用户/系统轮次中的重复预填充。
- 连续缓冲区设计消除了碎片开销,使检查点成本低廉——这是低延迟 GPU 系统的好模式。