Paper: 2604.06154 Authors: Mutsumi Sasaki, Kouta Nakayama, Yusuke Miyao, Yohei Oseki, Masaru Isonuma Categories: cs.CL
The Gap
Existing machine unlearning methods operate like a blacklist: you identify specific harmful knowledge (hate speech patterns, dangerous instructions, toxic expressions) and surgically remove it from the model. This works for known threats but fails catastrophically against the long tail of harm. New jailbreak techniques emerge daily. Cultural contexts shift what counts as harmful. The attack surface is infinite, but your blacklist is finite.
The core limitation: reactive enumeration doesn’t scale. You’re playing whack-a-mole with an adversary who invents new moles faster than you can swing.
Problem: Infinite harmful content variants
   |
   v
Assumption: Whitelist (safe knowledge) is smaller than blacklist (harmful content)
   |
   v
Method: Forget everything EXCEPT explicitly retained knowledge
   |
   v
Evidence: Maintains domain performance + resists diverse jailbreaks
   |
   v
Conclusion: Inversion of unlearning paradigm enables comprehensive safety
The Increment
One sentence: Before this paper, we removed known bad things from models; after, we can remove everything except known good things.
Core Mechanism
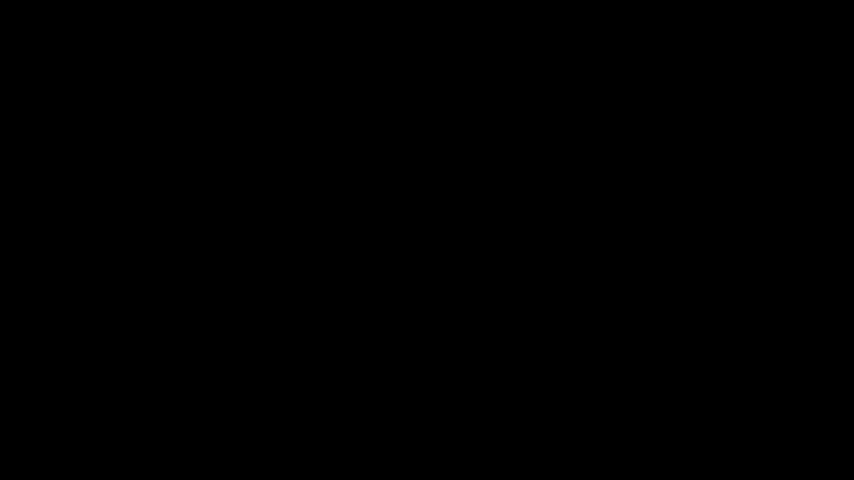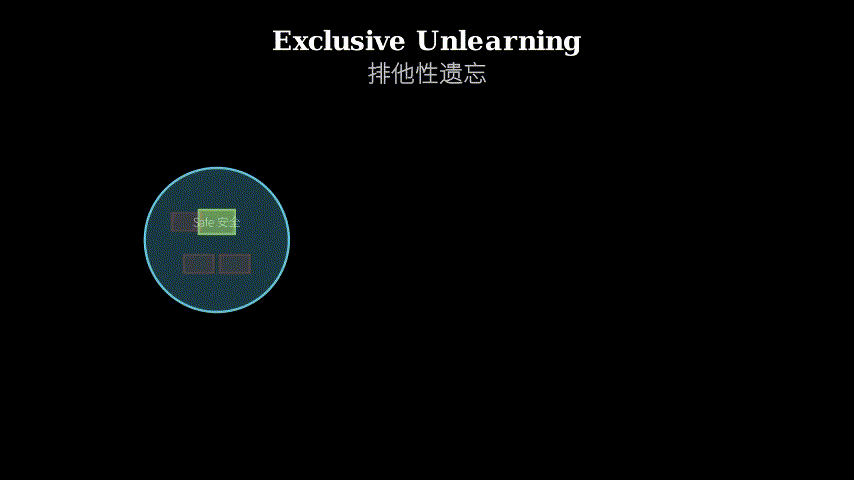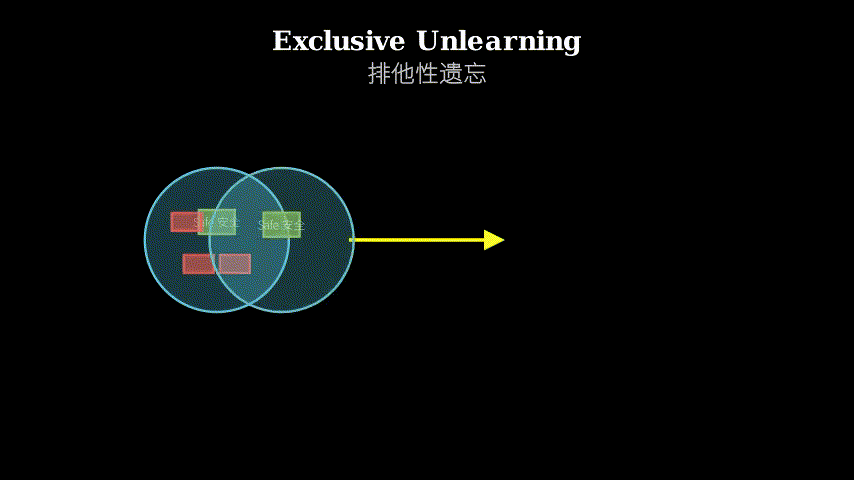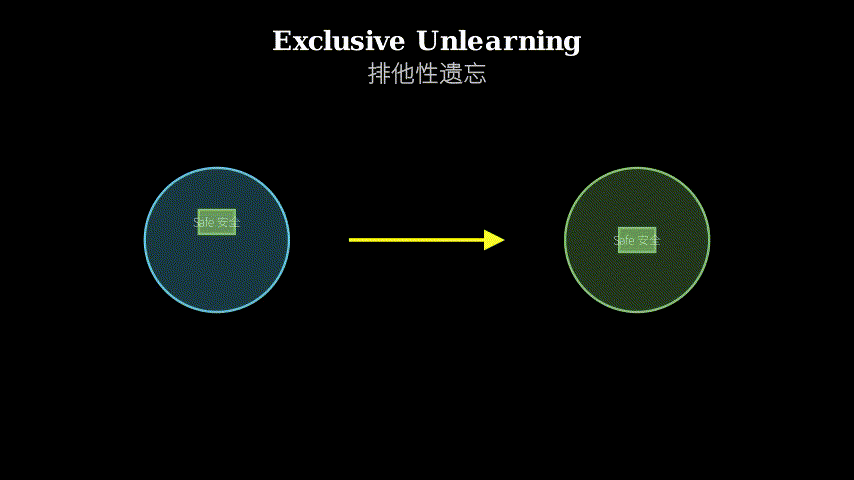
Exclusive Unlearning inverts the standard unlearning setup. Traditional methods take a pretrained model and a “forget set” of harmful examples, then optimize to degrade performance on those examples while preserving general capabilities. EU instead takes a “retain set” of safe, useful examples (medical Q&A, math problems, general instructions) and optimizes to preserve ONLY those capabilities while degrading everything else.
The training process uses a dual objective: maximize likelihood on the retain set while minimizing likelihood on a broad “forget set” that represents general knowledge. The forget set isn’t carefully curated harmful content—it’s just diverse text from the original pretraining corpus. The key insight is that by making the forget set large and diverse, you’re effectively erasing the model’s general knowledge base, leaving only the narrow capabilities defined by your retain set.
Implementation uses gradient ascent on the forget set (pushing those probabilities down) and gradient descent on the retain set (keeping those probabilities high). The balance between these objectives controls how aggressively you erase general knowledge versus how much you preserve domain-specific capabilities.
Pretrained Model
      |
      v
   [Retain Set]  <--- Safe domain knowledge (medicine, math, etc.)
      |
      +----------> Gradient Descent (preserve)
      |
   [Forget Set]  <--- Broad general knowledge
      |
      +----------> Gradient Ascent (erase)
      |
      v
  EU Model (narrow but safe)
Think of it like renovating a house by demolition. Traditional unlearning is removing specific rooms you don’t want (the meth lab in the basement, the asbestos insulation). Exclusive Unlearning is tearing down the entire house except for the rooms you explicitly want to keep (kitchen, bedroom, bathroom). You mark those rooms with tape, then bring in the wrecking ball. Everything outside the tape gets demolished. The result is a smaller house, but you’re guaranteed there’s no hidden meth lab because there’s no hidden anything—only what you explicitly preserved survives.
Key Concepts
-
Retain Set as Safety Boundary: In traditional ML, your training set defines what the model learns. In EU, your retain set defines what the model is ALLOWED to know. It’s not just training data—it’s a capability whitelist. If a skill isn’t represented in the retain set, the model loses it. This makes the retain set curation the critical safety bottleneck: you must enumerate all legitimate use cases upfront, or you’ll accidentally erase them.
-
Gradient Ascent on Forget Set: Normal training minimizes loss (makes the model better at predicting the data). Gradient ascent maximizes loss (makes the model worse at predicting the data). When you do gradient ascent on a broad forget set, you’re systematically degrading the model’s ability to generate that kind of content. It’s like running the training process in reverse. The model “unlearns” by moving its weights in the direction that makes those predictions less likely.
-
Whitelist vs Blacklist Paradigm: Security systems use two approaches: blacklists (block known bad things) and whitelists (allow only known good things). Blacklists are convenient but incomplete. Whitelists are restrictive but comprehensive. EU applies whitelist thinking to model capabilities: instead of trying to enumerate all harmful behaviors to block, enumerate all safe behaviors to allow. Everything else gets blocked by default. The tradeoff is reduced flexibility—your model can only do what you explicitly permitted.
Framework Shift
Before (Blacklist Unlearning):        After (Whitelist Unlearning):

  [Pretrained Model]                    [Pretrained Model]
         |                                      |
    Full Capability                        Full Capability
         |                                      |
         v                                      v
  Remove: Hate speech                    Retain: Medicine
  Remove: Violence                       Retain: Math
  Remove: Toxicity                       Retain: Coding
  Remove: ...                            Forget: Everything else
         |                                      |
         v                                      v
  [Model with holes]                     [Model with walls]
   Still vulnerable to                    Safe by default,
   unknown attacks                        limited by design
From reactive patching to proactive containment, the core shift is inverting the default assumption from “allow unless blocked” to “block unless allowed”.
Expert Assessment
Problem choice: Real gap. The arms race between jailbreak techniques and safety patches is genuinely unsustainable for production systems. However, the paper frames this as purely a technical problem when it’s also a product design problem—do we actually want LLMs with such narrow capabilities? The gap is real but the solution space is broader than presented.
Method maturity: Conceptually elegant but operationally naive. The hard part isn’t the gradient ascent/descent mechanics—it’s curating a retain set that captures all legitimate use cases without accidentally including attack vectors. The paper handwaves this with “domain-specific datasets” but doesn’t address how you’d build a retain set for a general-purpose assistant. Also, no analysis of what happens when users need capabilities outside the retain set—do you just tell them “sorry, we forgot how to do that for safety reasons”?
Experimental integrity: Baselines are fair but limited. They compare against standard unlearning methods and show EU is more robust to jailbreaks. However, they only test on a few domains (medicine, math) and don’t explore the boundary cases—what happens with ambiguous queries that could be legitimate or harmful depending on context? The jailbreak evaluation uses existing benchmarks, which is good, but doesn’t test against adaptive attacks designed specifically to exploit EU’s whitelist structure.
Writing quality: The introduction oversells the novelty—inverting unlearning from blacklist to whitelist is a straightforward idea once stated. The method section is clear but the evaluation section buries important limitations in supplementary material. The discussion of retain set curation (the actual hard problem) gets two paragraphs. Rewriting Section 4 to honestly address the operational challenges of deploying EU would elevate this from a neat trick to a serious proposal.
Verdict: weak accept — Solid idea with clean execution, but the paper solves the easy part (mechanics) while underexploring the hard part (retain set design and real-world deployment constraints).
Takeaways
Inversion as a design pattern: When you can’t enumerate all bad cases, try enumerating all good cases instead. This applies beyond ML safety—API design, access control, content moderation. The tradeoff is always flexibility vs security.
Gradient ascent for capability removal: If you need to make a model worse at something, gradient ascent on that task is a principled approach. Useful for removing biases, forgetting copyrighted content, or degrading performance on proxy tasks that correlate with unwanted behaviors.
Retain set curation is the bottleneck: The paper’s main contribution is showing that whitelist unlearning works technically. The main unsolved problem is how to build retain sets that are comprehensive enough for real applications but narrow enough for safety guarantees. If you’re deploying this, budget most of your effort for retain set design, not training.
论文: 2604.06154 作者: Mutsumi Sasaki, Kouta Nakayama, Yusuke Miyao, Yohei Oseki, Masaru Isonuma 分类: cs.CL
缺口
现有的机器遗忘方法像黑名单一样运作:你识别出特定的有害知识(仇恨言论模式、危险指令、有毒表达),然后从模型中精准移除。
这对已知威胁有效,但面对长尾危害时会灾难性失败。
新的越狱技术每天都在出现。
文化语境会改变什么算作有害。
攻击面是无限的,但你的黑名单是有限的。
核心局限:被动枚举无法扩展。
你在和一个发明新鼹鼠的速度比你挥锤子还快的对手玩打地鼠游戏。
问题:无限的有害内容变体
   |
   v
假设:白名单(安全知识)比黑名单(有害内容)小
   |
   v
方法:忘掉除了明确保留的知识之外的一切
   |
   v
证据:保持领域性能 + 抵抗多样化越狱
   |
   v
结论:遗忘范式的反转实现全面安全
增量
一句话: 这篇论文之前,我们从模型中移除已知的坏东西;之后,我们可以移除除了已知好东西之外的一切。
核心机制
排他性遗忘反转了标准的遗忘设置。
传统方法拿一个预训练模型和一个有害样本的”遗忘集”,然后优化以降低在这些样本上的性能,同时保留通用能力。
EU则拿一个安全有用样本的”保留集”(医学问答、数学问题、通用指令),优化以只保留这些能力,同时降低其他一切。
训练过程使用双重目标:最大化保留集上的似然,同时最小化广泛”遗忘集”上的似然。
遗忘集不是精心策划的有害内容——只是来自原始预训练语料库的多样化文本。
关键洞察是,通过让遗忘集大而多样,你实际上在擦除模型的通用知识库,只留下由保留集定义的狭窄能力。
实现使用遗忘集上的梯度上升(把这些概率压下去)和保留集上的梯度下降(把这些概率保持高位)。
这些目标之间的平衡控制着你擦除通用知识的激进程度与保留领域特定能力的程度。
预训练模型
      |
      v
   [保留集]  <--- 安全领域知识(医学、数学等)
      |
      +----------> 梯度下降(保留)
      |
   [遗忘集]  <--- 广泛的通用知识
      |
      +----------> 梯度上升(擦除)
      |
      v
  EU模型(狭窄但安全)
把它想象成通过拆除来翻新房子。
传统遗忘是移除你不想要的特定房间(地下室的制毒实验室、石棉保温层)。
排他性遗忘是拆掉整栋房子,除了你明确想保留的房间(厨房、卧室、浴室)。
你用胶带标记那些房间,然后带来破坏球。
胶带外的一切都被拆除。
结果是一栋更小的房子,但你保证没有隐藏的制毒实验室,因为没有任何隐藏的东西——只有你明确保留的才能存活。
关键概念
- 保留集作为安全边界: 在传统机器学习中,你的训练集定义模型学什么。
在EU中,你的保留集定义模型被允许知道什么。
它不只是训练数据——它是能力白名单。
如果一个技能没有在保留集中表示,模型就会失去它。
这使得保留集的策划成为关键的安全瓶颈:你必须预先枚举所有合法用例,否则你会意外擦除它们。
- 遗忘集上的梯度上升: 正常训练最小化损失(让模型更擅长预测数据)。
梯度上升最大化损失(让模型更不擅长预测数据)。
当你在广泛的遗忘集上做梯度上升时,你在系统性地降低模型生成那种内容的能力。
这就像反向运行训练过程。
模型通过将权重移动到使这些预测不太可能的方向来”遗忘”。
- 白名单vs黑名单范式: 安全系统使用两种方法:黑名单(阻止已知的坏东西)和白名单(只允许已知的好东西)。
黑名单方便但不完整。
白名单限制性强但全面。
EU将白名单思维应用于模型能力:不是试图枚举所有要阻止的有害行为,而是枚举所有要允许的安全行为。
其他一切默认被阻止。
权衡是降低灵活性——你的模型只能做你明确允许的事情。
框架转变
之前(黑名单遗忘):                之后(白名单遗忘):

  [预训练模型]                        [预训练模型]
         |                                   |
    全部能力                              全部能力
         |                                   |
         v                                   v
  移除:仇恨言论                        保留:医学
  移除:暴力                            保留:数学
  移除:毒性                            保留:编程
  移除:...                             遗忘:其他一切
         |                                   |
         v                                   v
  [有漏洞的模型]                        [有围墙的模型]
   仍然容易受到                          默认安全,
   未知攻击                              设计上受限
从被动修补到主动遏制,核心转变是将默认假设从”除非阻止否则允许”反转为”除非允许否则阻止”。
专家评审
选题眼光: 真实缺口。
越狱技术和安全补丁之间的军备竞赛对生产系统来说确实不可持续。
然而,论文将此纯粹框定为技术问题,而它也是产品设计问题——我们真的想要能力如此狭窄的大语言模型吗?缺口是真实的,但解决方案空间比呈现的更广。
方法成熟度: 概念上优雅但操作上天真。
困难的部分不是梯度上升/下降机制——而是策划一个保留集,既能捕获所有合法用例,又不会意外包含攻击向量。
论文用”领域特定数据集”轻描淡写,但没有解决如何为通用助手构建保留集。
此外,没有分析当用户需要保留集之外的能力时会发生什么——你只是告诉他们”抱歉,为了安全我们忘了怎么做那个”吗?
实验诚意: 基线公平但有限。
他们与标准遗忘方法比较,显示EU对越狱更稳健。
然而,他们只在几个领域(医学、数学)上测试,没有探索边界情况——对于根据上下文可能合法或有害的模糊查询会发生什么?越狱评估使用现有基准,这很好,但没有测试专门设计来利用EU白名单结构的自适应攻击。
写作功力: 引言过度推销新颖性——将遗忘从黑名单反转为白名单一旦说出来就是个直接的想法。
方法部分清晰,但评估部分将重要局限埋在补充材料中。
关于保留集策划(实际的难题)的讨论只有两段。
重写第4节以诚实地解决部署EU的操作挑战,会将这篇论文从一个巧妙技巧提升为严肃提案。
判决: 弱接收 — 扎实的想法和干净的执行,但论文解决了简单的部分(机制),同时对困难的部分(保留集设计和真实世界部署约束)探索不足。
要点总结
反转作为设计模式: 当你无法枚举所有坏情况时,尝试枚举所有好情况。
这适用于机器学习安全之外——API设计、访问控制、内容审核。
权衡总是灵活性vs安全性。
用于能力移除的梯度上升: 如果你需要让模型在某事上变差,在那个任务上做梯度上升是一种有原则的方法。
对移除偏见、遗忘受版权保护的内容或降低与不想要行为相关的代理任务的性能很有用。
保留集策划是瓶颈: 论文的主要贡献是展示白名单遗忘在技术上可行。
主要未解决的问题是如何构建既足够全面用于实际应用又足够狭窄以保证安全的保留集。
如果你要部署这个,将大部分精力预算用于保留集设计,而不是训练。