Paper: 2603.12267 Authors: Tianwei Xiong, Jun Hao Liew, Zilong Huang, Zhijie Lin, Jiashi Feng, Xihui Liu Categories: cs.CV
The Gap
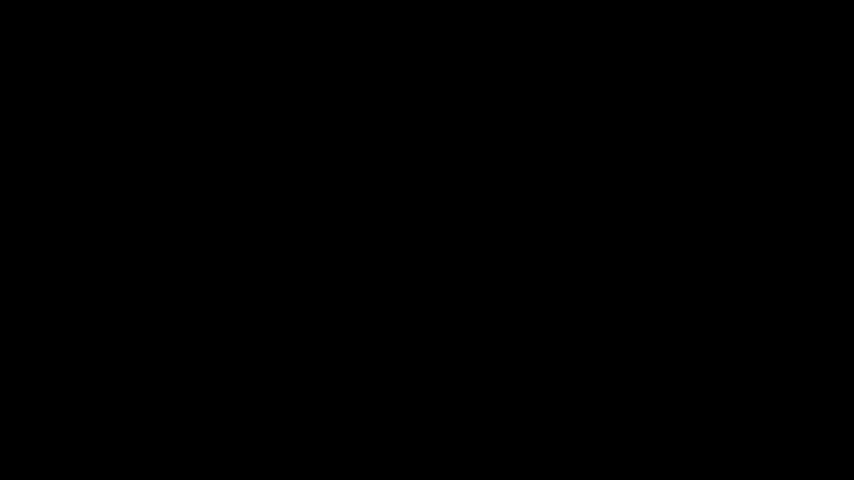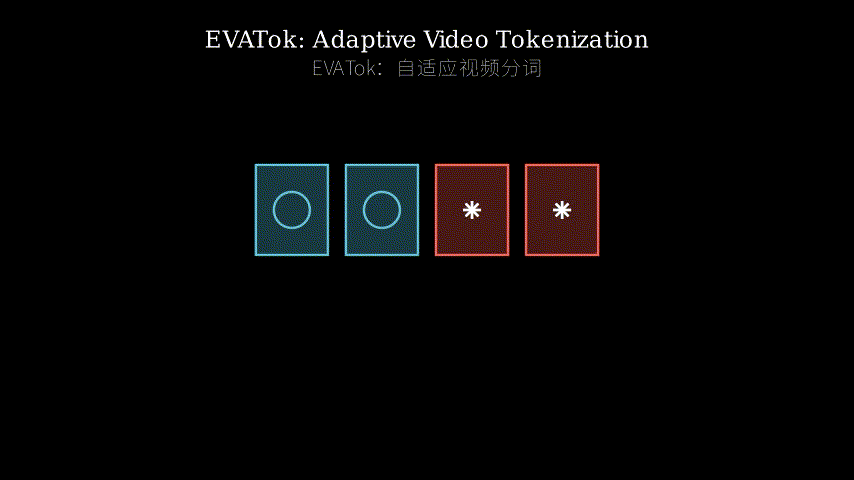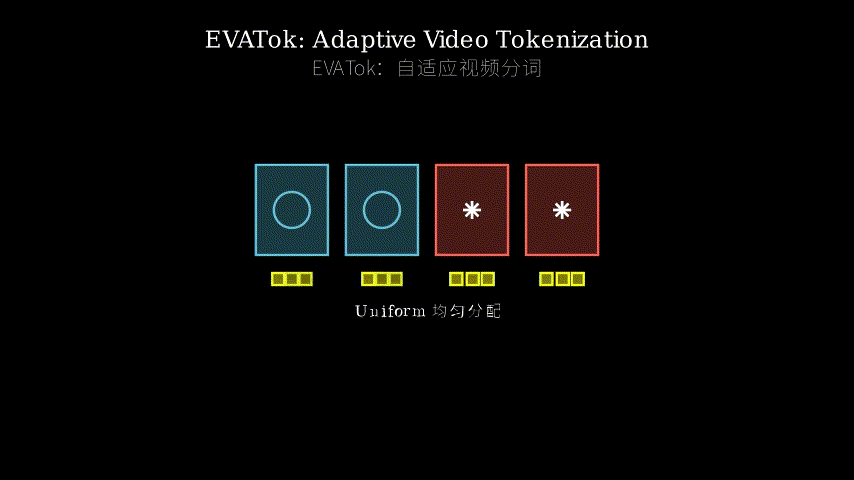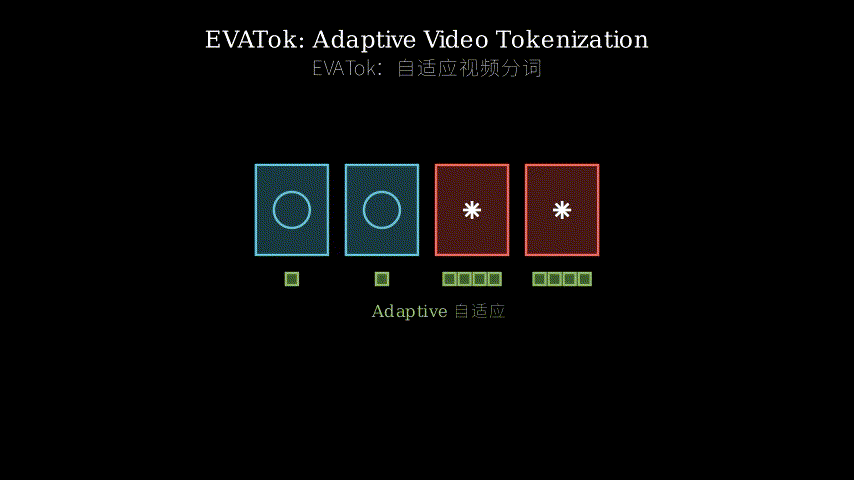
Autoregressive video generation works by first compressing video into discrete tokens, then training a transformer to predict those tokens sequentially. The quality ceiling and the compute cost both scale directly with token count. Prior tokenizers — including the recent LARP — assign a fixed number of tokens per temporal block regardless of what’s actually in that block. A talking head with a static background gets the same token budget as a chaotic action sequence. That’s a fundamental mismatch between representation cost and information content.
The prior art’s assumption is: uniform compression is good enough. But it isn’t. Static segments are over-tokenized (wasted capacity), dynamic segments are under-tokenized (quality loss), and the downstream AR model pays full compute for every token whether it was necessary or not.
Problem: Fixed token budget per block, regardless of content complexity
    |
    v
Assumption: Uniform compression is sufficient for all video types
    |
    v
Consequence: Static blocks waste tokens / Dynamic blocks lose quality
    |
    v
Method: Estimate optimal per-block token count -> train lightweight router
         -> train tokenizer conditioned on variable-length assignments
    |
    v
Evidence: 24.4%+ token savings vs LARP on UCF-101, state-of-the-art FVD
    |
    v
Conclusion: Adaptive allocation dominates fixed allocation on quality-cost curve
The Increment
One sentence: Before EVATok, video tokenizers treated every temporal block as equally complex; after EVATok, token budgets are routed dynamically based on content, making the quality-cost tradeoff a dial rather than a fixed point.
Core Mechanism
EVATok has three moving parts that are trained in sequence. First, an oracle search: for each training video, they sweep over possible token-count assignments across temporal blocks and find the assignment that maximizes reconstruction quality at a given total budget. This gives them a dataset of (video, optimal assignment) pairs — ground truth for what a smart allocator should do.
Second, a lightweight router: a small network trained to predict the optimal assignment from the video’s content features (they use a pretrained semantic encoder here). At inference time, the router runs fast and outputs a token-count schedule for the incoming video before the tokenizer even sees it.
Third, the adaptive tokenizer itself: a VQ-VAE style encoder-decoder that is conditioned on the assignment schedule. It learns to encode each temporal block into exactly the number of tokens the router prescribed. The decoder reconstructs from variable-length token sequences. The whole system is trained end-to-end after the oracle phase.
Training Phase:
  Video -> [Oracle Search] -> Optimal Assignment Labels
                                      |
                                      v
  Video + Semantic Features -> [Router Training] -> Router weights
                                      |
                                      v
  Video + Assignment -> [Tokenizer Training] -> Adaptive VQ-VAE weights

Inference Phase:
  Video -> Semantic Encoder -> Router -> Assignment Schedule
                                              |
                                              v
                               Video -> Adaptive Tokenizer -> Variable-length tokens
                                              |
                                              v
                               AR Transformer -> Generated tokens -> Decoder -> Video
Think of it like a newspaper layout editor. A fixed-length tokenizer is a junior editor who gives every story exactly the same column inches — the crossword puzzle gets the same space as the front-page investigation. EVATok is the experienced editor who looks at each story first, decides how much space it deserves, and then sends it to the typesetter with a specific column budget. The oracle search is the editor’s years of experience distilled into a rubric. The router is a fast intern who learned that rubric and can make the call in seconds. The adaptive tokenizer is the typesetter who can actually execute variable-length layouts. The AR transformer downstream is the reader — and they’re happier because the important stories got room to breathe.
Key Concepts
-
Adaptive tokenization: Normally a tokenizer maps input -> fixed-size code. Adaptive tokenization means the code size itself is a variable that depends on the input. Concretely: a 16-frame clip of someone blinking gets 32 tokens; a 16-frame clip of an explosion gets 128 tokens. The tokenizer architecture has to handle both, which requires conditioning mechanisms (like cross-attention or FiLM layers) that take the target length as an input signal.
-
Oracle assignment: You can’t directly supervise a router without knowing what the right answer is. The oracle phase solves this by brute-forcing the answer on training data — try many assignments, measure reconstruction quality for each, pick the best. This is expensive but only done once offline. The result is a labeled dataset that makes router training a standard supervised learning problem. The key insight is that “optimal assignment” is well-defined and measurable (PSNR/SSIM), so you can generate ground truth without human annotation.
-
Quality-cost tradeoff curve: For any tokenizer, you can plot reconstruction quality vs. token count. A fixed tokenizer gives you one point on this curve. An adaptive tokenizer gives you a whole curve — different videos land at different points, but the average point is better than any single fixed point could achieve. This is the core claim: adaptive allocation Pareto-dominates fixed allocation.
Framework Shift
Before (mainstream approach):        After (this paper):

  Video                                Video
    |                                    |
    v                                    v
 [Tokenizer]                      [Semantic Encoder]
    |                                    |
    v                                    v
 N tokens (fixed)                  [Router] -> Assignment Schedule
 N tokens (fixed)                    |
 N tokens (fixed)                    v
    |                            [Adaptive Tokenizer]
    v                                    |
 AR Transformer                         v
 (pays for all N*3)              n1 / n2 / n3 tokens (variable)
                                         |
                                         v
                                  AR Transformer
                                  (pays for n1+n2+n3 < N*3)
From uniform compression to content-aware allocation, the core shift is treating token budget as a resource to be scheduled, not a hyperparameter to be set once.
Expert Assessment
Problem choice: This is a real gap. The mismatch between uniform tokenization and non-uniform video complexity is obvious in hindsight, and it’s surprising it took this long to get a clean solution. The field has been so focused on scaling AR transformers that the tokenizer bottleneck got underexplored. Good timing — as video AR models get bigger, the token efficiency problem becomes more acute.
Method maturity: The three-stage pipeline (oracle -> router -> adaptive tokenizer) is clean and principled. The oracle search is the most expensive piece but it’s offline, so it’s fine in practice. The router being lightweight is important — if it were heavy, you’d eat back the savings. One thing worth scrutinizing: the oracle search space is combinatorial. How they prune it matters a lot for whether the “optimal” assignments are actually optimal or just locally good. The paper should be clearer about this.
Experimental integrity: UCF-101 class-to-video is a reasonable benchmark but it’s also a relatively easy one by 2025 standards. The comparison to LARP is the most meaningful number. The 24.4% token savings claim is specific enough to be credible, but I’d want to see the quality-cost curves plotted explicitly rather than just endpoint comparisons. The semantic encoder integration is presented as an “advanced training recipe” which feels like it’s doing more work than the paper fully accounts for — how much of the gain is the adaptive allocation vs. the better encoder?
Writing quality: The “advanced training recipe” section is where the paper gets hand-wavy. It bundles together the semantic encoder integration with the adaptive mechanism without cleanly ablating their contributions. If the authors rewrote that section as a proper ablation table — adaptive allocation alone, semantic encoder alone, both together — the paper’s actual contribution would be much clearer and more defensible.
Verdict: weak accept — the core idea is sound and the results are real, but the paper undersells its own ablations and the oracle search details need more transparency.
Takeaways
The oracle-then-distill pattern is the most transferable idea here. If you have any system where you want a fast predictor for an expensive optimization (token allocation, resolution selection, compute routing), you can generate ground truth by running the expensive version offline on training data, then train a cheap predictor to mimic it. This is essentially a form of learning-to-optimize that sidesteps the need for differentiable optimization at inference time.
The specific framing of “token budget as a schedulable resource” also transfers cleanly to image tokenization, audio tokenization, or any modality where information density varies spatially or temporally. The machinery EVATok builds — variable-length VQ-VAE conditioned on an assignment schedule — is reusable.
One concrete technique worth stealing: using a pretrained semantic encoder as the input to the router rather than raw pixels. The semantic features are more predictive of “how complex is this to reconstruct” than pixel statistics, and they’re cheap to compute with an off-the-shelf model.
论文: 2603.12267 作者: Tianwei Xiong, Jun Hao Liew, Zilong Huang, Zhijie Lin, Jiashi Feng, Xihui Liu 分类: cs.CV
缺口
自回归视频生成的流程是:先把视频压缩成离散 Token 序列,再训练 Transformer 逐步预测这些 Token。 Token 数量直接决定了重建质量的上限,也直接决定了下游生成的计算开销。
现有的视频 Tokenizer——包括近期的 LARP——对每个时间块分配固定数量的 Token,完全不管这个块里装的是什么内容。 一段背景静止的说话人脸,和一段混乱的动作场景,拿到的 Token 预算完全一样。 这是表示代价与信息量之间的根本性错配。
先前工作的隐含假设是:均匀压缩对所有视频都够用。 但事实并非如此。 静态片段被过度 Tokenize(浪费容量),动态片段被欠 Tokenize(质量损失),下游 AR 模型为每个 Token 付出完整的计算代价,不管它是否必要。
问题:每个时间块固定 Token 预算,不考虑内容复杂度
    |
    v
假设:均匀压缩对所有视频类型都足够
    |
    v
后果:静态块浪费 Token / 动态块质量受损
    |
    v
方法:估计每块最优 Token 数 -> 训练轻量路由器
      -> 训练基于可变长度分配的自适应 Tokenizer
    |
    v
证据:在 UCF-101 上比 LARP 节省 24.4%+ Token,FVD 达到 SOTA
    |
    v
结论:自适应分配在质量-代价曲线上全面优于固定分配
增量
一句话:EVATok 之前,视频 Tokenizer 把每个时间块当作同等复杂度处理;EVATok 之后,Token 预算根据内容动态路由,质量-代价权衡从一个固定点变成了一条可调的曲线。
核心机制
EVATok 由三个模块组成,按顺序训练。
第一步,Oracle 搜索:对每段训练视频,遍历各时间块可能的 Token 数分配方案,找到在给定总预算下重建质量最优的那个方案。 这一步产出一个(视频,最优分配)的标注数据集——也就是一个聪明的分配器应该做什么的”标准答案”。
第二步,轻量路由器:用一个小网络,从视频的语义特征(预训练语义编码器提取)预测最优分配方案。 推理时路由器运行很快,在 Tokenizer 处理视频之前就输出 Token 数调度表。
第三步,自适应 Tokenizer 本身:一个 VQ-VAE 风格的编解码器,以分配调度表为条件。 它学会把每个时间块编码成路由器指定数量的 Token,解码器则从可变长度的 Token 序列重建视频。 整个系统在 Oracle 阶段之后端到端训练。
训练阶段:
  视频 -> [Oracle 搜索] -> 最优分配标签
                                |
                                v
  视频 + 语义特征 -> [路由器训练] -> 路由器权重
                                |
                                v
  视频 + 分配方案 -> [Tokenizer 训练] -> 自适应 VQ-VAE 权重

推理阶段:
  视频 -> 语义编码器 -> 路由器 -> 分配调度表
                                      |
                                      v
                         视频 -> 自适应 Tokenizer -> 可变长度 Token
                                      |
                                      v
                         AR Transformer -> 生成 Token -> 解码器 -> 视频
用一个比喻来理解整个系统:把它想象成一家报纸的版面编辑。
固定长度 Tokenizer 是一个新手编辑,给每篇稿子分配完全相同的版面——填字游戏和头版调查报道占同样多的栏位。 EVATok 是一个经验丰富的老编辑,先看每篇稿子的内容,判断它值多少版面,再把具体的栏位预算交给排版师。
Oracle 搜索是老编辑多年经验提炼出的判断标准。 路由器是学会了这套标准、能在几秒内做出决策的快手助理。 自适应 Tokenizer 是能执行可变版面排版的排版师。 下游的 AR Transformer 是读者——因为重要的故事有了足够的空间,读者体验更好了。
关键概念
-
自适应 Tokenization:普通 Tokenizer 把输入映射到固定大小的编码。自适应 Tokenization 的意思是,编码的大小本身是一个依赖输入的变量。具体来说:一段 16 帧的眨眼视频得到 32 个 Token;一段 16 帧的爆炸场景得到 128 个 Token。Tokenizer 架构必须能处理两种情况,这需要以目标长度为输入信号的条件化机制(比如交叉注意力或 FiLM 层)。
-
Oracle 分配:在不知道正确答案的情况下,你没法直接监督路由器。Oracle 阶段通过在训练数据上暴力搜索来解决这个问题——尝试多种分配方案,测量每种方案的重建质量,选最好的。这一步很贵,但只需要离线做一次。结果是一个有标签的数据集,把路由器训练变成了标准的监督学习问题。关键洞察在于:“最优分配”是可定义、可测量的(PSNR/SSIM),所以可以在不需要人工标注的情况下生成真值。
-
质量-代价权衡曲线:对任何 Tokenizer,你都可以画出重建质量 vs. Token 数的曲线。固定 Tokenizer 给你曲线上的一个点。自适应 Tokenizer 给你整条曲线——不同视频落在不同的点上,但平均点比任何单一固定点都更好。这是核心主张:自适应分配在 Pareto 意义上优于固定分配。
框架转变
之前(主流方法):                    之后(本文方法):

  视频                                  视频
    |                                     |
    v                                     v
 [Tokenizer]                       [语义编码器]
    |                                     |
    v                                     v
 N 个 Token(固定)                  [路由器] -> 分配调度表
 N 个 Token(固定)                     |
 N 个 Token(固定)                     v
    |                             [自适应 Tokenizer]
    v                                     |
 AR Transformer                           v
 (为全部 N*3 个 Token 付费)       n1 / n2 / n3 个 Token(可变)
                                          |
                                          v
                                   AR Transformer
                                   (只为 n1+n2+n3 < N*3 付费)
从均匀压缩到内容感知分配,核心转变是:把 Token 预算从一个一次性设定的超参数,变成一种可以被调度的资源。
专家评审
选题眼光:这是真实的缺口。 均匀 Tokenization 与非均匀视频复杂度之间的错配,事后看来显而易见,令人惊讶的是这么久才有人给出干净的解法。 该领域一直专注于扩展 AR Transformer,Tokenizer 瓶颈被低估了。 时机不错——随着视频 AR 模型越来越大,Token 效率问题会越来越突出。
方法成熟度:三阶段流程(Oracle -> 路由器 -> 自适应 Tokenizer)清晰且有原则。 Oracle 搜索是最贵的部分,但它是离线的,实践中可以接受。 路由器轻量这一点很关键——如果路由器很重,节省的计算就会被吃回去。 有一点值得仔细审视:Oracle 搜索空间是组合爆炸的,他们如何剪枝直接决定了”最优”分配是真正最优还是局部最优。 论文在这里应该更透明。
实验诚意:UCF-101 类别到视频生成是合理的基准,但以 2025 年的标准来看也是相对容易的一个。 与 LARP 的对比是最有意义的数字。 24.4% Token 节省的说法足够具体,可信度尚可,但我希望看到质量-代价曲线被明确画出来,而不只是端点比较。 语义编码器的集成被描述为”高级训练方案”,感觉它做的贡献比论文完全交代的要多——到底有多少收益来自自适应分配,有多少来自更好的编码器?
写作功力:“高级训练方案”那一节是论文最含糊的地方。 它把语义编码器集成和自适应机制捆绑在一起,没有干净地消融各自的贡献。 如果作者把那一节重写成一张规范的消融表——单独自适应分配、单独语义编码器、两者结合——论文的实际贡献会清晰得多,也更经得起推敲。
判决:弱接收——核心思路扎实,结果是真实的,但论文对自身消融实验的呈现不够充分,Oracle 搜索的细节需要更多透明度。
要点总结
最值得迁移的思路是”Oracle 然后蒸馏”这个模式。 如果你有任何系统需要对一个昂贵的优化问题做快速预测(Token 分配、分辨率选择、计算路由),都可以用这个方法:离线在训练数据上跑昂贵版本生成真值,再训练一个廉价预测器来模仿它。 这本质上是一种”学会优化”,绕开了推理时需要可微优化的麻烦。
“Token 预算作为可调度资源”这个框架也可以直接迁移到图像 Tokenization、音频 Tokenization,或任何信息密度在空间或时间上不均匀的模态。 EVATok 构建的机制——以分配调度表为条件的可变长度 VQ-VAE——是可复用的。
一个具体可偷的技术:用预训练语义编码器的输出作为路由器的输入,而不是原始像素。 语义特征对”这段内容重建起来有多复杂”的预测能力,远强于像素统计量,而且用现成模型计算很便宜。