Paper: 2603.03111 Authors: Raad Khraishi, Iman Zafar, Katie Myles, Greig A Cowan Categories: cs.CL
The Gap
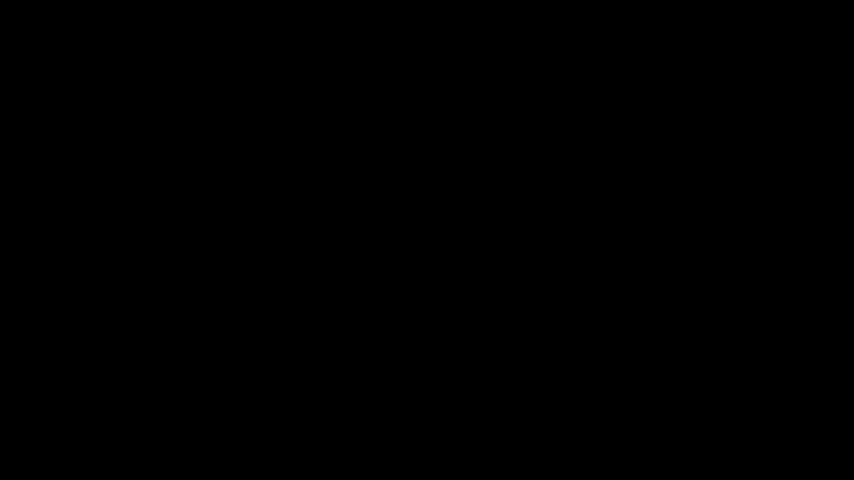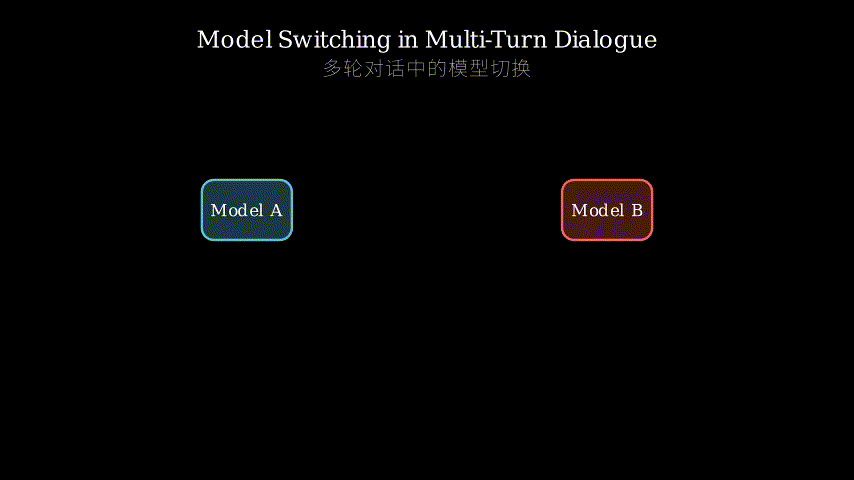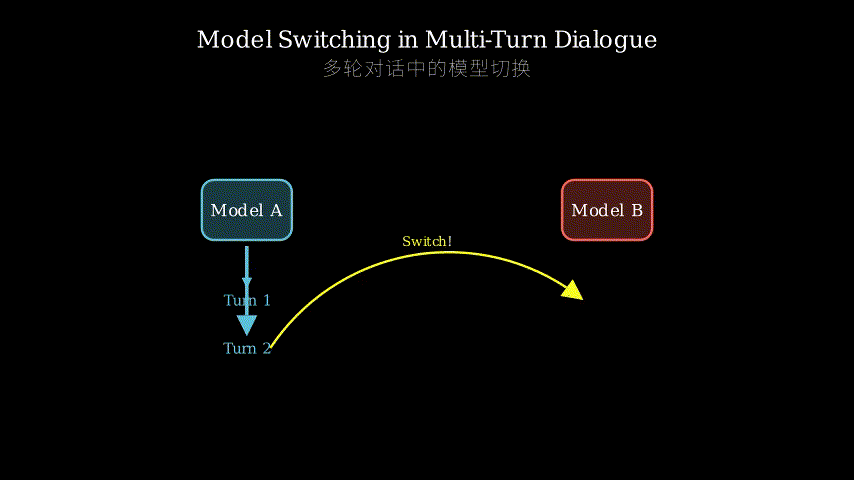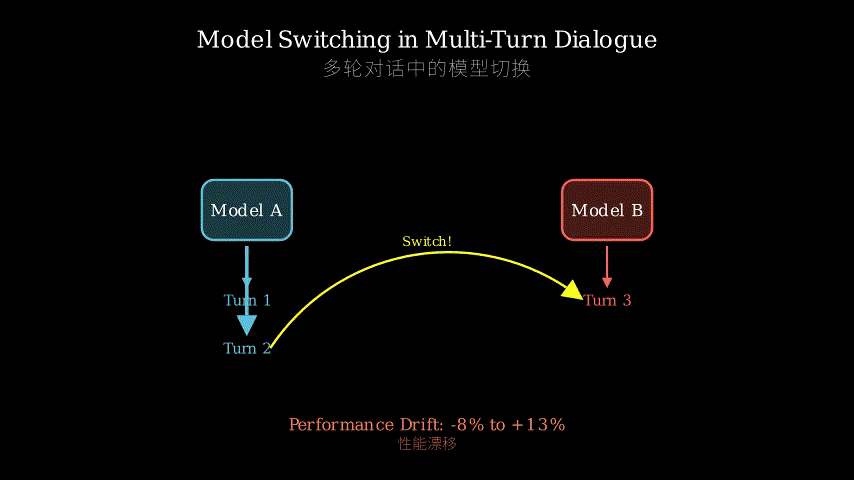
LLM benchmarks assume a single model handles the entire conversation. But production systems don’t work that way—they switch models mid-dialogue for upgrades, cost optimization, or failover. When GPT-4 starts a conversation and Claude finishes it, nobody knows what happens to performance. Prior work evaluated models in isolation or measured cross-model consistency in single-turn settings, but ignored the sequential dependency problem: later models must condition on dialogue history written by different models with different styles, assumptions, and failure modes.
Real-world problem:
  Model A writes turns 1-3  -->  Model B reads A's output
                                 and writes turn 4
                                      |
                                      v
                            Performance drift?
                                      |
                                      v
Gap: No benchmark measures this    Method: Switch-matrix
     +                                  +
     |                                  |
     v                                  v
Assumption: Context mismatch       Evidence: -8 to +13 pp swings
            matters                         on Multi-IF
                                           +/- 4 F1 on CoQA
                                      |
                                      v
                            Conclusion: Handoff robustness
                                       is a missing reliability
                                       dimension
The Increment
One sentence: Before this paper, we had no way to quantify performance drift from model handoffs in multi-turn systems; after, we have a benchmark showing handoffs can swing outcomes as much as upgrading model tiers.
Core Mechanism
The switch-matrix benchmark runs every pairwise combination of models: one model (the prefix model) generates the first N-1 turns of a conversation, then another model (the suffix model) generates the final turn and answer. The diagonal of this matrix represents no-switch baselines where the same model handles all turns. Off-diagonal cells measure handoff effects.
For each switch pair, the method computes paired episode-level differences: take the same conversation, run it with and without a handoff, and measure the delta in task performance (F1 for QA, success rate for instruction following). Bootstrap confidence intervals determine statistical significance. The key insight is treating each conversation as a paired experiment—same input, different handoff condition—which isolates the switching effect from task difficulty variance.
Switch Matrix (4 models example):

         Suffix Model -->
       +-----+-----+-----+-----+
       |  A  |  B  |  C  |  D  |
    +--+-----+-----+-----+-----+
  P |A | AA  | AB  | AC  | AD  |  <- A writes prefix,
  r |  |     |     |     |     |     B/C/D write suffix
  e +--+-----+-----+-----+-----+
  f |B | BA  | BB  | BC  | BD  |
  i |  |     |     |     |     |
  x +--+-----+-----+-----+-----+
    |C | CA  | CB  | CC  | CD  |
  M |  |     |     |     |     |
  o +--+-----+-----+-----+-----+
  d |D | DA  | DB  | DC  | DD  |
  e |  |     |     |     |     |
  l +--+-----+-----+-----+-----+

Diagonal = no-switch baseline
Off-diagonal = handoff effect
Compare: AB vs BB (how much does B degrade with A's prefix?)
Think of it like a relay race where runners have different running styles. The switch-matrix is a tournament where every runner starts some races and finishes others. The diagonal measures pure speed—Usain Bolt running the whole race himself. Off-diagonal cells measure handoff friction—what happens when Bolt’s aggressive start forces the next runner to adjust their stride mid-race? Some runners adapt seamlessly to any handoff (suffix-robust models), others stumble unless they get their own style of handoff (suffix-fragile models). The prefix influence term measures how much your running style disrupts the next runner; suffix susceptibility measures how much you stumble when handed a baton from someone else’s style.
Key Concepts
-
Context Mismatch: When Model B reads dialogue history written by Model A, it encounters text it would never generate itself—different phrasing, reasoning patterns, or implicit assumptions. Imagine reading a half-finished email draft from a colleague who writes very differently than you. You can continue it, but you’re constantly translating their style into yours, and that cognitive overhead leaks into the final output. In LLMs, this manifests as the suffix model either over-correcting (ignoring useful context) or under-correcting (blindly following a suboptimal path set by the prefix).
-
Prefix Influence vs Suffix Susceptibility: These are the two factors that determine handoff drift. Prefix influence is how much your dialogue style constrains future turns—some models write generic, adaptable context (low influence), others write highly specific context that locks in assumptions (high influence). Suffix susceptibility is how much you depend on self-generated context—some models are robust readers that extract value from any prefix (low susceptibility), others are fragile and only perform well on their own writing style (high susceptibility). The paper shows these two terms are roughly additive and explain ~70% of observed variance.
-
Paired Episode-Level Bootstrap: Standard benchmarking compares aggregate metrics across different test sets, which conflates task difficulty with model differences. This method runs the same conversation twice—once with handoff, once without—and measures the delta. By pairing episodes, you control for task difficulty and isolate the switching effect. Bootstrap resampling then builds confidence intervals over these paired deltas, giving you statistical rigor without assuming normal distributions. It’s like A/B testing where each user sees both variants in sequence, rather than splitting users into groups.
Framework Shift
Before (mainstream approach):        After (this paper):

Single model evaluation:             Switch-matrix evaluation:

  [Model A]                            [Prefix] --> [Suffix]
      |                                   |            |
      v                                   v            v
  Turn 1 --> Turn 2 --> Turn 3        Turn 1-2    Turn 3
      |                                   |            |
      v                                   +-----+------+
   Metric                                       |
                                                v
Assumption: Homogeneous                    Metric delta
            dialogue history                    |
                                                v
Misses: Real-world handoffs            Captures: Handoff drift
From isolated model evaluation to handoff-aware evaluation, the core shift is measuring performance under context mismatch rather than assuming dialogue coherence.
Expert Assessment
Problem choice: This is a real operational gap, not manufactured. The paper identifies a blind spot in how we deploy LLMs—production systems do switch models, and nobody measured the cost. It sits at the intersection of benchmarking methodology and systems reliability, which is exactly where the field needs work as LLMs move from research to production. The timing is right: model switching is common enough to matter but recent enough that no one formalized the measurement.
Method maturity: The switch-matrix is conceptually simple—almost obvious in hindsight—which is a strength. It’s not trying to be clever; it’s just systematically measuring something everyone assumed was fine. The paired bootstrap approach is solid statistics, not overkill. The decomposition into prefix influence and suffix susceptibility is elegant and interpretable. No simpler approach would capture the directional, model-specific effects they found.
Experimental integrity: Baselines are fair—they compare handoffs against no-switch controls on the same episodes. The statistical rigor (bootstrap CIs, paired tests) is appropriate. The effect sizes are large enough to matter practically (8-13 pp swings). One concern: they only test on two benchmarks (CoQA and Multi-IF), and both are relatively short conversations (few turns). Longer dialogues might amplify or dampen effects unpredictably. Also, they don’t explore mitigation strategies—just measurement—so we don’t know if the problem is fixable or fundamental.
Writing quality: The paper is clear and well-structured. The switch-matrix framing is intuitive. The decomposition analysis (Section 4) is the strongest part—showing that two terms explain 70% of variance is a clean result. The weakest section is the discussion of implications—they gesture at “handoff-aware mitigation” but don’t propose concrete solutions. Rewriting Section 5 to include at least one mitigation experiment (e.g., prompt engineering to smooth handoffs, or fine-tuning suffix models on foreign prefixes) would elevate the paper from “here’s a problem” to “here’s a problem and a path forward.”
Verdict: weak accept — Identifies a real operational gap with clean methodology, but stops at measurement without exploring solutions.
Takeaways
The switch-matrix benchmark is immediately useful for anyone running multi-model systems. You can adapt it to your own task by running prefix/suffix splits and measuring paired deltas. The prefix influence / suffix susceptibility decomposition gives you a compressed risk profile: test a new model’s susceptibility once, and you can predict its handoff behavior with existing models.
The broader lesson: operational reliability dimensions (like handoff robustness) don’t show up in single-model benchmarks. If you’re building production systems, you need to test the seams—model switches, fallbacks, retries—not just the happy path. This paper’s framing of “context mismatch” as a first-class failure mode is worth stealing for other sequential systems (e.g., multi-agent workflows, human-AI collaboration).
Concretely: if you’re doing model routing or A/B testing in production, add handoff drift to your metrics dashboard. Measure not just “how good is Model B?” but “how good is Model B after Model A’s prefix?” The paper shows this can swing outcomes by as much as a full model tier upgrade, which means ignoring it is leaving performance on the table.
论文: 2603.03111 作者: Raad Khraishi, Iman Zafar, Katie Myles, Greig A Cowan 分类: cs.CL
缺口
大模型基准测试默认单一模型处理整个对话。 但生产系统不是这样运作的——它们会在对话中途切换模型,用于升级、成本优化或故障转移。 当 GPT-4 开启对话而 Claude 结束对话时,没人知道性能会发生什么变化。 此前的工作要么孤立评估模型,要么在单轮设置中测量跨模型一致性,但忽略了序列依赖问题:后续模型必须基于不同模型编写的对话历史进行条件化,而这些模型有不同的风格、假设和失败模式。
现实问题:
  模型 A 写轮次 1-3  -->  模型 B 读取 A 的输出
                          并写轮次 4
                               |
                               v
                         性能漂移?
                               |
                               v
缺口: 无基准测量此效应      方法: 切换矩阵
     +                         +
     |                         |
     v                         v
假设: 上下文不匹配          证据: Multi-IF 上 -8 到 +13 pp
      很重要                      波动,CoQA 上 +/- 4 F1
                               |
                               v
                         结论: 切换鲁棒性是缺失的
                              可靠性维度
增量
一句话: 这篇论文之前,我们无法量化多轮系统中模型切换导致的性能漂移;之后,我们有了一个基准,显示切换可导致的结果波动相当于升级模型档次。
核心机制
切换矩阵基准运行模型的每个成对组合:一个模型(前缀模型)生成对话的前 N-1 轮,然后另一个模型(后缀模型)生成最后一轮和答案。 矩阵的对角线代表无切换基线,即同一模型处理所有轮次。 非对角线单元格测量切换效应。
对于每个切换对,该方法计算成对的情节级差异:取同一对话,分别在有切换和无切换的情况下运行,并测量任务性能的增量(问答的 F1,指令遵循的成功率)。 自举置信区间确定统计显著性。 关键洞察是将每个对话视为成对实验——相同输入,不同切换条件——这将切换效应与任务难度方差隔离开来。
切换矩阵(4 个模型示例):

         后缀模型 -->
       +-----+-----+-----+-----+
       |  A  |  B  |  C  |  D  |
    +--+-----+-----+-----+-----+
  前 |A | AA  | AB  | AC  | AD  |  <- A 写前缀,
  缀 |  |     |     |     |     |     B/C/D 写后缀
    +--+-----+-----+-----+-----+
  模 |B | BA  | BB  | BC  | BD  |
  型 |  |     |     |     |     |
    +--+-----+-----+-----+-----+
    |C | CA  | CB  | CC  | CD  |
    |  |     |     |     |     |
    +--+-----+-----+-----+-----+
    |D | DA  | DB  | DC  | DD  |
    |  |     |     |     |     |
    +--+-----+-----+-----+-----+

对角线 = 无切换基线
非对角线 = 切换效应
比较: AB vs BB (B 在 A 的前缀下退化多少?)
把它想象成接力赛,跑者有不同的跑步风格。 切换矩阵是一场锦标赛,每个跑者在某些比赛中起跑,在其他比赛中冲刺。 对角线测量纯速度——博尔特自己跑完全程。 非对角线单元格测量切换摩擦——当博尔特激进的起跑迫使下一个跑者在比赛中途调整步伐时会发生什么? 有些跑者能无缝适应任何切换(后缀鲁棒模型),其他人除非得到自己风格的切换否则会stumble(后缀脆弱模型)。 前缀影响项测量你的跑步风格对下一个跑者的干扰程度;后缀易感性测量当从别人的风格接棒时你stumble的程度。
关键概念
-
上下文不匹配: 当模型 B 读取模型 A 编写的对话历史时,它遇到的是它自己永远不会生成的文本——不同的措辞、推理模式或隐含假设。 想象一下阅读同事写的半成品邮件草稿,而这位同事的写作风格与你截然不同。 你可以继续写,但你不断地将他们的风格翻译成你的风格,这种认知开销会泄漏到最终输出中。 在大模型中,这表现为后缀模型要么过度纠正(忽略有用的上下文),要么纠正不足(盲目遵循前缀设定的次优路径)。
-
前缀影响 vs 后缀易感性: 这是决定切换漂移的两个因素。 前缀影响是你的对话风格对未来轮次的约束程度——有些模型写通用的、可适应的上下文(低影响),其他模型写高度特定的上下文,锁定假设(高影响)。 后缀易感性是你对自生成上下文的依赖程度——有些模型是鲁棒的阅读者,能从任何前缀中提取价值(低易感性),其他模型很脆弱,只在自己的写作风格上表现良好(高易感性)。 论文显示这两项大致可加,解释了约 70% 的观察方差。
-
成对情节级自举: 标准基准测试比较不同测试集上的聚合指标,这混淆了任务难度与模型差异。 此方法将同一对话运行两次——一次有切换,一次没有——并测量增量。 通过配对情节,你控制了任务难度并隔离了切换效应。 自举重采样然后在这些成对增量上构建置信区间,在不假设正态分布的情况下提供统计严谨性。 这就像 A/B 测试,每个用户依次看到两个变体,而不是将用户分成组。
框架转变
之前(主流方法):                之后(本文方法):

单模型评估:                    切换矩阵评估:

  [模型 A]                       [前缀] --> [后缀]
      |                             |            |
      v                             v            v
  轮次1 --> 轮次2 --> 轮次3      轮次1-2      轮次3
      |                             |            |
      v                             +-----+------+
   指标                                   |
                                          v
假设: 同质对话历史                    指标增量
                                          |
                                          v
遗漏: 现实世界的切换            捕获: 切换漂移
从孤立模型评估到切换感知评估,核心转变是在上下文不匹配下测量性能,而不是假设对话连贯性。
专家评审
选题眼光: 这是真实的运营缺口,不是人造的。 论文识别了我们部署大模型方式中的盲点——生产系统确实会切换模型,而没人测量成本。 它位于基准测试方法论和系统可靠性的交叉点,这正是随着大模型从研究转向生产,该领域需要工作的地方。 时机恰当:模型切换已经足够普遍以至于重要,但又足够新以至于没人正式化测量。
方法成熟度: 切换矩阵在概念上很简单——事后看几乎显而易见——这是一个优势。 它不试图耍聪明;它只是系统地测量每个人都假设没问题的东西。 成对自举方法是扎实的统计学,不是过度设计。 分解为前缀影响和后缀易感性是优雅且可解释的。 没有更简单的方法能捕获他们发现的定向、模型特定效应。
实验诚意: 基线公平——他们在相同情节上比较切换与无切换对照。 统计严谨性(自举置信区间、成对检验)是适当的。 效应大小足够大以至于在实践中重要(8-13 pp 波动)。 一个担忧:他们只在两个基准(CoQA 和 Multi-IF)上测试,而且两者都是相对较短的对话(少数轮次)。 更长的对话可能会不可预测地放大或抑制效应。 此外,他们没有探索缓解策略——只是测量——所以我们不知道问题是可修复的还是根本性的。
写作功力: 论文清晰且结构良好。 切换矩阵框架直观。 分解分析(第 4 节)是最强的部分——显示两项解释 70% 方差是一个干净的结果。 最弱的部分是对影响的讨论——他们暗示”切换感知缓解”但没有提出具体解决方案。 重写第 5 节以包含至少一个缓解实验(例如,提示工程以平滑切换,或在外来前缀上微调后缀模型)将把论文从”这是一个问题”提升到”这是一个问题和前进的道路”。
判决: 弱接收 — 用干净的方法论识别了真实的运营缺口,但止步于测量而未探索解决方案。
要点总结
切换矩阵基准对任何运行多模型系统的人都立即有用。 你可以通过运行前缀/后缀分割并测量成对增量来将其适配到你自己的任务。 前缀影响/后缀易感性分解给你一个压缩的风险概况:测试一次新模型的易感性,你就可以预测它与现有模型的切换行为。
更广泛的教训:运营可靠性维度(如切换鲁棒性)不会出现在单模型基准中。 如果你在构建生产系统,你需要测试接缝——模型切换、故障转移、重试——而不仅仅是快乐路径。 本文将”上下文不匹配”作为一流故障模式的框架值得为其他序列系统(例如,多智能体工作流、人机协作)借鉴。
具体而言:如果你在生产中进行模型路由或 A/B 测试,将切换漂移添加到你的指标仪表板。 测量的不仅是”模型 B 有多好?”而是”模型 B 在模型 A 的前缀之后有多好?” 论文显示这可以使结果波动相当于完整的模型档次升级,这意味着忽略它就是在浪费性能。