Paper: 2605.22785 Authors: Mirac Suzgun, Emily Shen, Federico Bianchi, Alexander Spangher, Thomas Icard, Daniel E. Ho, Dan Jurafsky, James Zou Categories: cs.CL
The Gap
Prior work on LLM factuality focuses on static benchmarks (TriviaQA, NaturalQuestions) or synthetic datasets. These miss a critical real-world use case: people asking chatbots about breaking news hours after it happens. We don’t know if commercial systems with proprietary retrieval pipelines can handle fresh facts across languages and regions. The gap is empirical: no systematic measurement of how these black-box systems perform on same-day news in non-English contexts.
Problem: Static benchmarks     Assumption: Retrieval-augmented
  miss temporal + regional  ->   systems handle fresh facts
       dynamics                  uniformly across languages
                                          |
                                          v
Method: 14-day live eval      Evidence: 90%+ accuracy BUT
  on same-day BBC news    ->   11-17% drop in free-response,
  across 6 languages            Hindi 10% behind, 70% errors
                                are retrieval failures
                                          |
                                          v
Conclusion: High accuracy masks systematic inequity,
  retrieval fragility, and adversarial vulnerability
The Increment
One sentence: Before this paper, we assumed commercial AI chatbots handled breaking news uniformly well; after, we know high aggregate accuracy conceals regional bias, retrieval bottlenecks, and brittleness to imperfect queries.
Core Mechanism
The evaluation pipeline has three stages. First, question generation: human annotators read same-day BBC News articles (published within 24 hours) across six regional services and write factual questions with four multiple-choice options. Each question is answerable from the article alone. Second, chatbot querying: the team sends questions to six commercial systems (Gemini 3 Flash/Pro, Grok 4, Claude 4.5 Sonnet, GPT-5, GPT-4o mini) in both multiple-choice and free-response formats, recording answers and cited sources. Third, adversarial probing: a subset of questions is modified to contain subtle false premises (e.g., changing a person’s title or event location) to test whether models detect fabrications or hallucinate answers.
BBC News (6 regions) --> Human annotators --> Questions (MC + free-response)
                                                      |
                                                      v
                         6 commercial chatbots <-- Query + record citations
                                                      |
                                                      v
                         Accuracy scoring + error taxonomy + adversarial subset
Think of this as a restaurant health inspection. The inspector (researchers) doesn’t just check the dining room (aggregate accuracy). They go into the kitchen (retrieval pipeline), examine the supply chain (which sources models cite), and test edge cases (what happens if an ingredient is spoiled—the false premise). A restaurant can have a clean dining room but fail on food sourcing or handling contaminated ingredients. Similarly, chatbots can score 90% on well-formed questions but collapse when the supply chain (retrieval) fails or the input is subtly corrupted.
Key Concepts
-
Retrieval vs. reasoning failure: When a model gets a question wrong, the error can stem from two places. A retrieval failure means the model never accessed a document containing the answer—it searched the wrong sources or the right source wasn’t indexed. A reasoning failure means the model retrieved the correct document but extracted the wrong answer from it. This paper finds 70%+ of errors are retrieval failures. Imagine a student failing an open-book exam: if they never opened the right chapter, that’s retrieval failure; if they read the right page but misunderstood it, that’s reasoning failure. The distinction matters because fixes differ—better search vs. better reading comprehension.
-
False premise detection: A question with a false premise embeds a fabricated fact (e.g., “What did President Smith say about the treaty?” when no President Smith exists). A robust system should detect the false premise and refuse to answer. This paper finds models often hallucinate answers instead, with the worst system accepting fabrications 64% of the time. The detection-accuracy paradox emerges: the model best at spotting false premises doesn’t achieve the highest adversarial accuracy because it over-abstains on legitimate questions. It’s like a security guard who’s great at spotting fake IDs but also turns away real customers—high precision, low recall.
Framework Shift
Before (mainstream approach):        After (this paper):

Benchmark: Static QA datasets        Benchmark: Live same-day news
  (TriviaQA, NaturalQuestions)         across 6 languages/regions
           |                                      |
           v                                      v
Evaluation: Aggregate accuracy       Evaluation: Accuracy + error taxonomy
  on English text                      + citation analysis + adversarial
           |                                      |
           v                                      v
Assumption: High accuracy means      Finding: High accuracy masks regional
  system works well                    inequity, retrieval dependence,
                                       adversarial brittleness
From static benchmarks to live temporal evaluation, the core shift is from measuring what models know to measuring how they fail in real-world information retrieval under time pressure and linguistic diversity.
Expert Assessment
Problem choice: Real and timely. As chatbots become news intermediaries, understanding their failure modes matters for information equity. The temporal dimension (same-day news) is underexplored and practically important. The multi-language, multi-region design is ambitious and reveals inequities that English-only evals miss.
Method maturity: Straightforward but labor-intensive. Human annotation of 2,100 questions over 14 days is solid ground truth. The adversarial subset (false premises) is clever. However, the paper doesn’t control for article difficulty or newsworthiness across regions—Hindi articles might cover different event types than US articles, confounding language effects with topic effects. The citation analysis is manual and qualitative; automated source-quality scoring would strengthen claims about retrieval bias.
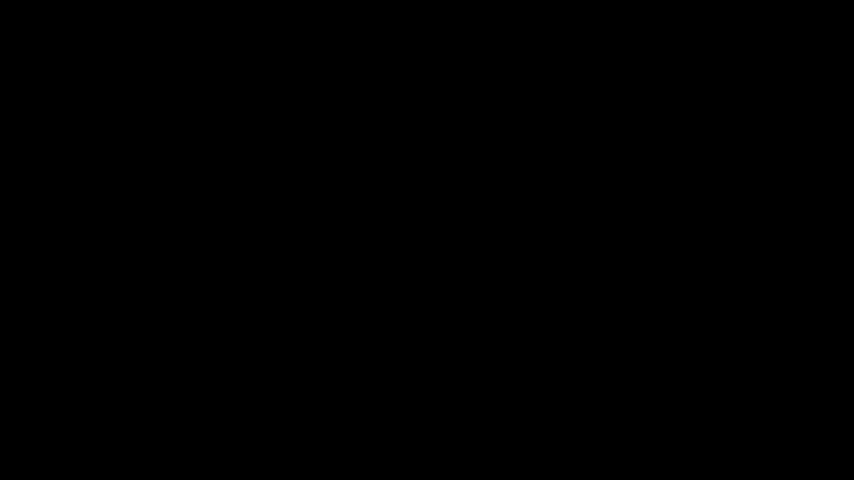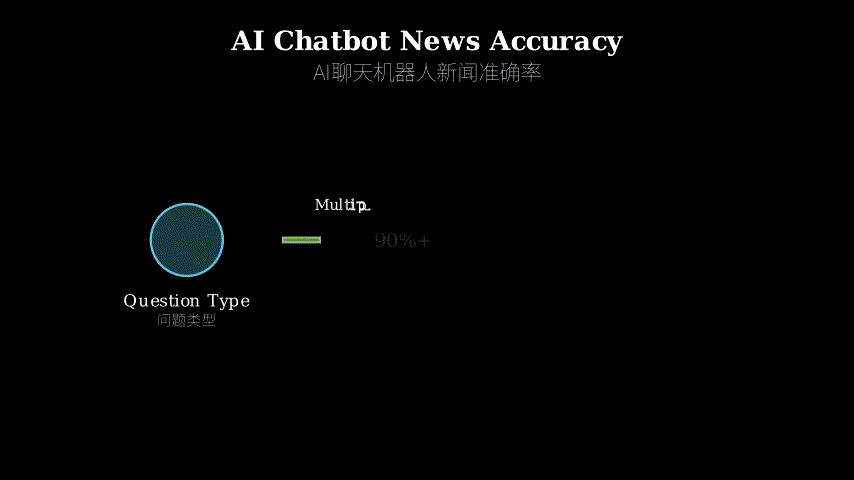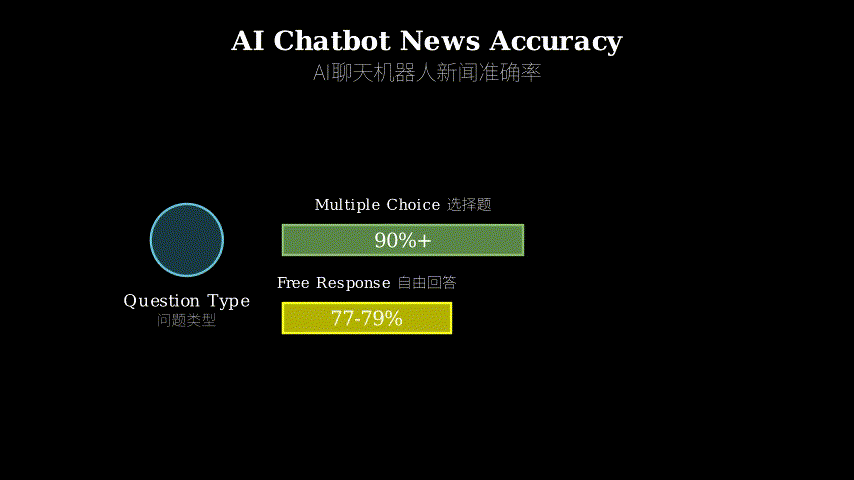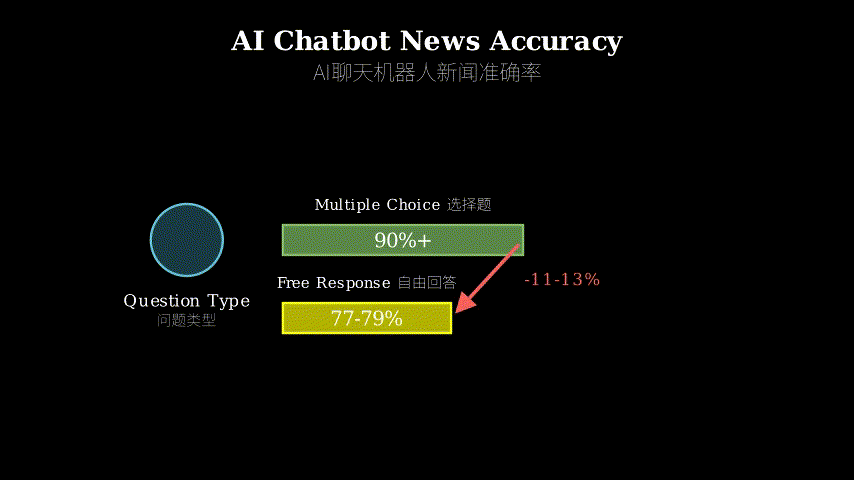
Experimental integrity: Baselines are fair (six major commercial systems, no cherry-picking). The 11-17% drop from multiple-choice to free-response is a critical finding—many evals only report MC accuracy, which inflates perceived performance. The Hindi underperformance (79% vs. 89-91%) is stark and well-documented with citation evidence. One concern: the paper doesn’t report inter-annotator agreement on question quality or answer correctness, so we can’t assess noise in the ground truth.
Writing quality: The abstract and introduction are crisp. The results section is dense with numbers but lacks visual summaries—a figure showing accuracy by language and model would clarify patterns faster than tables. The error taxonomy (retrieval vs. reasoning) is introduced late; moving it earlier would frame the results better. The discussion of the detection-accuracy paradox is buried in a subsection; it deserves prominence as a counterintuitive finding.
Verdict: weak accept — Addresses a real gap with solid empirical work, but the experimental design has confounds (topic vs. language) and the presentation could be tightened. The findings are important for practitioners deploying chatbots as news tools, even if the method isn’t groundbreaking.
Takeaways
For practitioners building retrieval-augmented systems: Don’t trust aggregate accuracy. Slice performance by language, region, and query type. This paper shows 90% overall can hide 79% on Hindi—your users in underserved languages are getting a worse product. Invest in retrieval infrastructure (indexing non-English sources, multilingual embeddings) before scaling reasoning capabilities.
For evaluators: Add free-response formats to your benchmarks. Multiple-choice inflates scores by 11-17 percentage points. Test adversarial robustness with false premises—it reveals whether your model is reasoning or pattern-matching.
For researchers: The detection-accuracy paradox (best detector ≠ best adversarial performer) suggests premise detection and answer generation are partially independent. You might need separate modules: one to validate the question, another to answer it. This is a design insight, not just an empirical observation.
论文: 2605.22785 作者: Mirac Suzgun, Emily Shen, Federico Bianchi, Alexander Spangher, Thomas Icard, Daniel E. Ho, Dan Jurafsky, James Zou 分类: cs.CL
缺口
此前关于大语言模型事实性的研究聚焦于静态基准(TriviaQA、NaturalQuestions)或合成数据集。
这些研究遗漏了一个关键的真实场景:人们在新闻发生几小时后向聊天机器人提问。
我们不知道带有专有检索管道的商业系统能否处理跨语言、跨地区的新鲜事实。
缺口是经验性的:没有系统性测量这些黑盒系统在非英语语境下处理当日新闻的表现。
问题:静态基准遗漏      假设:检索增强系统
  时间与地区动态    ->   能统一处理各语言
                         的新鲜事实
                              |
                              v
方法:14天实时评估      证据:准确率超90%,但
  BBC当日新闻跨    ->   自由回答下降11-17%,
  6种语言               印地语落后10%,70%
                        错误源于检索失败
                              |
                              v
结论:高准确率掩盖系统性不平等、
  检索脆弱性和对抗脆弱性
增量
一句话:这篇论文之前,我们以为商业 AI 聊天机器人能统一良好地处理突发新闻;之后,我们知道高总体准确率掩盖了地区偏见、检索瓶颈和对不完美查询的脆弱性。
核心机制
评估管道分三个阶段。
第一,问题生成:人类标注员阅读当日(24小时内发布)BBC 新闻文章,覆盖六个地区服务,编写带四个选项的事实性问题。
每个问题仅凭文章即可回答。
第二,聊天机器人查询:团队向六个商业系统(Gemini 3 Flash/Pro、Grok 4、Claude 4.5 Sonnet、GPT-5、GPT-4o mini)发送问题,包括选择题和自由回答格式,记录答案和引用来源。
第三,对抗探测:修改部分问题,植入微妙的虚假前提(如改变人物头衔或事件地点),测试模型能否检测伪造信息或产生幻觉答案。
BBC新闻(6地区) --> 人类标注员 --> 问题(选择题+自由回答)
                                        |
                                        v
                   6个商业聊天机器人 <-- 查询+记录引用
                                        |
                                        v
                   准确率评分 + 错误分类 + 对抗子集
把这想象成餐厅卫生检查。
检查员(研究者)不只检查餐厅大堂(总体准确率)。
他们进入厨房(检索管道),检查供应链(模型引用哪些来源),测试边缘情况(如果食材变质会怎样——虚假前提)。
餐厅可以有干净的大堂,但在食材采购或处理污染食材上不及格。
类似地,聊天机器人可以在规范问题上得90分,但当供应链(检索)失败或输入被微妙破坏时崩溃。
关键概念
- 检索失败 vs 推理失败:当模型答错问题时,错误可能源于两处。
检索失败意味着模型从未访问包含答案的文档——它搜索了错误来源或正确来源未被索引。
推理失败意味着模型检索到正确文档但提取了错误答案。
本文发现70%以上的错误是检索失败。
想象学生开卷考试不及格:如果他们从未翻开正确章节,那是检索失败;如果他们读了正确页面但理解错误,那是推理失败。
这个区分很重要,因为修复方法不同——更好的搜索 vs 更好的阅读理解。
- 虚假前提检测:带虚假前提的问题嵌入了伪造事实(如”史密斯总统对条约说了什么?“但不存在史密斯总统)。
稳健的系统应检测虚假前提并拒绝回答。
本文发现模型常常产生幻觉答案,最差系统64%的时间接受伪造信息。
检测-准确率悖论出现:最擅长发现虚假前提的模型未达到最高对抗准确率,因为它对合法问题过度弃权。
这就像保安很擅长识别假证件,但也拒绝真顾客——高精确率,低召回率。
框架转变
之前(主流方法):              之后(本文方法):

基准:静态问答数据集            基准:跨6种语言/地区
  (TriviaQA, NaturalQuestions)    的实时当日新闻
           |                              |
           v                              v
评估:英文文本的                评估:准确率 + 错误分类
  总体准确率                      + 引用分析 + 对抗测试
           |                              |
           v                              v
假设:高准确率意味着            发现:高准确率掩盖地区
  系统运作良好                    不平等、检索依赖、
                                  对抗脆弱性
从静态基准到实时时序评估,核心转变是从测量模型知道什么到测量它们在时间压力和语言多样性下的真实信息检索中如何失败。
专家评审
选题眼光:真实且及时。
随着聊天机器人成为新闻中介,理解其失败模式对信息公平很重要。
时间维度(当日新闻)探索不足且实际重要。
多语言、多地区设计有野心,揭示了纯英语评估遗漏的不平等。
方法成熟度:直接但劳动密集。
14天内人工标注2100个问题是可靠的真值。
对抗子集(虚假前提)很巧妙。
但论文未控制跨地区的文章难度或新闻价值——印地语文章可能覆盖与美国文章不同的事件类型,将语言效应与主题效应混淆。
引用分析是人工定性的;自动化来源质量评分会加强关于检索偏见的主张。
实验诚意:基线公平(六个主要商业系统,无挑选)。
从选择题到自由回答下降11-17%是关键发现——许多评估只报告选择题准确率,夸大了感知性能。
印地语表现不佳(79% vs 89-91%)很明显,引用证据充分。
一个担忧:论文未报告标注员对问题质量或答案正确性的一致性,因此我们无法评估真值中的噪声。
写作功力:摘要和引言简洁。
结果部分数字密集但缺乏视觉总结——一张按语言和模型显示准确率的图会比表格更快澄清模式。
错误分类(检索 vs 推理)引入较晚;提前会更好地框定结果。
检测-准确率悖论的讨论埋在小节中;它作为反直觉发现值得突出。
判决:弱接收 — 用扎实的经验工作解决真实缺口,但实验设计有混淆(主题 vs 语言),呈现可以收紧。
对于部署聊天机器人作为新闻工具的实践者,发现很重要,即使方法不算开创性。
要点总结
对于构建检索增强系统的实践者:不要相信总体准确率。
按语言、地区和查询类型切分性能。
本文显示90%总体可以隐藏79%的印地语——你在服务不足语言中的用户得到更差的产品。
在扩展推理能力之前投资检索基础设施(索引非英语来源、多语言嵌入)。
对于评估者:在基准中添加自由回答格式。
选择题夸大分数11-17个百分点。
用虚假前提测试对抗鲁棒性——它揭示你的模型是在推理还是模式匹配。
对于研究者:检测-准确率悖论(最佳检测器 ≠ 最佳对抗表现者)表明前提检测和答案生成部分独立。
你可能需要独立模块:一个验证问题,另一个回答问题。
这是设计洞见,不只是经验观察。