Paper: 2605.13841 Authors: Tara Bogavelli, Gabrielle Gauthier Melançon, Katrina Stankiewicz, Oluwanifemi Bamgbose, Fanny Riols, Hoang H. Nguyen, Raghav Mehndiratta, Lindsay Devon Brin, Joseph Marinier, Hari Subramani Categories: cs.SD, cs.AI, cs.CL, cs.LG
The Gap
Voice agents are everywhere now—booking appointments, handling customer service, managing enterprise workflows. But existing benchmarks test them in pieces: ASR accuracy here, NLU there, maybe some task completion metrics. None capture what actually breaks in production: the user simulator says something weird, the agent interrupts mid-sentence, background noise tanks performance, or the conversation derails after turn three.
Prior work either uses static test sets (no dynamic conversation flow), text-only evaluation (missing audio-specific failures), or single-metric scoring (can’t distinguish “got the task done” from “pleasant to talk to”). The gap: no unified framework that both generates realistic multi-turn audio conversations and measures the full spectrum of voice-specific failure modes across different agent architectures.
Problem: Voice agents fail in production in ways benchmarks don't catch
   |
   v
Assumption: Need both realistic simulation AND comprehensive measurement
   |
   v
Method: Bot-to-bot audio conversations + dual metrics (accuracy + experience)
   |
   v
Evidence: 12 systems tested, none exceed 0.5 on both metrics simultaneously
   |
   v
Conclusion: Current voice agents have fundamental gaps in reliability
The Increment
One sentence: Before EVA-Bench, you couldn’t compare a cascaded ASR→NLU→TTS pipeline against an end-to-end neural voice model on the same realistic conversation scenarios—now you can, with metrics that separate “did it work” from “was it usable.”
Core Mechanism
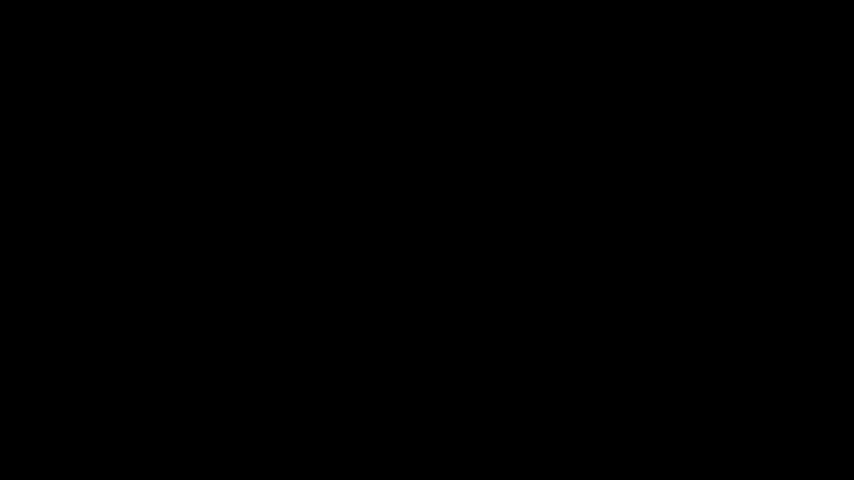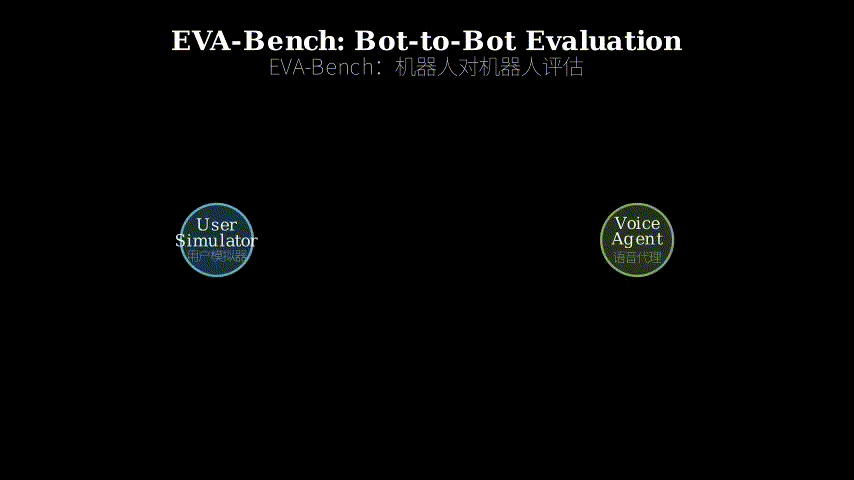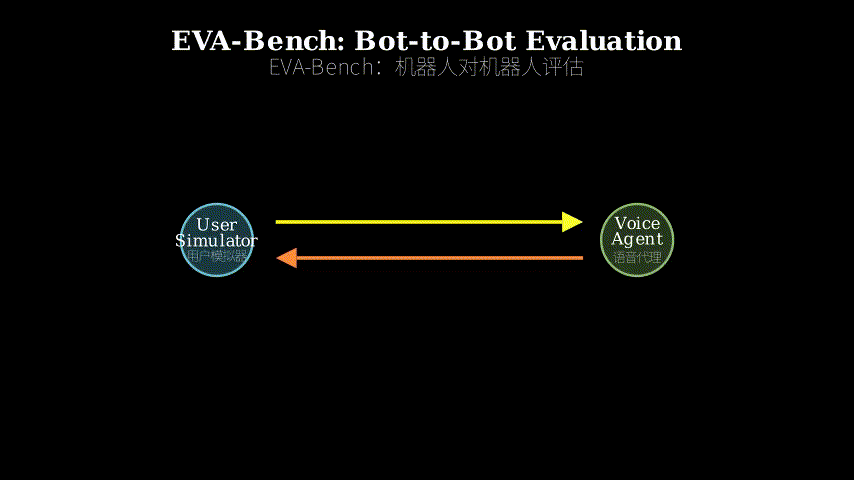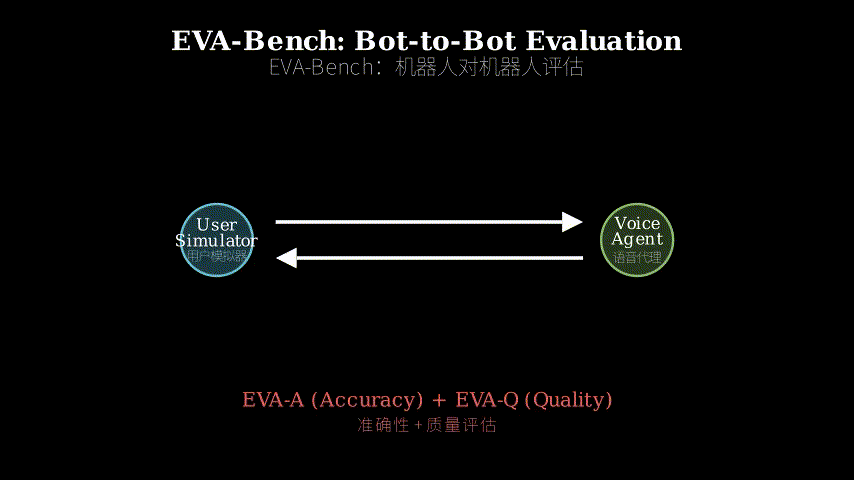
EVA-Bench has two halves: simulation and measurement. On the simulation side, it runs bot-to-bot conversations where a user simulator (itself a voice agent) talks to the agent under test. The simulator follows a scenario script but adapts dynamically—if the agent asks for clarification, the simulator responds naturally. Crucially, EVA-Bench validates each simulated conversation: if the simulator makes an error (misunderstands the agent, goes off-script), the framework detects it and regenerates that conversation before scoring.
On the measurement side, EVA-Bench computes two composite metrics. EVA-A (Accuracy) combines task completion (did the agent achieve the goal?), faithfulness (did it follow instructions without hallucinating?), and speech fidelity (was the audio intelligible?). EVA-X (Experience) combines conversation progression (did the dialogue flow naturally?), spoken conciseness (was the agent verbose?), and turn-taking timing (did it interrupt or leave awkward pauses?). Each metric is architecture-agnostic, so you can directly compare a traditional cascaded system against a modern end-to-end model.
Simulation Loop:
  Scenario Script --> User Simulator (voice agent)
                           |
                           v (audio)
                    Agent Under Test
                           |
                           v (audio)
                    User Simulator responds
                           |
                           v
                    Validation Check
                      /          \
                 Error?          OK?
                   |              |
              Regenerate      Continue
                   |              |
                   +------<-------+
                           |
                           v
                    Conversation Complete --> Scoring

Measurement:
  Conversation Transcript + Audio
           |
           +---> EVA-A: Task + Faithfulness + Speech Fidelity
           |
           +---> EVA-X: Progression + Conciseness + Turn-timing
Think of EVA-Bench as a driving test for voice agents. The simulation is the test course: you don’t just check if the car can turn left (static test), you put it through real traffic scenarios with other drivers (bot-to-bot). The validation is the examiner watching for cheating—if the other “driver” (user simulator) does something illegal, you restart that scenario. The dual metrics are like separating “did you reach the destination” (EVA-A) from “would I feel safe as your passenger” (EVA-X). A car might technically complete the route but terrify everyone with sudden braking and lane swerving. Similarly, a voice agent might finish the task but be so awkward to talk to that users hang up.
Key Concepts
-
Bot-to-bot simulation with validation: Instead of humans manually testing agents or using pre-recorded audio, EVA-Bench has two voice agents talk to each other. One plays the user (following a scenario), the other is the system being tested. The key innovation is automatic validation: after each conversation, EVA-Bench checks if the user simulator stayed on-script and responded appropriately. If the simulator made a mistake (e.g., misheard the agent and gave a nonsensical response), that conversation is flagged and regenerated. This ensures you’re scoring the agent’s performance, not the simulator’s errors. Concrete example: if the agent asks “What’s your account number?” and the simulator randomly says “I like pizza,” validation catches this and reruns the scenario.
-
Architecture-agnostic composite metrics: Voice agents come in three flavors: cascaded (separate ASR, NLU, dialogue manager, TTS), end-to-end (single neural model from audio to audio), and hybrid (mix of both). Prior benchmarks often favor one architecture because metrics are tied to intermediate representations (e.g., word error rate assumes you have ASR output). EVA-Bench’s metrics work on any architecture because they only look at the final audio conversation and task outcome. EVA-A checks if the job got done correctly, EVA-X checks if the conversation felt natural—both measurable from audio alone, no internal access needed.
-
Pass@1, pass@k, pass^k for reliability: A voice agent might succeed on a task 80% of the time, but which 80%? Pass@1 is the success rate on first try (what users experience). Pass@k is the best result across k attempts (peak capability). Pass^k is the worst result across k attempts (reliable capability). The gap between pass@k and pass^k reveals brittleness: a large gap means the agent is inconsistent. EVA-Bench found a median gap of 0.44 on EVA-A, meaning agents that sometimes work well often fail catastrophically on the same scenario with slight variations.
Framework Shift
Before (mainstream approach):        After (this paper):

Static Test Set                      Dynamic Simulation
  +-------------+                      User Simulator
  | Pre-recorded|                           |
  | audio files | ---> Agent               (adapts)
  +-------------+                            |
                                        Agent Under Test
Single Metric                                |
  Task Success: 85%                     (validates)
  (but was it usable?)                       |
                                        Dual Metrics
                                        EVA-A: 0.42
                                        EVA-X: 0.38
Architecture-Specific                  (both matter)
  ASR WER: 12%
  (can't compare end-to-end)         Architecture-Agnostic
                                        (compare any system)
From static audio clips to adaptive conversations, the core shift is treating voice agents as interactive systems rather than pipelines to be tested in isolation.
Expert Assessment
Problem choice: Real gap. Voice agents are deployed at scale (customer service, healthcare, enterprise), but evaluation lags behind. Existing benchmarks like LibriSpeech test ASR, DSTC tests dialogue, but nothing bridges the full audio-to-audio loop with realistic multi-turn dynamics. The authors correctly identify that production failures (interruptions, noise robustness, conversational awkwardness) aren’t captured by component-level metrics.
Method maturity: Solid engineering, not a novel algorithmic insight. The bot-to-bot simulation idea isn’t new (used in game AI, chatbot testing), but applying it to voice with automatic validation is practical and well-executed. The dual-metric design (accuracy vs experience) is sensible—separates “works” from “usable.” The pass@k / pass^k distinction is borrowed from code generation benchmarks but fits well here. No major methodological risks, though the validation mechanism’s accuracy depends on the quality of the user simulator itself (potential circularity).
Experimental integrity: Strong. 12 systems across all three architectures, 213 scenarios, controlled perturbations (accent, noise). The finding that no system exceeds 0.5 on both metrics is credible—voice agents are genuinely hard. The pass@k - pass^k gap of 0.44 is a red flag for the field, not the paper. Baselines seem fair, though I’d want to see ablations on the validation mechanism (how often does it incorrectly flag good conversations?). The accent/noise perturbation results (mean drop up to 0.314) are expected but quantified rigorously.
Writing quality: Clear and well-structured. The abstract front-loads the contribution. The method section could be tighter—some redundancy between simulation and validation explanations. The results section is dense with numbers; a summary table comparing systems head-to-head would help. The related work section is thorough but could better position EVA-Bench relative to recent end-to-end voice model papers (e.g., AudioLM, SpeechGPT).
Verdict: strong accept — Fills a real evaluation gap with a practical, reproducible framework and reveals significant reliability issues in current voice agents.
Takeaways
Practitioners can steal the dual-metric framing: separate “did it work” from “was it pleasant.” This applies beyond voice—chatbots, code assistants, any interactive AI. The pass@k / pass^k gap is a useful diagnostic for brittleness in any stochastic system. If your model’s best-of-5 performance is way better than worst-of-5, you have a reliability problem, not just an accuracy problem.
The bot-to-bot simulation with validation is transferable: if you’re testing any conversational AI, having a simulated user that can detect its own errors (and regenerate bad interactions) prevents garbage data from polluting your metrics. The validation mechanism is the key—without it, you’re scoring a mix of your agent’s failures and your simulator’s failures.
For voice-specific work: the finding that no system balances accuracy and experience suggests current architectures make a tradeoff. Cascaded systems might be more accurate but clunky (slow turn-taking), end-to-end systems might be smoother but less reliable. If you’re building a voice agent, measure both dimensions early—optimizing for task success alone will produce something users hate talking to.
论文: 2605.13841 作者: Tara Bogavelli, Gabrielle Gauthier Melançon, Katrina Stankiewicz, Oluwanifemi Bamgbose, Fanny Riols, Hoang H. Nguyen, Raghav Mehndiratta, Lindsay Devon Brin, Joseph Marinier, Hari Subramani 分类: cs.SD, cs.AI, cs.CL, cs.LG
缺口
语音代理现在无处不在——预约、客服、企业流程管理。
但现有基准测试都是分段测:
这里测 ASR 准确率,那里测 NLU,可能还有些任务完成度指标。
没有一个能捕捉生产环境中真正出问题的地方:
用户模拟器说了奇怪的话,代理说到一半就打断,背景噪音让性能崩溃,或者对话进行到第三轮就跑偏了。
之前的工作要么用静态测试集(没有动态对话流),要么只测文本(漏掉音频特有的失败模式),要么单一指标打分(分不清”任务完成了”和”聊得舒服”)。
缺口在于:
没有统一框架既能生成真实的多轮音频对话,又能测量不同代理架构下语音特有失败模式的全谱。
问题:语音代理在生产中的失败方式,基准测不出来
   |
   v
假设:需要真实模拟 + 全面测量
   |
   v
方法:机器人对机器人音频对话 + 双指标(准确性 + 体验)
   |
   v
证据:测了12个系统,没有一个在两个指标上同时超过0.5
   |
   v
结论:当前语音代理在可靠性上有根本性缺口
增量
一句话:
EVA-Bench 之前,你没法在同样的真实对话场景下比较级联式 ASR→NLU→TTS 管道和端到端神经语音模型——现在可以了,而且指标能区分”能用”和”好用”。
核心机制
EVA-Bench 分两半:
模拟和测量。
模拟这边,它跑机器人对机器人的对话,一个用户模拟器(本身也是语音代理)和被测代理对话。
模拟器遵循场景脚本但动态适应——如果代理要求澄清,模拟器自然回应。
关键是 EVA-Bench 会验证每段模拟对话:
如果模拟器出错(误解代理、偏离脚本),框架检测到后会在打分前重新生成那段对话。
测量这边,EVA-Bench 计算两个复合指标。
EVA-A(准确性)结合任务完成度(代理达成目标了吗?
)、忠实度(有没有遵循指令、没有幻觉?
)、语音保真度(音频清晰吗?
)。
EVA-X(体验)结合对话推进(对话流畅吗?
)、口语简洁性(代理啰嗦吗?
)、轮次时机(有没有打断或留下尴尬停顿?
)。
每个指标都与架构无关,所以你能直接比较传统级联系统和现代端到端模型。
模拟循环:
  场景脚本 --> 用户模拟器(语音代理)
                    |
                    v(音频)
              被测代理
                    |
                    v(音频)
              用户模拟器回应
                    |
                    v
              验证检查
                /        \
           出错?        正常?
             |            |
          重新生成      继续
             |            |
             +-----<------+
                    |
                    v
              对话完成 --> 打分

测量:
  对话记录 + 音频
        |
        +---> EVA-A:任务 + 忠实度 + 语音保真度
        |
        +---> EVA-X:推进 + 简洁性 + 轮次时机
把 EVA-Bench 想象成语音代理的驾照考试。
模拟是考试路线:
你不只是检查车能不能左转(静态测试),而是让它在真实交通场景中和其他司机互动(机器人对机器人)。
验证是考官盯着防作弊——如果另一个”司机”(用户模拟器)做了违规动作,你重考那个场景。
双指标就像分开”你到目的地了吗”(EVA-A)和”我坐你车上感觉安全吗”(EVA-X)。
一辆车可能技术上完成了路线,但急刹车和乱变道吓坏所有人。
同样,语音代理可能完成任务,但聊起来太别扭,用户直接挂断。
关键概念
- 带验证的机器人对机器人模拟:
EVA-Bench 不让人工手动测试代理,也不用预录音频,而是让两个语音代理互相对话。
一个扮演用户(遵循场景),另一个是被测系统。
关键创新是自动验证:
每段对话后,EVA-Bench 检查用户模拟器有没有按脚本走、回应是否恰当。
如果模拟器出错(比如听错代理的话,给了无厘头回应),那段对话被标记并重新生成。
这确保你打分的是代理的表现,不是模拟器的错误。
具体例子:
如果代理问”您的账号是多少?
“,模拟器随机说”我喜欢披萨”,验证会捕捉到这个并重跑场景。
- 架构无关的复合指标:
语音代理有三种形态:
级联式(独立的 ASR、NLU、对话管理器、TTS),端到端(从音频到音频的单一神经模型),混合式(两者结合)。
之前的基准往往偏向某种架构,因为指标绑定中间表示(比如词错误率假设你有 ASR 输出)。
EVA-Bench 的指标适用于任何架构,因为它们只看最终的音频对话和任务结果。
EVA-A 检查工作有没有正确完成,EVA-X 检查对话感觉自然不自然——两者都能从音频单独测量,不需要内部访问。
- Pass@1、pass@k、pass^k 衡量可靠性:
语音代理可能在任务上有 80% 成功率,但是哪 80%?
Pass@1 是首次尝试的成功率(用户体验到的)。
Pass@k 是 k 次尝试中的最佳结果(峰值能力)。
Pass^k 是 k 次尝试中的最差结果(可靠能力)。
Pass@k 和 pass^k 之间的差距揭示脆弱性:
差距大意味着代理不稳定。
EVA-Bench 发现 EVA-A 上的中位数差距是 0.44,意思是有时表现好的代理,在同一场景的轻微变化下经常灾难性失败。
框架转变
之前(主流方法):                之后(本文方法):

静态测试集                        动态模拟
  +-------------+                   用户模拟器
  | 预录音频    |                        |
  | 文件        | ---> 代理            (适应)
  +-------------+                        |
                                    被测代理
单一指标                                 |
  任务成功率:85%                    (验证)
  (但好用吗?)                         |
                                    双指标
                                    EVA-A:0.42
                                    EVA-X:0.38
架构特定                            (两者都重要)
  ASR WER:12%
  (没法比较端到端)                架构无关
                                    (比较任何系统)
从静态音频片段到自适应对话,核心转变是把语音代理当作交互系统,而不是孤立测试的管道。
专家评审
选题眼光:
真缺口。
语音代理大规模部署了(客服、医疗、企业),但评估落后。
现有基准比如 LibriSpeech 测 ASR,DSTC 测对话,但没有一个打通完整的音频到音频循环,带真实多轮动态。
作者正确识别出生产失败(打断、噪音鲁棒性、对话尴尬)没被组件级指标捕捉到。
方法成熟度:
扎实的工程,不是新颖的算法洞见。
机器人对机器人模拟的想法不新(游戏 AI、聊天机器人测试用过),但应用到语音并加上自动验证是实用且执行良好的。
双指标设计(准确性 vs 体验)合理——分开”能用”和”好用”。
Pass@k / pass^k 区分是从代码生成基准借来的,但在这里很合适。
没有大的方法论风险,不过验证机制的准确性依赖用户模拟器本身的质量(潜在循环性)。
实验诚意:
强。
12 个系统覆盖三种架构,213 个场景,受控扰动(口音、噪音)。
发现没有系统在两个指标上同时超过 0.5 是可信的——语音代理确实难。
Pass@k - pass^k 差距 0.44 是给领域的红旗,不是给论文的。
基线看起来公平,不过我想看验证机制的消融(它多久会错误标记好对话?
)。
口音/噪音扰动结果(平均下降最多 0.314)是预期的,但量化严谨。
写作功力:
清晰且结构良好。
摘要前置贡献。
方法部分可以更紧凑——模拟和验证解释之间有些冗余。
结果部分数字密集;
一个系统正面对比的汇总表会有帮助。
相关工作部分详尽,但可以更好地定位 EVA-Bench 相对于近期端到端语音模型论文(比如 AudioLM、SpeechGPT)的位置。
判决:
强接收 — 用实用、可复现的框架填补了真实的评估缺口,并揭示了当前语音代理的重大可靠性问题。
要点总结
实践者能偷走双指标框架:
分开”能用”和”好用”。
这适用于语音之外——聊天机器人、代码助手、任何交互式 AI。
Pass@k / pass^k 差距是任何随机系统脆弱性的有用诊断。
如果你的模型”五次中最好”的表现远好于”五次中最差”,你有可靠性问题,不只是准确性问题。
带验证的机器人对机器人模拟可迁移:
如果你在测试任何对话 AI,有一个能检测自身错误的模拟用户(并重新生成坏交互)能防止垃圾数据污染你的指标。
验证机制是关键——没有它,你打分的是你的代理失败和你的模拟器失败的混合。
对于语音特定工作:
发现没有系统平衡准确性和体验,说明当前架构在做权衡。
级联系统可能更准确但笨拙(轮次慢),端到端系统可能更流畅但不太可靠。
如果你在构建语音代理,早期就测量两个维度——只优化任务成功会产出用户讨厌对话的东西。