Paper: 2605.18746 Authors: Yining Hong, Jiageng Liu, Han Yin, Manling Li, Leonidas Guibas, Li Fei-Fei, Jiajun Wu, Yejin Choi Categories: cs.CV, cs.AI, cs.CL, cs.LG, cs.RO
The Gap
Existing spatial reasoning benchmarks assume oracle observations—agents receive perfect views and reason about what they see. This mirrors how we evaluate vision models: feed them images, measure accuracy. But real spatial intelligence isn’t passive perception. A child learning object permanence doesn’t stare at a static scene; they peek behind the couch, shake the box, open the drawer. The observation itself is the outcome of action.
Prior work (Embodied Question Answering, Vision-and-Language Navigation) gives agents mobility but still treats perception as given. The agent moves, but the task design doesn’t require reasoning about what to look at versus what the view reveals. The gap: no benchmark tests whether models can close the perception-action loop—decide what abilities to deploy (look, walk, grab), sequence them strategically, and accumulate evidence through exploration rather than hoping the right view appears.
Problem: Spatial tasks need active evidence gathering
   |
   v
Assumption: Oracle views hide action-selection competence
   |
   v
Method: ESI-Bench forces agents to choose actions that yield informative observations
   |
   v
Evidence: Active exploration >> passive multi-view; failures trace to poor action choice
   |
   v
Conclusion: Action blindness, not perception weakness, bottlenecks spatial intelligence
The Increment
One sentence: Before—spatial reasoning assumed perfect observations; after—spatial reasoning requires learning what to observe.
Core Mechanism
ESI-Bench is built on OmniGibson, a physics simulator supporting perception, locomotion, and manipulation. It spans 10 task categories grounded in Spelke’s core knowledge systems: object permanence (tracking occluded objects), solidity (understanding physical constraints), containment (reasoning about what’s inside containers), support (predicting stability), and shape constancy (recognizing objects across viewpoints). Each task withholds critical information from the initial view—an object is behind a wall, inside a closed drawer, or only identifiable from a specific angle.
The agent receives no privileged state. It must decide: Should I move closer? Open this container? Rotate the object? Each action costs tokens (simulating real-world effort) and yields a new observation. The benchmark measures not just final accuracy but the efficiency of the exploration strategy—how many actions to reach a confident, correct answer.
Experiments compare three regimes: (1) single passive view, (2) random multi-view (agent sees N random perspectives), (3) active exploration (agent chooses actions). State-of-the-art MLLMs (GPT-4V, Gemini, Claude) are tested with and without explicit 3D grounding (point clouds, depth maps).
Task Setup:
  Initial View --> [Occluded / Ambiguous Scene]
       |
       v
  Agent Decision Tree:
    - Perceive (zoom, rotate view)
    - Locomote (move to new position)
    - Manipulate (open, lift, shake)
       |
       v
  New Observation --> Update Belief --> Repeat or Answer
       |
       v
  Evaluation: Accuracy + Action Efficiency
Think of ESI-Bench as a detective game where the crime scene is interactive. A passive detective gets a single photo and guesses. A random detective gets 20 photos from arbitrary angles—more data, but no strategy. An active detective walks the scene, opens drawers where evidence might hide, checks sightlines, and tests hypotheses. The crime (task) is the same, but the investigation method (observation strategy) determines success. ESI-Bench is the crime scene; the agent is the detective; actions are investigative moves. The benchmark doesn’t test “Can you see the clue?” but “Do you know where to look for it?”
Key Concepts
-
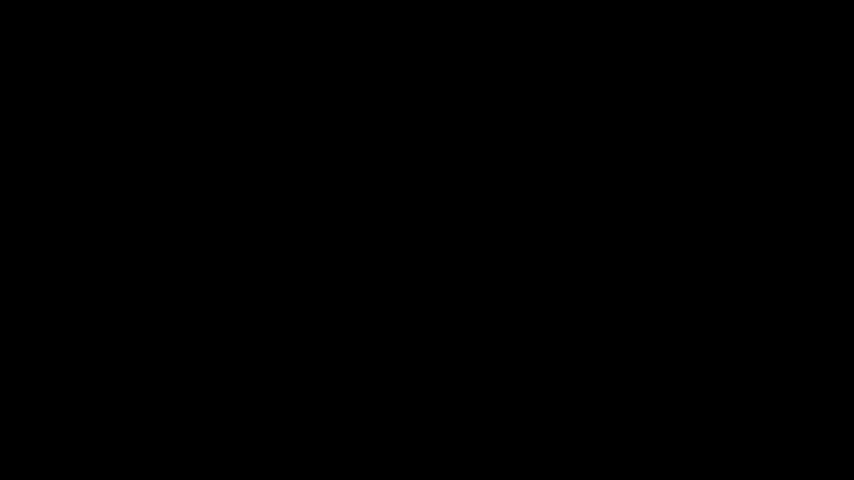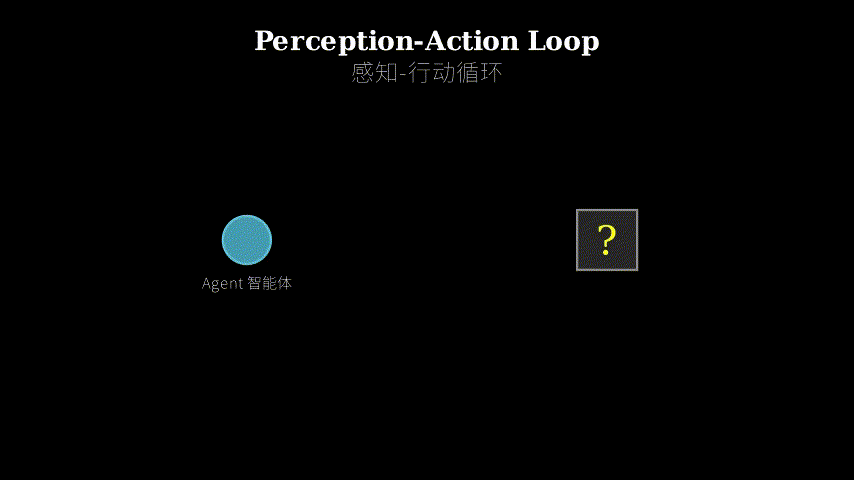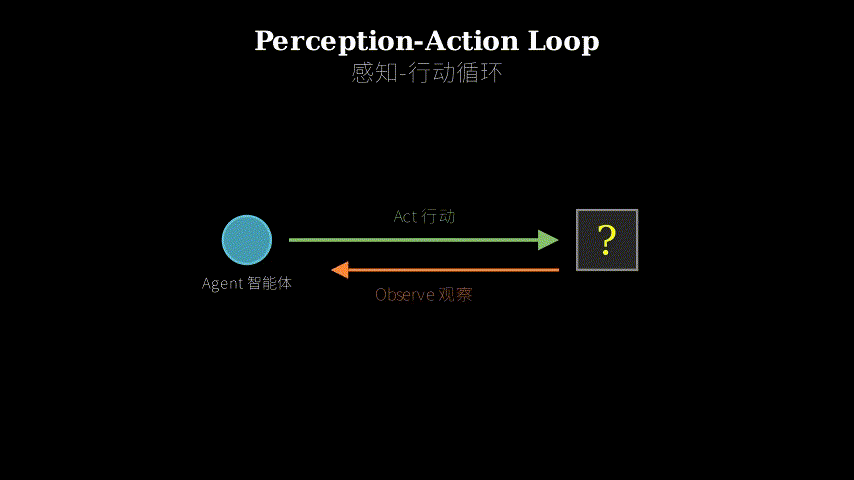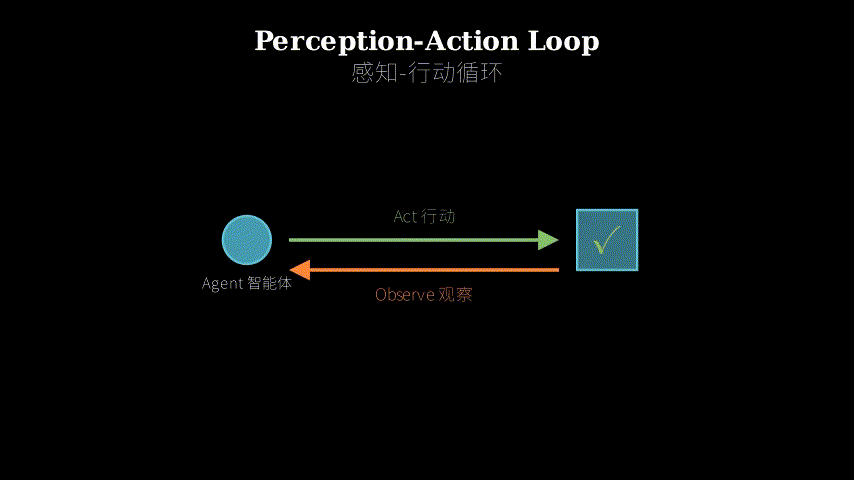
Perception-Action Loop: In passive vision, perception is input and reasoning is output. In embodied intelligence, perception and action form a cycle: you act to change what you perceive, then perceive to decide the next action. A robot determining if a box is empty can’t solve this from a photo—it must lift the box (action) to feel its weight (perception), or open it (action) to see inside (perception). The loop closes when action choices are informed by what you need to perceive, not just what you currently see. ESI-Bench operationalizes this by making task success depend on choosing actions that reveal hidden information, not just processing visible information better.
-
Action Blindness: Models fail not because they can’t recognize objects or estimate depth, but because they can’t map uncertainty to action. When a model sees a closed drawer and needs to know what’s inside, action blindness manifests as: (a) not recognizing the drawer is closed, (b) recognizing it but not choosing to open it, or (c) opening it but not understanding that the new view resolves the uncertainty. It’s a metacognitive failure—the model doesn’t know what it doesn’t know, so it can’t seek the right evidence. Human studies in the paper show people naturally seek falsifying viewpoints (“Let me check the other side to be sure”). Models commit early with high confidence regardless of evidence quality.
-
Emergent Spatial Strategies: Without explicit instructions, agents discover task-specific exploration patterns. For object permanence tasks, successful agents learn to circle occluders. For containment tasks, they learn to manipulate containers before answering. These strategies aren’t programmed—they emerge from the reward structure (correct answers after fewer actions score higher). The emergence is fragile: random multi-view often degrades performance because irrelevant views add noise, proving that *more observation ≠ better reasoning without strategic selection.
Framework Shift
Before (mainstream approach):        After (this paper):

  [Image] --> [Model] --> [Answer]     [Scene] --> [Agent]
                                              |
                                              v
                                        Choose Action
                                              |
                                              v
                                        [New View] --> Update
                                              |
                                              v
                                        Repeat or Answer

  Perception = Input                   Perception = Outcome of Action
  Task: Reason about what you see      Task: Decide what to see
From oracle observations to earned observations, the core shift is reframing the observer as an actor.
Expert Assessment
Problem choice: This is a real gap. Embodied AI research has focused on navigation and manipulation as separate modules, but the integration—using action to resolve perceptual uncertainty—remains underexplored. The problem sits at the intersection of vision, robotics, and reasoning, which makes it both important and difficult to benchmark cleanly. The grounding in Spelke’s core knowledge systems is intellectually honest; these aren’t arbitrary tasks but foundational spatial competencies.
Method maturity: The benchmark design is sound. Using OmniGibson provides physical realism without the cost of real-world data collection. The action space (perceive/locomote/manipulate) is minimal but sufficient to test the hypothesis. The comparison between passive, random multi-view, and active exploration is the right ablation. However, the paper leans heavily on prompting existing MLLMs rather than training embodied agents from scratch, which limits the conclusions about what’s learnable versus what’s a prompting artifact.
Experimental integrity: Baselines are fair. The finding that random multi-view often hurts performance is surprising and well-documented. The human studies add credibility—showing humans naturally seek falsifying evidence while models don’t is a clean result. One concern: the 3D grounding experiments show imperfect 3D representations harm performance, but the paper doesn’t deeply investigate *why. Is it noise in the point clouds? Misalignment between 2D and 3D? This feels like a missed opportunity for a follow-up ablation.
Writing quality: The abstract and introduction are strong. The related work section is thorough but dense—cutting 20% would improve flow. The results section buries the lead: the action blindness finding (Section 4.3) should come earlier because it’s the paper’s most important contribution. The human study (Section 4.4) is well-executed but feels tacked on; integrating it into the main narrative would strengthen the argument.
Verdict: Strong accept—this benchmark will be widely used, and the action blindness insight reframes how we should evaluate spatial reasoning.
Takeaways
For practitioners building embodied agents: Don’t assume more views = better reasoning. Test whether your agent can *choose informative actions, not just process more data. If your agent explores randomly, you’re likely adding noise.
For vision researchers: Spatial reasoning benchmarks that provide oracle views are measuring the wrong thing. If your model scores 90% on a static spatial reasoning dataset, that doesn’t predict embodied performance—action selection is a separate competence.
For prompt engineers: The paper shows that prompting MLLMs to “explore actively” yields emergent strategies without explicit instructions. This suggests that task framing (emphasizing uncertainty and evidence-gathering) can unlock latent capabilities in foundation models.
Transferable technique: The “action cost” mechanism (each action consumes tokens, forcing efficiency) is a simple way to prevent brute-force exploration in any interactive benchmark. Steal this for your own evaluation setups.
论文: 2605.18746 作者: Yining Hong, Jiageng Liu, Han Yin, Manling Li, Leonidas Guibas, Li Fei-Fei, Jiajun Wu, Yejin Choi 分类: cs.CV, cs.AI, cs.CL, cs.LG, cs.RO
缺口
现有的空间推理基准假设观测是完美的——智能体收到完美视角,然后推理它们看到的东西。
这反映了我们评估视觉模型的方式:喂给它们图像,测量准确率。
但真正的空间智能不是被动感知。
学习物体永久性的孩子不会盯着静态场景;他们会探头看沙发后面,摇晃盒子,打开抽屉。
观测本身就是行动的结果。
先前工作(具身问答、视觉-语言导航)给了智能体移动能力,但仍然把感知当作既定输入。
智能体会移动,但任务设计不要求推理”该看什么”与”视角揭示了什么”之间的区别。
缺口在于:没有基准测试模型能否闭合感知-行动循环——决定部署什么能力(看、走、抓),战略性地排序它们,通过探索积累证据而非期待正确视角自动出现。
问题:空间任务需要主动收集证据
   |
   v
假设:完美视角掩盖了行动选择能力
   |
   v
方法:ESI-Bench 强制智能体选择能产生信息性观测的行动
   |
   v
证据:主动探索 >> 被动多视角;失败源于糟糕的行动选择
   |
   v
结论:行动盲目性,而非感知弱点,是空间智能的瓶颈
增量
一句话:之前——空间推理假设完美观测;之后——空间推理需要学习观测什么。
核心机制
ESI-Bench 构建在 OmniGibson 上,这是一个支持感知、移动和操作的物理模拟器。
它涵盖10个任务类别,基于 Spelke 的核心知识系统:物体永久性(追踪被遮挡的物体)、固体性(理解物理约束)、容纳性(推理容器内部有什么)、支撑性(预测稳定性)、形状恒常性(跨视角识别物体)。
每个任务都从初始视角隐藏关键信息——物体在墙后,在关闭的抽屉里,或只能从特定角度识别。
智能体不接收特权状态。
它必须决定:我该靠近吗?
打开这个容器?
旋转物体?
每个行动消耗代币(模拟现实世界的努力),并产生新观测。
基准不仅测量最终准确率,还测量探索策略的效率——需要多少行动才能得出自信、正确的答案。
实验比较三种模式:(1) 单一被动视角,(2) 随机多视角(智能体看到N个随机视角),(3) 主动探索(智能体选择行动)。
测试了最先进的 MLLM(GPT-4V、Gemini、Claude),有无显式3D基础(点云、深度图)。
任务设置:
  初始视角 --> [被遮挡 / 模糊场景]
       |
       v
  智能体决策树:
    - 感知(缩放、旋转视角)
    - 移动(移动到新位置)
    - 操作(打开、举起、摇晃)
       |
       v
  新观测 --> 更新信念 --> 重复或回答
       |
       v
  评估:准确率 + 行动效率
把 ESI-Bench 想象成犯罪现场是可交互的侦探游戏。
被动侦探拿到一张照片就猜测。
随机侦探拿到20张任意角度的照片——数据更多,但没有策略。
主动侦探走遍现场,打开可能藏证据的抽屉,检查视线,测试假设。
犯罪(任务)相同,但调查方法(观测策略)决定成败。
ESI-Bench 是犯罪现场;智能体是侦探;行动是调查动作。
基准不测试”你能看到线索吗?“而是”你知道去哪里找线索吗?“
关键概念
- 感知-行动循环:在被动视觉中,感知是输入,推理是输出。
在具身智能中,感知和行动形成循环:你行动以改变你感知的内容,然后感知以决定下一个行动。
机器人判断盒子是否为空,无法从照片解决——它必须举起盒子(行动)感受重量(感知),或打开它(行动)看里面(感知)。
当行动选择由你需要感知的内容而非当前看到的内容驱动时,循环闭合。
ESI-Bench 通过让任务成功依赖于选择揭示隐藏信息的行动,而非仅仅更好地处理可见信息,来操作化这一点。
- 行动盲目性:模型失败不是因为无法识别物体或估计深度,而是因为无法将不确定性映射到行动。
当模型看到关闭的抽屉并需要知道里面有什么时,行动盲目性表现为:(a) 没有识别出抽屉是关闭的,(b) 识别出来但不选择打开它,或 (c) 打开了但不理解新视角解决了不确定性。
这是元认知失败——模型不知道自己不知道什么,所以无法寻求正确的证据。
论文中的人类研究显示,人们自然寻求证伪视角(“让我检查另一边以确认”)。
模型无论证据质量如何都会早早做出高置信度承诺。
- 涌现的空间策略:没有明确指令,智能体发现了特定任务的探索模式。
对于物体永久性任务,成功的智能体学会绕着遮挡物转圈。
对于容纳性任务,它们学会在回答前操作容器。
这些策略不是编程的——它们从奖励结构中涌现(更少行动后的正确答案得分更高)。
涌现是脆弱的:随机多视角常常降低性能,因为无关视角增加噪声,证明更多观测 ≠ 更好推理,如果没有战略性选择。
框架转变
之前(主流方法):                之后(本文方法):

  [图像] --> [模型] --> [答案]     [场景] --> [智能体]
                                          |
                                          v
                                    选择行动
                                          |
                                          v
                                    [新视角] --> 更新
                                          |
                                          v
                                    重复或回答

  感知 = 输入                       感知 = 行动的结果
  任务:推理你看到的               任务:决定看什么
从完美观测到赚取的观测,核心转变是将观察者重构为行动者。
专家评审
选题眼光:这是真实的缺口。
具身AI研究专注于导航和操作作为独立模块,但整合——使用行动解决感知不确定性——仍未充分探索。
问题位于视觉、机器人和推理的交叉点,这使它既重要又难以干净地基准化。
基于 Spelke 核心知识系统的基础是智识诚实的;这些不是任意任务,而是基础空间能力。
方法成熟度:基准设计合理。
使用 OmniGibson 提供物理真实性,无需真实世界数据收集的成本。
行动空间(感知/移动/操作)最小但足以测试假设。
被动、随机多视角和主动探索之间的比较是正确的消融。
然而,论文严重依赖提示现有 MLLM 而非从头训练具身智能体,这限制了关于什么是可学习的与什么是提示伪影的结论。
实验诚意:基线公平。
随机多视角常常损害性能的发现令人惊讶且有充分记录。
人类研究增加了可信度——显示人类自然寻求证伪证据而模型不会,这是一个干净的结果。
一个担忧:3D基础实验显示不完美的3D表示损害性能,但论文没有深入调查为什么。
是点云中的噪声?
2D和3D之间的错位?
这感觉像是后续消融的错失机会。
写作功力:摘要和引言很强。
相关工作部分彻底但密集——削减20%会改善流畅性。
结果部分埋没了重点:行动盲目性发现(第4.3节)应该更早出现,因为它是论文最重要的贡献。
人类研究(第4.4节)执行良好但感觉附加;将其整合到主叙事中会加强论证。
判决:强接收——这个基准将被广泛使用,行动盲目性洞见重构了我们应该如何评估空间推理。
要点总结
对于构建具身智能体的实践者:不要假设更多视角 = 更好推理。
测试你的智能体能否选择信息性行动,而非仅仅处理更多数据。
如果你的智能体随机探索,你可能在增加噪声。
对于视觉研究者:提供完美视角的空间推理基准在测量错误的东西。
如果你的模型在静态空间推理数据集上得分90%,这不能预测具身性能——行动选择是独立的能力。
对于提示工程师:论文显示提示 MLLM “主动探索”会产生涌现策略,无需明确指令。
这表明任务框架(强调不确定性和证据收集)可以解锁基础模型中的潜在能力。
可迁移技术:“行动成本”机制(每个行动消耗代币,强制效率)是防止任何交互式基准中蛮力探索的简单方法。
为你自己的评估设置偷走这个。