Paper: 2606.27354
Authors: Haina Jiang, Liam Wang, Peng-Chen Chen, Min Seop Kwak, Seungryong Kim, Brian Bell, Jeong Joon Park
Categories: cs.LG, cs.AI, cs.CV, math.NA
The Gap
Existing neural solvers for PDEs fall into two camps. Purely data-driven surrogates (e.g., DeepONet, FNO) learn a static mapping from parameters to solutions; once trained, they cannot correct their own constraint violations and extrapolate poorly. Hybrid methods (e.g., PINN-based refinements, physics-informed correction steps) use the PDE residual as an optimization target, running gradient descent or Gauss-Newton steps at inference time. They achieve better physical consistency, but this paper identifies a critical flaw: numerically minimizing the PDE residual is an unreliable proxy for reconstruction accuracy in ill-conditioned systems. The residual can be low while the prediction is still far from the true solution, especially when the PDE operator has a large condition number. This explains why hybrid methods often show impressive residual reduction but mediocre accuracy.
The authors instead ask: what if the residual is not a loss to minimize, but a feature to read? They propose Error-Conditioned Neural Solvers (ENS), which take the residual field as an input to the network at each iteration, enabling it to learn a correction policy that directly targets solution accuracy rather than residual magnitude.
Problem: Neural surrogates can't self-correct
  Assumption: Minimizing residual = accurate solution
    Method: Feed residual field as input to network
      Evidence: 10x improvement on turbulent Kolmogorov flow
        Conclusion: Learned correction beats residual minimization
           when PDE is ill-conditioned
The Increment
One sentence: Before ENS, hybrid methods treated the PDE residual as a loss to minimize and often got low residuals but wrong answers; after ENS, the residual is treated as a feature to read, and the network learns to correct its own errors directly.
Core Mechanism
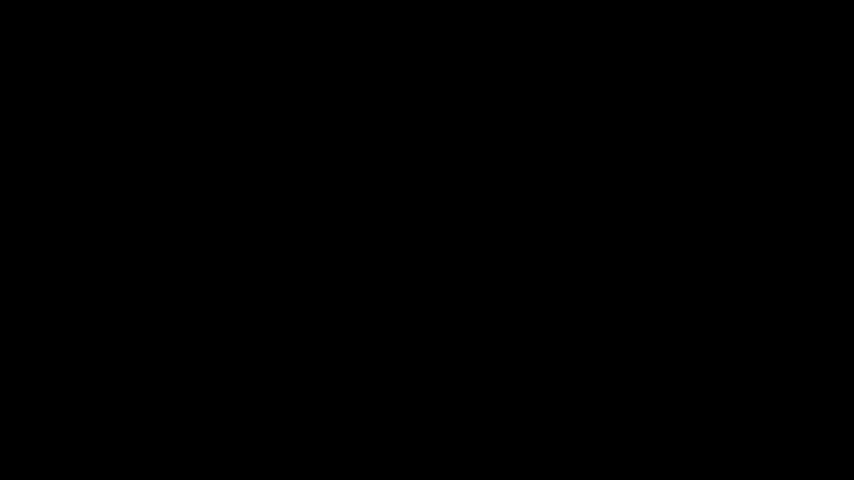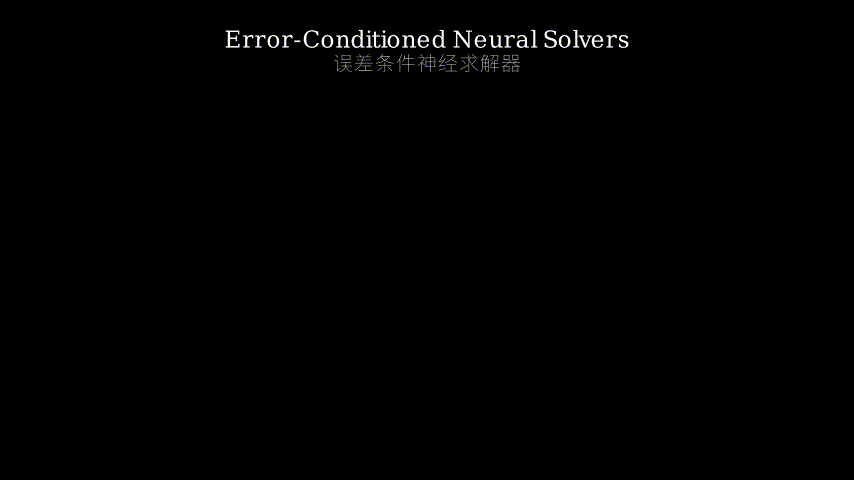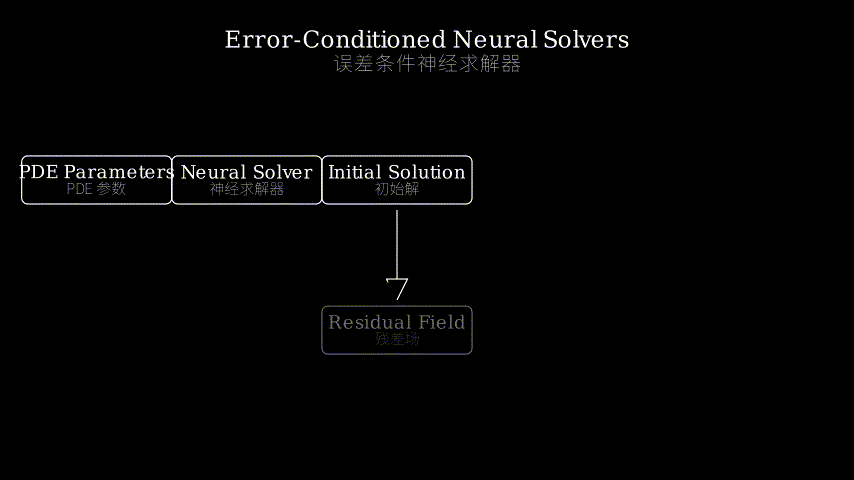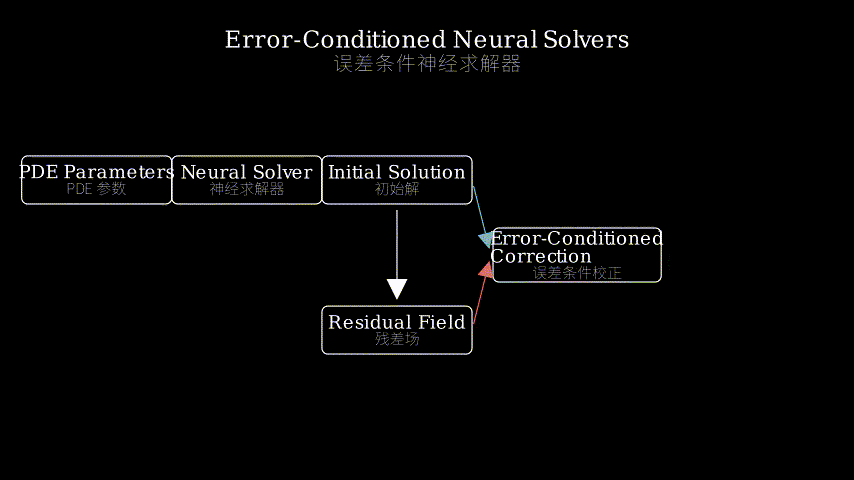
ENS works as an iterative refinement loop. At each step, the network receives three things: the PDE parameters (e.g., coefficients, boundary conditions), the current prediction of the solution field, and the computed PDE residual field (i.e., how much the current prediction violates the PDE at each point). The network outputs a correction delta to be added to the current prediction. This process repeats for a fixed number of steps (e.g., 5-10). The entire pipeline—including the iterative loop—is trained end-to-end, with the loss being the final prediction error against ground-truth solutions.
The key design choice is that the residual is not differentiated through for gradient-based optimization; it is simply a spatial feature map fed into the network. This avoids the instability and cost of second-order optimization. The network learns to interpret the spatial structure of its own errors—high residual regions signal where correction is needed, and the shape of the residual hints at the type of correction required (e.g., smoothing shocks, sharpening interfaces).
[Data flow of ENS at inference time]
+-----------+     +-----------+     +-----------+
| PDE params| --> |   ENS     | --> | Correction|
+-----------+     | Network   |     | delta     |
                  +-----------+     +-----------+
                         ^                |
                         |                v
                  +-----------+     +-----------+
                  | Current   |     | Next      |
                  | prediction| <-- | prediction|
                  +-----------+     +-----------+
                         ^
                         |
                  +-----------+
                  | Residual  |
                  | field     |
                  +-----------+
Structural metaphor: Think of ENS as a sketch artist who refines a portrait.
- The PDE parameters are the subject’s description (height, hair, nose).
- The initial prediction is the first rough sketch, often wrong.
- The residual field is a map of where the sketch violates the subject’s actual proportions—like a heatmap showing “here the nose is too wide, here the chin is too short”.
- The ENS network is the artist who, instead of being told to minimize some abstract “error score”, is shown that heatmap directly and learns to adjust the pencil strokes in exactly those regions.
- The correction delta is the new set of strokes.
- The iterative loop is the artist checking, adjusting, checking again.
The crucial point: the artist never tries to minimize the heatmap value globally—they just look at it and decide where to draw next. This is fundamentally different from trying to solve an optimization problem that the heatmap represents.
Key Concepts
- Ill-conditioned PDE systems: A PDE is ill-conditioned when small changes in the solution cause large changes in the residual, or vice versa. This happens in turbulent flows, shocks, or high-frequency oscillations. In such cases, minimizing the residual can lead to solutions that satisfy the PDE equation numerically but are far from the true physical solution. ENS avoids this by not treating residual as an optimization objective.
- Residual as input feature, not loss: Standard hybrid methods compute the residual and then backpropagate through it to update the prediction. ENS computes the residual and simply concatenates it with the prediction as an input channel to the network. The network learns to read the residual’s spatial patterns and map them to appropriate corrections. This is a fundamental shift from “optimization” to “perception.”
- Learned correction policy vs. gradient descent: Hybrid methods use a fixed optimization algorithm (like gradient descent with step size). ENS learns a correction policy that is conditioned on the current state (prediction + residual). This policy can be nonlinear, data-adaptive, and can exploit patterns that gradient descent misses. It also generalizes to new parameter regimes because the residual field itself encodes the physics violation, which transfers under distribution shift.
Framework Shift
Before (hybrid methods):                After (ENS):
+------------------+                   +------------------+
| PDE params       |                   | PDE params       |
| + current pred   |                   | + current pred   |
|       |          |                   |       |          |
|       v          |                   |       v          |
| Compute residual |                   | Compute residual |
|       |          |                   |       |          |
|       v          |                   |       v          |
| Gradient descent |                   | Concatenate w/   |
| on residual loss |                   | prediction       |
|       |          |                   |       |          |
|       v          |                   |       v          |
| Update prediction|                   | Neural network   |
+------------------+                   | outputs delta    |
                                         |       |          |
                                         |       v          |
                                         | Update prediction|
                                         +------------------+

Key difference: In hybrid methods, the residual drives an optimization loop. In ENS, the residual is just an input feature to a learned correction network.
One sentence: From treating the residual as a loss to be minimized, to treating it as a feature to be perceived—the core shift is replacing optimization with learned perception.
Expert Assessment
Problem choice: Real gap, well-motivated. The observation that residual minimization can give wrong answers in ill-conditioned systems is a genuine insight that many practitioners overlook. This paper sits at the intersection of scientific computing and learned optimization, a hot area.
Method maturity: Clever and principled. The simplicity of replacing an optimizer with a read/residual-conditioned network is elegant. There’s no brute-force hyperparameter search; the architecture is straightforward (convolutional or graph neural net). The authors also show that ENS avoids the compute cost of second-order methods (no autograd through residual), which is a practical win.
Experimental integrity: Strong. They evaluate on four PDE families (Poisson, Burgers, Navier-Stokes, Kolmogorov flow) with multiple baselines (FNO, DeepONet, PINN, hybrid Gauss-Newton). The 10x improvement on Kolmogorov flow is striking. They also test zero-shot generalization and cross-equation transfer, which is rare. No obvious red flags; metrics are well-chosen (relative L2 error, residual norm). I’d like to see more ablations on the number of iterations and whether the residual conditioning is strictly necessary (they claim it is, but a comparison with simply feeding the current prediction again would be helpful).
Writing quality: Solid but dense. The introduction clearly states the gap; the theory section on ill-conditioning is rigorous. The authors sometimes rush through experimental setup. Section 4.3 (generalization) could be expanded to discuss failure cases. The website is a nice supplementary resource.
Verdict: Strong accept — a novel and well-executed idea that opens a new direction for physics-informed machine learning, with convincing experiments and clear practical benefits.
Takeaways
- Stop minimizing residuals; start reading them. If you’re working on PDE surrogates, try conditioning your refinement network on the residual field as an input channel. It’s cheap and often works better than gradient descent.
- Ill-conditioning is a feature, not a bug. The paper shows that the regimes where residual minimization fails are exactly where ENS excels. If your PDE is stiff or turbulent, ENS is especially promising.
- Iterative refinement can be learned end-to-end. You don’t need to bake a fixed optimization algorithm into your model. Train the refinement loop with a prediction loss, and let the network discover its own correction strategy.
- Check your residual vs. accuracy correlation. Before committing to a hybrid method, plot residual vs. true error on a validation set. If the correlation is weak (as in ill-conditioned settings), you have the exact problem ENS solves.
论文: 2606.27354
作者: Haina Jiang, Liam Wang, Peng-Chen Chen, Min Seop Kwak, Seungryong Kim, Brian Bell, Jeong Joon Park
分类: cs.LG, cs.AI, cs.CV, math.NA
缺口
现有的PDE神经求解器分为两大阵营.
纯数据驱动代理模型(如DeepONet, FNO)学习从参数到解的静态映射, 一旦训练完成就无法纠正自身违反约束的错误, 外推能力差.
混合方法(如基于PINN的修正、物理信息校正步骤)则将PDE残差作为优化目标, 在推理时执行梯度下降或高斯-牛顿步骤.
它们能实现更好的物理一致性, 但本文发现了一个关键缺陷:在病态系统中, 数值上最小化PDE残差并不是重建精度的可靠代理.
当PDE算子条件数很大时, 残差可能很小但预测结果仍远离真实解.
这解释了为什么混合方法常常残差漂亮但精度平平.
作者转而提出:如果残差不作为损失来最小化, 而是作为特征来读取呢?
他们提出了误差条件神经求解器(ENS), 在每个迭代步骤将残差场作为网络输入, 使其学会直接针对解精度而非残差大小的校正策略.
问题: 神经代理无法自我校正
  假设: 最小化残差 = 精确解
    方法: 将残差场作为网络输入
      证据: 在湍流Kolmogorov流上提升10倍
        结论: 学习到的校正优于残差最小化
           当PDE病态时尤为明显
增量
一句话: 之前混合方法把PDE残差当作损失最小化, 常得到低残差但错误的解; ENS将残差当作特征来读取, 让网络直接学会校正自身误差.
核心机制
ENS是一个迭代求精循环.
每步中, 网络接收三样东西:PDE参数(系数、边界条件等)、当前的预测场、以及计算出的PDE残差场(当前预测在每个点违反PDE的程度).
网络输出一个校正增量, 加到当前预测上.
此过程重复固定步数(如5-10步).
整个流水线——包括迭代循环——以端到端方式训练, 损失函数为最终预测与真解之间的误差.
关键设计在于:残差不参与自动微分用于梯度优化, 它只是一个被送入网络的空间特征图.
这避免了二阶优化的不稳定性和计算成本.
网络学会解读自身误差的空间结构——高残差区域提示需要校正, 残差的形状暗示校正类型(例如, 平滑激波、锐化界面).
[ENS推理时的数据流]
+-----------+     +-----------+     +-----------+
| PDE参数   | --> |  ENS网络  | --> | 校正增量 |
+-----------+     +-----------+     +-----------+
                         ^                |
                         |                v
                  +-----------+     +-----------+
                  | 当前预测  | <-- | 下一预测  |
                  +-----------+     +-----------+
                         ^
                         |
                  +-----------+
                  | 残差场   |
                  +-----------+
结构比喻: 把ENS想象成一位不断细化肖像画的素描画家.
- PDE参数是模特的外貌描述(身高、发型、鼻型).
- 初始预测是第一笔粗糙的速写, 常常不对.
- 残差场是一张显示速写与模特真实比例冲突的地图——有点像热力图, 显示”这里鼻子太宽, 那里下巴太短”.
- ENS网络就是画家, 他不被要求去最小化某个抽象的”误差分数”, 而是直接看到那张热力图, 并学会在那些区域调整铅笔线条.
- 校正增量就是新加的线条.
- 迭代循环就是画家检查、调整、再检查的过程.
关键点:画家从不试图从全局上最小化热力图的值——他只是看它, 然后决定在哪里下笔. 这与试图求解热力图所代表的优化问题有本质区别.
关键概念
- 病态PDE系统: 当解的微小变化会导致残差巨大变化(或反之)时, PDE就是病态的. 这发生在湍流、激波或高频振荡中. 此时最小化残差可能得到数值上满足方程却远离真实物理的解. ENS通过不把残差作为优化目标来避免这一问题.
- 残差作为输入特征而非损失: 混合方法计算残差, 然后通过它反向传播来更新预测. ENS计算残差, 然后简单地将它与预测拼接作为网络的输入通道. 网络学会读取残差的空间模式, 并将它们映射到合适的校正. 这是从”优化”到”感知”的根本转变.
- 学习校正策略 vs 梯度下降: 混合方法使用固定优化算法(如带步长的梯度下降). ENS学习一种校正策略, 该策略以当前状态(预测+残差)为条件. 这种策略可以是非线性的、数据自适应的, 并且能够利用梯度下降无法捕捉的模式. 它还能泛化到新的参数区间, 因为残差场本身编码了违反物理的行为, 该行为在分布偏移下是可迁移的.
框架转变
之前(混合方法):                    之后(ENS):
+------------------+                +------------------+
| PDE参数          |                | PDE参数          |
| + 当前预测       |                | + 当前预测       |
|       |          |                |       |          |
|       v          |                |       v          |
| 计算残差        |                | 计算残差        |
|       |          |                |       |          |
|       v          |                |       v          |
| 在残差损失上    |                | 与预测拼接      |
| 做梯度下降      |                |       |          |
|       |          |                |       v          |
|       v          |                | 神经网络        |
| 更新预测        |                | 输出增量        |
+------------------+                |       |          |
                                     |       v          |
                                     | 更新预测        |
                                     +------------------+

核心差异: 混合方法中残差驱动优化循环, ENS中残差仅是学习校正网络的输入特征.
一句话: 从把残差作为损失来最小化, 到把它作为特征来感知——核心转变是用学习感知代替优化.
专家评审
选题眼光: 真缺口, 动机明确. 指出残差最小化在病态系统中可能给出错误答案, 这是一个被许多从业者忽视的深刻见解. 该工作处于科学计算与学习优化的交叉热点.
方法成熟度: 巧妙且有原则. 用读取残差网络替代优化器的想法简单而优雅. 没有暴力调参, 架构简洁(卷积或图神经网络). 作者还表明ENS避免了二阶方法的计算成本(无需对残差自动微分), 这是实用的胜利.
实验诚意: 扎实. 在四个PDE族(Poisson, Burgers, Navier-Stokes, Kolmogorov流)上评估, 包含多个基线(FNO, DeepONet, PINN, 混合Gauss-Newton). 在Kolmogorov流上10倍提升令人印象深刻. 还测试了零样本泛化和跨方程迁移, 这很少见. 无明显红旗; 指标选择合理(相对L2误差, 残差范数). 希望看到更多关于迭代次数和残差条件是否必要的消融实验(他们声称必要, 但若能对比仅输入当前预测的情况会更清晰).
写作功力: 扎实但密集. 引言清楚指出空白; 关于病态系统的理论部分严谨. 作者有时在实验设置上略过. 第4.3节(泛化性)可以扩展讨论失败案例. 网站作为补充资源很好.
判决: 强接收 — 一个新颖且执行良好的想法, 为物理信息机器学习开辟了新方向, 实验有说服力, 实际收益明确.
要点总结
- 停止最小化残差, 开始读取残差. 如果你在做PDE代理模型, 尝试将残差场作为输入通道加到求精网络上. 代价低, 且往往优于梯度下降.
- 病态是特征, 不是bug. 论文表明残差最小化失效的区域正是ENS大放异彩的地方. 如果你的PDE是刚性的或湍流, ENS尤其有潜力.
- 迭代求精可以端到端学习. 不必在模型中嵌入固定的优化算法. 用预测损失训练求精循环, 让网络自己发现校正策略.
- 检查残差与精度的相关性. 在采用混合方法前, 在验证集上绘制残差与真实误差的关系图. 如果相关性弱(如在病态设定中), 你就遇到了ENS要解决的那类问题.