Paper: 2605.15179 Authors: Ellwil Sharma, Arastu Sharma Categories: cs.LG, cs.AI, physics.comp-ph
The Gap
Universal foundation models for scientific computing promise to handle multiple physical regimes in one network. But when you train a single dense neural operator on both open-channel fluid dynamics and porous media flows, the gradients fight each other. Open-channel flows need spectral representations for turbulent cascades. Porous media flows need geometric sensitivity for boundary-dominated transport. Forcing both through the same parameter path causes gradient conflict, unstable training, and plasticity loss—the model forgets what it learned about one regime when learning the other.
Prior work either trains separate models per physics domain (no knowledge transfer) or uses dense multi-task architectures that suffer from negative transfer. The gap: no architecture that lets different physics regimes coexist in one model without interfering.
Problem: Multi-physics co-training
    |
    v
Gradient conflict in dense networks
    |
    v
Assumption: Different physics need different parameter paths
    |
    v
Method: Sparse MoE routing to specialized experts
    |
    v
Evidence: Autonomous domain bifurcation in routing telemetry
    |
    v
Conclusion: Sparse routing mitigates multi-physics interference
The Increment
One sentence: Before this paper, multi-physics neural operators either trained separately or suffered gradient conflict; after, a single model routes different regimes to specialized experts and converges simultaneously.
Core Mechanism
Shodh-MoE compresses 3D physical fields into 16³ latent tokens using a physics-informed autoencoder. The encoder enforces divergence-free velocity through a Helmholtz decomposition inside the tokenizer—velocity is parameterized as the curl of a vector potential, guaranteeing zero divergence by construction. This produces physically valid latent representations.
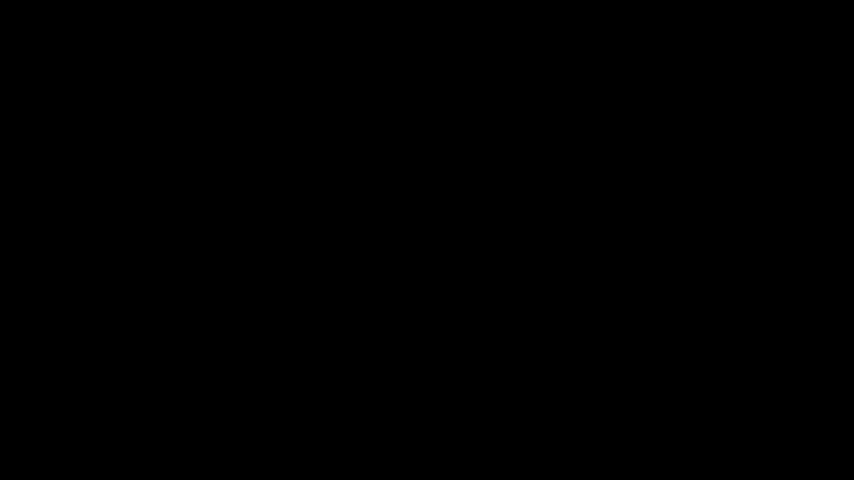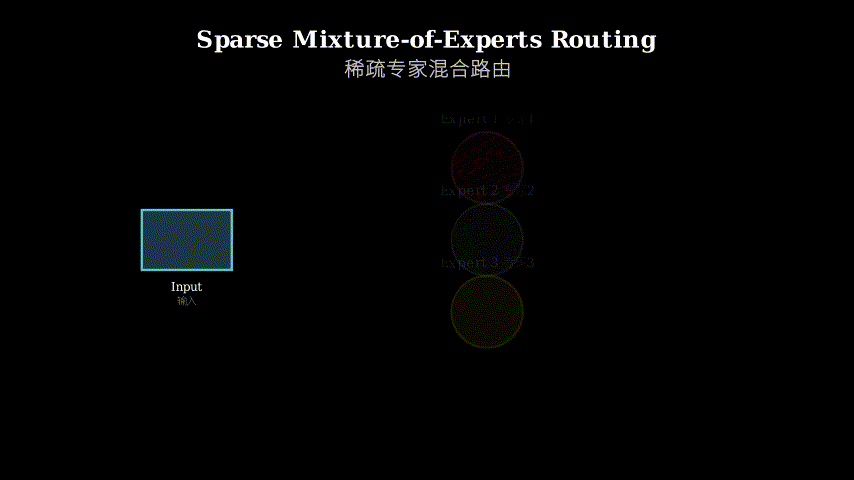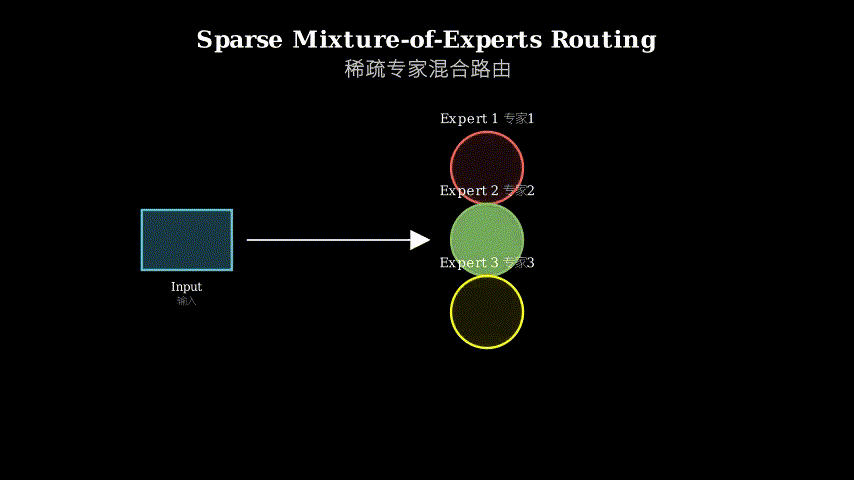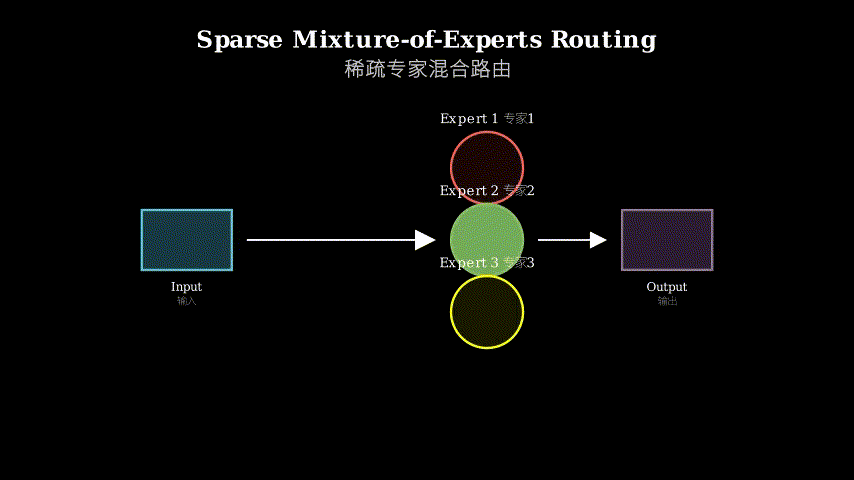
A transformer processes these latent tokens, but instead of routing all tokens through the same feedforward layers, a Top-1 soft-semantic router examines each token and assigns it to one of several expert subnetworks. Each expert is a separate feedforward block with its own parameters. The router learns to send tokens from different physical regimes to different experts. Some experts can be shared across regimes for universal symmetries, but domain-specific experts handle regime-specific mechanisms.
During training on mixed open-channel and porous-media data, the router autonomously learns to bifurcate: open-channel tokens go to Expert 0, porous-media tokens go to Expert 1. No manual labeling of token types—the router discovers this split from gradient signals alone. The model converges on both regimes simultaneously because each expert’s gradients no longer conflict with the other’s.
Input: 3D physical field (128^3 grid)
    |
    v
Physics-informed autoencoder
    | (Helmholtz velocity parameterization)
    v
Compressed latent tokens (16^3)
    |
    v
    +---> Router (examines each token)
    |         |
    |         +---> Expert 0 (open-channel specialist)
    |         |
    |         +---> Expert 1 (porous-media specialist)
    |         |
    |         +---> Shared experts (universal symmetries)
    |
    v
Transformer output (processed latents)
    |
    v
Decoder (reconstructs physical field)
    |
    v
Output: Divergence-free velocity field
Think of this like a hospital emergency room. Patients (tokens) arrive with different conditions (physical regimes). A triage nurse (router) quickly assesses each patient and sends them to the appropriate specialist: cardiac patients to the cardiologist (Expert 0), trauma cases to the trauma surgeon (Expert 1). Some staff like nurses (shared experts) help everyone. Each specialist develops deep expertise in their domain without being distracted by unrelated cases. The triage nurse learns which symptoms map to which specialist purely from observing outcomes—no one hands her a manual. The hospital (model) handles all cases simultaneously without specialists stepping on each other’s toes.
Key Concepts
-
Negative transfer: When training a neural network on multiple tasks simultaneously makes it worse at each task than training separate networks. Imagine learning piano and drums at the same time—if practicing piano makes you worse at drums, that’s negative transfer. In multi-physics models, gradients from one PDE regime can push parameters in directions that hurt performance on another regime. The network oscillates between regimes instead of improving on both.
-
Divergence-free velocity: In incompressible fluid flow, mass conservation requires that velocity divergence equals zero (∇·v = 0). If you imagine velocity as arrows showing flow direction, divergence measures whether flow is “spreading out” (positive) or “converging” (negative) at each point. Zero divergence means flow is neither created nor destroyed—what flows in must flow out. Standard neural networks can output any velocity field, including physically impossible ones with non-zero divergence. Shodh-MoE enforces this constraint by parameterizing velocity as v = ∇ × A (curl of a vector potential), which mathematically guarantees ∇·v = 0 because the divergence of a curl is always zero.
-
Sparse activation: In a mixture-of-experts model, “sparse” means each input activates only a subset of experts, not all of them. If you have 8 experts but each token only goes to 1 expert (Top-1 routing), then 7/8 of the expert parameters are inactive for that token. This is opposite to dense models where every parameter processes every input. Sparse activation enables specialization—experts can develop distinct skills because they see different subsets of data—and reduces computation because you’re not running the full model for every input.
Framework Shift
Before (dense multi-task):           After (sparse MoE):

All physics                          Open-channel tokens
    |                                    |
    v                                    v
+-------------------+                +--------+
| Single parameter  |                | Expert |
| path (all layers  |                |   0    |
| process all data) |                +--------+
+-------------------+
    |                                Porous-media tokens
    v                                    |
Gradient conflict                        v
Unstable training                    +--------+
                                     | Expert |
                                     |   1    |
                                     +--------+

                                     No gradient conflict
                                     Simultaneous convergence
From forcing all physics through one parameter bottleneck to giving each regime its own specialized path, the core shift is from shared interference to isolated specialization with selective sharing.
Expert Assessment
Problem choice: Real gap. Multi-physics foundation models are a legitimate frontier in scientific ML, and negative transfer is a documented blocker. The problem sits at the intersection of scaling laws (bigger models, more tasks) and physical constraints (conservation laws, regime-specific mechanisms). Not manufactured—this is where the field is stuck.
Method maturity: Clever architectural insight, not brute force. The Helmholtz velocity parameterization is elegant—enforcing divergence-free constraints inside the tokenizer rather than as a post-hoc loss term. The sparse routing is borrowed from NLP (Switch Transformers, GLaM) but the application to multi-physics is novel. However, the paper doesn’t explore simpler baselines like task-specific adapter layers or low-rank expert decompositions. The jump to full MoE might be overkill for two regimes.
Experimental integrity: Strong on physics verification (divergence ~10⁻¹⁰ is impressive), but the experimental setup is narrow. Only two physical regimes, only 20,000 training steps, no comparison to other multi-task architectures beyond implicit claims about dense models. The routing telemetry (Expert 0 for open-channel, Expert 1 for porous-media) is compelling evidence of autonomous bifurcation, but we don’t see what happens with more than two regimes or with regimes that share more overlap. Baselines are missing—no comparison to separate models, no ablation on number of experts, no analysis of what happens if you force dense routing.
Writing quality: The abstract and introduction are crisp. The method section buries the key insight (Helmholtz parameterization) in a subordinate clause—this should be front and center. The results section reports numbers without error bars or statistical significance tests. The related work section is thin—doesn’t engage with recent work on modular networks, task arithmetic, or other approaches to negative transfer. Rewriting the method section to lead with the physics constraints and then show how the architecture satisfies them would elevate the whole paper.
Verdict: weak accept — Solid architectural contribution with strong physics verification, but experimental scope is too narrow and baselines are missing. The core idea (sparse routing for multi-physics) is sound and the divergence-free guarantee is valuable, but the paper needs broader evaluation to support claims about “universal” foundation models.
Takeaways
Enforce physical constraints in the architecture, not the loss function. The Helmholtz velocity parameterization guarantees divergence-free flow by construction—no need to add a penalty term and hope the optimizer respects it. This pattern transfers: if your domain has hard constraints (symmetries, conservation laws, boundary conditions), bake them into the network structure rather than treating them as soft objectives.
Routing telemetry as a diagnostic tool. Watching which tokens go to which experts during training reveals whether the model is learning meaningful specialization or just random assignment. If held-out validation tokens from different regimes route to different experts without supervision, that’s evidence the architecture is doing something right. This applies beyond physics—any multi-domain model can use routing patterns to diagnose whether domains are interfering.
Sparse activation for gradient isolation. When tasks have conflicting gradients, sparse routing lets each task update its own parameters without stepping on the others. This is cheaper than training separate models and more effective than dense multi-task learning. The tradeoff: routing overhead and potential load imbalance (some experts get more traffic than others). Worth exploring in any setting where negative transfer is a problem.
论文: 2605.15179 作者: Ellwil Sharma, Arastu Sharma 分类: cs.LG, cs.AI, physics.comp-ph
缺口
科学计算的通用基础模型承诺用一个网络处理多种物理体系。
但当你在同一个密集神经算子上同时训练明渠流体动力学和多孔介质流动时,梯度会互相打架。
明渠流动需要谱表示来捕捉湍流级联。
多孔介质流动需要几何敏感性来处理边界主导的输运。
强行让两者走同一条参数路径会导致梯度冲突、训练不稳定、可塑性丧失——模型在学习一个体系时会忘记另一个体系学到的东西。
此前的工作要么给每个物理领域训练单独的模型(没有知识迁移),要么用密集的多任务架构(遭受负迁移)。
缺口在于:没有架构能让不同物理体系在一个模型中共存而不互相干扰。
问题:多物理联合训练
    |
    v
密集网络中的梯度冲突
    |
    v
假设:不同物理需要不同的参数路径
    |
    v
方法:稀疏 MoE 路由到专门的专家
    |
    v
证据:路由遥测中的自主领域分叉
    |
    v
结论:稀疏路由缓解多物理干扰
增量
一句话: 这篇论文之前,多物理神经算子要么分开训练要么遭受梯度冲突;之后,单个模型将不同体系路由到专门的专家并同时收敛。
核心机制
Shodh-MoE 用一个物理信息自编码器将 3D 物理场压缩成 16³ 个潜在 token。
编码器通过分词器内部的亥姆霍兹分解来强制速度无散——速度被参数化为矢量势的旋度,从构造上保证零散度。
这产生了物理上有效的潜在表示。
一个 transformer 处理这些潜在 token,但不是让所有 token 都走相同的前馈层,而是用一个 Top-1 软语义路由器检查每个 token 并将其分配给若干专家子网络之一。
每个专家是一个独立的前馈块,有自己的参数。
路由器学会将来自不同物理体系的 token 发送给不同的专家。
有些专家可以跨体系共享以处理通用对称性,但领域特定的专家处理体系特定的机制。
在混合明渠和多孔介质数据的训练过程中,路由器自主学会分叉:明渠 token 去专家 0,多孔介质 token 去专家 1。
不需要手动标注 token 类型——路由器仅从梯度信号中发现这种分裂。
模型在两个体系上同时收敛,因为每个专家的梯度不再与另一个冲突。
输入:3D 物理场(128^3 网格)
    |
    v
物理信息自编码器
    |(亥姆霍兹速度参数化)
    v
压缩的潜在 token(16^3)
    |
    v
    +---> 路由器(检查每个 token)
    |         |
    |         +---> 专家 0(明渠专家)
    |         |
    |         +---> 专家 1(多孔介质专家)
    |         |
    |         +---> 共享专家(通用对称性)
    |
    v
Transformer 输出(处理后的潜在表示)
    |
    v
解码器(重建物理场)
    |
    v
输出:无散速度场
把这想象成医院急诊室。
病人(token)带着不同的病症(物理体系)到达。
分诊护士(路由器)快速评估每个病人并将他们送到合适的专家:心脏病人去心脏科医生(专家 0),创伤病例去创伤外科医生(专家 1)。
有些员工比如护士(共享专家)帮助所有人。
每个专家在自己的领域发展深度专业知识,不会被无关病例分心。
分诊护士纯粹通过观察结果学会哪些症状对应哪个专家——没人给她一本手册。
医院(模型)同时处理所有病例,专家之间不会互相妨碍。
关键概念
- 负迁移: 当同时在多个任务上训练神经网络反而让它在每个任务上都比训练单独网络更差。
想象同时学钢琴和架子鼓——如果练钢琴让你打鼓更差,这就是负迁移。
在多物理模型中,来自一个偏微分方程体系的梯度会把参数推向损害另一个体系性能的方向。
网络在体系之间振荡而不是在两者上都改进。
- 无散速度: 在不可压缩流体流动中,质量守恒要求速度散度等于零(∇·v = 0)。
如果你把速度想象成显示流动方向的箭头,散度衡量的是流动在每个点是”扩散”(正值)还是”汇聚”(负值)。
零散度意味着流动既不被创造也不被消灭——流入的必须流出。
标准神经网络可以输出任何速度场,包括散度非零的物理上不可能的场。
Shodh-MoE 通过将速度参数化为 v = ∇ × A(矢量势的旋度)来强制这个约束,这在数学上保证 ∇·v = 0,因为旋度的散度总是零。
- 稀疏激活: 在混合专家模型中,“稀疏”意味着每个输入只激活专家的一个子集,而不是全部。
如果你有 8 个专家但每个 token 只去 1 个专家(Top-1 路由),那么对于那个 token,7/8 的专家参数是不活跃的。
这与密集模型相反,密集模型中每个参数处理每个输入。
稀疏激活实现专业化——专家可以发展不同的技能,因为他们看到不同的数据子集——并减少计算,因为你不是对每个输入运行完整模型。
框架转变
之前(密集多任务):             之后(稀疏 MoE):

所有物理                         明渠 token
    |                                |
    v                                v
+-------------------+            +--------+
| 单一参数路径      |            | 专家 0 |
|(所有层处理       |            +--------+
| 所有数据)        |
+-------------------+            多孔介质 token
    |                                |
    v                                v
梯度冲突                         +--------+
训练不稳定                       | 专家 1 |
                                 +--------+

                                 无梯度冲突
                                 同时收敛
从强制所有物理走一个参数瓶颈到给每个体系自己的专门路径,核心转变是从共享干扰到隔离专业化加选择性共享。
专家评审
选题眼光: 真缺口。
多物理基础模型是科学机器学习的合法前沿,负迁移是有文献记录的障碍。
问题位于缩放定律(更大的模型、更多的任务)和物理约束(守恒定律、体系特定机制)的交叉点。
不是人造的——这是该领域卡住的地方。
方法成熟度: 巧妙的架构洞察,不是蛮力。
亥姆霍兹速度参数化很优雅——在分词器内部强制无散约束而不是作为事后的损失项。
稀疏路由借鉴自 NLP(Switch Transformers、GLaM),但应用到多物理是新颖的。
然而,论文没有探索更简单的基线,比如任务特定的适配器层或低秩专家分解。
对于两个体系来说,跳到完整的 MoE 可能是杀鸡用牛刀。
实验诚意: 物理验证很强(散度 ~10⁻¹⁰ 令人印象深刻),但实验设置狭窄。
只有两个物理体系,只有 20,000 训练步,除了对密集模型的隐含声明外没有与其他多任务架构的比较。
路由遥测(专家 0 对应明渠,专家 1 对应多孔介质)是自主分叉的有力证据,但我们看不到超过两个体系或体系之间有更多重叠时会发生什么。
缺少基线——没有与单独模型的比较,没有关于专家数量的消融,没有分析如果强制密集路由会发生什么。
写作功力: 摘要和引言简洁。
方法部分把关键洞察(亥姆霍兹参数化)埋在从句里——这应该放在最前面和中心位置。
结果部分报告数字时没有误差条或统计显著性检验。
相关工作部分单薄——没有与模块化网络、任务算术或其他负迁移方法的最新工作交流。
重写方法部分,先讲物理约束然后展示架构如何满足它们,会提升整篇论文。
判决: 弱接收 — 扎实的架构贡献加强大的物理验证,但实验范围太窄且缺少基线。
核心想法(多物理的稀疏路由)是合理的,无散保证是有价值的,但论文需要更广泛的评估来支持关于”通用”基础模型的声明。
要点总结
在架构中而非损失函数中强制物理约束。
亥姆霍兹速度参数化从构造上保证无散流动——不需要添加惩罚项并希望优化器尊重它。
这个模式可迁移:如果你的领域有硬约束(对称性、守恒定律、边界条件),把它们烘焙到网络结构中而不是把它们当作软目标。
路由遥测作为诊断工具。
观察训练期间哪些 token 去哪些专家揭示模型是在学习有意义的专业化还是只是随机分配。
如果来自不同体系的留出验证 token 在没有监督的情况下路由到不同的专家,这是架构做对了某事的证据。
这适用于物理之外——任何多领域模型都可以用路由模式来诊断领域是否在干扰。
用于梯度隔离的稀疏激活。
当任务有冲突的梯度时,稀疏路由让每个任务更新自己的参数而不踩到其他任务。
这比训练单独的模型更便宜,比密集多任务学习更有效。
权衡:路由开销和潜在的负载不平衡(有些专家比其他专家获得更多流量)。
在负迁移是问题的任何设置中都值得探索。