Paper: 2605.21488 Authors: Benhao Huang, Zhengyang Geng, Zico Kolter Categories: cs.LG
The Gap
Iterative reasoning models (like chain-of-thought or recurrent refinement) scale test-time compute by updating latent states. They work empirically, but we don’t understand why they generalize beyond memorized patterns. Prior approaches either rely on external verifiers (expensive, domain-specific) or task-specific priors (limits generality). The core mystery: what internal mechanism lets a neural network “think longer” and arrive at better solutions?
This paper proposes that generalizable reasoning emerges from learning task-conditioned attractors—latent dynamical systems where stable fixed points correspond to valid solutions. The hypothesis: if you train a network to iteratively refine a latent state, it learns a landscape where “rolling downhill” leads to correct answers.
Problem: Iterative models work, but mechanism unclear
   |
   v
Hypothesis: Networks learn attractor landscapes
   |                    (stable points = solutions)
   v
Method: Equilibrium Reasoners (EqR)
   |        - Scale depth (more iterations)
   |        - Scale breadth (multiple trajectories)
   v
Evidence: Convergence strength predicts accuracy gains
   |         Sudoku: 2.6% -> 99% with 40k-layer unrolling
   v
Conclusion: Attractor dynamics explain scalable reasoning
The Increment
One sentence: Before, we knew iterative refinement helps but not why; after, we have a mechanistic explanation (learned attractors) and a principled way to scale test-time compute (depth + breadth) without external verifiers.
Core Mechanism
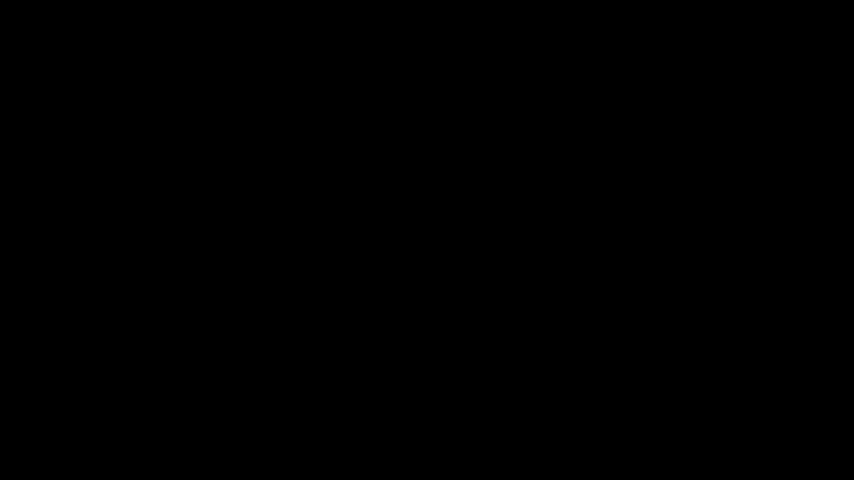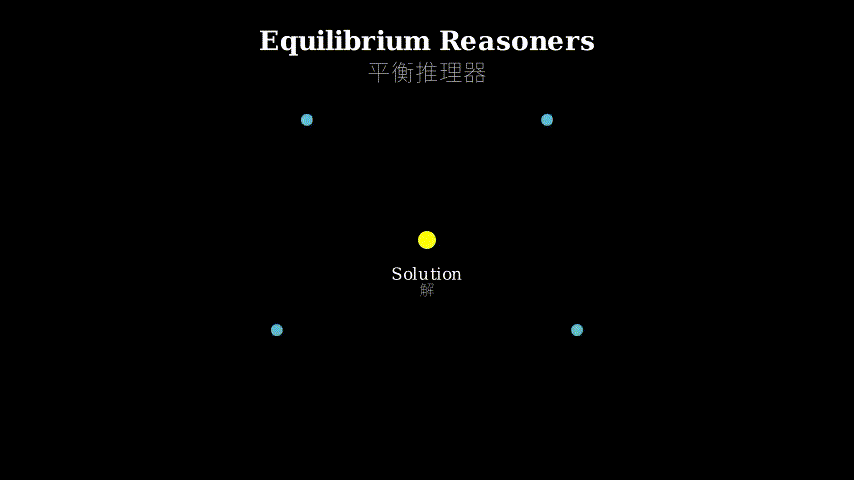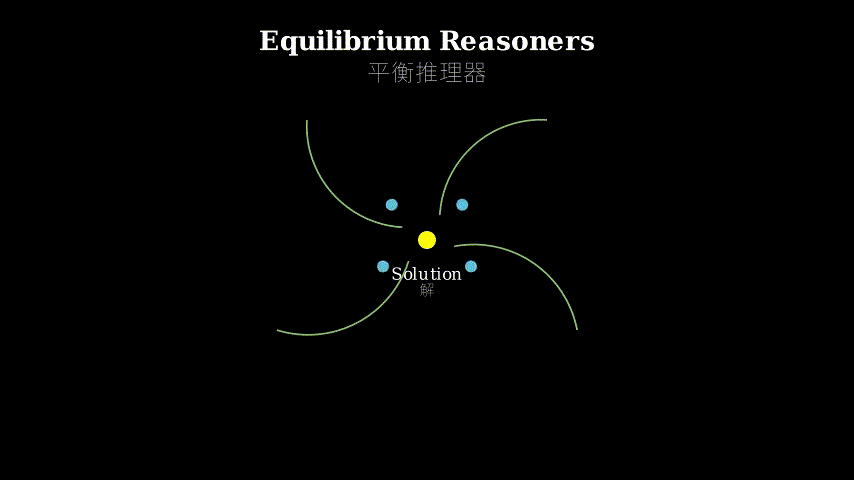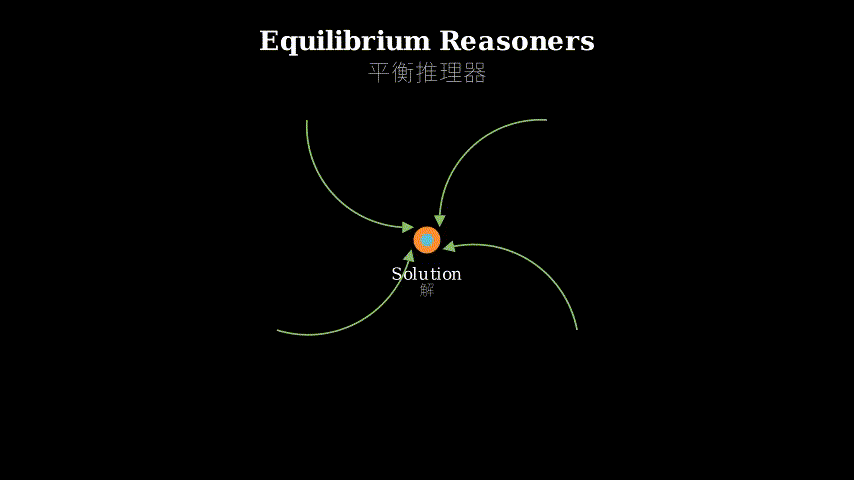
Equilibrium Reasoners treat reasoning as a dynamical system. You start with a latent state (could be random, could be task-conditioned), then repeatedly apply a learned update function. The network is trained so that this iterative process converges to a stable fixed point—an attractor—that encodes a valid solution.
Two scaling axes: depth (run more iterations, like unrolling a recurrent network deeper) and breadth (start from multiple random initializations, aggregate their trajectories). Depth lets hard problems “settle” into attractors. Breadth hedges against bad initializations by exploring multiple basins of attraction.
The key insight: you don’t need an external verifier to know when to stop. The network learns to converge. Strong convergence (small change between iterations) correlates with correct solutions. Weak convergence signals the model is still “searching.”
Input (task) --> Latent state z_0
                      |
                      v
         +------------+------------+
         |  Update: z_t+1 = f(z_t, task)
         +------------+------------+
                      |
                      v (iterate until convergence)
                      |
         Attractor: z* (stable fixed point)
                      |
                      v
         Decode z* --> Solution
Think of it like a marble rolling on a landscape. The landscape’s shape is determined by the task (Sudoku vs. logic puzzle vs. math problem). Training carves valleys (attractors) at locations corresponding to valid solutions. At test time, you drop the marble (initialize latent state) and let physics (the learned update function) do the work. If the landscape is well-formed, the marble rolls into a valley (converges to a solution). Hard problems have shallow valleys—you need more time (depth) for the marble to settle. Multiple marbles (breadth) increase the chance that at least one finds a good valley.
Key Concepts
-
Attractor: Imagine a bowl on a table. If you drop a marble anywhere inside the bowl, it rolls to the bottom and stays there. That bottom point is an attractor—a stable state the system naturally moves toward. In EqR, the “bowl” is the learned latent dynamics, and the “bottom” is a latent representation of a valid solution. The network learns to shape the landscape so that iterating the update function pulls you toward these stable points. Simple problems have deep, obvious bowls (converge fast). Hard problems have shallow, complex bowls (need more iterations to settle).
-
Test-time scaling: Most neural networks are fixed at inference—you run one forward pass and get an answer. EqR lets you trade compute for accuracy *after training. Run more iterations (depth scaling) to let hard problems converge. Run multiple trajectories from different starting points (breadth scaling) to explore different solution basins. This is like giving the model “thinking time” without retraining. The paper shows this scales dramatically: equivalent to unrolling 40,000 layers for extreme Sudoku puzzles.
Framework Shift
Before (mainstream approach):        After (this paper):

Input --> Model --> Output           Input --> Init latent z_0
          (fixed depth)                        |
                                               v
  OR                                  +--------+--------+
                                      | z_t+1 = f(z_t)  |
Input --> Model --> Candidate         +--------+--------+
          |                                    |
          v                           (iterate until stable)
     Verifier (external)                       |
          |                                    v
          v                           Attractor z* --> Output
     Accept/Reject                    (no external verifier)

Depth = architecture                 Depth = test-time choice
Breadth = beam search (discrete)     Breadth = trajectory aggregation
From fixed-depth feedforward or verifier-dependent search to learned attractor dynamics with adaptive test-time scaling, the core shift is internalizing the convergence criterion.
Expert Assessment
Problem choice: Real gap. Test-time compute scaling is a hot topic (see o1, self-consistency methods), but the mechanistic story has been hand-wavy. Framing it through dynamical systems and attractors is intellectually satisfying and connects to a rich literature in optimization and physics. Not manufactured—this addresses a genuine mystery in why iterative refinement works.
Method maturity: Clever insight, not brute force. The attractor framing is elegant, but the implementation is straightforward: train a recurrent latent model with a convergence loss. The depth/breadth scaling is intuitive once you accept the attractor hypothesis. One concern: the paper doesn’t deeply explore *how to train networks to form good attractors—it mostly shows that if you train iteratively, attractors emerge. The training recipe feels underspecified for practitioners.
Experimental integrity: Baselines are fair. The Sudoku results are striking (2.6% → 99%), but Sudoku is a best-case scenario for this approach (discrete, verifiable, well-defined solution space). The paper acknowledges this and tests on other domains (logic, math), though less extensively. The 40k-layer claim is technically true but slightly misleading—it’s 40k *equivalent layers via iteration, not a single massive network. The convergence-accuracy correlation is well-documented and convincing.
Writing quality: The abstract and intro are strong—clear hypothesis, clean framing. The method section is dense and could use more intuition-building before diving into equations. The attractor metaphor is introduced but not fully exploited; a figure showing actual learned attractor landscapes would be illuminating. The related work section is thorough but reads like a checklist. Rewriting the method section with more visual aids and concrete examples would elevate the paper significantly.
Verdict: strong accept — Provides a mechanistic lens (attractors) for understanding iterative reasoning, demonstrates dramatic test-time scaling without verifiers, and opens a research direction. The Sudoku results alone justify publication, and the framework is general enough to inspire follow-up work.
Takeaways
For practitioners: If you’re building iterative reasoning systems, train with a convergence objective (minimize change between iterations) and monitor convergence strength at test time as a proxy for confidence. Don’t stop at a fixed iteration count—let the model tell you when it’s done. For hard instances, scale depth (more iterations) before scaling breadth (multiple trajectories), since depth is cheaper.
For researchers: The attractor framing suggests a new evaluation metric: measure the “basin of attraction” around correct solutions (how far can you perturb the initial state and still converge?). This could replace or complement accuracy. Also, the paper hints that training dynamics matter—networks that converge faster during training might form better attractors. Worth investigating training schedules that explicitly shape the attractor landscape.
Transferable technique: The depth/breadth scaling trade-off applies beyond reasoning. Any iterative refinement model (image generation, protein folding, trajectory optimization) could benefit from adaptive test-time scaling based on convergence signals. The key is training the model to converge, not just to output good answers.
论文: 2605.21488 作者: Benhao Huang, Zhengyang Geng, Zico Kolter 分类: cs.LG
缺口
迭代推理模型(如思维链或循环细化)通过更新潜在状态来扩展测试时计算。
它们在实践中有效,但我们不理解为什么它们能泛化到记忆模式之外。
先前方法要么依赖外部验证器(昂贵、领域特定),要么依赖任务特定先验(限制通用性)。
核心谜题:什么内部机制让神经网络能”思考更久”并得出更好的解?
本文提出,可泛化推理源于学习任务条件吸引子——稳定不动点对应有效解的潜在动力系统。
假设:如果训练网络迭代细化潜在状态,它会学习一个”顺坡而下”通向正确答案的景观。
问题:迭代模型有效,但机制不明
   |
   v
假设:网络学习吸引子景观
   |        (稳定点 = 解)
   v
方法:平衡推理器(EqR)
   |    - 扩展深度(更多迭代)
   |    - 扩展广度(多条轨迹)
   v
证据:收敛强度预测准确率提升
   |     数独:2.6% -> 99%(40k层展开)
   v
结论:吸引子动力学解释可扩展推理
增量
一句话: 之前我们知道迭代细化有帮助但不知为何;
之后我们有了机制解释(学习的吸引子)和无需外部验证器扩展测试时计算的原则性方法(深度+广度)。
核心机制
平衡推理器将推理视为动力系统。
从潜在状态开始(可以是随机的,可以是任务条件的),然后重复应用学习的更新函数。
网络被训练成这个迭代过程收敛到稳定不动点——一个吸引子——编码有效解。
两个扩展轴:深度(运行更多迭代,像展开更深的循环网络)和广度(从多个随机初始化开始,聚合它们的轨迹)。
深度让困难问题”沉降”到吸引子。
广度通过探索多个吸引盆来对冲糟糕的初始化。
关键洞察:你不需要外部验证器来知道何时停止。
网络学会收敛。
强收敛(迭代间变化小)与正确解相关。
弱收敛表明模型仍在”搜索”。
输入(任务)--> 潜在状态 z_0
                      |
                      v
         +------------+------------+
         |  更新:z_t+1 = f(z_t, 任务)
         +------------+------------+
                      |
                      v(迭代直到收敛)
                      |
         吸引子:z*(稳定不动点)
                      |
                      v
         解码 z* --> 解
把它想象成弹珠在景观上滚动。
景观的形状由任务决定(数独 vs 逻辑谜题 vs 数学问题)。
训练在对应有效解的位置雕刻山谷(吸引子)。
测试时,你放下弹珠(初始化潜在状态)让物理(学习的更新函数)做功。
如果景观形成良好,弹珠滚入山谷(收敛到解)。
困难问题有浅山谷——你需要更多时间(深度)让弹珠沉降。
多个弹珠(广度)增加至少一个找到好山谷的机会。
关键概念
- 吸引子: 想象桌上的碗。
如果你把弹珠扔到碗里任何地方,它会滚到底部并停在那里。
那个底部点就是吸引子——系统自然移向的稳定状态。
在EqR中,“碗”是学习的潜在动力学,“底部”是有效解的潜在表示。
网络学习塑造景观,使得迭代更新函数将你拉向这些稳定点。
简单问题有深而明显的碗(快速收敛)。
困难问题有浅而复杂的碗(需要更多迭代才能沉降)。
- 测试时扩展: 大多数神经网络在推理时是固定的——你运行一次前向传播得到答案。
EqR让你在训练后用计算换准确率。
运行更多迭代(深度扩展)让困难问题收敛。
从不同起点运行多条轨迹(广度扩展)探索不同解盆。
这就像给模型”思考时间”而无需重新训练。
论文显示这能大幅扩展:相当于为极端数独谜题展开40,000层。
框架转变
之前(主流方法):              之后(本文方法):

输入 --> 模型 --> 输出          输入 --> 初始化潜在 z_0
        (固定深度)                      |
                                         v
  或                            +--------+--------+
                                | z_t+1 = f(z_t)  |
输入 --> 模型 --> 候选            +--------+--------+
        |                                |
        v                       (迭代直到稳定)
   验证器(外部)                         |
        |                                v
        v                       吸引子 z* --> 输出
   接受/拒绝                    (无外部验证器)

深度 = 架构                     深度 = 测试时选择
广度 = 束搜索(离散)            广度 = 轨迹聚合
从固定深度前馈或依赖验证器的搜索到具有自适应测试时扩展的学习吸引子动力学,核心转变是内化收敛准则。
专家评审
选题眼光: 真实缺口。
测试时计算扩展是热门话题(见o1、自洽方法),但机制故事一直含糊不清。
通过动力系统和吸引子来框定在智识上令人满意,并连接到优化和物理学的丰富文献。
不是人造的——这解决了迭代细化为何有效的真正谜题。
方法成熟度: 巧妙洞察,非蛮力。
吸引子框架优雅,但实现直截了当:训练带收敛损失的循环潜在模型。
深度/广度扩展一旦接受吸引子假设就很直观。
一个担忧:论文没有深入探索如何训练网络形成好的吸引子——它主要展示如果你迭代训练,吸引子会出现。
训练配方对实践者来说感觉规定不足。
实验诚意: 基线公平。
数独结果惊人(2.6% → 99%),但数独是这种方法的最佳场景(离散、可验证、定义良好的解空间)。
论文承认这点并在其他领域(逻辑、数学)测试,尽管不那么广泛。
40k层声称技术上正确但略有误导——是通过迭代的40k等效层,不是单个巨大网络。
收敛-准确率相关性有充分记录且令人信服。
写作功力: 摘要和引言强——清晰假设、干净框定。
方法部分密集,在深入方程前可以多建立直觉。
吸引子比喻被引入但未充分利用;
展示实际学习的吸引子景观的图会很有启发性。
相关工作部分彻底但读起来像清单。
用更多视觉辅助和具体例子重写方法部分会显著提升论文。
判决: 强接收 — 为理解迭代推理提供机制透镜(吸引子),展示无需验证器的戏剧性测试时扩展,并开启研究方向。
仅数独结果就证明发表合理,且框架足够通用以激发后续工作。
要点总结
对实践者: 如果你在构建迭代推理系统,用收敛目标训练(最小化迭代间变化)并在测试时监控收敛强度作为置信度代理。
不要在固定迭代次数停止——让模型告诉你何时完成。
对困难实例,在扩展广度(多条轨迹)前先扩展深度(更多迭代),因为深度更便宜。
对研究者: 吸引子框定建议新评估指标:测量正确解周围的”吸引盆”(你能扰动初始状态多远仍然收敛?)。
这可以替代或补充准确率。
此外,论文暗示训练动力学重要——训练期间收敛更快的网络可能形成更好的吸引子。
值得研究显式塑造吸引子景观的训练计划。
可迁移技术: 深度/广度扩展权衡适用于推理之外。
任何迭代细化模型(图像生成、蛋白质折叠、轨迹优化)都能从基于收敛信号的自适应测试时扩展中受益。
关键是训练模型收敛,而不仅仅是输出好答案。