Paper: 2603.12252 Authors: Xuanlang Dai, Yujie Zhou, Long Xing, Jiazi Bu, Xilin Wei, Yuhong Liu, Beichen Zhang, Kai Chen, Yuhang Zang Categories: cs.CV, cs.CL
The Gap
The standard playbook for hard visual reasoning tasks is: plug an MLLM into a diffusion transformer (DiT) as a text encoder, let it encode the prompt, and hand the embedding off to the denoising process. Works fine for “a red apple on a table.” Falls apart for “solve this 9x9 Sudoku grid.”
Two things go wrong. First, single-pass encoding never triggers chain-of-thought. MLLMs are known to reason better when they think step-by-step, but a one-shot encode call skips all of that — you get the model’s first instinct, not its considered answer. Second, even if the encoding were perfect, the guidance is frozen. The DiT denoises over dozens of steps, but it’s steering by the same fixed vector the whole time. Complex tasks need progressive decomposition — early steps should lay out structure, later steps should fill in details — but a static embedding can’t do that.
Prior work (standard MLLM-DiT pipelines) treated the MLLM as a smarter tokenizer. This paper treats it as a reasoner that needs to stay in the loop.
Problem: MLLM used as static encoder
    |
    v
Assumption 1: CoT requires iterative state updates, not one-shot encoding
Assumption 2: DiT denoising benefits from evolving guidance, not fixed vectors
    |
    v
Method:
  [Iterative Thought Guidance] --> refine latent thought states over steps
  [Terminal Thought Grounding]  --> anchor final state to ground-truth text
    |
    v
Evidence: Maze / TSP / VSP / Sudoku benchmarks, 92.1% avg, +8.3pp over best baseline
    |
    v
Conclusion: Endogenous CoT in the encoder + dynamic guidance in the decoder = better structured reasoning
The Increment
One sentence: Before this paper, MLLMs in diffusion pipelines were mute oracles consulted once; after it, they’re active reasoners whose thinking evolves in sync with the denoising process.
Core Mechanism
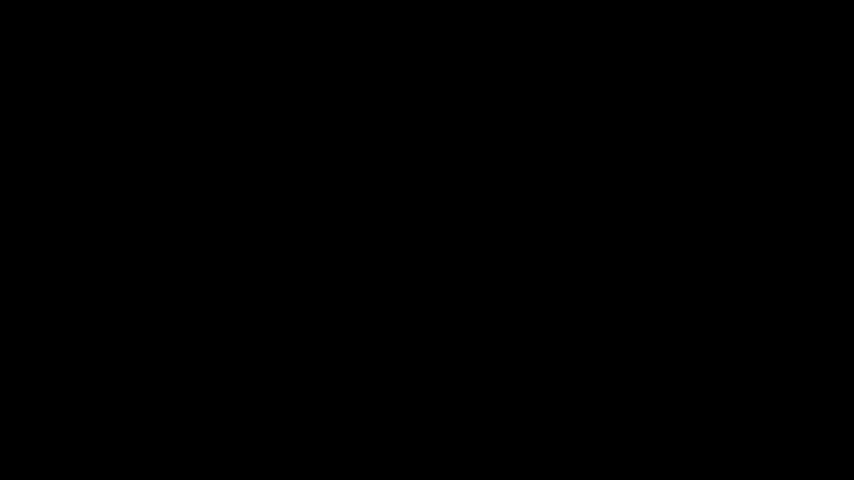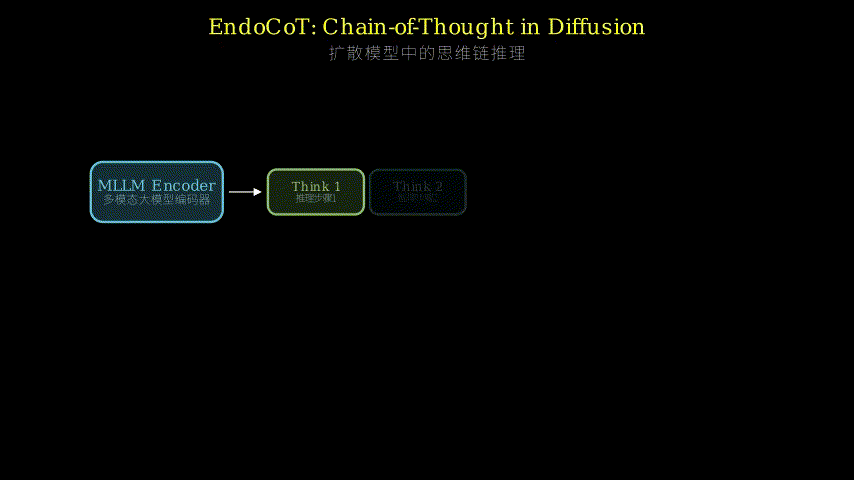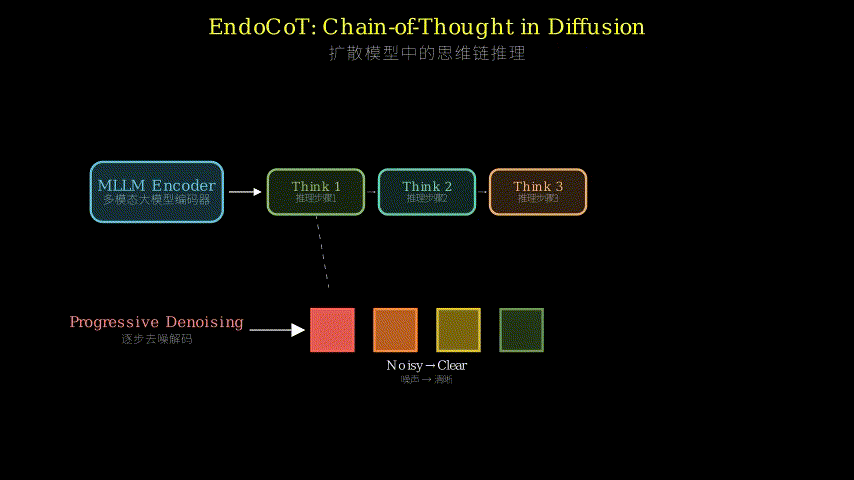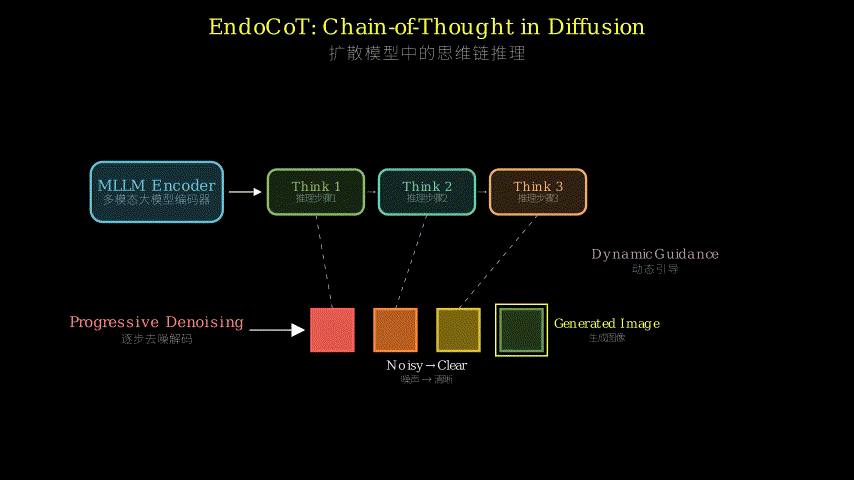
The framework has two interlocking pieces. The first is the Iterative Thought Guidance (ITG) module. Instead of encoding the prompt once, ITG maintains a latent “thought state” — a vector that gets updated across multiple rounds. At each round, the MLLM takes the current thought state plus the original prompt and produces a refined state. This is essentially unrolling the chain-of-thought process into the embedding space: each iteration is one reasoning step, and the state carries the accumulated reasoning forward.
The second piece is Terminal Thought Grounding (TTG). After the iterative refinement converges, you have a final thought state. TTG aligns this final state with the ground-truth answer text using a contrastive or alignment loss. This prevents the iterative process from drifting into some arbitrary latent region — it keeps the reasoning trajectory tethered to what the answer actually looks like in text space.
These two thought states — the evolving intermediate ones and the grounded final one — are then injected into the DiT’s cross-attention layers at different denoising timesteps. Early timesteps get earlier thought states (coarse reasoning), later timesteps get later ones (refined reasoning). The guidance is no longer a static vector; it’s a schedule.
Prompt
  |
  v
[MLLM Encoder]
  |
  v
Thought State t=0
  |
  +---> [ITG: MLLM(state_t, prompt) --> state_t+1] --+
  |                                                   |
  +<--------------------------------------------------+
  |   (repeat N times)
  v
Final Thought State
  |
  +---> [TTG: align(final_state, ground_truth_text)]
  |
  v
Thought State Schedule [s_0, s_1, ..., s_N]
  |
  v
DiT Denoising:
  step 1 <-- s_0 (coarse guidance)
  step 2 <-- s_1
  ...
  step T <-- s_N (fine-grained guidance)
  |
  v
Output Image / Solution
Think of it like a detective briefing a sketch artist. In the old approach, the detective describes the suspect once, the artist draws, done. In EndoCoT, the detective keeps refining their description as the sketch develops — “actually, the jaw was sharper, the eyes were closer together” — and the artist updates the drawing accordingly. The TTG module is like the detective checking their notes against a known photo at the end to make sure they haven’t drifted into fiction. The ITG module is the back-and-forth conversation. The thought state schedule is the sequence of revised briefs handed to the artist at each stage of the drawing.
Key Concepts
-
Chain-of-Thought in embedding space: Normally, CoT means generating intermediate text tokens (“first, I notice… then, I conclude…”). Here, CoT happens in the continuous latent space — no tokens are generated, but the thought state vector is iteratively updated in a way that mimics the reasoning trajectory. The intuition: if you run the MLLM’s attention layers repeatedly over the same input while carrying forward a state, you’re approximating what would happen if it wrote out its reasoning step by step.
-
Dynamic guidance scheduling: Standard diffusion conditioning gives the DiT one context vector for all timesteps. Dynamic scheduling means different timesteps receive different conditioning vectors. This matters because diffusion models are known to handle different aspects of generation at different noise levels — coarse structure early, fine details late. Matching the reasoning depth of the guidance to the denoising stage is the key structural insight here.
-
Terminal grounding: Without this, iterative refinement in latent space can wander. TTG is a regularizer that says “your final thought state must be close to the embedding of the correct answer.” It’s the difference between a student who thinks hard but goes off on a tangent versus one who keeps checking their work against the answer key.
Framework Shift
Before (mainstream approach):        After (this paper):

Prompt                               Prompt
  |                                    |
  v                                    v
[MLLM: encode once]                  [MLLM: iterate N times]
  |                                    |   state_0 -> state_1 -> ... -> state_N
  v                                    |                                   |
Fixed embedding e                      |                              [TTG: ground]
  |                                    v
  +---> DiT step 1                   Thought schedule [s_0..s_N]
  |                                    |
  +---> DiT step 2                     +---> DiT step 1 (guided by s_0)
  |                                    |
  +---> DiT step T                     +---> DiT step T (guided by s_N)
  |                                    |
  v                                    v
Output                               Output

Same e at every step                 Different s_i at each step
From static oracle to active co-reasoner, the core shift is: the MLLM’s reasoning and the DiT’s denoising are now temporally coupled, not sequentially decoupled.
Expert Assessment
Problem choice: This is a real gap. The mismatch between single-pass encoding and multi-step denoising has been quietly ignored because most diffusion tasks don’t need deep reasoning. As the field pushes into structured problem-solving (routing, constraint satisfaction, spatial planning), this mismatch becomes load-bearing. The paper is well-positioned on the field’s trajectory.
Method maturity: The core idea is clean and the two-module design is well-motivated. That said, the iterative thought guidance is essentially repeated MLLM forward passes, which is expensive. The paper doesn’t deeply engage with whether a lighter mechanism — say, a small recurrent module trained on top of frozen MLLM embeddings — could achieve similar results at a fraction of the cost. The “endogenous” framing is a bit generous; you’re still running the MLLM multiple times, which is more “iterative exogenous” than truly endogenous.
Experimental integrity: The benchmark suite (Maze, TSP, VSP, Sudoku) is reasonable for structured reasoning, but these are all combinatorial/algorithmic tasks. It’s not clear the gains transfer to more naturalistic spatial reasoning (e.g., compositional scene generation). The +8.3pp improvement is solid, but the paper should show ablations that isolate ITG vs TTG contributions more cleanly — if TTG alone gets you 6pp, the iterative part is less impressive than advertised.
Writing quality: The motivation section is strong. The weakest part is the analysis of why the method works — there’s no visualization of how thought states evolve across iterations, which would be the most convincing evidence that CoT is actually happening in latent space rather than just “more compute = better results.” Adding that would elevate the paper from “it works” to “here’s why it works.”
Verdict: weak accept — solid engineering contribution with a clean story, but needs stronger mechanistic evidence that the iterative reasoning is doing what the authors claim.
Takeaways
A few concrete things worth stealing:
-
The thought state schedule idea — mapping reasoning depth to denoising timestep — is transferable to any conditional generation task where the condition has internal structure. If you’re conditioning on a program, a proof, or a multi-step plan, you could similarly schedule which “stage” of the condition guides which denoising step.
-
TTG as a grounding regularizer is a lightweight trick: align your final latent state to a known-good text embedding before using it downstream. This is applicable anywhere you have iterative latent refinement and want to prevent drift.
-
The framing of “MLLM as reasoner, not tokenizer” is worth internalizing. If you’re building any pipeline that uses an LLM/MLLM as an encoder, ask whether single-pass encoding is actually sufficient for your task’s reasoning demands.
论文: 2603.12252 作者: Xuanlang Dai, Yujie Zhou, Long Xing, Jiazi Bu, Xilin Wei, Yuhong Liu, Beichen Zhang, Kai Chen, Yuhang Zang 分类: cs.CV, cs.CL
缺口
当前主流做法是把多模态大语言模型(MLLM)接到扩散变换器(DiT)前面当文本编码器。 对”桌上一个红苹果”这类任务,这套流程运转良好。 但遇到”解这道数独”或”找迷宫出口”,就开始露馅了。
问题出在两处。 第一,单次编码永远激活不了链式推理(CoT)。 MLLM 的推理能力依赖逐步展开的思维过程,但一次性的 encode 调用直接跳过了这个过程——你拿到的是模型的第一反应,不是深思熟虑后的答案。 第二,即便编码是准确的,这个指导信号在整个去噪过程中是冻结的。 DiT 要跑几十步去噪,却始终盯着同一个固定向量。 复杂任务需要逐步分解——早期步骤建立整体结构,后期步骤填充细节——但静态嵌入做不到这一点。
以往的工作把 MLLM 当成一个更聪明的分词器。 这篇论文把它当成一个需要全程参与的推理者。
问题:MLLM 被当作静态编码器使用
    |
    v
假设1:CoT 需要迭代状态更新,而非一次性编码
假设2:DiT 去噪受益于动态指导,而非固定向量
    |
    v
方法:
  [迭代思维指导 ITG] --> 跨步骤精炼潜在思维状态
  [终态思维锚定 TTG] --> 将最终状态对齐到真实答案文本
    |
    v
证据:Maze / TSP / VSP / Sudoku 基准,平均准确率 92.1%,超越最强基线 8.3 个百分点
    |
    v
结论:编码器端的内生 CoT + 解码器端的动态指导 = 更强的结构化推理能力
增量
一句话:这篇论文之前,扩散流程里的 MLLM 是被问一次就沉默的神谕;之后,它变成了与去噪过程同步演进的主动推理者。
核心机制
框架由两个相互咬合的模块构成。 第一个是迭代思维指导模块(ITG)。 它不再对提示词做一次性编码,而是维护一个潜在”思维状态”向量,并在多轮迭代中持续更新。 每一轮,MLLM 接收当前思维状态和原始提示词,输出一个精炼后的新状态。 这本质上是把链式推理过程展开到嵌入空间里:每次迭代是一个推理步骤,状态向量携带着累积的推理结果向前传递。
第二个模块是终态思维锚定(TTG)。 迭代精炼收敛后,你得到一个最终思维状态。 TTG 通过对比损失或对齐损失,把这个最终状态拉向真实答案的文本嵌入。 这防止了迭代过程在潜在空间里漫无目的地漂移——它把推理轨迹牢牢拴在”正确答案长什么样”这个锚点上。
这两类思维状态——迭代过程中的中间状态和最终锚定状态——随后按时间步注入 DiT 的交叉注意力层。 早期去噪步骤接收早期思维状态(粗粒度推理),后期步骤接收后期状态(精细推理)。 指导信号不再是静态向量,而是一张时间表。
提示词
  |
  v
[MLLM 编码器]
  |
  v
思维状态 t=0
  |
  +---> [ITG: MLLM(state_t, prompt) --> state_t+1] --+
  |                                                   |
  +<--------------------------------------------------+
  |   (重复 N 次)
  v
最终思维状态
  |
  +---> [TTG: align(final_state, ground_truth_text)]
  |
  v
思维状态时间表 [s_0, s_1, ..., s_N]
  |
  v
DiT 去噪过程:
  第 1 步 <-- s_0(粗粒度指导)
  第 2 步 <-- s_1
  ...
  第 T 步 <-- s_N(精细指导)
  |
  v
输出图像 / 解答
用一个比喻来理解这套机制:想象一位侦探在指导一位素描师画嫌疑人画像。 旧方法里,侦探描述一次,素描师画完,结束。 在 EndoCoT 里,侦探随着画像的推进不断修正描述——“下巴其实更尖,眼睛靠得更近”——素描师随之调整。 TTG 模块相当于侦探在最后把画像和一张已知照片比对,确保没有偏离现实。 ITG 模块是那一轮轮的来回对话。 思维状态时间表是侦探在每个绘画阶段递给素描师的修订简报。
关键概念
-
嵌入空间中的链式推理:通常意义上的 CoT 是生成中间文本 token(“首先我注意到……然后我得出……”)。 这里的 CoT 发生在连续潜在空间里——不生成任何 token,但思维状态向量被迭代更新,近似模拟了逐步推理的轨迹。 直觉上:如果你反复让 MLLM 的注意力层处理同一输入并携带前向状态,你就在近似它逐步写出推理过程时会发生的事。
-
动态指导调度:标准扩散条件给 DiT 的所有时间步提供同一个上下文向量。 动态调度意味着不同时间步接收不同的条件向量。 这很重要,因为扩散模型在不同噪声水平下处理生成的不同方面——早期处理粗粒度结构,后期处理精细细节。 把指导信号的推理深度与去噪阶段匹配起来,是本文最核心的结构性洞见。
-
终态锚定:没有这个机制,潜在空间里的迭代精炼会漫游。 TTG 是一个正则化器,它说:“你的最终思维状态必须接近正确答案的嵌入。” 这区分了两种学生:一种努力思考但跑偏了,另一种边思考边对照答案检验自己。
框架转变
之前(主流方法):                    之后(本文方法):

提示词                               提示词
  |                                    |
  v                                    v
[MLLM:编码一次]                     [MLLM:迭代 N 次]
  |                                    |  s_0 -> s_1 -> ... -> s_N
  v                                    |                         |
固定嵌入 e                             |                    [TTG 锚定]
  |                                    v
  +---> DiT 第 1 步                  思维状态时间表 [s_0..s_N]
  |                                    |
  +---> DiT 第 2 步                    +---> DiT 第 1 步(由 s_0 指导)
  |                                    |
  +---> DiT 第 T 步                    +---> DiT 第 T 步(由 s_N 指导)
  |                                    |
  v                                    v
输出                                 输出

每步都用同一个 e                     每步用不同的 s_i
从静态神谕到主动协同推理者,核心转变是:MLLM 的推理过程与 DiT 的去噪过程在时间维度上耦合了,而不再是顺序解耦的两个阶段。
专家评审
选题眼光:这是真实存在的缺口。 单次编码与多步去噪之间的错配长期被忽视,因为大多数扩散任务不需要深度推理。 随着领域向结构化问题求解(路径规划、约束满足、空间推理)推进,这个错配变得越来越关键。 论文的时机选得不错,站在了领域发展的合理节点上。
方法成熟度:核心思路干净,两模块设计动机充分。 但迭代思维指导本质上是反复跑 MLLM 前向传播,计算开销不小。 论文没有认真探讨一个更轻量的替代方案——比如在冻结 MLLM 嵌入上训练一个小型循环模块——是否能以更低代价达到类似效果。 “内生”(endogenous)这个标签有点过度包装:你仍然在多次调用 MLLM,叫”迭代外生”可能更准确。
实验诚意:基准套件(迷宫、TSP、VSP、数独)对结构化推理是合理的选择,但这些全是组合/算法类任务。 收益能否迁移到更自然的空间推理任务(比如组合场景生成)尚不清楚。 +8.3pp 的提升是实在的,但论文应该提供更干净的消融实验,把 ITG 和 TTG 各自的贡献分离出来——如果 TTG 单独就能带来 6pp,那迭代部分的价值就没有宣传的那么大。
写作功力:动机部分写得扎实。 最薄弱的地方是对”为什么有效”的分析——论文没有可视化思维状态在迭代过程中如何演变,而这恰恰是最有说服力的证据,能证明潜在空间里真的发生了 CoT,而不只是”更多计算 = 更好结果”。 补上这部分,论文就能从”它有效”升级到”这是它有效的原因”。
判决:弱接收——工程贡献扎实,叙事清晰,但缺乏足够强的机制性证据来支撑迭代推理真正在做作者所声称的事情。
要点总结
几个值得直接借用的具体想法:
思维状态调度的思路——把推理深度映射到去噪时间步——可以迁移到任何条件生成任务中,只要条件本身有内部结构。 如果你在用程序、证明或多步计划作为条件,同样可以调度”条件的哪个阶段”指导”哪个去噪步骤”。
TTG 作为锚定正则化器是个轻量技巧:在把最终潜在状态用于下游之前,把它对齐到一个已知的好的文本嵌入。 这适用于任何有迭代潜在精炼且需要防止漂移的场景。
“MLLM 作为推理者而非分词器”这个思维框架值得内化。 如果你在构建任何以 LLM/MLLM 作为编码器的流程,先问一句:单次编码对你任务的推理需求真的够用吗?