Paper: 2605.06663 Authors: Ryan Wang, Akshita Bhagia, Sewon Min Categories: cs.CL
The Gap
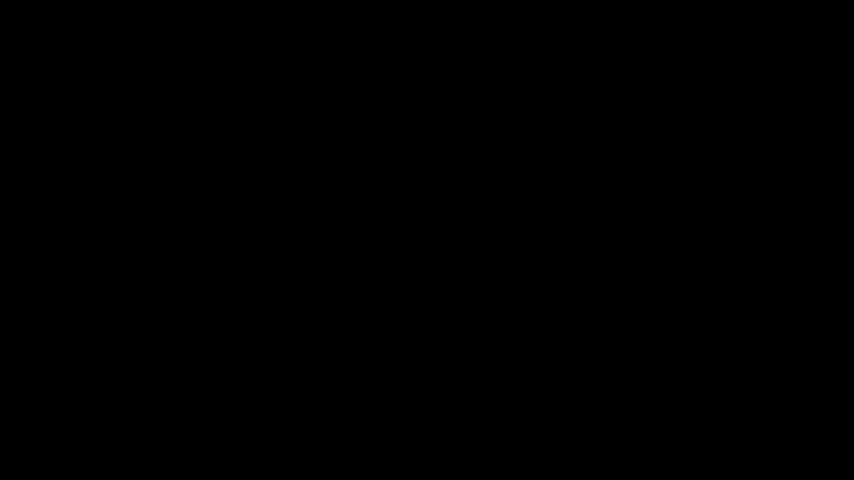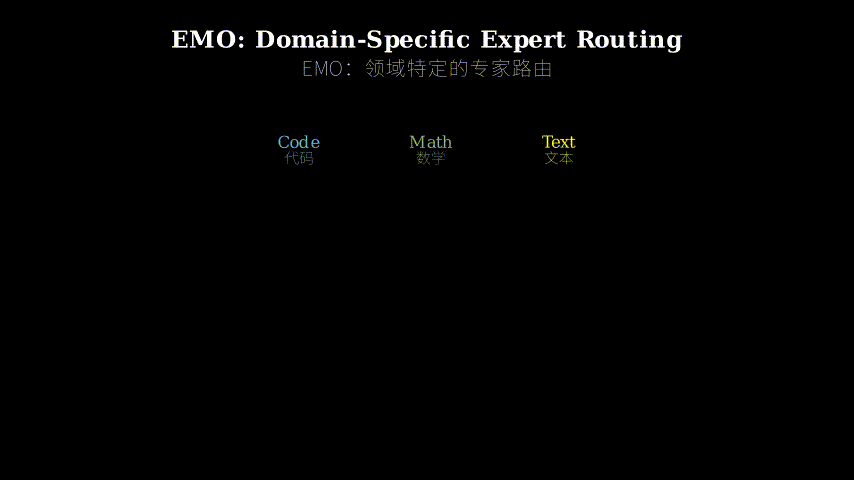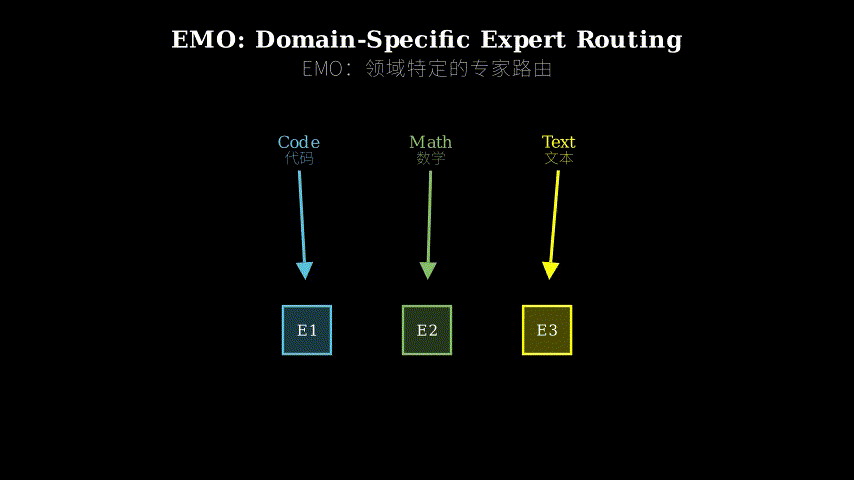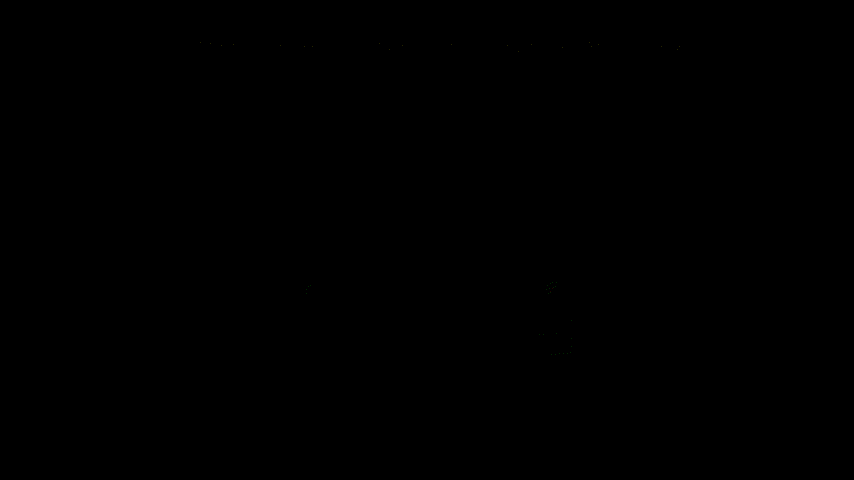
Standard MoEs activate sparse experts per token, promising efficiency. But when you try to deploy only a subset of experts for a specific domain (say, just the “math experts” for a calculator app), performance collapses. The model was never trained to work with partial expert sets—it learned entangled dependencies across all experts. This blocks memory-efficient deployment: you still need to load the full 14B model even if your app only needs 3B worth of capabilities.
Prior work either accepts this limitation (deploy everything) or uses human-defined expert assignments (code experts, math experts), which requires manual annotation and doesn’t scale. The gap: how do you train an MoE where expert subsets are independently functional, without human priors?
Problem: Standard MoE experts are entangled
   |
   v
Observation: Tokens in same document share domain
   |
   v
Method: Force document tokens to use shared expert pool
   |
   v
Evidence: 25% experts retained -> 1% performance drop
   |
   v
Conclusion: Emergent modularity enables subset deployment
The Increment
One sentence: Before EMO, deploying a subset of MoE experts meant broken models; after EMO, you can ship 25% of the experts and retain 99% of performance.
Core Mechanism
EMO adds one constraint during training: all tokens within a document must select experts from the same small pool (e.g., 4 experts out of 64 total). Different documents can use different pools, but within a document, the expert choice is shared. This forces the model to organize experts by domain—since documents are typically domain-coherent (a math paper uses math throughout, a code file uses code throughout), tokens from similar domains naturally converge on similar expert pools.
The architecture is otherwise standard: 8 MoE layers, each with 64 experts, top-2 routing per token. The key difference is the routing mechanism. Instead of each token independently picking 2 experts from all 64, the model first samples a pool of 4 experts for the entire document, then each token picks 2 from that pool. The pool is sampled using an aggregated routing score across all document tokens, ensuring coherence.
During inference, you can identify which expert subsets handle which domains (by analyzing routing patterns on domain-specific data), then deploy only those subsets. A code-focused app loads the 16 experts that activate on code; a math app loads a different 16. The model was trained to function this way, so performance degrades gracefully rather than collapsing.
Standard MoE:                    EMO:

Token1 ---> [64 experts]         Document boundary
Token2 ---> [64 experts]              |
Token3 ---> [64 experts]              v
  (independent routing)          [Sample pool: 4/64]
                                      |
                                      v
                                 Token1 ---> [4 experts]
                                 Token2 ---> [4 experts]
                                 Token3 ---> [4 experts]
                                   (shared pool)
Think of it like a restaurant kitchen. In a standard MoE, every dish (token) can call any chef (expert) from the entire kitchen—flexible but chaotic, and you can’t send half the chefs home without ruining service. EMO is like assigning a small team of chefs to each table (document). A table ordering Italian gets the Italian team; a table ordering sushi gets the sushi team. Each dish at the table still picks from its assigned team, but the team itself is coherent. Now you can run an Italian-only night with just the Italian chefs, and service works fine. The constraint (team per table) forces specialization to emerge naturally based on what customers order together.
Key Concepts
-
Document-level expert pooling: Instead of letting each token independently choose from all experts, EMO first selects a small subset of experts for the entire document, then restricts all tokens in that document to choose from that subset. This is implemented by computing an aggregated routing score across all document tokens, sampling a pool (e.g., 4 experts), then performing standard top-k routing within that pool. The key insight: documents are domain-coherent, so this constraint aligns expert selection with semantic domains without explicit labels.
-
Emergent modularity: The property that expert subsets become independently functional without being explicitly trained for independence. In standard MoEs, experts co-adapt—expert A learns to rely on expert B’s outputs downstream, creating entanglement. EMO’s document pooling breaks this: since different documents use different pools, an expert can’t rely on another expert always being present. This forces each expert to be more self-contained, and groups of experts that co-occur frequently (because they handle the same domain) naturally form coherent modules.
-
Semantic vs syntactic specialization: Standard MoEs show syntactic specialization—one expert handles punctuation, another handles capitalization, another handles specific token positions. These are low-level patterns that don’t correspond to human-meaningful categories. EMO’s experts show semantic specialization—one group handles math, another handles code, another handles legal text. This emerges because document pooling groups experts by the domains that co-occur within documents, which are semantic units. Semantic specialization is what enables practical subset deployment: you can ship “the math experts” because they form a coherent functional unit.
Framework Shift
Before (standard MoE):           After (EMO):

[All 64 experts]                 [All 64 experts]
       |                                |
   per-token                      per-document
    routing                         pooling
       |                                |
       v                                v
  Token uses                    Document uses
  any 2/64                      shared 4/64
                                       |
  (entangled,                    per-token
   not modular)                   routing
                                       |
                                       v
                                  Token uses
                                  any 2/4

                                  (modular,
                                   subset-deployable)
From token-level independence to document-level coherence, the core shift is trading routing flexibility for emergent structure.
Expert Assessment
Problem choice: Real gap. As models scale to 100B+ parameters, memory constraints become the bottleneck for deployment. The inability to use MoE subsets is a known pain point, not a manufactured problem. This sits at the intersection of efficiency and modularity, both hot topics.
Method maturity: Elegant insight, not brute force. The document pooling constraint is simple—almost trivial—but the emergent behavior is non-obvious. The risk: it relies on documents being domain-coherent, which is true for pretraining corpora but may not hold for all applications (e.g., multi-topic conversations). The paper doesn’t explore failure modes deeply.
Experimental integrity: Baselines are fair. The comparison to standard MoE is apples-to-apples (same architecture, same data, same compute). The subset deployment experiments are convincing: 25% retention with 1% drop is a clean result. However, the paper only tests on one model size (1B active, 14B total) and one dataset (1T tokens). Scaling behavior is unknown. The domain specialization analysis (Section 4.3) is qualitative—they show examples of expert routing on math/code, but don’t quantify purity or overlap rigorously.
Writing quality: The core idea is clear, but the paper front-loads motivation and delays the method until Section 3. Section 2 (related work) is dense and could be trimmed. The biggest weakness: the paper doesn’t discuss when document pooling might fail. What if documents are multi-domain? What if the corpus has poor document boundaries? These are practical concerns left unaddressed. Rewriting Section 5 (limitations and future work) to be more critical would elevate the paper.
Verdict: weak accept — Solves a real problem with a simple, effective method, but limited experimental scope and insufficient failure mode analysis prevent a strong accept.
Takeaways
Constraint-driven emergence: When you want a model to learn structure (modularity, specialization, composability), don’t annotate it—constrain the training dynamics to make that structure advantageous. EMO’s document pooling is a forcing function: it makes modular experts more efficient than entangled ones. This principle transfers: if you want disentangled representations, constrain what can interact; if you want hierarchical structure, constrain information flow across levels.
Semantic units as inductive bias: Documents are semantic units (mostly). By aligning model constraints with semantic boundaries, EMO gets semantic specialization for free. This is cheaper than human annotation and more robust than clustering embeddings post-hoc. Generalizes to other domains: use sentence boundaries for fine-grained tasks, use user sessions for personalization, use code functions for program synthesis.
Graceful degradation through modularity: The 25% → 1% drop result is the key practical win. If you’re building systems that need to scale down (edge deployment, cost optimization, A/B testing), design for subset functionality from the start. Retrofitting modularity onto a monolithic model is hard; training for it is easy if you pick the right constraints.
论文: 2605.06663 作者: Ryan Wang, Akshita Bhagia, Sewon Min 分类: cs.CL
缺口
标准的混合专家模型(MoE)对每个token稀疏激活专家,承诺提高效率。
但当你尝试只部署专家子集用于特定领域(比如只用”数学专家”做计算器应用)时,性能会崩溃。
模型从未被训练成能用部分专家工作——它学到的是所有专家之间的纠缠依赖。
这阻碍了内存高效部署:即使你的应用只需要3B的能力,你仍然需要加载完整的14B模型。
此前的工作要么接受这个限制(部署全部),要么使用人工定义的专家分配(代码专家、数学专家),这需要手动标注且无法扩展。
缺口在于:如何训练一个专家子集可以独立工作的MoE,且不需要人工先验?
问题:标准MoE专家相互纠缠
   |
   v
观察:同一文档内的token共享领域
   |
   v
方法:强制文档内token使用共享专家池
   |
   v
证据:保留25%专家 -> 性能仅降1%
   |
   v
结论:涌现的模块性支持子集部署
增量
一句话: EMO之前,部署MoE专家子集意味着模型损坏;
EMO之后,你可以只发布25%的专家,保留99%的性能。
核心机制
EMO在训练时增加一个约束:文档内所有token必须从同一个小池子(比如64个专家中的4个)选择专家。
不同文档可以使用不同的池子,但在文档内部,专家选择是共享的。
这迫使模型按领域组织专家——因为文档通常是领域连贯的(数学论文全程用数学,代码文件全程用代码),来自相似领域的token自然会收敛到相似的专家池。
架构本身是标准的:8个MoE层,每层64个专家,每个token选top-2。
关键区别在于路由机制。
不是每个token独立从64个专家中选2个,而是模型先为整个文档采样一个4专家的池子,然后每个token从这个池子里选2个。
池子的采样使用所有文档token的聚合路由分数,确保连贯性。
推理时,你可以识别哪些专家子集处理哪些领域(通过分析领域特定数据上的路由模式),然后只部署这些子集。
代码应用加载在代码上激活的16个专家;
数学应用加载另外16个。
模型被训练成这样工作,所以性能优雅降级而非崩溃。
标准MoE:                        EMO:

Token1 ---> [64个专家]           文档边界
Token2 ---> [64个专家]                |
Token3 ---> [64个专家]                v
  (独立路由)                   [采样池子:4/64]
                                      |
                                      v
                                 Token1 ---> [4个专家]
                                 Token2 ---> [4个专家]
                                 Token3 ---> [4个专家]
                                   (共享池子)
把它想象成餐厅厨房。
在标准MoE中,每道菜(token)可以叫整个厨房的任何厨师(expert)——灵活但混乱,而且你不能让一半厨师回家而不毁掉服务。
EMO像是给每张桌子(文档)分配一个小团队的厨师。
点意大利菜的桌子得到意大利团队;
点寿司的桌子得到寿司团队。
桌上的每道菜仍然从分配的团队中选择,但团队本身是连贯的。
现在你可以只用意大利厨师办一个意大利之夜,服务照常运转。
约束(每桌一个团队)根据顾客一起点的菜,自然地迫使专业化涌现。
关键概念
- 文档级专家池:不是让每个token独立从所有专家中选择,EMO先为整个文档选择一个小的专家子集,然后限制该文档中所有token从这个子集中选择。
实现方式是计算所有文档token的聚合路由分数,采样一个池子(比如4个专家),然后在这个池子内执行标准的top-k路由。
关键洞察:文档是领域连贯的,所以这个约束将专家选择与语义领域对齐,无需显式标签。
- 涌现的模块性:专家子集在没有被显式训练为独立的情况下,变得可以独立工作的性质。
在标准MoE中,专家会共同适应——专家A学会依赖下游专家B的输出,产生纠缠。
EMO的文档池打破了这一点:因为不同文档使用不同的池子,一个专家不能依赖另一个专家总是存在。
这迫使每个专家更加自包含,而频繁共现的专家组(因为它们处理相同领域)自然形成连贯的模块。
- 语义vs句法专业化:标准MoE显示句法专业化——一个专家处理标点,另一个处理大写,另一个处理特定token位置。
这些是低级模式,不对应人类有意义的类别。
EMO的专家显示语义专业化——一组处理数学,另一组处理代码,另一组处理法律文本。
这是因为文档池按文档内共现的领域对专家分组,而文档是语义单元。
语义专业化使实际的子集部署成为可能:你可以发布”数学专家”,因为它们形成了一个连贯的功能单元。
框架转变
之前(标准MoE):                之后(EMO):

[全部64个专家]                   [全部64个专家]
       |                                |
   每token                          每文档
    路由                             池化
       |                                |
       v                                v
  Token使用                        文档使用
  任意2/64                         共享4/64
                                       |
  (纠缠,                          每token
   非模块化)                         路由
                                       |
                                       v
                                  Token使用
                                  任意2/4

                                  (模块化,
                                   可子集部署)
从token级独立到文档级连贯,核心转变是用路由灵活性换取涌现结构。
专家评审
选题眼光:真实缺口。
随着模型扩展到100B+参数,内存约束成为部署的瓶颈。
无法使用MoE子集是已知痛点,不是人造问题。
这处于效率和模块性的交叉点,都是热门话题。
方法成熟度:优雅洞察,非蛮力。
文档池约束很简单——几乎平凡——但涌现行为并不明显。
风险:它依赖文档的领域连贯性,这对预训练语料库成立,但可能不适用于所有应用(比如多主题对话)。
论文没有深入探讨失败模式。
实验诚意:基线公平。
与标准MoE的比较是同等条件(相同架构、相同数据、相同计算)。
子集部署实验令人信服:保留25%损失1%是干净的结果。
然而,论文只测试了一个模型规模(1B激活,14B总量)和一个数据集(1T token)。
扩展行为未知。
领域专业化分析(第4.3节)是定性的——他们展示了数学/代码上的专家路由示例,但没有严格量化纯度或重叠。
写作功力:核心思想清晰,但论文前置动机,将方法推迟到第3节。
第2节(相关工作)密集,可以精简。
最大弱点:论文没有讨论文档池何时可能失败。
如果文档是多领域的怎么办?
如果语料库的文档边界很差怎么办?
这些是未解决的实际问题。
重写第5节(局限性和未来工作)使其更批判性,会提升论文。
判决:弱接收 — 用简单有效的方法解决真实问题,但实验范围有限且失败模式分析不足,无法达到强接收。
要点总结
约束驱动涌现:当你想让模型学习结构(模块性、专业化、可组合性)时,不要标注它——约束训练动态使该结构变得有利。
EMO的文档池是一个强制函数:它使模块化专家比纠缠专家更高效。
这个原则可迁移:如果你想要解耦表示,约束什么可以交互;
如果你想要层次结构,约束跨层级的信息流。
语义单元作为归纳偏置:文档是语义单元(大多数情况下)。
通过将模型约束与语义边界对齐,EMO免费获得语义专业化。
这比人工标注便宜,比事后聚类嵌入更鲁棒。
推广到其他领域:对细粒度任务使用句子边界,对个性化使用用户会话,对程序合成使用代码函数。
通过模块性实现优雅降级:25% → 1%降幅的结果是关键的实际胜利。
如果你在构建需要缩小规模的系统(边缘部署、成本优化、A/B测试),从一开始就设计子集功能。
将模块性改装到单体模型上很难;
如果你选对约束,训练它很容易。