Paper: 2604.01193 Authors: Ruixiang Zhang, Richard He Bai, Huangjie Zheng, Navdeep Jaitly, Ronan Collobert, Yizhe Zhang Categories: cs.CL
The Gap
Code generation models typically improve through three paths: reinforcement learning with verifiers (expensive, needs test cases), distillation from stronger teacher models (needs access to better models), or synthetic data generation (needs external tools). All require additional infrastructure beyond the model itself.
The boundary: Can a model improve at code generation using nothing but its own raw outputs? No verifier to check correctness, no teacher to learn from, no RL reward signal. Prior work assumed you need at least one of these external signals.
Problem: LLMs plateau without external feedback
   |
   v
Assumption: Models already know more than they show
   |                    (decoding constraints hide capability)
   v
Method: Sample diverse outputs → Filter → Fine-tune on filtered set
   |
   v
Evidence: +13% pass@1 on LiveCodeBench (42.4% → 55.3%)
   |
   v
Conclusion: Self-distillation works; gains from reshaping token distributions
The Increment
One sentence: Before this paper, improving code generation required external signals (verifiers/teachers/rewards); after, models can bootstrap from their own diverse outputs through simple supervised fine-tuning.
Core Mechanism
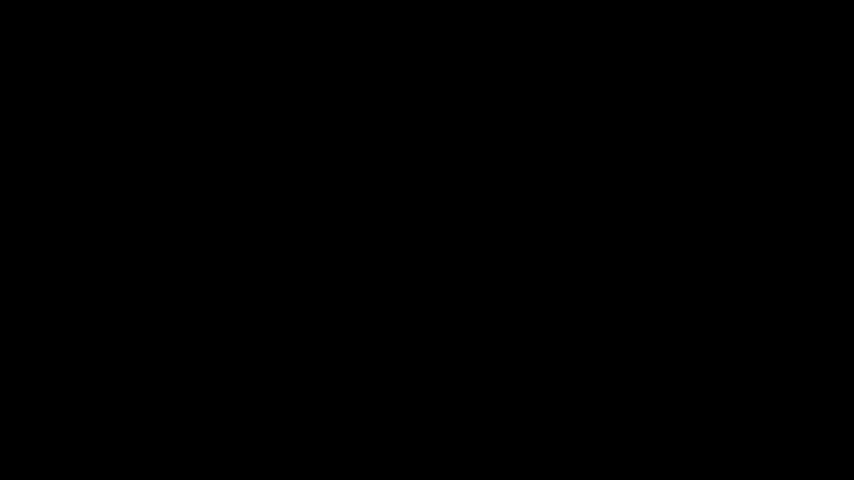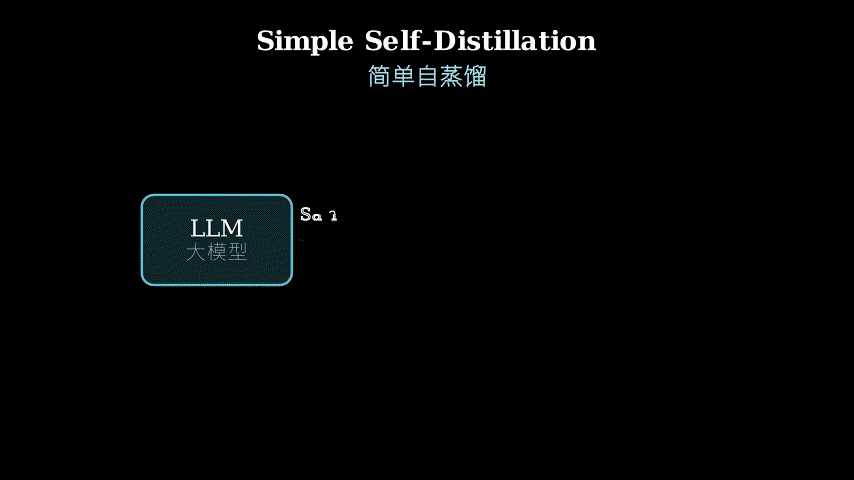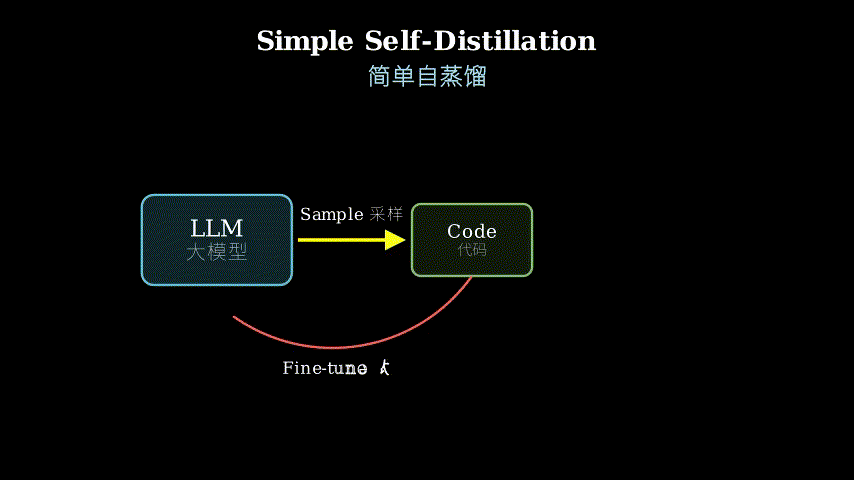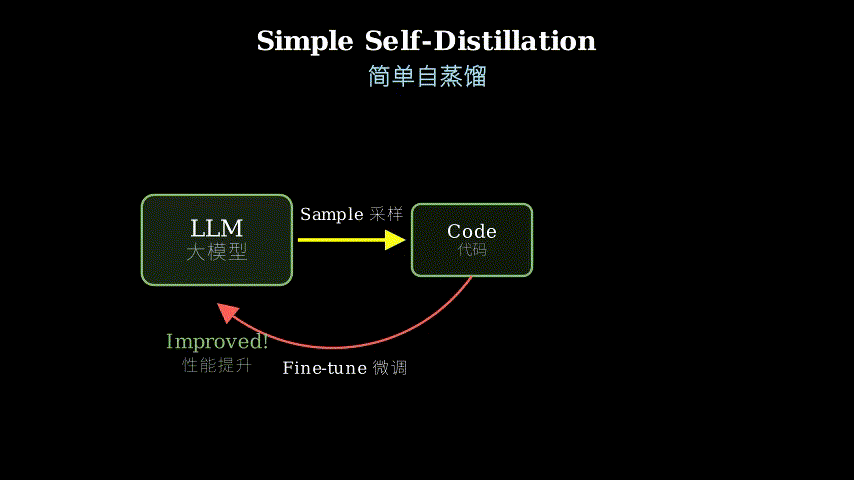
Simple Self-Distillation (SSD) has three steps. First, sample many solutions from the model using higher temperature (0.8) and nucleus sampling (top-p=0.95) to increase diversity. Second, filter these samples by a simple criterion: keep only solutions that pass basic syntax checks and execute without errors. Third, fine-tune the original model on this filtered dataset using standard supervised learning.
The data flow is circular: model → diverse samples → filter → training data → improved model. No external components enter this loop. The filtering step is deliberately minimal—just syntax and runtime checks, not correctness verification. This means the training set contains both correct and incorrect solutions, but all are at least well-formed code.
Original Model (T=0.6, top-p=0.9)
   |
   | sample with T=0.8, top-p=0.95
   v
[Raw Outputs: 100 solutions per problem]
   |
   | filter: syntax + runtime checks only
   v
[Filtered Set: ~30-50 solutions per problem]
   |
   | standard supervised fine-tuning
   v
Improved Model (same inference config)
Think of this like a jazz musician practicing improvisation. During practice (sampling), you play loosely, exploring variations you wouldn’t use in performance. You record these sessions, then listen back and identify passages that “work”—not necessarily perfect, but structurally sound. You drill those passages until they become part of your vocabulary. When you return to performance mode (inference), you haven’t learned new theory, but you’ve internalized patterns that were always in your capability range, just rarely surfaced under performance constraints.
The key insight: the model at temperature 0.8 explores solution spaces it knows but rarely visits at temperature 0.6. Fine-tuning on these explorations doesn’t teach new knowledge—it reshapes the probability landscape so useful patterns become more accessible during normal inference.
Key Concepts
-
Precision-Exploration Conflict: In code generation, some tokens demand precision (API names, syntax) while others benefit from exploration (algorithm choices, variable names). Standard decoding uses one temperature for everything, forcing a compromise. Low temperature gives precision but misses creative solutions; high temperature explores but makes syntax errors. SSD resolves this by training the model to internalize when to be precise vs exploratory, rather than forcing a global tradeoff at inference time. Concrete example: when generating
requests.get(url), the model must precisely output “requests” and “get”, but can explore different error-handling strategies. Single-temperature decoding can’t optimize both simultaneously. -
Self-Distillation Without a Teacher: Traditional distillation transfers knowledge from a large teacher to a small student. Here, the teacher and student are the same model at different decoding configurations. The “teacher” (high-temperature sampling) doesn’t know more facts—it explores more of the solution space. The “student” (fine-tuned model) learns to access those solutions without needing high temperature. It’s like distilling not knowledge but search strategy.
-
Distribution Reshaping: Fine-tuning doesn’t just increase probability of correct tokens—it changes how probability mass distributes across the vocabulary in context-dependent ways. In contexts requiring precision (like after
import), SSD suppresses the long tail of low-probability distractors. In contexts allowing exploration (like algorithm implementation), it preserves diversity. The paper shows this through token distribution analysis: entropy decreases in precision-critical positions, stays high in exploration-friendly positions.
Framework Shift
Before (mainstream approach):        After (this paper):

Model → [Verifier/Teacher/RL] → Improved Model
         ^
         |                              Model ──┐
    External Signal                            |
                                               | sample (high T)
                                               v
                                          [Raw Outputs]
                                               |
                                               | filter (minimal)
                                               v
                                          [Training Data]
                                               |
                                               | fine-tune
                                               v
                                          Improved Model
                                          (closed loop)
From external-signal-driven improvement to self-bootstrapping through decoding configuration diversity, the core shift is recognizing that capability gaps often reflect access problems, not knowledge gaps.
Expert Assessment
Problem choice: Real gap. The field has been stuck in an expensive equilibrium where improvement requires either massive compute (RL), proprietary models (distillation), or extensive test suites (verification). Showing that models can improve from their own outputs challenges the assumption that external signals are necessary. This sits at an interesting inflection point where models are capable enough that their diverse outputs contain signal, but not so capable that simple sampling already surfaces optimal solutions.
Method maturity: Embarrassingly simple, which is both strength and weakness. The method is literally “sample more, filter, fine-tune”—no novel algorithms. But simplicity here is a feature: it reveals that prior approaches may have been over-engineering. The precision-exploration framing is the real contribution, giving theoretical grounding to why such a naive method works. However, the paper doesn’t explore failure modes deeply—when does this stop working? What happens after multiple rounds?
Experimental integrity: Baselines are fair but limited. The paper compares against the base model and shows consistent gains across model families (Qwen, Llama) and sizes (4B-30B), which is strong. But it doesn’t compare against other self-improvement methods like self-consistency or rejection sampling at inference time. The filtering criterion (syntax + runtime) is suspiciously lenient—how much does training on incorrect-but-syntactic code hurt? The paper claims gains concentrate on harder problems but doesn’t show where the method fails. Ablations are solid (temperature, filtering threshold, data size) but miss some obvious experiments: what if you iterate SSD multiple times? Does it compound or saturate?
Writing quality: The precision-exploration framing in Section 4 is excellent and should have been frontloaded. The introduction buries the key insight under method description. Section 3 (experiments) is thorough but repetitive—the per-model-family results could be condensed into a single table with a summary paragraph. The related work section is perfunctory, missing connections to curriculum learning and self-play literature where similar bootstrapping dynamics appear. If the authors rewrote Section 1 to lead with the precision-exploration conflict and positioned SSD as a solution to that specific problem, the paper would be much stronger.
Verdict: weak accept — The core finding (self-distillation works for code generation) is valuable and the simplicity is refreshing, but the paper feels like it’s reporting a surprising empirical result without fully understanding why it works or when it breaks. The precision-exploration framing is underdeveloped. This is a strong workshop paper or a weak conference paper that needs one more revision to mature the theory.
Takeaways
Practitioners can steal the decoding configuration trick: when you need diverse outputs for any downstream task (not just fine-tuning), don’t just crank up temperature uniformly—use nucleus sampling with p=0.95 and temperature around 0.8, then filter aggressively. This explores more of the model’s capability range than standard sampling.
The precision-exploration lens transfers to any generation task with mixed constraints. In dialogue, some turns need factual precision (answering “what’s the capital of France?”) while others allow creativity (suggesting weekend plans). Current systems use one temperature for everything. You could apply SSD’s insight: sample diverse responses, filter for basic coherence, fine-tune to internalize when to be precise vs exploratory.
For code specifically: if you’re building on top of an LLM and can’t afford RL or don’t have test cases, SSD offers a cheap post-training step. Generate 50-100 solutions per problem in your domain, keep the syntactically valid ones, fine-tune. The paper shows this works even without correctness verification, which is surprising and useful.
The meta-lesson: before adding complex infrastructure (verifiers, teachers, RL), check if your model already has the capability but can’t access it under standard decoding. Sometimes the problem isn’t knowledge, it’s search.
论文: 2604.01193 作者: Ruixiang Zhang, Richard He Bai, Huangjie Zheng, Navdeep Jaitly, Ronan Collobert, Yizhe Zhang 分类: cs.CL
缺口
代码生成模型通常通过三条路径改进:带验证器的强化学习(昂贵,需要测试用例)、从更强教师模型蒸馏(需要访问更好的模型)、或合成数据生成(需要外部工具)。
所有这些都需要模型本身之外的额外基础设施。
边界在于:模型能否仅用自己的原始输出来改进代码生成?
没有验证器检查正确性,没有教师学习,没有强化学习奖励信号。
先前工作假设你至少需要这些外部信号之一。
问题:LLM在没有外部反馈时陷入瓶颈
   |
   v
假设:模型已经知道的比它展示的更多
   |                    (解码约束隐藏了能力)
   v
方法:采样多样输出 → 过滤 → 在过滤集上微调
   |
   v
证据:LiveCodeBench上pass@1提升13% (42.4% → 55.3%)
   |
   v
结论:自蒸馏有效;收益来自重塑token分布
增量
一句话: 这篇论文之前,改进代码生成需要外部信号(验证器/教师/奖励);之后,模型可以通过简单的监督微调从自己的多样输出中自举。
核心机制
简单自蒸馏(SSD)分三步。
第一步,使用更高温度(0.8)和核采样(top-p=0.95)从模型采样许多解决方案以增加多样性。
第二步,用简单标准过滤这些样本:只保留通过基本语法检查且执行无错误的解决方案。
第三步,在这个过滤数据集上用标准监督学习微调原始模型。
数据流是循环的:模型 → 多样样本 → 过滤 → 训练数据 → 改进模型。
没有外部组件进入这个循环。
过滤步骤刻意保持最小化——只做语法和运行时检查,不做正确性验证。
这意味着训练集包含正确和错误的解决方案,但都至少是格式良好的代码。
原始模型 (T=0.6, top-p=0.9)
   |
   | 用T=0.8, top-p=0.95采样
   v
[原始输出:每个问题100个解决方案]
   |
   | 过滤:仅语法+运行时检查
   v
[过滤集:每个问题约30-50个解决方案]
   |
   | 标准监督微调
   v
改进模型 (相同推理配置)
把这想象成爵士音乐家练习即兴演奏。
练习时(采样),你演奏得很松弛,探索你不会在表演中使用的变奏。
你录下这些练习,然后回听并识别”有效”的段落——不一定完美,但结构上合理。
你反复练习这些段落,直到它们成为你词汇的一部分。
当你回到表演模式(推理)时,你没有学习新理论,但你已经内化了那些一直在你能力范围内、只是在表演约束下很少浮现的模式。
关键洞察:温度0.8的模型探索它知道但在温度0.6时很少访问的解空间。
在这些探索上微调不是教新知识——而是重塑概率景观,让有用的模式在正常推理时更容易访问。
关键概念
- 精确性-探索性冲突: 在代码生成中,有些token需要精确(API名称、语法),而其他token受益于探索(算法选择、变量名)。
标准解码对所有内容使用一个温度,强制妥协。
低温度给出精确性但错过创造性解决方案;高温度探索但产生语法错误。
SSD通过训练模型内化何时精确vs探索来解决这个问题,而不是在推理时强制全局权衡。
具体例子:生成requests.get(url)时,模型必须精确输出”requests”和”get”,但可以探索不同的错误处理策略。
单温度解码无法同时优化两者。
- 无教师的自蒸馏: 传统蒸馏将知识从大教师转移到小学生。
这里,教师和学生是不同解码配置下的同一模型。
“教师”(高温采样)不知道更多事实——它探索更多解空间。
“学生”(微调模型)学会在不需要高温的情况下访问这些解决方案。
这就像蒸馏的不是知识而是搜索策略。
- 分布重塑: 微调不只是增加正确token的概率——它以上下文依赖的方式改变概率质量在词汇表上的分布。
在需要精确的上下文中(如import之后),SSD抑制低概率干扰项的长尾。
在允许探索的上下文中(如算法实现),它保持多样性。
论文通过token分布分析展示了这一点:熵在精确关键位置降低,在探索友好位置保持高位。
框架转变
之前(主流方法):                之后(本文方法):

模型 → [验证器/教师/强化学习] → 改进模型
         ^
         |                              模型 ──┐
    外部信号                                  |
                                             | 采样(高温)
                                             v
                                        [原始输出]
                                             |
                                             | 过滤(最小)
                                             v
                                        [训练数据]
                                             |
                                             | 微调
                                             v
                                        改进模型
                                        (闭环)
从外部信号驱动的改进到通过解码配置多样性的自举,核心转变是认识到能力差距通常反映访问问题,而非知识差距。
专家评审
选题眼光: 真实缺口。
该领域一直困在昂贵的均衡中,改进需要大量计算(强化学习)、专有模型(蒸馏)或广泛测试套件(验证)。
展示模型可以从自己的输出改进,挑战了外部信号必要的假设。
这处于一个有趣的拐点:模型足够强大,其多样输出包含信号,但又不够强大到简单采样就能浮现最优解。
方法成熟度: 简单得令人尴尬,这既是优点也是缺点。
方法字面上就是”多采样、过滤、微调”——没有新算法。
但这里简单是特性:它揭示了先前方法可能过度工程化。
精确性-探索性框架是真正的贡献,为如此朴素的方法为何有效提供了理论基础。
然而,论文没有深入探索失败模式——这何时停止工作?
多轮后会发生什么?
实验诚意: 基线公平但有限。
论文与基础模型比较,并展示在模型家族(Qwen、Llama)和规模(4B-30B)上的一致收益,这很有力。
但它没有与其他自改进方法比较,如推理时的自洽性或拒绝采样。
过滤标准(语法+运行时)宽松得可疑——在不正确但语法正确的代码上训练会造成多大伤害?
论文声称收益集中在更难的问题上,但没有展示方法在哪里失败。
消融实验扎实(温度、过滤阈值、数据大小),但错过了一些明显实验:如果多次迭代SSD会怎样?
它会复合还是饱和?
写作功力: 第4节的精确性-探索性框架很出色,应该前置。
引言把关键洞察埋在方法描述下。
第3节(实验)彻底但重复——每个模型家族的结果可以压缩成一个表格加摘要段落。
相关工作部分敷衍,缺少与课程学习和自博弈文献的联系,那里出现类似的自举动态。
如果作者重写第1节,以精确性-探索性冲突开头,并将SSD定位为该特定问题的解决方案,论文会强得多。
判决: 弱接收 — 核心发现(自蒸馏对代码生成有效)有价值,简单性令人耳目一新,但论文感觉像是在报告一个令人惊讶的经验结果,而没有完全理解它为何有效或何时失效。
精确性-探索性框架发展不足。
这是一篇强研讨会论文或弱会议论文,需要再修订一次以成熟理论。
要点总结
实践者可以偷走解码配置技巧:当你需要多样输出用于任何下游任务(不仅是微调)时,不要只是均匀提高温度——使用p=0.95的核采样和约0.8的温度,然后积极过滤。
这比标准采样探索更多模型的能力范围。
精确性-探索性视角迁移到任何具有混合约束的生成任务。
在对话中,有些轮次需要事实精确(回答”法国首都是什么?”),而其他轮次允许创造性(建议周末计划)。
当前系统对所有内容使用一个温度。
你可以应用SSD的洞察:采样多样响应,过滤基本连贯性,微调以内化何时精确vs探索。
对于代码具体而言:如果你在LLM之上构建且负担不起强化学习或没有测试用例,SSD提供了廉价的后训练步骤。
在你的领域为每个问题生成50-100个解决方案,保留语法有效的,微调。
论文显示即使没有正确性验证这也有效,这令人惊讶且有用。
元教训:在添加复杂基础设施(验证器、教师、强化学习)之前,检查你的模型是否已经具有能力但在标准解码下无法访问。
有时问题不是知识,而是搜索。