Paper: 2605.12498 Authors: Christen Millerdurai, Shaoxiang Wang, Yaxu Xie, Vladislav Golyanik, Didier Stricker, Alain Pagani Categories: cs.CV, cs.GR
The Gap
Monocular RGB methods for egocentric hand pose estimation have hit two walls. First, they suffer from depth-scale ambiguity—you can’t tell if a hand is small and close or large and far from a single image. Second, head-mounted devices use wildly different optics (fisheye, perspective, distorted wide-FOV), and current models need expensive device-specific datasets for each configuration. Training on HoloLens data doesn’t transfer to Quest, which doesn’t transfer to Magic Leap.
Prior work either ignores absolute scale (outputs relative pose) or assumes a fixed camera model. Methods like HaMeR and HAMER-Ego predict hand pose but not its absolute position in camera space. Device-specific approaches like those trained on H2O or AssemblyHands achieve good accuracy but collapse when the camera changes.
Problem: Monocular egocentric hand pose
    |
    v
Limitation 1: Depth-scale ambiguity
    |                    +---> Relative pose only (HaMeR, HAMER-Ego)
    +---> Prior work ----+
    |                    +---> Device-specific training (H2O, AssemblyHands)
    v
Limitation 2: Camera model diversity
    |
    v
Gap: No unified method for absolute 3D pose across camera types
    |
    v
EgoForce: Forearm as scale anchor + ray space solver
    |
    v
Evidence: 28% MPJPE reduction on HOT3D, consistent across fisheye/perspective
    |
    v
Conclusion: Forearm geometry breaks scale ambiguity; ray space enables cross-device generalization
The Increment
One sentence: Before EgoForce, you needed separate models for each head-mounted device and got only relative hand pose; after EgoForce, a single model outputs absolute 3D hand position across fisheye, perspective, and wide-FOV cameras.
Core Mechanism
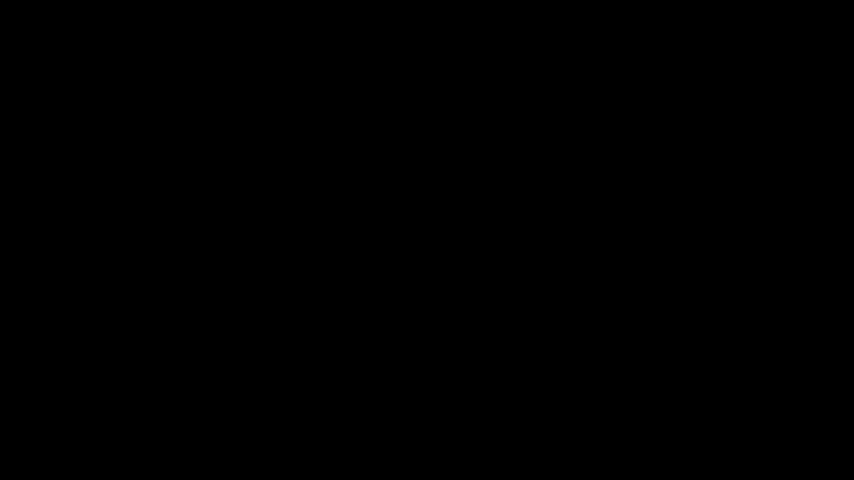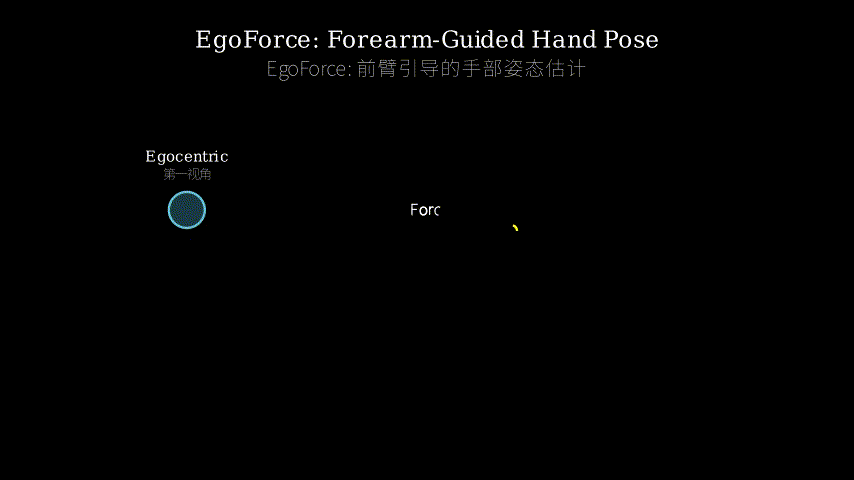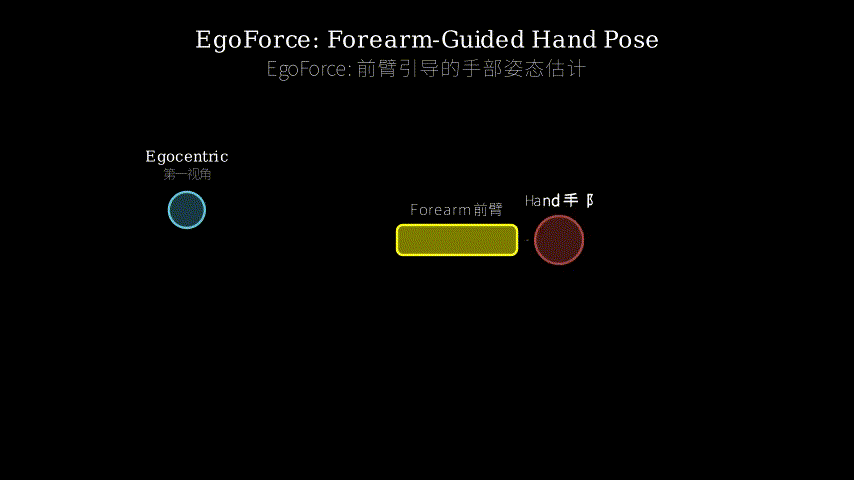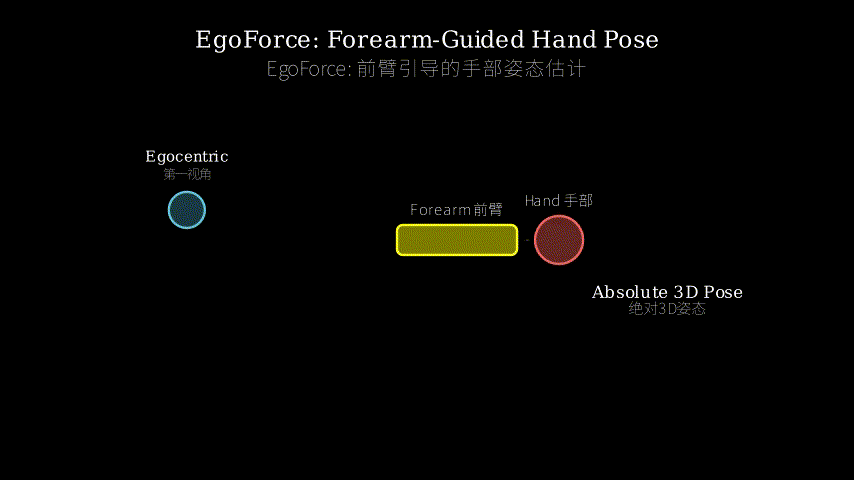
EgoForce has three components working in sequence. First, a differentiable forearm representation models the arm as a kinematic chain with known bone lengths (forearm is ~25cm in adults). This acts as a physical ruler in the scene. Second, a unified arm-hand transformer takes the egocentric image and predicts both hand joints and forearm geometry (elbow position, wrist orientation) in a shared latent space. The transformer is trained on data from multiple camera types simultaneously, learning camera-agnostic features. Third, a ray space closed-form solver takes the predicted 2D hand keypoints and forearm geometry, then solves for absolute 3D positions by intersecting rays from the camera with the forearm constraint.
Data flows like this: raw image → transformer → 2D keypoints + forearm parameters → ray space solver → absolute 3D hand pose in camera coordinates. The forearm acts as a scale reference—if you know the elbow-to-wrist distance is 25cm and you see both in the image, you can triangulate absolute depth. The ray space formulation handles different camera models (fisheye distortion, perspective projection) by working in a unified ray representation before projecting to 3D.
Input Image (fisheye/perspective/wide-FOV)
    |
    v
[Unified Arm-Hand Transformer]
    |
    +---> 2D hand keypoints (21 joints)
    |
    +---> Forearm geometry (elbow pos, wrist orient, bone lengths)
    |
    v
[Ray Space Solver]
    |  (intersect camera rays with forearm constraint)
    |
    v
Absolute 3D Hand Pose (camera space, metric scale)
Think of it like surveying land with a measuring tape. You’re standing on a hill (the camera) trying to map where someone’s hand is in 3D space. You can see the hand’s silhouette (2D keypoints), but you don’t know if it’s a child’s hand close by or an adult’s hand far away—that’s the scale ambiguity. Now imagine the person extends their arm, and you know their forearm is exactly 25cm long. That’s your measuring tape. You see where the elbow and wrist appear in your view, and because you know the real-world distance between them, you can calculate how far away the whole arm-hand system is. The “ray space solver” is like drawing sight lines from your eye through each joint you see, then finding where those lines must intersect in 3D to satisfy the constraint that the forearm is 25cm long. Different camera lenses (fisheye vs normal) bend those sight lines differently, but the measuring tape (forearm) stays the same length, so the math still works.
Key Concepts
-
Depth-scale ambiguity: In a single 2D image, a small object close to the camera looks identical to a large object far away—same pixel size, same shape. Without stereo vision or other depth cues, you can’t tell which is true. For hands, this means you can estimate joint angles (relative pose) but not absolute distance from the camera. Prior monocular methods output hand pose in a normalized coordinate system (e.g., root joint at origin, hand scaled to unit size), which is useless for AR/VR applications that need to know “is the hand 30cm or 60cm from my face?” EgoForce breaks this by using the forearm as a known-length reference—like holding a ruler in the scene.
-
Ray space representation: Different cameras project 3D points to 2D differently. A perspective camera uses linear projection (straight lines stay straight). A fisheye camera uses radial distortion (straight lines curve). Handling each requires different math. Ray space unifies this: instead of working with pixel coordinates (x, y), you work with the 3D ray direction from the camera center through each pixel. A 2D point (x, y) becomes a ray vector (dx, dy, dz). Now all camera models are just different ways to compute that ray direction. The solver works in ray space, so it doesn’t care whether the input was fisheye or perspective—it just sees rays and solves for 3D positions that project back onto those rays while satisfying the forearm constraint.
-
Differentiable forearm model: The forearm is modeled as a kinematic chain (shoulder → elbow → wrist) with fixed bone lengths. “Differentiable” means you can compute gradients through this model during training. Why does this matter? The network predicts forearm parameters (joint angles, positions), and the solver uses those to compute 3D hand pose. If the final 3D pose is wrong, gradients flow backward through the solver into the forearm parameters, teaching the network to predict better forearm geometry. This end-to-end training is why the forearm constraint actually helps—it’s not just a post-processing step, it’s baked into the learning process.
Framework Shift
Before (mainstream approach):        After (EgoForce):

Camera Image                         Camera Image
    |                                    |
    v                                    v
[Hand Pose Network]                  [Arm-Hand Transformer]
    |                                    |
    +---> Relative 3D pose               +---> 2D keypoints
          (normalized, no scale)         +---> Forearm geometry
    |                                    |
    v                                    v
Output: Hand shape/joints            [Ray Space Solver]
        in arbitrary scale               |  (forearm = scale anchor)
                                         v
Train separately for each            Output: Absolute 3D pose
camera type (fisheye, perspective)           in camera space

                                     Train once, works across
                                     all camera types
One sentence: From predicting relative hand pose per camera type to predicting absolute hand position via forearm-anchored ray solving across unified camera models, the core shift is treating the arm as a metric ruler rather than ignoring it.
Expert Assessment
Problem choice: Real gap. AR/VR applications genuinely need absolute hand position (not just pose) for interaction, and the device fragmentation problem is acute—every headset uses different optics. The forearm insight is clever: it’s always visible in egocentric views and provides a known-length reference. Not manufactured.
Method maturity: The forearm constraint is the key insight; the rest is solid engineering. The ray space formulation is elegant—it’s the right abstraction for handling diverse cameras. However, the paper doesn’t deeply explore failure modes: what happens when the forearm is occluded or foreshortened? The differentiable forearm model is standard inverse kinematics, not novel. The transformer architecture is off-the-shelf (ViT backbone). The novelty is in the combination, not individual components.
Experimental integrity: Baselines are fair (HaMeR, HAMER-Ego, recent egocentric methods). The 28% MPJPE reduction on HOT3D is substantial. Cross-dataset evaluation (HOT3D, H2O, AssemblyHands) strengthens the generalization claim. One concern: the paper doesn’t report failure rates or provide error analysis by hand pose (e.g., does it fail on extreme wrist angles?). Ablations are present but could be more thorough—what’s the contribution of each component in isolation?
Writing quality: The method section is dense and assumes familiarity with ray tracing and inverse kinematics. The forearm representation could be explained more intuitively upfront. The related work section is thorough but reads like a literature dump. The results section is strong—clear tables, good visualizations. If I were rewriting, I’d lead with the forearm-as-ruler intuition in the introduction and defer mathematical details to an appendix.
Verdict: weak accept — Solves a real problem with a clever insight (forearm as scale anchor) and demonstrates strong empirical results, but the method is more engineering than algorithmic breakthrough, and the evaluation could probe failure modes more deeply.
Takeaways
Forearm as a scale anchor: If your task involves estimating metric 3D properties from monocular images, look for a known-size reference in the scene. For hands, it’s the forearm. For faces, it could be interpupillary distance. For full-body pose, it could be torso height. The key is finding something that’s (1) always visible, (2) has low variance across people, and (3) can be modeled differentiably.
Ray space for camera unification: If you’re building a vision system that needs to work across different camera models (fisheye, perspective, omnidirectional), don’t write separate code paths for each. Convert pixel coordinates to 3D ray directions as early as possible, do all processing in ray space, then project back to pixels only at the end. This is a general pattern for camera-agnostic algorithms.
End-to-end differentiable constraints: When you have domain knowledge (e.g., bone lengths are fixed), encode it as a differentiable module in your network rather than as a post-processing step. This lets gradients flow through the constraint during training, which is more effective than trying to satisfy the constraint after the fact. The forearm model here is a good example—it’s not just used for inference, it’s part of the loss function during training.
论文: 2605.12498 作者: Christen Millerdurai, Shaoxiang Wang, Yaxu Xie, Vladislav Golyanik, Didier Stricker, Alain Pagani 分类: cs.CV, cs.GR
缺口
单目RGB方法在第一视角手部姿态估计上撞了两堵墙。
第一,深度尺度歧义——从单张图像无法判断手是小而近还是大而远。
第二,头戴设备使用的光学系统千差万别(鱼眼、透视、畸变广角),现有模型需要为每种配置准备昂贵的设备专用数据集。
在HoloLens上训练的模型无法迁移到Quest,Quest的模型也无法迁移到Magic Leap。
此前的工作要么忽略绝对尺度(输出相对姿态),要么假设固定的相机模型。
HaMeR和HAMER-Ego等方法预测手部姿态但不预测其在相机空间的绝对位置。
H2O或AssemblyHands等设备专用方法精度不错,但相机一换就崩溃。
问题:单目第一视角手部姿态
    |
    v
局限1:深度尺度歧义
    |                    +---> 仅相对姿态 (HaMeR, HAMER-Ego)
    +---> 此前工作 ------+
    |                    +---> 设备专用训练 (H2O, AssemblyHands)
    v
局限2:相机模型多样性
    |
    v
缺口:无统一方法跨相机类型输出绝对3D姿态
    |
    v
EgoForce:前臂作为尺度锚点 + 射线空间求解器
    |
    v
证据:HOT3D上MPJPE降低28%,鱼眼/透视间表现一致
    |
    v
结论:前臂几何打破尺度歧义;射线空间实现跨设备泛化
增量
一句话:EgoForce之前,每个头戴设备需要单独模型且只能得到相对手部姿态;EgoForce之后,单个模型在鱼眼、透视、广角相机间输出绝对3D手部位置。
核心机制
EgoForce有三个顺序工作的组件。
第一,可微前臂表示将手臂建模为已知骨长的运动链(成人前臂约25厘米)。
这充当场景中的物理标尺。
第二,统一臂-手Transformer接收第一视角图像,在共享潜空间中预测手部关节和前臂几何(肘部位置、腕部方向)。
Transformer同时在多种相机类型的数据上训练,学习相机无关特征。
第三,射线空间闭式求解器接收预测的2D手部关键点和前臂几何,通过相机射线与前臂约束的交点求解绝对3D位置。
数据流:原始图像 → Transformer → 2D关键点 + 前臂参数 → 射线空间求解器 → 相机坐标系中的绝对3D手部姿态。
前臂充当尺度参考——如果你知道肘到腕的距离是25厘米且在图像中看到两者,就能三角测量绝对深度。
射线空间表示在投影到3D前工作在统一射线表示中,从而处理不同相机模型(鱼眼畸变、透视投影)。
输入图像(鱼眼/透视/广角)
    |
    v
[统一臂-手Transformer]
    |
    +---> 2D手部关键点(21个关节)
    |
    +---> 前臂几何(肘位置、腕方向、骨长)
    |
    v
[射线空间求解器]
    |  (相机射线与前臂约束求交)
    |
    v
绝对3D手部姿态(相机空间,度量尺度)
把它想象成用卷尺测量土地。
你站在山上(相机)试图绘制某人手在3D空间的位置。
你能看到手的轮廓(2D关键点),但不知道是近处的小孩手还是远处的成人手——这就是尺度歧义。
现在想象那人伸出手臂,你知道他们的前臂正好25厘米长。
这就是你的卷尺。
你看到肘和腕在视野中的位置,因为知道它们之间的真实距离,就能计算整个臂-手系统有多远。
“射线空间求解器”就像从你眼睛通过每个看到的关节画视线,然后找到这些线在3D中必须相交的位置,以满足前臂长25厘米的约束。
不同相机镜头(鱼眼vs普通)会不同地弯曲这些视线,但卷尺(前臂)长度不变,所以数学仍然成立。
关键概念
- 深度尺度歧义:在单张2D图像中,靠近相机的小物体看起来与远离相机的大物体完全相同——像素大小相同、形状相同。
没有立体视觉或其他深度线索,无法判断哪个为真。
对于手,这意味着可以估计关节角度(相对姿态)但无法估计与相机的绝对距离。
此前的单目方法在归一化坐标系中输出手部姿态(例如根关节在原点,手缩放到单位大小),这对需要知道”手离我脸30厘米还是60厘米”的AR/VR应用毫无用处。
EgoForce通过使用前臂作为已知长度参考打破这一点——就像在场景中握着一把尺子。
- 射线空间表示:不同相机以不同方式将3D点投影到2D。
透视相机使用线性投影(直线保持直线)。
鱼眼相机使用径向畸变(直线弯曲)。
处理每种需要不同数学。
射线空间统一了这一点:不使用像素坐标(x, y),而是使用从相机中心穿过每个像素的3D射线方向。
2D点(x, y)变成射线向量(dx, dy, dz)。
现在所有相机模型只是计算该射线方向的不同方式。
求解器在射线空间工作,所以不关心输入是鱼眼还是透视——它只看到射线,求解投影回这些射线同时满足前臂约束的3D位置。
- 可微前臂模型:前臂被建模为固定骨长的运动链(肩→肘→腕)。
“可微”意味着训练期间可以通过该模型计算梯度。
为什么重要?网络预测前臂参数(关节角度、位置),求解器使用这些参数计算3D手部姿态。
如果最终3D姿态错误,梯度通过求解器反向流入前臂参数,教网络预测更好的前臂几何。
这种端到端训练是前臂约束真正有帮助的原因——它不只是后处理步骤,而是融入学习过程。
框架转变
之前(主流方法):                之后(EgoForce):

相机图像                          相机图像
    |                                 |
    v                                 v
[手部姿态网络]                    [臂-手Transformer]
    |                                 |
    +---> 相对3D姿态                  +---> 2D关键点
          (归一化,无尺度)            +---> 前臂几何
    |                                 |
    v                                 v
输出:任意尺度的                  [射线空间求解器]
      手部形状/关节                   |  (前臂 = 尺度锚点)
                                      v
为每种相机类型                    输出:相机空间中的
单独训练(鱼眼、透视)                  绝对3D姿态

                                  训练一次,适用于
                                  所有相机类型
一句话:从为每种相机类型预测相对手部姿态,到通过前臂锚定的射线求解在统一相机模型间预测绝对手部位置,核心转变是将手臂视为度量标尺而非忽略它。
专家评审
选题眼光:真实缺口。
AR/VR应用确实需要绝对手部位置(不只是姿态)来交互,设备碎片化问题很严重——每个头显使用不同光学系统。
前臂洞察很巧妙:它在第一视角中总是可见且提供已知长度参考。
不是人造问题。
方法成熟度:前臂约束是关键洞察;其余是扎实工程。
射线空间表示很优雅——是处理多样相机的正确抽象。
但论文没有深入探索失败模式:前臂被遮挡或透视缩短时会怎样?可微前臂模型是标准逆运动学,不新颖。
Transformer架构是现成的(ViT骨干)。
新颖性在组合,不在单个组件。
实验诚意:基线公平(HaMeR、HAMER-Ego、近期第一视角方法)。
HOT3D上28%的MPJPE降低很可观。
跨数据集评估(HOT3D、H2O、AssemblyHands)强化了泛化声明。
一个担忧:论文未报告失败率或按手部姿态提供误差分析(例如极端腕角度时是否失败?)。
消融实验存在但可以更彻底——每个组件单独的贡献是什么?
写作功力:方法部分密集,假设读者熟悉光线追踪和逆运动学。
前臂表示可以在前面更直观地解释。
相关工作部分很全面但读起来像文献堆砌。
结果部分很强——清晰的表格、好的可视化。
如果我重写,会在引言中先讲前臂作为标尺的直觉,将数学细节推迟到附录。
判决:弱接收 — 用巧妙洞察(前臂作为尺度锚点)解决真实问题并展示强实证结果,但方法更多是工程而非算法突破,评估可以更深入探查失败模式。
要点总结
前臂作为尺度锚点:如果你的任务涉及从单目图像估计度量3D属性,寻找场景中的已知尺寸参考。
对于手,是前臂。
对于脸,可能是瞳距。
对于全身姿态,可能是躯干高度。
关键是找到(1)总是可见、(2)人与人之间方差小、(3)可以可微建模的东西。
射线空间用于相机统一:如果你在构建需要跨不同相机模型(鱼眼、透视、全向)工作的视觉系统,不要为每种写单独代码路径。
尽早将像素坐标转换为3D射线方向,在射线空间做所有处理,然后仅在最后投影回像素。
这是相机无关算法的通用模式。
端到端可微约束:当你有领域知识(例如骨长固定)时,将其编码为网络中的可微模块而非后处理步骤。
这让梯度在训练期间流过约束,比事后试图满足约束更有效。
这里的前臂模型是好例子——它不只用于推理,而是训练期间损失函数的一部分。