Paper: 2603.16867 Authors: Yelysei Bondarenko, Thomas Hehn, Rob Hesselink, Romain Lepert, Fabio Valerio Massoli, Evgeny Mironov, Leyla Mirvakhabova, Tribhuvanesh Orekondy, Spyridon Stasis, Andrey Kuzmin Categories: cs.LG, cs.CL
The Gap
Chain-of-thought (CoT) reasoning in LLMs works brilliantly on servers but crashes into three walls on mobile: (1) verbose reasoning traces burn through tokens at 3-5x the rate of direct answers, (2) massive KV-cache footprints from long contexts exhaust device memory, and (3) existing distillation approaches copy the teacher’s wordy style verbatim, inheriting inefficiency. Prior work like knowledge distillation from GPT-4 or specialized reasoning models assumes unlimited compute—fine for cloud, fatal for a phone with 8GB RAM and battery constraints.
Problem: CoT reasoning too expensive for edge devices
   |
   v
Assumption: Reasoning capability can be compressed
            without losing accuracy
   |
   v
Method: LoRA adapters + RL budget forcing +
        dynamic switching + KV-cache sharing
   |
   v
Evidence: Qwen2.5-7B achieves 85%+ accuracy with
          40-60% token reduction on mobile
   |
   v
Conclusion: Practical on-device reasoning is feasible
            under strict resource constraints
The Increment
One sentence: Before this paper, you couldn’t run CoT reasoning on phones without killing the battery or waiting forever; after, you can toggle reasoning on-demand with compressed traces that fit in mobile memory.
Core Mechanism
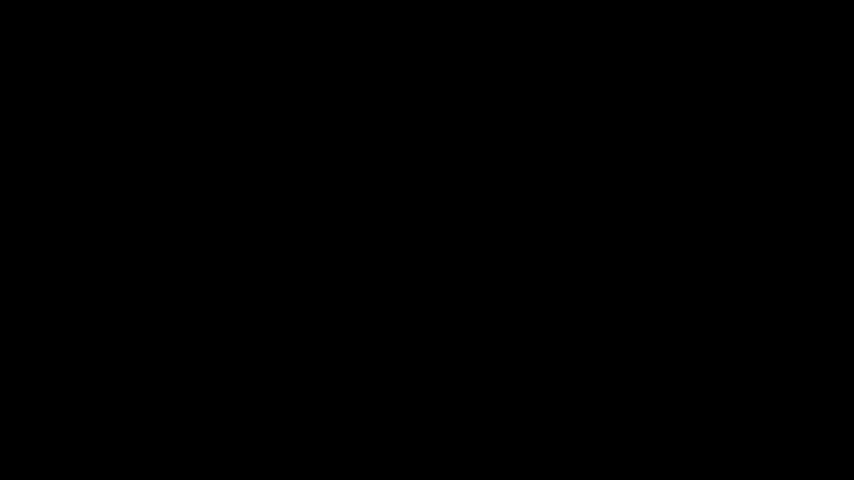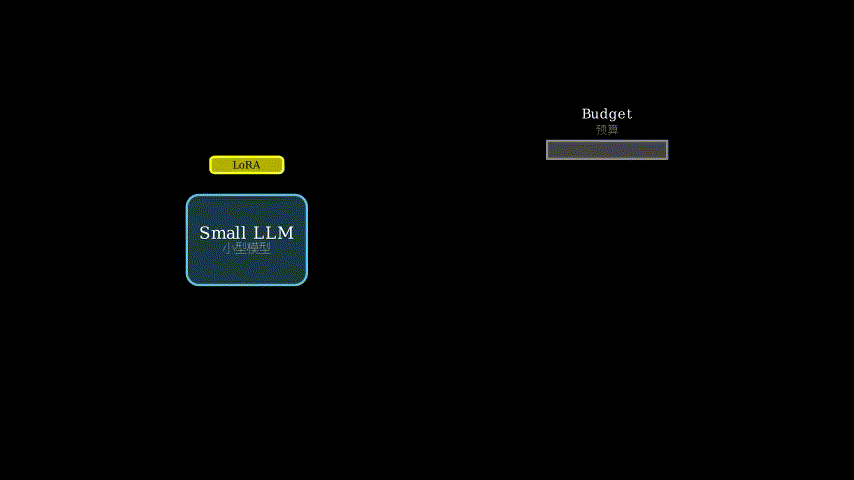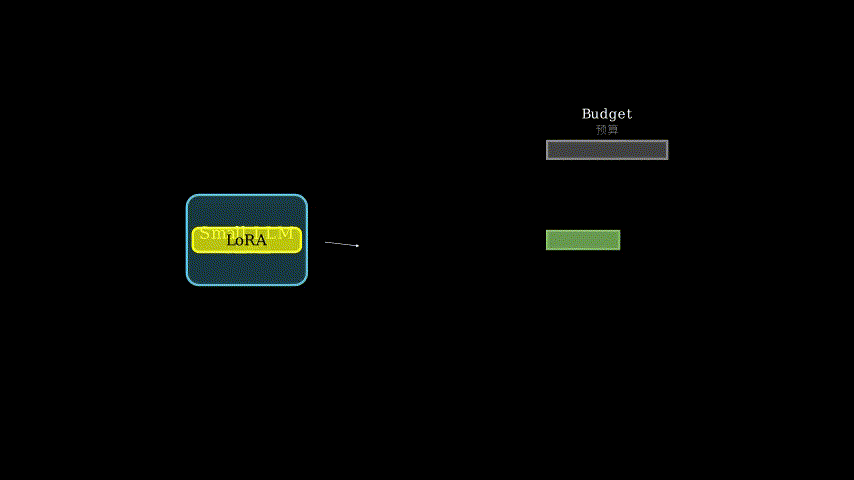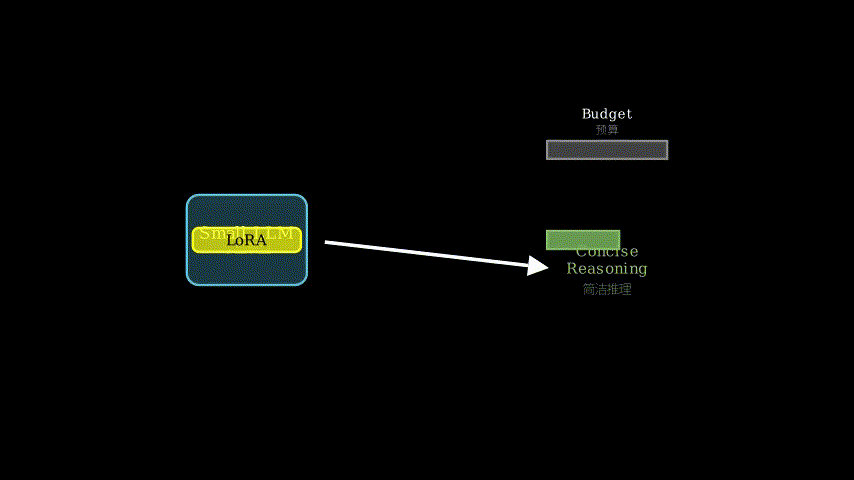
The method has four interlocking pieces. First, they train lightweight LoRA adapters on top of a small base model (Qwen2.5-7B) using supervised fine-tuning on reasoning datasets. These adapters learn to generate reasoning traces without retraining the entire model. Second, they apply reinforcement learning with a “budget forcing” reward that penalizes long responses—the model learns to compress its reasoning while maintaining correctness. Third, they introduce parallel test-time scaling where multiple reasoning paths run simultaneously, picking the best answer (trading slight latency for accuracy). Fourth, they build a dynamic switching mechanism that activates the reasoning adapter only when the problem needs it, plus a KV-cache sharing trick during prompt encoding that reuses cached computations across adapter switches.
Input Question
      |
      v
[Router] --no--> [Base Model] --> Quick Answer
      |
     yes
      |
      v
[LoRA Reasoning Adapter]
      |
      +---> [Parallel Path 1] --+
      |                          |
      +---> [Parallel Path 2] ---+--> [Vote/Select]
      |                          |        |
      +---> [Parallel Path 3] --+         v
                                    Final Answer
      ^
      |
[RL Budget Forcing: reward = accuracy - λ*length]
Think of this like a restaurant kitchen with different stations. The base model is your line cook who handles routine orders fast. The LoRA adapter is a specialist chef who only comes in for complex dishes. The RL budget forcing is the head chef constantly yelling “less garnish, same taste!”—training the specialist to plate beautifully without unnecessary flourishes. The parallel test-time scaling is like having three cooks make the same dish simultaneously and picking the best one. The dynamic switching is the expediter who decides whether to call in the specialist or let the line cook handle it. The KV-cache sharing is prep work done once and reused—chopped onions that both stations can grab from the same container instead of each chopping their own.
Key Concepts
-
LoRA (Low-Rank Adaptation): Instead of retraining all 7 billion parameters of your model, you freeze the base weights and add tiny “adapter” layers with maybe 0.1% of the parameters. These adapters learn task-specific behavior by modifying the model’s internal representations through low-rank matrix updates. Imagine you have a massive encyclopedia—instead of rewriting the whole thing to add medical knowledge, you clip in a thin supplement booklet that redirects certain lookups. Training the booklet is cheap; the encyclopedia stays intact.
-
Budget Forcing via RL: Standard training optimizes for accuracy alone. Budget forcing adds a penalty term for response length to the reward function: reward = accuracy - λ × token_count. The model learns through trial and error (reinforcement learning) that verbose reasoning gets punished even if correct. It’s like training a lawyer to win cases in 5 minutes instead of 50—same verdict, tighter argument. The λ parameter controls the trade-off: higher λ means more aggressive compression.
-
KV-Cache Sharing: During transformer decoding, each token’s key-value pairs get cached to avoid recomputing them. When you switch adapters mid-generation, naively you’d rebuild the cache from scratch. This paper shares the prompt’s KV-cache across adapter switches—the base model processes the question once, caches it, and both the base model and reasoning adapter reuse that cache. It’s like two people reading the same document: instead of each making their own notes, they share one set of annotations.
Framework Shift
Before (mainstream approach):        After (this paper):

[Large Teacher Model]                [Small Base Model]
         |                                   |
    Generate CoT                        [LoRA Adapter]
         |                                   |
    [Distillation]                    [RL Budget Forcing]
         |                                   |
    [Small Model]                      Compressed CoT
         |                                   |
    Verbose CoT                        [Dynamic Switch]
    (3-5x tokens)                           |
         |                            Activate only when needed
    High memory                              |
    Always-on reasoning              [KV-Cache Sharing]
                                             |
                                      Low memory footprint
[One sentence: From always-on verbose reasoning distilled from giants to on-demand compressed reasoning learned through budget constraints, the core shift is treating reasoning as a switchable capability with explicit resource awareness.]
Expert Assessment
Problem choice: Real gap. Edge deployment of LLMs is a massive practical bottleneck—everyone wants ChatGPT on their phone but nobody wants to drain their battery in 20 minutes. The paper targets the right constraint: reasoning is expensive, but not every query needs it. The gap sits at the intersection of model compression and reasoning, which is timely given the push toward on-device AI.
Method maturity: Mostly clever assembly of existing techniques rather than fundamental innovation. LoRA is standard, RL for length control has been explored, parallel decoding is known. The novelty is in the combination and the specific application to edge reasoning. The dynamic switching mechanism is the most interesting piece—it’s simple but addresses a real inefficiency (why pay reasoning costs for “what’s 2+2?”). The KV-cache sharing is a solid engineering insight but not groundbreaking.
Experimental integrity: Experiments are on Qwen2.5-7B only, which limits generalizability claims. They show 40-60% token reduction with “minimal accuracy loss” but don’t define “minimal” precisely across all tasks. The baselines are reasonable (standard distillation, base model without adapters) but missing comparisons to other compression methods like pruning or quantization combined with reasoning. The mobile device demos are compelling but lack detailed latency/energy breakdowns. I’d want to see ablations on the λ parameter sweep and failure case analysis.
Writing quality: The abstract oversells slightly (“state-of-the-art performance” is vague). The method section is dense—the four components could be introduced with clearer motivation for why each is necessary. The related work section lumps together distillation and edge deployment without drawing sharp distinctions. If they rewrote Section 3 to lead with the problem decomposition (memory, latency, accuracy) and then show how each component addresses one constraint, the paper would be much clearer.
Verdict: weak accept — Solid engineering contribution with practical impact, but incremental on the research front; the combination is useful even if the pieces aren’t novel.
Takeaways
The dynamic switching mechanism is immediately transferable: don’t run expensive models on every input, build a cheap router to decide when complexity is warranted. The RL budget forcing technique (reward = accuracy - λ × cost) is a general pattern for any resource-constrained generation task—summarization, code generation, dialogue. The KV-cache sharing insight applies anywhere you’re switching between model variants mid-generation (adapters, different quantization levels, ensemble members). The broader lesson: when deploying to constrained environments, make resource consumption a first-class optimization target during training, not just an afterthought during inference.
论文: 2603.16867 作者: Yelysei Bondarenko, Thomas Hehn, Rob Hesselink, Romain Lepert, Fabio Valerio Massoli, Evgeny Mironov, Leyla Mirvakhabova, Tribhuvanesh Orekondy, Spyridon Stasis, Andrey Kuzmin 分类: cs.LG, cs.CL
缺口
大模型的链式思维(CoT)推理在服务器上表现出色,但在移动设备上撞上三堵墙:(1)冗长的推理轨迹消耗的 token 是直接回答的 3-5 倍,(2)长上下文产生的巨大 KV 缓存占满设备内存,(3)现有的蒸馏方法逐字复制教师模型的啰嗦风格,继承了低效问题。
先前工作如从 GPT-4 蒸馏知识或专门的推理模型,都假设算力无限——在云端没问题,在只有 8GB 内存和电池限制的手机上就是致命伤。
问题:CoT 推理对边缘设备太昂贵
   |
   v
假设:推理能力可以压缩而不损失准确率
   |
   v
方法:LoRA 适配器 + 强化学习预算约束 +
      动态切换 + KV 缓存共享
   |
   v
证据:Qwen2.5-7B 在移动设备上达到 85%+ 准确率,
      token 减少 40-60%
   |
   v
结论:在严格资源约束下,设备端推理可行
增量
一句话:这篇论文之前,你无法在手机上运行 CoT 推理而不耗尽电池或等到天荒地老;之后,你可以按需开启推理,压缩后的轨迹能装进移动设备内存。
核心机制
方法有四个互锁的部分。
首先,他们在小型基础模型(Qwen2.5-7B)之上训练轻量级 LoRA 适配器,使用推理数据集进行监督微调。
这些适配器学会生成推理轨迹,无需重新训练整个模型。
其次,他们应用强化学习的”预算约束”奖励机制,惩罚过长的响应——模型学会压缩推理同时保持正确性。
第三,他们引入并行测试时扩展,多条推理路径同时运行,选择最佳答案(用轻微延迟换准确率)。
第四,他们构建动态切换机制,仅在问题需要时激活推理适配器,加上提示编码期间的 KV 缓存共享技巧,在适配器切换时重用缓存计算。
输入问题
      |
      v
[路由器] --否--> [基础模型] --> 快速回答
      |
     是
      |
      v
[LoRA 推理适配器]
      |
      +---> [并行路径 1] --+
      |                     |
      +---> [并行路径 2] ----+--> [投票/选择]
      |                     |        |
      +---> [并行路径 3] --+         v
                                 最终答案
      ^
      |
[强化学习预算约束:奖励 = 准确率 - λ*长度]
把这想象成一个餐厅厨房的不同工作站。
基础模型是你的流水线厨师,快速处理常规订单。
LoRA 适配器是专业大厨,只在复杂菜品时才出场。
强化学习预算约束是主厨不断喊”少装饰,同样味道!“——训练专业厨师摆盘精美但不浪费。
并行测试时扩展像是让三个厨师同时做同一道菜,选最好的那份。
动态切换是传菜员,决定是叫专业厨师还是让流水线厨师处理。
KV 缓存共享是一次性完成的备菜工作——切好的洋葱两个工作站都能从同一个容器里拿,而不是各切各的。
关键概念
- LoRA(低秩适配):不重新训练模型的全部 70 亿参数,而是冻结基础权重,添加只占 0.1% 参数量的微小”适配器”层。
这些适配器通过低秩矩阵更新修改模型内部表示,学习特定任务行为。
想象你有一本巨大的百科全书——不是重写整本书来添加医学知识,而是夹进一本薄薄的补充小册子,重定向某些查询。
训练小册子很便宜;百科全书保持原样。
- 强化学习预算约束:标准训练只优化准确率。
预算约束在奖励函数中添加响应长度的惩罚项:奖励 = 准确率 - λ × token 数量。
模型通过试错(强化学习)学到,冗长的推理即使正确也会被惩罚。
这就像训练律师在 5 分钟而非 50 分钟内赢得案件——同样的判决,更紧凑的论证。
λ 参数控制权衡:λ 越高,压缩越激进。
- KV 缓存共享:在 transformer 解码期间,每个 token 的键值对被缓存以避免重复计算。
当你在生成中途切换适配器时,天真的做法是从头重建缓存。
本文在适配器切换时共享提示的 KV 缓存——基础模型处理问题一次,缓存它,基础模型和推理适配器都重用该缓存。
这就像两个人读同一份文档:不是各自做笔记,而是共享一套注释。
框架转变
之前(主流方法):                之后(本文方法):

[大型教师模型]                    [小型基础模型]
         |                               |
    生成 CoT                        [LoRA 适配器]
         |                               |
    [蒸馏]                          [强化学习预算约束]
         |                               |
    [小型模型]                      压缩后的 CoT
         |                               |
    冗长的 CoT                      [动态切换]
    (3-5倍 token)                        |
         |                          仅在需要时激活
    高内存占用                            |
    推理始终开启                    [KV 缓存共享]
                                         |
                                    低内存占用
[一句话:从始终开启的、从巨型模型蒸馏的冗长推理,到按需开启的、通过预算约束学习的压缩推理,核心转变是将推理视为可切换的能力,并明确感知资源。]
专家评审
选题眼光:真实缺口。
大模型的边缘部署是巨大的实践瓶颈——每个人都想在手机上用 ChatGPT,但没人想 20 分钟就耗尽电池。
论文瞄准了正确的约束:推理昂贵,但不是每个查询都需要它。
这个缺口位于模型压缩和推理的交叉点,在设备端 AI 的推动下很及时。
方法成熟度:主要是现有技术的巧妙组装,而非根本性创新。
LoRA 是标准技术,用强化学习控制长度已有探索,并行解码是已知方法。
新颖性在于组合方式和对边缘推理的具体应用。
动态切换机制是最有趣的部分——简单但解决了真实的低效问题(为什么”2+2等于几”也要付推理成本?)。
KV 缓存共享是扎实的工程洞察,但不算突破性。
实验诚意:实验只在 Qwen2.5-7B 上进行,限制了泛化性声明。
他们展示了 40-60% 的 token 减少和”最小准确率损失”,但没有在所有任务上精确定义”最小”。
基线合理(标准蒸馏、无适配器的基础模型),但缺少与其他压缩方法(如剪枝或量化结合推理)的比较。
移动设备演示令人信服,但缺乏详细的延迟/能耗分解。
我想看 λ 参数扫描的消融实验和失败案例分析。
写作功力:摘要略有夸大(“最先进性能”很模糊)。
方法部分密集——四个组件可以用更清晰的动机引入,说明为什么每个都必要。
相关工作部分把蒸馏和边缘部署混在一起,没有划清界限。
如果他们重写第 3 节,先提出问题分解(内存、延迟、准确率),然后展示每个组件如何解决一个约束,论文会清晰得多。
判决:弱接收 — 扎实的工程贡献,有实际影响,但在研究前沿是渐进式的;组合有用,即使各部分不新颖。
要点总结
动态切换机制可立即迁移:不要在每个输入上运行昂贵模型,构建廉价路由器决定何时需要复杂性。
强化学习预算约束技术(奖励 = 准确率 - λ × 成本)是任何资源受限生成任务的通用模式——摘要、代码生成、对话。
KV 缓存共享洞察适用于任何在生成中途切换模型变体的场景(适配器、不同量化级别、集成成员)。
更广泛的教训:部署到受限环境时,在训练期间将资源消耗作为一等优化目标,而不仅仅是推理时的事后考虑。