Paper: 2605.02794 Authors: Srinivas Soumitri Miriyala, Sowmya Vajrala, Sravanth Kodavanti, Vikram Nelvoy Rajendiran, Sharan Kumar Allur Categories: cs.CV
The Gap
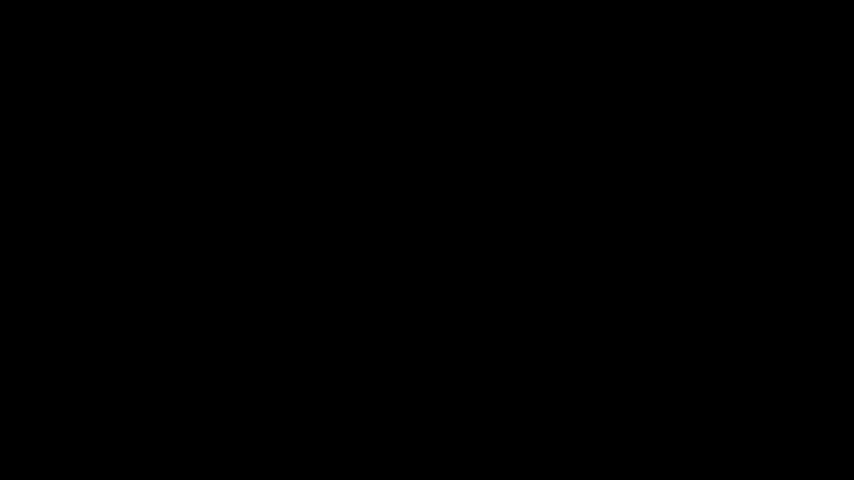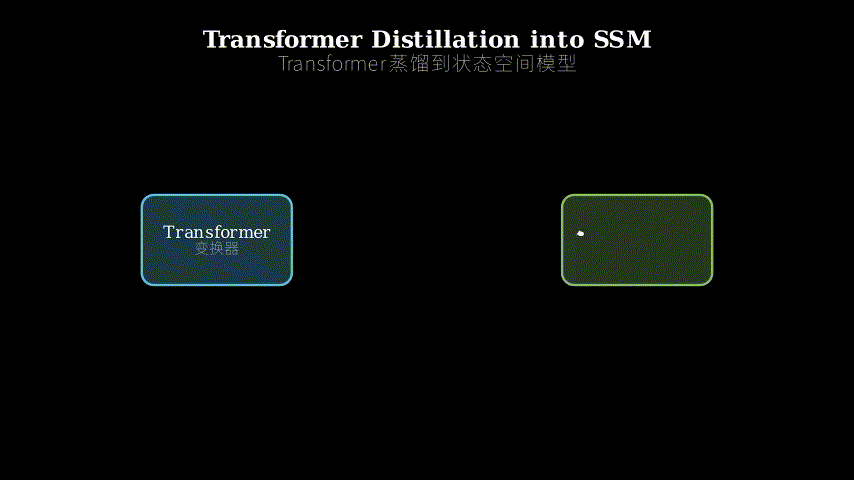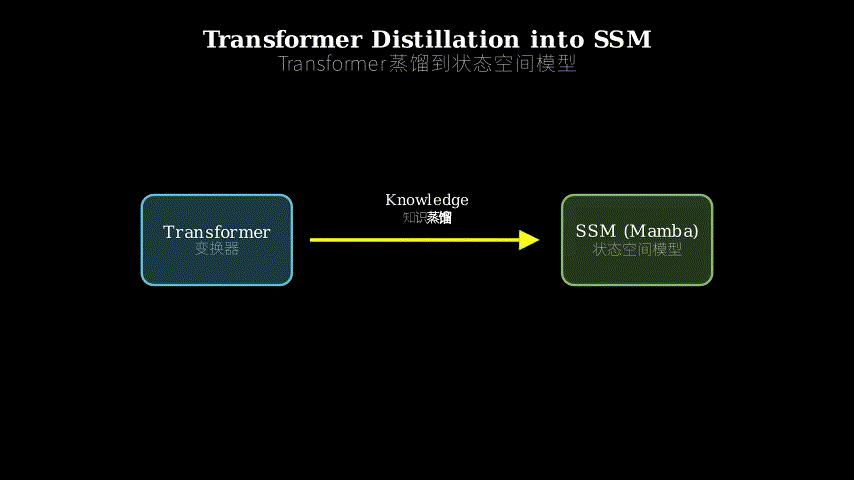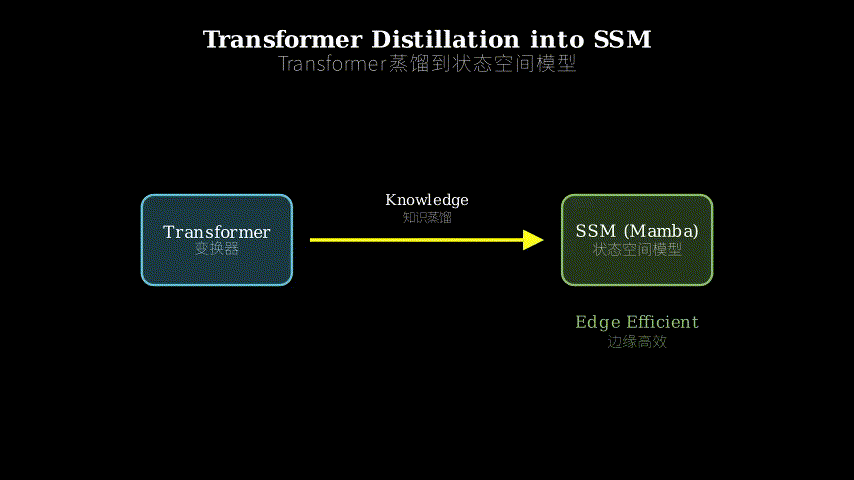
Transformer-based image restoration models like Restormer achieve strong quality by modeling long-range dependencies through self-attention, but their quadratic complexity makes them prohibitively slow on edge devices—10+ seconds per image on mobile CPUs. State-space models (SSMs) like Mamba offer linear-time inference but lack the global receptive field needed for fine-grained restoration tasks. Existing work treats this as a binary choice: either accept slow transformers for quality or settle for fast-but-weak SSMs. No one has systematically explored whether SSMs can be taught to mimic transformer behavior through distillation, or how to automatically discover which blocks to swap for a given task and hardware constraint.
Problem: Transformers too slow on edge, SSMs too weak for restoration
                              |
                              v
Assumption: SSMs can learn transformer-like features via distillation
                              |
                              v
Method: Train SSM blocks as transformer surrogates + search hybrid configs
                              |
                              v
Evidence: 1.17-3.4x speedup on Snapdragon 8 Elite, competitive quality
                              |
                              v
Conclusion: Task-specific hybrid architectures beat monolithic designs
The Increment
One sentence: Before this paper, you chose between slow-but-accurate transformers or fast-but-weak SSMs for mobile image restoration; after, you can automatically discover task-specific hybrids that run 1.7-3.4x faster with minimal quality loss.
Core Mechanism
The method has three stages. First, train a full transformer baseline (Restormer) and a set of lightweight Mamba SSM blocks. Use feature distillation: freeze the transformer, pass images through both models, and train the SSM blocks to match the transformer’s intermediate feature maps layer-by-layer. This creates “aligned” SSM blocks that approximate transformer behavior but run in linear time.
Second, build a search space of hybrid U-Net architectures where each encoder/decoder block can be either a transformer or its distilled SSM counterpart. The search space is modular: blocks are pre-trained and swapped in, not trained from scratch during search.
Third, run Efficient Network Search (ENS): a multi-objective optimization that samples hybrid configurations, evaluates them on validation data, and assigns a score that balances restoration quality (PSNR/SSIM) against transformer usage (number of transformer blocks). ENS uses transformer count as a proxy for latency—fewer transformers means faster inference—so you don’t need to profile every candidate on actual hardware during search. The top-scoring hybrid for each task (deblurring, deraining, denoising) becomes the final model.
Stage 1: Distillation          Stage 2: Search Space         Stage 3: ENS

Transformer (frozen)           [ T1 ]--[ T2 ]--[ T3 ]        Sample configs
     |                              \      \      \           Evaluate quality
     v                               \      \      \          Penalize T-count
Feature maps                    [ S1 ]--[ S2 ]--[ S3 ]       Select best hybrid
     |                          (T = Transformer block)            |
     v                          (S = Distilled SSM block)          v
SSM (training)                                              ENS-Deblurring
     |                         Mix and match per layer      ENS-Deraining
     v                                                       ENS-Denoising
Match features
Think of this like building a sports team. You have star players (transformers) who are incredibly skilled but tire quickly, and rookies (SSMs) who have stamina but lack experience. First, you train the rookies by having them shadow the stars in practice—watch every move, learn the plays (distillation). Then you need to decide the lineup for different games (tasks). You can’t afford to field all stars because they’ll burn out (latency), but you can’t field all rookies because you’ll lose (quality). So you run simulations (ENS) to find which positions need stars and which can be covered by trained rookies. For a fast-paced game (deblurring), you might use mostly rookies with a few stars in key positions. For a technical game (denoising), you keep more stars on the field. The lineup is custom per game, and you discover it by optimizing for wins while minimizing star player minutes.
Key Concepts
-
Feature Distillation: Standard knowledge distillation trains a small model to mimic a large model’s final outputs (e.g., class probabilities). Feature distillation goes deeper: the student model learns to reproduce the teacher’s intermediate representations—the feature maps at each layer. Why? Because in image restoration, the path matters as much as the destination. A transformer might restore a sharp edge by first detecting texture gradients, then refining boundaries, then suppressing noise. If an SSM only matches the final output, it might achieve similar PSNR through a completely different (and less robust) internal process. By matching intermediate features, the SSM learns the transformer’s problem-solving strategy, not just its answers. Concretely: freeze the transformer, pass an image through both models, compute L2 loss between their feature maps at corresponding layers, backprop only through the SSM. The SSM becomes a “surrogate” that approximates the transformer’s internal computations.
-
State-Space Models (SSMs): Traditional RNNs process sequences one token at a time, maintaining a hidden state that gets updated at each step—this is inherently sequential and slow. SSMs like Mamba reformulate sequence modeling as a continuous-time dynamical system: the hidden state evolves according to differential equations that can be discretized and solved in parallel. The key trick is that Mamba’s state transitions are linear and can be computed via efficient scans (cumulative sums with learned gates), giving O(n) complexity instead of O(n²) attention. For images, you flatten spatial dimensions into a sequence (e.g., raster scan), process with the SSM, then reshape back. SSMs lack attention’s explicit pairwise comparisons, so they struggle with long-range dependencies—but they’re fast. This paper’s bet: if you teach an SSM to mimic a transformer’s features, it inherits some of the transformer’s global modeling ability without the quadratic cost.
-
Multi-Objective Architecture Search: Most neural architecture search (NAS) optimizes a single metric like accuracy. But real deployment cares about multiple competing objectives: you want high quality and low latency. Multi-objective search treats this as a Pareto optimization problem: find architectures where you can’t improve one objective without hurting another. ENS simplifies this by using transformer count as a differentiable proxy for latency—more transformers = slower inference. The search objective becomes: maximize restoration quality, minimize transformer usage. This avoids expensive hardware profiling during search (you don’t need to benchmark every candidate on a Snapdragon), but still correlates with real latency because transformers dominate runtime. After search, you validate the top candidates on actual hardware to confirm the proxy held up.
Framework Shift
Before (mainstream approach):        After (this paper):

Monolithic architecture:             Task-specific hybrid:

  Input                                Input
    |                                    |
    v                                    v
[Transformer] x N layers             [Transformer] (critical layers)
    |                                    |
    v                                    v
[Transformer] x N layers             [SSM] (bulk processing)
    |                                    |
    v                                    v
[Transformer] x N layers             [SSM] (bulk processing)
    |                                    |
    v                                    v
  Output                             [Transformer] (refinement)
                                         |
One size fits all tasks                  v
Slow on edge devices                   Output

                                     Discovered per task
                                     1.7-3.4x faster
From uniform depth to strategic allocation, the core shift is treating architecture as a task-specific resource budget rather than a fixed template.
Expert Assessment
Problem choice: Real gap. Mobile image restoration is a genuine deployment bottleneck—10 seconds per image is unusable for consumer apps. The transformer-vs-SSM tradeoff is well-established in NLP and vision, so exploring hybrid designs is a natural next step. The problem sits at the intersection of model compression and hardware-aware NAS, both active areas.
Method maturity: Mostly engineering, not deep insight. Feature distillation is standard (FitNets, 2015). Mamba is off-the-shelf. The novelty is in the combination: distilling transformers into SSMs for vision, then searching over hybrid configs. ENS is clever but not groundbreaking—using transformer count as a latency proxy is reasonable but coarse (ignores memory bandwidth, kernel fusion, etc.). The paper doesn’t explore why distillation works or when it fails; it’s a recipe that happens to work for these three tasks.
Experimental integrity: Baselines are fair (Restormer is a strong transformer baseline, pure Mamba is the SSM baseline). The speedup numbers are measured on real hardware (Snapdragon 8 Elite CPU), not FLOPs, which is good. But: (1) Only three tasks tested—does this generalize to super-resolution, inpainting, etc.? (2) No ablation on distillation loss design or search hyperparameters. (3) Quality metrics (PSNR/SSIM) are reported but no perceptual metrics (LPIPS) or user studies—PSNR can be misleading for restoration. (4) The search cost is not reported—how many candidate architectures were evaluated? Overall, the experiments are competent but not exhaustive.
Writing quality: The abstract and intro are clear. The method section is dense and assumes familiarity with distillation and NAS—a diagram showing the full pipeline (distillation → search → deployment) would help. The results section lists numbers but doesn’t analyze failure modes or discuss where hybrids struggle. The related work is thin—no comparison to other hybrid architectures (e.g., MobileViT, EfficientFormer) or hardware-aware NAS methods (e.g., FBNet, ProxylessNAS). Rewriting Section 4 (Experiments) to include qualitative analysis and failure cases would elevate the paper.
Verdict: Weak accept—solid engineering contribution with real speedups on mobile hardware, but limited novelty and shallow analysis. Useful for practitioners, not a conceptual advance.
Takeaways
Distillation as a block-level tool: Instead of distilling entire models, distill individual components (transformer blocks → SSM blocks) and treat them as interchangeable parts. This modular approach lets you mix-and-match without retraining from scratch. Transferable to any domain where you have a slow-but-accurate model and a fast-but-weak alternative (e.g., distilling BERT layers into linear RNNs for NLP).
Proxy metrics for hardware-aware search: If you’re doing NAS under latency constraints, you don’t need to benchmark every candidate on target hardware during search—find a cheap proxy that correlates with real latency (here, transformer count). Validate the proxy on a small sample, then use it to prune the search space. Saves weeks of profiling.
Task-specific architectures beat one-size-fits-all: Deblurring needs different compute allocation than denoising. Instead of designing a single architecture for all tasks, let search discover task-specific hybrids. This is obvious in hindsight but underutilized—most papers still report one model for all benchmarks.
论文: 2605.02794 作者: Srinivas Soumitri Miriyala, Sowmya Vajrala, Sravanth Kodavanti, Vikram Nelvoy Rajendiran, Sharan Kumar Allur 分类: cs.CV
缺口
基于 Transformer 的图像修复模型(如 Restormer)通过自注意力机制建模长程依赖,实现了很强的修复质量,但其二次复杂度在边缘设备上慢得令人发指——移动 CPU 上每张图要 10 多秒。
状态空间模型(SSM)如 Mamba 提供线性时间推理,但缺乏细粒度修复任务所需的全局感受野。
现有工作把这当成二选一:要么接受慢速 Transformer 换质量,要么将就快速但弱的 SSM。
没人系统探索过 SSM 能否通过蒸馏学会 Transformer 的行为,或者如何针对给定任务和硬件约束自动发现该替换哪些块。
问题:Transformer 在边缘太慢,SSM 对修复太弱
                    |
                    v
假设:SSM 可以通过蒸馏学习 Transformer 式特征
                    |
                    v
方法:训练 SSM 块作为 Transformer 替身 + 搜索混合配置
                    |
                    v
证据:骁龙 8 Elite 上 1.17-3.4 倍加速,质量相当
                    |
                    v
结论:任务特定混合架构胜过单一设计
增量
一句话:这篇论文之前,移动图像修复要在慢而准的 Transformer 和快而弱的 SSM 之间二选一;
之后,你可以自动发现任务特定的混合架构,速度快 1.7-3.4 倍,质量损失极小。
核心机制
方法分三个阶段。
第一阶段,训练一个完整的 Transformer 基线(Restormer)和一组轻量级 Mamba SSM 块。
使用特征蒸馏:冻结 Transformer,让图像同时通过两个模型,训练 SSM 块逐层匹配 Transformer 的中间特征图。
这创建了”对齐”的 SSM 块,近似 Transformer 行为但以线性时间运行。
第二阶段,构建混合 U-Net 架构的搜索空间,其中每个编码器/解码器块可以是 Transformer 或其蒸馏的 SSM 对应块。
搜索空间是模块化的:块是预训练好的,直接换入,搜索时不从头训练。
第三阶段,运行高效网络搜索(ENS):一个多目标优化,采样混合配置,在验证数据上评估,分配一个平衡修复质量(PSNR/SSIM)和 Transformer 使用量(Transformer 块数量)的分数。
ENS 用 Transformer 数量作为延迟的代理——Transformer 越少推理越快——所以搜索时不需要在实际硬件上分析每个候选。
每个任务(去模糊、去雨、去噪)得分最高的混合配置成为最终模型。
阶段 1:蒸馏                阶段 2:搜索空间           阶段 3:ENS

Transformer(冻结)        [ T1 ]--[ T2 ]--[ T3 ]     采样配置
     |                          \      \      \        评估质量
     v                           \      \      \       惩罚 T 数量
特征图                      [ S1 ]--[ S2 ]--[ S3 ]    选最佳混合
     |                      (T = Transformer 块)            |
     v                      (S = 蒸馏的 SSM 块)             v
SSM(训练中)                                         ENS-去模糊
     |                     每层混搭                   ENS-去雨
     v                                                ENS-去噪
匹配特征
把这想象成组建运动队。
你有明星球员(Transformer),技术超群但体力消耗快,还有新秀(SSM),耐力好但经验不足。
首先,你让新秀跟着明星练习——观察每个动作,学习战术(蒸馏)。
然后你要为不同比赛(任务)决定阵容。
你负担不起全明星阵容,因为他们会累垮(延迟),但也不能全上新秀,因为会输(质量)。
所以你跑模拟(ENS)找出哪些位置需要明星,哪些可以由训练过的新秀顶上。
对于快节奏比赛(去模糊),你可能主要用新秀,关键位置放几个明星。
对于技术性比赛(去噪),你保留更多明星在场上。
阵容是每场比赛定制的,通过优化胜率同时最小化明星球员上场时间来发现。
关键概念
- 特征蒸馏:标准知识蒸馏训练小模型模仿大模型的最终输出(如类别概率)。
特征蒸馏更深入:学生模型学习重现教师的中间表示——每层的特征图。
为什么?
因为在图像修复中,过程和结果一样重要。
Transformer 可能通过先检测纹理梯度,再细化边界,再抑制噪声来修复锐利边缘。
如果 SSM 只匹配最终输出,它可能通过完全不同(且不太鲁棒)的内部过程达到相似的 PSNR。
通过匹配中间特征,SSM 学习 Transformer 的解题策略,而不只是答案。
具体做法:冻结 Transformer,让图像通过两个模型,计算对应层特征图之间的 L2 损失,只通过 SSM 反向传播。
SSM 成为近似 Transformer 内部计算的”替身”。
- 状态空间模型(SSM):传统 RNN 逐个 token 处理序列,维护一个在每步更新的隐藏状态——这本质上是串行的,很慢。
SSM 如 Mamba 将序列建模重新表述为连续时间动力系统:隐藏状态根据可以离散化并并行求解的微分方程演化。
关键技巧是 Mamba 的状态转换是线性的,可以通过高效扫描(带学习门的累积和)计算,复杂度是 O(n) 而非 O(n²) 的注意力。
对于图像,你把空间维度展平成序列(如光栅扫描),用 SSM 处理,再重塑回去。
SSM 缺乏注意力的显式成对比较,所以在长程依赖上挣扎——但它们快。
本文的赌注:如果你教 SSM 模仿 Transformer 的特征,它继承了 Transformer 的部分全局建模能力,但没有二次代价。
- 多目标架构搜索:大多数神经架构搜索(NAS)优化单一指标如准确率。
但真实部署关心多个竞争目标:你想要高质量和低延迟。
多目标搜索把这当成帕累托优化问题:找到无法在不损害另一个目标的情况下改进一个目标的架构。
ENS 通过使用 Transformer 数量作为延迟的可微代理来简化这一点——更多 Transformer = 更慢推理。
搜索目标变成:最大化修复质量,最小化 Transformer 使用。
这避免了搜索期间昂贵的硬件分析(你不需要在骁龙上基准测试每个候选),但仍与真实延迟相关,因为 Transformer 主导运行时间。
搜索后,你在实际硬件上验证顶级候选,确认代理成立。
框架转变
之前(主流方法):                之后(本文方法):

单一架构:                        任务特定混合:

  输入                                输入
    |                                    |
    v                                    v
[Transformer] x N 层                [Transformer](关键层)
    |                                    |
    v                                    v
[Transformer] x N 层                [SSM](批量处理)
    |                                    |
    v                                    v
[Transformer] x N 层                [SSM](批量处理)
    |                                    |
    v                                    v
  输出                               [Transformer](精修)
                                         |
所有任务一个尺寸                          v
边缘设备上慢                            输出

                                     每个任务发现
                                     快 1.7-3.4 倍
从均匀深度到战略分配,核心转变是把架构当成任务特定的资源预算,而非固定模板。
专家评审
选题眼光:真缺口。
移动图像修复是真实的部署瓶颈——每张图 10 秒对消费级应用不可用。
Transformer 与 SSM 的权衡在 NLP 和视觉中都已确立,所以探索混合设计是自然的下一步。
问题位于模型压缩和硬件感知 NAS 的交叉点,两者都是活跃领域。
方法成熟度:主要是工程,不是深刻洞见。
特征蒸馏是标准做法(FitNets,2015)。
Mamba 是现成的。
新颖性在于组合:将 Transformer 蒸馏到 SSM 用于视觉,然后搜索混合配置。
ENS 聪明但不突破——用 Transformer 数量作为延迟代理合理但粗糙(忽略内存带宽、内核融合等)。
论文没探索蒸馏为何有效或何时失败;
这是一个碰巧对这三个任务有效的配方。
实验诚意:基线公平(Restormer 是强 Transformer 基线,纯 Mamba 是 SSM 基线)。
加速数字在真实硬件(骁龙 8 Elite CPU)上测量,不是 FLOPs,这很好。
但:(1)只测了三个任务——这能推广到超分辨率、修复等吗?
(2)没有蒸馏损失设计或搜索超参数的消融。
(3)报告了质量指标(PSNR/SSIM)但没有感知指标(LPIPS)或用户研究——PSNR 对修复可能误导。
(4)未报告搜索成本——评估了多少候选架构?
总体而言,实验称职但不详尽。
写作功力:摘要和引言清晰。
方法部分密集,假设读者熟悉蒸馏和 NAS——一个显示完整流程(蒸馏 → 搜索 → 部署)的图会有帮助。
结果部分列出数字但不分析失败模式或讨论混合架构在哪里挣扎。
相关工作单薄——没有与其他混合架构(如 MobileViT、EfficientFormer)或硬件感知 NAS 方法(如 FBNet、ProxylessNAS)的比较。
重写第 4 节(实验)加入定性分析和失败案例会提升论文。
判决:弱接收——在移动硬件上有实际加速的扎实工程贡献,但新颖性有限,分析浅薄。
对实践者有用,不是概念进步。
要点总结
蒸馏作为块级工具:不要蒸馏整个模型,蒸馏单个组件(Transformer 块 → SSM 块)并把它们当成可互换部件。
这种模块化方法让你可以混搭而无需从头重新训练。
可迁移到任何有慢而准模型和快而弱替代品的领域(如将 BERT 层蒸馏到线性 RNN 用于 NLP)。
硬件感知搜索的代理指标:如果你在延迟约束下做 NAS,搜索期间不需要在目标硬件上基准测试每个候选——找一个与真实延迟相关的廉价代理(这里是 Transformer 数量)。
在小样本上验证代理,然后用它修剪搜索空间。
节省数周的分析时间。
任务特定架构胜过一刀切:去模糊需要的计算分配与去噪不同。
不要为所有任务设计单一架构,让搜索发现任务特定的混合。
这事后看来显而易见但利用不足——大多数论文仍为所有基准报告一个模型。