Paper: 2608.12271 Authors: Pedro Sousa, Will Tebbutt, Sadiq Jaffer, Robin Young, Anil Madhavapeddy, Richard E. Turner Categories: cs.LG, physics.ao-ph
The Gap
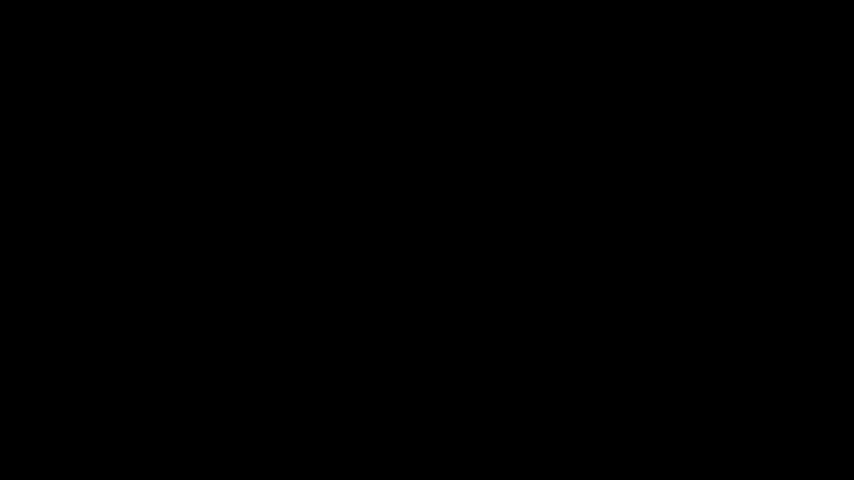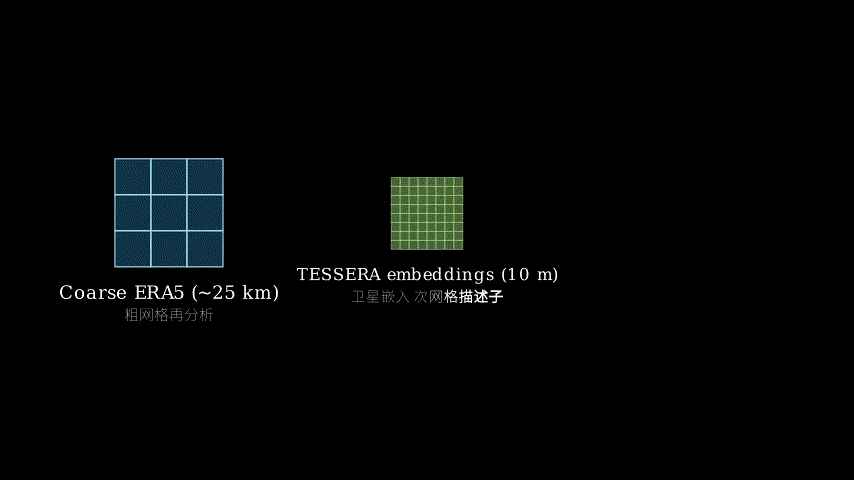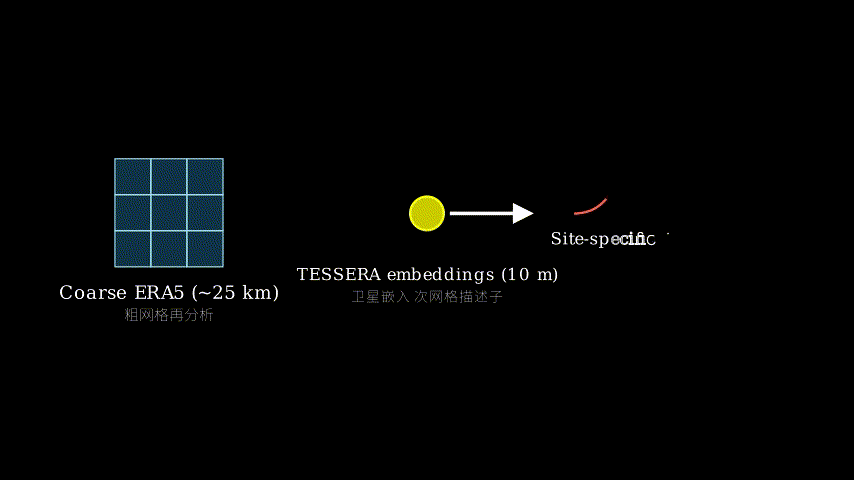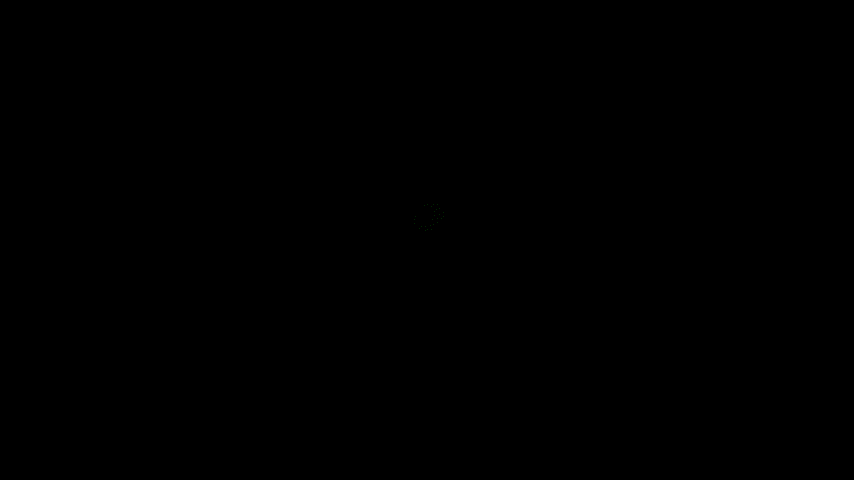
Global reanalysis and AI forecast products live on grids of roughly 25 km. Inside one such cell you can have a lake, a ridge, a city centre, and a pine plantation. ERA5 gives all of them the same 2 m temperature. Anyone who actually needs a number at a location — a wind farm, a vineyard, a road-icing service — has to bridge that gap.
The established way to bridge it is statistical downscaling with a learned model that takes the coarse atmospheric state plus a description of the site, and predicts the local observation. The strongest probabilistic version of this is the convolutional conditional neural process (ConvCNP) family, which can predict at arbitrary off-grid points and returns a distribution rather than a point. These models already work. Their weak spot is the “description of the site”: it’s hand-crafted topography. Elevation, slope, aspect, terrain position index at a few smoothing scales. Someone decided in advance that terrain shape is what matters sub-grid.
Terrain shape is clearly part of what matters. But a paved car park and a wet meadow at identical elevation and slope get identical descriptors, and they do not have identical 2 m temperature or 10 m wind. What’s missing is the state of the surface, not just its geometry — albedo, roughness, moisture, vegetation structure, urban fabric. That information exists in satellite imagery, and Earth-observation foundation models now compress satellite time series into per-pixel embeddings. The question this paper asks is uncomfortable on its face: those embeddings summarise a year. Weather downscaling is instantaneous. Can a slow descriptor help a fast prediction?
[Problem]
  one 25 km cell = one number for a lake, a ridge, and a city
        |
        v
[Prior art]
  ConvCNP downscaler + hand-crafted topo descriptors
  (elevation, slope, aspect, TPI)
  ... encodes the SHAPE of the land, not the STATE of the surface
        |
        v
[Assumption]
  the sub-grid departure at a site is mostly PERSISTENT
  => a slow (annual) descriptor can serve a fast (hourly) task
        |
        v
[Method]
  compress a 10 m TESSERA embedding patch -> short vector d
  feed d to the ConvCNP decoder alongside coarse state + topo
        |
        v
[Evidence]
  5 climatically diverse regions
  stations held out in SPACE and in TIME
  CRPS skill: +11.5% (2 m temperature), +6.2% (10 m wind speed)
  survives swapping ERA5 -> Aurora forecasts as the coarse input
  survives brand-new stations with no regional history
        |
        v
[Conclusion]
  annual-timescale EO embeddings are usable sub-grid descriptors
  wind gains more from surface state; temperature more from terrain
The Increment
One sentence: Before, the sub-grid half of a probabilistic downscaler was a human-designed topography vector; after, it can be a learned compression of a satellite foundation model’s embeddings, and that swap buys double-digit CRPS improvement on temperature without touching the atmospheric model.
Core Mechanism
Start with the backbone, which is not new and the authors don’t pretend it is. A ConvCNP takes gridded coarse fields, pushes them through a CNN, and produces a continuous latent function over space — you can evaluate it anywhere, not just at grid nodes. A decoder then evaluates that latent at a query location and outputs the parameters of a predictive distribution for the target variable at that point. That’s why it handles station data: stations sit at arbitrary coordinates, and you want a spread, not just a mean.
The new part sits on the side channel. Around each query location, take a patch of TESSERA embeddings at 10 m resolution. That patch is large — thousands of pixels, each with an embedding vector — so it cannot be fed to the decoder directly. A learned compressor squeezes the patch into a short descriptor vector. Critically, this compressor is trained end to end against the downscaling loss, not with a reconstruction or clustering objective. The model is not asked “summarise this land cover”; it is asked “extract from this land cover whatever predicts how this site departs from its grid cell.” Those are different objectives and the second one is the interesting one.
At prediction time the decoder therefore sees three things: the interpolated coarse atmospheric state at the query point, the hand-crafted topographic features (kept, not replaced), and the learned surface descriptor. The paper’s per-variable analysis then splits the credit: for 2 m temperature, topography explains most of the sub-grid structure and TESSERA adds a modest increment; for 10 m wind speed, topography explains less and the surface descriptor contributes proportionally more of the useful signal. That asymmetry is physically sensible — wind at 10 m is dominated by surface roughness, which is exactly what elevation and slope cannot see.
 ERA5 (or Aurora) coarse fields, ~25 km, multi-variable
        |
        v
 +----------------------------+
 | ConvCNP encoder (CNN)      |   grid --> continuous latent
 +----------------------------+
        |
        |  r(.)  : latent function over space
        |
        |            TESSERA embeddings @ 10 m
        |            patch centred on target site
        |                    |
        |                    v
        |          +----------------------+
        |          | learned compressor   |  thousands of
        |          | patch --> vector d   |  pixels --> one
        |          | (trained end to end) |  short descriptor
        |          +----------------------+
        |                    |
        |    topo features   |
        |    (elev, slope)   |
        |         |          |
        v         v          v
 +--------------------------------------+
 | decoder at query location x          |
 |   inputs: r(x) , topo(x) , d(x)      |
 +--------------------------------------+
        |
        v
   p( y | x )  : mean + spread, off-grid, per station
The metaphor: think of a clinic predicting a patient’s body temperature this afternoon.
The regional weather model is the ambient reading — the clinic’s thermostat says 21 C in the building. That’s true of the whole ward, so it can’t distinguish patients. The hand-crafted topography is like knowing the patient’s height and weight: real, measurable, causally relevant, and chosen in advance by whoever designed the intake form. The TESSERA embedding is a year of wearable data compressed into a constitution profile: it says nothing about this afternoon, but it says this person runs warm, sweats early, has poor circulation in the extremities. The learned compressor is the clinician who has read a thousand of these wearable dossiers and knows which two or three summary numbers actually predict deviation from ward average — as opposed to a generic wellness score, which is what you’d get if you compressed the dossier without knowing the downstream question.
The ConvCNP decoder is the consultation: ambient reading, plus the intake form, plus the constitution profile, out comes a range for this afternoon rather than a single number. And the “new station” result maps cleanly: a patient walks in who has never visited this clinic, so there are no past readings to interpolate from — but they arrive wearing the watch. Their constitution profile is available on day one. That is why the embedding helps at newly deployed stations where a purely data-driven local correction has nothing to fit.
Key Concepts
-
Conditional neural process, and why “convolutional” matters: Ordinary regression learns one function from inputs to outputs. A conditional neural process learns a mapping from *a set of observations to a predictive distribution, so at test time you hand it whatever context you happen to have and it returns calibrated uncertainty without retraining. The “convolutional” version adds translation equivariance: if you slide the whole scene 50 km east, the predictions slide with it. In practice this is what makes the model generalise to stations it has never seen, because it learned a local rule (“this configuration of coarse state and surface implies this local departure”) rather than a lookup table of station identities.
-
CRPS: the continuous ranked probability score, the standard way to grade a probabilistic forecast. Intuition: your forecast is a cumulative distribution curve, the truth is a step function that jumps at the observed value, and CRPS is the squared area between them. It punishes you both for being wrong on average and for lying about your confidence — a razor-sharp forecast that misses scores terribly, and a hedge-everything wide forecast also scores poorly. If your prediction is a single point, CRPS collapses to mean absolute error, which is a nice sanity anchor. One caveat for reading the paper: “CRPS *skill” is a score relative to some reference, so an 11.5% improvement in skill is not the same as an 11.5% CRPS reduction, and the reference choice matters.
-
Earth-observation foundation model embeddings: instead of handing you raw satellite bands, these models pre-digest a full year of multi-sensor satellite time series per pixel and output a fixed-length vector. That vector encodes seasonal behaviour — when the field greened up, how the surface responded to rain, whether it’s permanently paved. Concretely: a wheat field and an evergreen forest can look nearly identical on one cloudless July image, but their annual trajectories are unmistakably different, and the embedding captures that difference. The paper’s bet is that this annual signature is a good proxy for the *persistent physical properties (roughness, thermal inertia, moisture availability) that set a site’s systematic offset from its grid cell.
Framework Shift
Before (mainstream approach):          After (this paper):

 coarse cell ------+                    coarse cell ----------+
                   |                                          |
 topo vector ------+--> [ConvCNP]       topo vector ----------+--> [ConvCNP]
 elev / slope /    |      |                                   |       |
 aspect / TPI      |      v             10 m EO patch         |       v
                   |   p(y|x)              |                  |    p(y|x)
                   |                       v                  |
   ^               |               [learned compressor] ------+
   |               |                       ^
 a human chose     |                       |
 which surface     |               the satellite record chose,
 properties        |               and the DOWNSTREAM LOSS chose
 matter                            which parts of it matter
One sentence: from asking a domain expert what about the ground matters to asking the downstream loss to pick it out of a satellite embedding, the core shift is that the sub-grid descriptor becomes a learned, transferable object rather than a fixed feature list.
Expert Assessment
Problem choice: Real gap, and well positioned. Downscaling literature has been iterating hard on the atmospheric side (better architectures, better generative models, diffusion) while the surface side stayed at “elevation plus a few terrain indices.” Meanwhile EO foundation models arrived and everyone in remote sensing has been looking for load-bearing downstream tasks beyond crop classification and land-cover mapping. This paper connects the two, and the timescale mismatch — annual embeddings for instantaneous prediction — is the kind of question that sounds like it shouldn’t work, which makes a positive result worth reporting. It’s an incremental contribution to a well-defined pipeline, not a new paradigm.
Method maturity: Clever plumbing rather than a new idea. The backbone is an existing ConvCNP downscaler; the contribution is one side channel and the decision to train its compressor against the downscaling loss. That decision is the actually good insight, and the framing of the surface descriptor as encoding “a location’s departure from the coarse-grid state” is a clean way to think about the problem. What I’d want checked is the cheaper alternative: a one-hot land-cover class from an off-the-shelf product like WorldCover, plus impervious fraction, plus distance to water, is a nearly free baseline that captures a lot of what “surface state” means for roughness and thermal inertia. If TESSERA only beats *topography, that’s a weak comparison; the interesting comparison is against a competent hand-crafted land-surface descriptor. There’s also a capacity confound — the embedding branch adds parameters, and a fair ablation needs a size-matched control.
Experimental integrity: The protocol is better than average. Holding stations out in *both space and time is the right thing to do and papers in this area often don’t. Five climatically distinct regions is reasonable coverage. The two robustness results carry real weight: swapping the coarse input from ERA5 to Aurora tests that the descriptor learned surface physics rather than ERA5’s specific biases, and the new-station result is the deployment scenario people actually care about. The per-variable decomposition, where topography wins for temperature and TESSERA contributes more for wind, is the kind of finding that suggests the authors were looking for the truth rather than for a headline number.
Two things I’d press on. First, leakage: TESSERA embeddings are derived from satellite observations over specific years. If the embedding years overlap the evaluation period, the embedding could encode that year’s climate anomaly at that location, not just persistent properties — a subtle and easily overlooked channel. The abstract doesn’t tell us how this was handled and it should be addressed head-on. Second, the reported gains are modest in absolute terms and expressed as skill-score percentages against an unstated reference; 6.2% on wind is small enough that it needs error bars across regions and seeds, not just a pooled average, since regional heterogeneity in downscaling results is notoriously large.
Writing quality: I’m judging mostly from the abstract, which is unusually disciplined — it states the timescale tension, gives the numbers, and admits where the contribution is smaller (temperature is mostly topography). If I could ask for one section to be expanded, it’s the compressor: patch size, embedding dimension, descriptor dimension, and architecture are exactly the knobs a reader needs to reproduce or to judge whether the gain is information or capacity. Second priority would be pushing the per-variable attribution from an observation into an analysis — if wind benefits because the embedding proxies surface roughness, show that by relating the learned descriptor to roughness estimates. That would turn an empirical result into a mechanistic one and lift the paper a full grade.
Verdict: weak accept — a well-executed, honestly evaluated demonstration that EO foundation model embeddings transfer to a task nobody built them for, held back by an architecturally thin contribution and a baseline set that likely omits the cheap land-cover competitor.
Takeaways
Things that transfer:
-
Train the compressor against the downstream loss, not a reconstruction objective. The reusable move is: when a foundation model gives you far more representation than your decoder can absorb, don’t reduce it with PCA or clustering or a generic autoencoder — let the task loss decide what to keep. Applies to any pipeline where a big pretrained representation meets a small task head.
-
Timescale mismatch is not automatically disqualifying. The reflex is to reject a slow descriptor for a fast prediction. The right test is whether the *residual you’re trying to explain is persistent, even if the target isn’t. Here the target (2 m temperature now) is fast but its departure from the grid-cell mean is slow. That reframing generalises: look for tasks where the bias structure is stable even though the signal is volatile — sensor calibration, per-user recommendation offsets, per-facility demand corrections.
-
Hold out in space and time, and swap the upstream input. Two protocol choices worth copying. Spatial-plus-temporal holdout kills the station-memorisation shortcut. Swapping the coarse driver (ERA5 to Aurora) is a cheap, powerful test that your auxiliary feature learned physics rather than the quirks of one data product — the general form is “change the upstream model and see if your improvement survives.”
-
*Report where your contribution doesn’t help. The temperature-versus-wind split makes the paper more credible, not less, and it hands the next researcher a hypothesis. Cheap to do, disproportionately valuable.
If you build site-specific weather products, the concrete action item is smaller and more immediate: your topographic descriptor stack is probably leaving surface-state information on the table, particularly for wind, and off-the-shelf EO embeddings are now an easy thing to bolt on and measure.
论文: 2608.12271 作者: Pedro Sousa, Will Tebbutt, Sadiq Jaffer, Robin Young, Anil Madhavapeddy, Richard E. Turner 分类: cs.LG, physics.ao-ph
缺口
全球再分析和 AI 预报产品都跑在约 25 km 的网格上。 一个格点里可能同时装着一个湖、一道山脊、一片市中心和一块松树林,而 ERA5 给它们同一个 2 m 气温值。 真正需要”某个点上的数字”的人——风电场、葡萄园、道路结冰预警服务——必须自己补上这个缺口。
现成的补法是统计降尺度:模型吃进粗网格大气状态加上一份”站点描述”,输出局地观测。 其中概率化做得最好的一支是卷积条件神经过程(ConvCNP),它能在任意非格点位置预测,并且给出分布而不是单点。 这类模型本身已经可用。 问题出在那份”站点描述”上——它是手工设计的地形量:高程、坡度、坡向、若干平滑尺度上的地形位置指数。 也就是说,有人事先替模型决定了”次网格尺度上重要的东西是地形形状”。
地形形状当然是重要因素之一。 但高程和坡度完全相同的一片沥青停车场和一块湿草甸会拿到完全相同的描述子,而它们的 2 m 气温和 10 m 风速显然不同。 缺的是地表的状态而不只是它的几何形状:反射率、粗糙度、湿度、植被结构、城市肌理。 这些信息就在卫星影像里,而地球观测基础模型现在能把卫星时间序列压成逐像素的嵌入向量。
于是本文提出一个乍看别扭的问题:这些嵌入概括的是一整年,而天气降尺度是瞬时的。 慢尺度的描述子能帮上快尺度的预测吗?
[问题]
  一个 25 km 格点 = 湖泊、山脊、城区共用一个数
        |
        v
[已有工作]
  ConvCNP 降尺度器 + 手工地形描述子
  (高程 / 坡度 / 坡向 / TPI)
  ... 编码了地面的"形状",没编码地表的"状态"
        |
        v
[假设]
  一个站点的次网格偏差主要是"持久性"的
  => 慢尺度(年)描述子可以服务快尺度(小时)任务
        |
        v
[方法]
  把 10 m 的 TESSERA 嵌入 patch 压成短向量 d
  与粗网格状态、地形量一起送进 ConvCNP 解码器
        |
        v
[证据]
  5 个气候差异显著的区域
  测试站点在"空间"和"时间"上双重留出
  CRPS 技巧: +11.5% (2 m 气温) / +6.2% (10 m 风速)
  把粗输入从 ERA5 换成 Aurora 预报后依然成立
  在毫无区域历史的新部署站点上依然成立
        |
        v
[结论]
  年尺度 EO 嵌入可以充当次网格描述子
  风速更依赖地表状态,气温更依赖地形
增量
一句话:以前概率降尺度器里”次网格”那一半是人手设计的地形向量;现在它可以是卫星基础模型嵌入的一段学出来的压缩表示,而这一换在完全不动大气侧模型的情况下就换来了气温上两位数的 CRPS 提升。
核心机制
先说骨架,这部分不新,作者也没假装它新。 ConvCNP 把粗网格场送进 CNN,产出一个空间上连续的隐函数——你可以在任意位置求值,不限于格点。 解码器在查询位置上求值,输出该点目标变量预测分布的参数。 这就是它能处理站点数据的原因:站点坐标任意,而你要的是一个区间不只是均值。
新东西挂在旁路上。 在每个查询位置周围取一块 10 m 分辨率的 TESSERA 嵌入 patch。 这块 patch 很大——上千个像素,每个都带一个嵌入向量——不可能直接塞给解码器。 于是用一个可学习的压缩器把整块 patch 挤成一个短描述子向量。
关键在于:这个压缩器是用降尺度损失端到端训练的,不是用重构或聚类目标训的。 模型被问的不是”总结一下这里的土地覆盖”,而是”从这片土地覆盖里抽出能预测该点相对格点偏差的那部分”。 这是两个不同的目标,而有意思的是第二个。
预测时解码器看到三样东西:查询点上插值出的粗网格大气状态、手工地形特征(保留而非替换)、以及学出来的地表描述子。 论文随后的分变量分析把功劳拆开:对 2 m 气温,地形解释了次网格结构的大部分,TESSERA 只是锦上添花;对 10 m 风速,地形解释得少,地表描述子贡献的有用信号占比明显更高。 这个不对称在物理上讲得通——10 m 风主要受地表粗糙度支配,而粗糙度正是高程和坡度看不见的东西。
 ERA5 (或 Aurora) 粗网格场, ~25 km, 多变量
        |
        v
 +----------------------------+
 | ConvCNP 编码器 (CNN)       |   网格 --> 连续隐表示
 +----------------------------+
        |
        |  r(.)  : 空间上的隐函数
        |
        |            TESSERA 嵌入 @ 10 m
        |            以目标站点为中心的 patch
        |                    |
        |                    v
        |          +----------------------+
        |          | 可学习压缩器         |  上千像素
        |          | patch --> 向量 d     |  --> 一个短
        |          | (端到端训练)         |      描述子
        |          +----------------------+
        |                    |
        |    地形特征        |
        |   (高程/坡度)      |
        |         |          |
        v         v          v
 +--------------------------------------+
 | 查询位置 x 上的解码器                |
 |   输入: r(x) , topo(x) , d(x)        |
 +--------------------------------------+
        |
        v
   p( y | x )  : 均值 + 离散度, 非格点, 逐站点
核喻:把它想成一家诊所在预测某位病人今天下午的体温。
区域天气模型是环境读数——楼里的温控器显示 21 度。 这对整个病房都成立,所以它区分不了病人。 手工地形描述子相当于知道病人的身高体重:真实、可测、因果相关,而且是当年设计入院表格的人事先挑定的。 TESSERA 嵌入则是一年可穿戴设备数据压成的”体质档案”:它对今天下午一无所知,但它说这个人偏燥热、容易出汗、四肢循环差。
那个可学习的压缩器,就是读过上千份这类可穿戴档案的临床医生,他知道哪两三个汇总数字真正能预测”相对病房均值的偏离”——而不是一个笼统的健康评分,后者正是你在不知道下游问题时压缩档案会得到的东西。
ConvCNP 解码器是那场问诊:环境读数 + 入院表格 + 体质档案,输出今天下午的一个区间而非一个数。 “新站点”那个结果也能干净地对上:一位从没来过这家诊所的病人走进来,没有历史读数可供插值——但他手上戴着表。 体质档案第一天就有。 这就是为什么在纯靠本地数据拟合订正无从下手的新部署站点上,嵌入依然有用。
关键概念
-
条件神经过程,以及”卷积”为什么要紧:普通回归学的是从输入到输出的一个函数。 条件神经过程学的是从一组观测到一个预测分布的映射,所以测试时你手里有什么上下文就丢什么进去,它直接返回带不确定度的预测,不用重训。 “卷积”版本额外加了平移等变性:把整个场景往东挪 50 km,预测跟着一起挪。 实际效果就是它能推广到从没见过的站点,因为它学的是一条局地规则(“这样的粗网格状态配这样的地表,意味着这样的局地偏差”),而不是一张按站点编号查的表。
-
CRPS:连续排序概率评分,评判概率预报的标准工具。 直觉是这样:你的预报是一条累积分布曲线,真值是一个在观测值处跳变的阶梯函数,CRPS 就是两者之间的平方面积。 它既罚你平均意义上报错,也罚你在自信程度上说谎——一个又尖又偏的预报分数很惨,一个啥都覆盖的宽预报分数也不好。 如果预测退化成单点,CRPS 就退化成平均绝对误差,这是个不错的直觉锚点。 读这篇论文要注意一个陷阱:“CRPS 技巧”是相对某个参考的分数,所以技巧提升 11.5% 不等于 CRPS 下降 11.5%,而参考选谁很关键。
-
地球观测基础模型嵌入:它不给你原始卫星波段,而是把每个像素上一整年的多传感器卫星时间序列先消化一遍,输出一个定长向量。 这个向量编码了季节行为——什么时候返青、地表对降雨如何响应、是否常年被硬化铺装覆盖。 举个具体例子:一块麦田和一片常绿林在七月某个无云影像上几乎长得一样,但它们的年度轨迹截然不同,而嵌入抓住了这个差别。 本文押的注是:这份年度签名可以很好地代理那些持久的物理属性(粗糙度、热惯量、可供蒸发的水分),而正是这些属性决定了一个站点相对其格点的系统性偏移。
框架转变
之前(主流方法):                     之后(本文方法):

 粗网格格点 ------+                    粗网格格点 --------+
                  |                                       |
 地形向量 --------+--> [ConvCNP]       地形向量 ----------+--> [ConvCNP]
 高程/坡度/       |      |                                 |       |
 坡向/TPI         |      v             10 m EO patch       |       v
                  |   p(y|x)              |                |    p(y|x)
                  |                       v                |
   ^              |               [可学习压缩器] ----------+
   |              |                       ^
 由人决定         |                       |
 地表的哪些属性   |               由卫星记录 + 下游损失
 重要                             共同决定哪部分重要
一句话:从问领域专家”地面上什么重要”,到让下游损失自己从卫星嵌入里挑出来,核心转变是次网格描述子从一张固定特征清单变成了一个可学习、可迁移的对象。
专家评审
选题眼光:真缺口,位置也选得好。 降尺度这条线近年在大气侧卷得很凶(更好的架构、生成模型、扩散模型),地表侧却一直停在”高程加几个地形指数”。 另一边,EO 基础模型出现之后,遥感圈一直在找除了作物分类和土地覆盖制图之外真正承重的下游任务。 这篇论文把两头接上了,而且”年尺度嵌入服务瞬时预测”这个时间尺度错配,属于那种”听起来不该成立”的问题——正因如此,正结果值得报道。 定位上,它是对一条成熟流水线的增量贡献,不是新范式。
方法成熟度:巧在接线,不在新意。 骨架是已有的 ConvCNP 降尺度器;贡献是一条旁路,加上”用降尺度损失训压缩器”这个决定。 这个决定才是真正的好洞见,而把地表描述子刻画为编码”该点相对粗网格状态的偏离”,是个很干净的问题视角。
我想追问的是更便宜的替代方案:从 WorldCover 之类现成产品取一个土地覆盖 one-hot,加上不透水面比例,加上到水体距离——这几乎是免费的基线,而且已经抓住了”地表状态”对粗糙度和热惯量的大部分含义。 如果 TESSERA 只赢过地形,那是弱对比;有意思的对比是赢过一个称职的手工地表描述子。 另外还有容量混淆:嵌入分支带来了额外参数,公平的消融需要一个参数量对齐的对照组。
实验诚意:协议比平均水平好。 在空间和时间上双重留出站点是正确做法,而这个领域的论文经常不这么做。 五个气候差异显著的区域覆盖度合理。 两个鲁棒性结果分量很足:把粗输入从 ERA5 换成 Aurora,检验的是描述子学到的是地表物理还是 ERA5 自己的偏差;新站点结果对应的是大家真正在意的部署场景。 分变量拆解(气温靠地形、风速更靠 TESSERA)这种发现,说明作者在找真相而不是找标题数字。
有两点我会追着问。 第一是泄漏:TESSERA 嵌入来自特定年份的卫星观测。 如果嵌入年份与评估时段重叠,嵌入可能编码了该地那一年的气候异常,而不只是持久属性——这是一条很隐蔽、很容易被忽略的通道。 摘要没说这一点如何处理,正文应该正面交代。
第二,报出的增益绝对值不大,而且是以相对某个未明说参考的技巧百分比表达的;风速 6.2% 小到必须给出跨区域、跨随机种子的误差棒,而不是一个池化后的平均值——降尺度结果的区域异质性是出了名的大。
写作功力:我主要是从摘要判断,而这份摘要相当有节制——它主动点出时间尺度张力、给了数字、也承认了贡献偏小的地方(气温主要还是靠地形)。 如果只能要求扩写一节,我要压缩器那一节:patch 尺寸、嵌入维度、描述子维度、架构,正是读者复现或判断”增益来自信息还是来自容量”所必需的旋钮。 第二优先是把分变量归因从一句观察升级为一段分析——如果风速受益是因为嵌入代理了地表粗糙度,那就把学到的描述子和粗糙度估计对上看看。 这一步能把经验结果变成机制结果,整篇论文能提一个档。
判决:弱接收 —— 一次执行扎实、评估诚实的演示,说明 EO 基础模型嵌入能迁移到没人为它设计的任务上;短板是架构贡献偏薄,且基线集合很可能漏掉了便宜的土地覆盖竞争者。
要点总结
可以迁移走的东西:
-
用下游损失训压缩器,别用重构目标。 可复用的动作是:当基础模型给你的表示远超解码器的吸收能力时,别用 PCA、聚类或通用自编码器去降维,让任务损失决定留什么。 任何”大预训练表示对接小任务头”的流水线都适用。
-
时间尺度错配不自动构成否决理由。 本能反应是拒绝”用慢描述子做快预测”。 正确的判据是:你试图解释的残差是否持久,即使目标本身不持久。 这里目标(此刻的 2 m 气温)很快,但它相对格点均值的偏离很慢。 这个重构可以推广:去找那些偏差结构稳定、信号本身多变的任务——传感器标定、逐用户推荐偏移、逐场站需求订正。
-
空间时间双重留出,并且换掉上游输入。 两个值得抄的协议选择。 空间加时间留出掐死了”记住站点”这条捷径。 换掉粗网格驱动源(ERA5 换 Aurora)是一个便宜又有力的检验:你的辅助特征学到的是物理,还是某个数据产品的怪癖。 一般形式就是”换掉上游模型,看你的提升还在不在”。
-
主动报告你的贡献在哪里没用。 气温 vs 风速的拆分让论文更可信而不是更弱,还顺手给下一个研究者递了个假设。 成本很低,价值不成比例地高。
如果你在做站点级天气产品,可落地的动作更小更直接:你那套地形描述子很可能漏掉了地表状态信息,尤其在风速上;而现成的 EO 嵌入现在已经是个很容易挂上去并量化收益的东西了。