Paper: 2604.09455 Authors: Weiyang Guo, Zesheng Shi, Liye Zhao, Jiayuan Ma, Zeen Zhu, Junxian He, Min Zhang, Jing Li Categories: cs.AI
The Gap
Tool-integrated reasoning (TIR) — getting LLMs to use external tools like APIs, calculators, or search engines — is stuck between two bad options. Zero-RL training starts from scratch, so the model wastes compute exploring dead ends and eventually collapses into repeating the same few successful patterns (mode degradation). SFT-then-RL fixes this by pre-training on expert examples, but then hits a wall: you need massive amounts of synthetic data, and the model’s performance plateaus because it gets trapped in low-entropy distributions — basically, it memorizes the expert’s style instead of learning to reason.
The real problem: these approaches treat expert knowledge and self-exploration as opposites. You either follow the expert (safe but rigid) or explore freely (flexible but wasteful). There’s no middle ground that lets you branch out from expert anchors while staying grounded.
Zero-RL:              SFT-then-RL:          E3-TIR (this paper):
Explore wildly   →    Follow expert    →    Branch from anchors
(wasteful)            (rigid)               (grounded + flexible)
  |                      |                        |
  v                      v                        v
Mode collapse      Low-entropy trap      Balanced learning
The Increment
Before: You pick either exploration (expensive, chaotic) or imitation (cheap, stuck). After: You can dynamically blend both, using expert trajectories as springboards for controlled branching, cutting data costs while maintaining learning velocity.
Core Mechanism
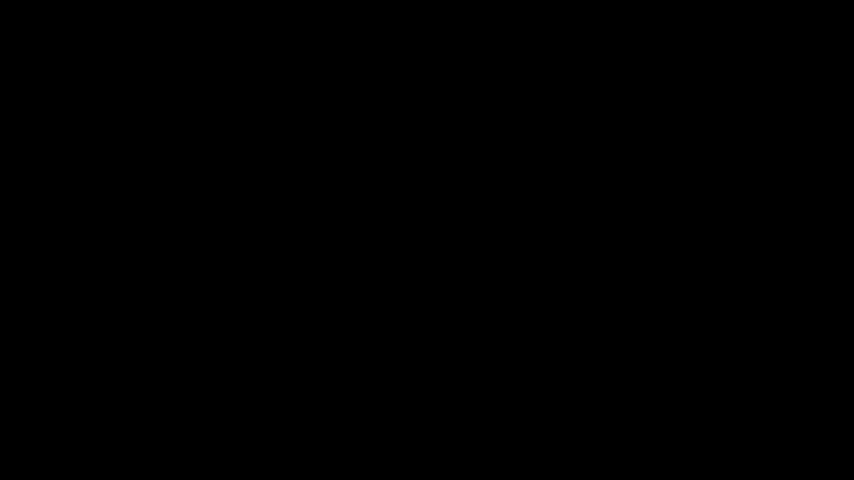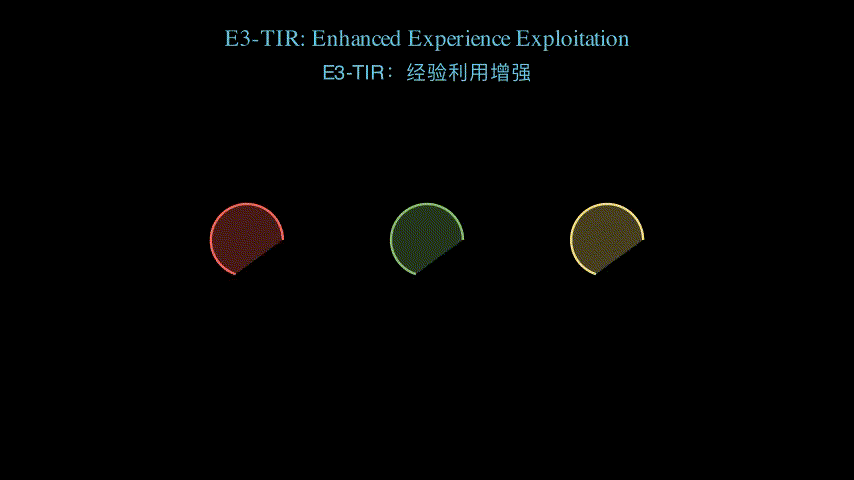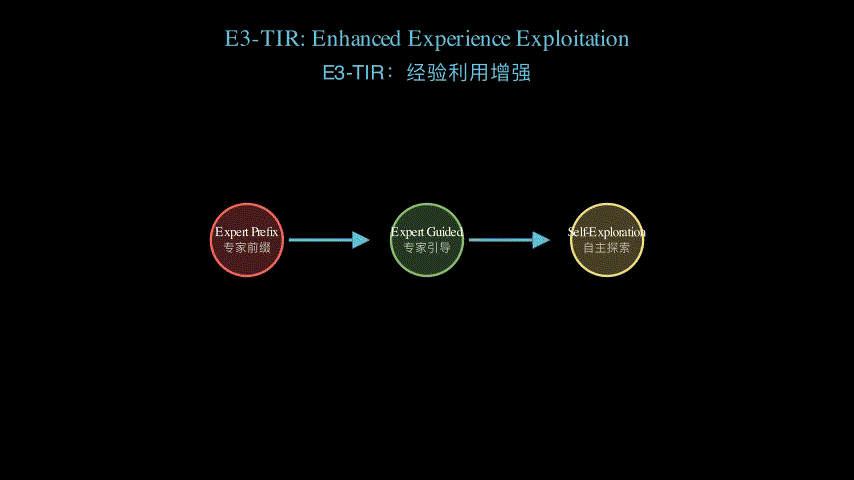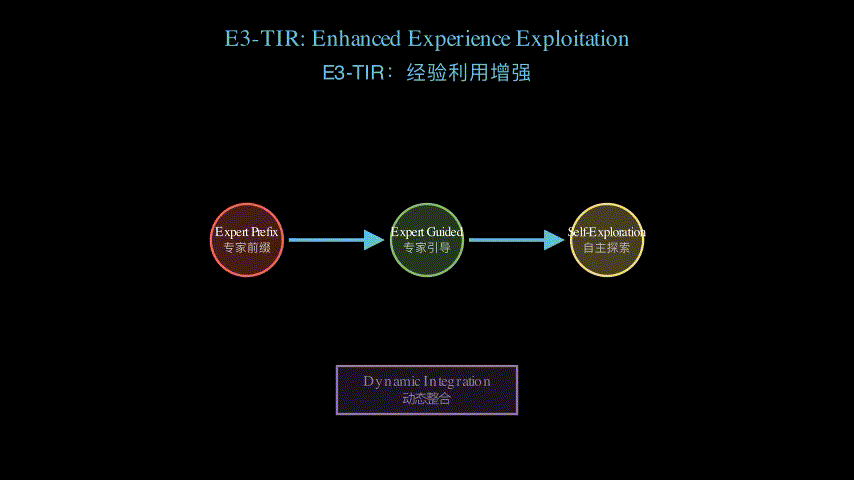
E3-TIR treats training as a three-way mixture. At each step, the model samples from one of three experience sources: (1) Expert Prefixes — the first N steps of an expert trajectory, then the model continues on its own; (2) Expert Guided — the model explores but gets nudged back toward expert paths when it drifts too far; (3) Self-Exploration — pure RL, no guardrails. The key insight is that these three aren’t separate training runs — they’re woven together in a single batch, with a “mix policy” that learns which ratio works best at each training stage.
The mechanism also handles a subtle problem: when you use shared expert prefixes across multiple trajectories, the model’s gradients from different branches can conflict. E3-TIR solves this by treating each branch as its own optimization problem, then carefully merging the updates so they don’t cancel each other out.
Expert trajectory:  S0 -> S1 -> S2 -> S3 -> S4 (goal)
                     |     |     |
                     +-----+-----+--- Expert Prefix
                           |
                           +--- Expert Guided (nudge back if drift)
                           |
                           +--- Self-Exploration (free roam)

Mix Policy learns: when to use which source
Think of it like a jazz ensemble learning from a conductor. The conductor (expert) plays the opening phrase. Some musicians (Expert Prefix) play the opening, then improvise freely. Others (Expert Guided) improvise but keep one ear on the conductor’s harmonic structure. A few (Self-Exploration) just jam. The ensemble director (mix policy) decides how many of each type to feature in each measure. Early on, more musicians follow the conductor. As they get better, more improvise. The magic is that they’re all playing together in the same room, learning from each other’s mistakes in real time, rather than practicing separately.
Key Concepts
-
Mode Degradation: When an RL agent finds one successful strategy, it stops exploring and just repeats it forever. Imagine a robot that learns to open a door by pushing — it then pushes at every problem, even when pulling would work. E3-TIR prevents this by mixing in guided and self-exploration branches that reward finding *different solutions.
-
Low-Entropy Collapse: After SFT on expert data, the model’s output distribution becomes narrow — it’s learned to mimic the expert’s style so well that it can’t deviate even when it should. Like a student who memorized the teacher’s lecture word-for-word but can’t answer a slightly different question. E3-TIR keeps entropy high by explicitly allocating compute to self-exploration, forcing the model to stay creative.
-
Distribution Shift: When you train on expert data then switch to RL, the model sees a sudden change in what trajectories look like (expert vs. self-generated). This whiplash causes instability. E3-TIR smooths this by gradually increasing the self-exploration ratio, so the model adapts incrementally rather than all at once.
Framework Shift
Before (mainstream approach):          After (this paper):

Expert Data    RL Training             Expert Data
    |              |                        |
    v              v                        v
  SFT          Finetune              Mix Policy
    |              |                   /  |  \
    +------+-------+            Expert  Guided  Self
           |                    Prefix  Explore Explore
           v                      |      |      |
        Agent                     +------+------+
                                        |
                                        v
                                    Agent
                                  (adaptive)

From: Sequential stages (SFT then RL)
To: Parallel blending with dynamic weighting
The core shift: From treating expert knowledge and exploration as sequential phases to treating them as concurrent, dynamically-weighted components of a single training process.
Expert Assessment
Problem choice: This is a real gap. The SFT-then-RL bottleneck is well-known in the RL community, and the paper correctly identifies that the issue isn’t just data cost — it’s the fundamental tension between staying grounded and staying flexible. The positioning is solid.
Method maturity: The core idea is elegant but not revolutionary. Mixing different data sources during training is standard practice; the novelty is in *how they mix (the three-way split with dynamic weighting) and why it works (resolving gradient conflicts from shared prefixes). The mix policy mechanism feels a bit underspecified in the abstract — I’d want to see how it’s actually learned. Is it a separate network? A hand-tuned schedule? This matters for reproducibility.
Experimental integrity: The 6× improvement is impressive, but I’d scrutinize the baseline. Are they comparing against the best SFT-then-RL setup, or a strawman? The “less than 10% of synthetic data” claim is strong — what’s the absolute number? Also, the ROI metric (1.46×) is interesting but feels cherry-picked. Why that specific combination of performance, data cost, and training efficiency? What if you weight them differently? The paper needs to show sensitivity analysis here.
Writing quality: The abstract is dense and jargon-heavy (“low-entropy collapse,” “distribution shifts,” “shared prefixes”). The paper would benefit from a clearer intuitive explanation upfront before diving into technical details. The jazz metaphor I used above isn’t in the paper — that’s a gap. Good papers make the core idea graspable in 30 seconds.
Verdict: Weak accept — The problem is real and the solution is sensible, but the execution feels incremental. It’s a solid engineering contribution (mixing three data sources smartly) rather than a conceptual breakthrough. The experimental results are strong enough to publish, but the method’s generality beyond tool-use tasks is unclear. Worth reading if you’re working on RL for LLMs; skip if you’re looking for fundamental insights.
Takeaways
-
Branching from anchors: Instead of pure exploration or pure imitation, use expert trajectories as starting points and let the model diverge. This pattern applies beyond tool-use — any domain where you have some expert data but need the model to generalize beyond it.
-
Gradient conflict resolution: When multiple training objectives share early-stage representations, explicitly separate their optimization paths before merging. This is a general technique for multi-task learning.
-
Dynamic weighting of data sources: Rather than a fixed train/val split or a static curriculum, learn which data source to sample from at each step. This could transfer to other curriculum learning problems.
-
ROI as a metric: Combining performance, data cost, and training efficiency into a single number is pragmatic. If you’re shipping models, this beats optimizing for any single metric.
论文: 2604.09455 作者: Weiyang Guo, Zesheng Shi, Liye Zhao, Jiayuan Ma, Zeen Zhu, Junxian He, Min Zhang, Jing Li 分类: cs.AI
缺口
工具集成推理(TIR)——让LLM使用API、计算器或搜索引擎等外部工具——陷入了两个坏选项之间。 零RL训练从零开始,模型浪费计算资源探索死胡同,最终陷入重复相同成功模式的困境(模式退化)。 SFT-then-RL通过在专家示范上预训练来解决这个问题,但随后遇到瓶颈:需要大量合成数据,模型性能停滞不前,因为它被困在低熵分布中——本质上,它学会了模仿专家的风格而不是学会推理。
真正的问题在于:这些方法把专家知识和自主探索视为对立面。 你要么跟随专家(安全但僵化),要么自由探索(灵活但浪费)。 没有中间地带让你从专家锚点出发分支探索,同时保持扎根。
零RL:            SFT-then-RL:       E3-TIR(本文):
野蛮探索    →     跟随专家      →    从锚点分支
(浪费)          (僵化)           (扎根+灵活)
  |                 |                    |
  v                 v                    v
模式崩溃      低熵陷阱            平衡学习
增量
之前:你要么选择探索(昂贵、混乱),要么选择模仿(便宜、停滞)。 之后:你可以动态混合两者,用专家轨迹作为受控分支的跳板,降低数据成本同时保持学习速度。
核心机制
E3-TIR将训练视为三向混合。 在每一步,模型从三个经验源中采样:(1)专家前缀——专家轨迹的前N步,然后模型自己继续;(2)专家引导——模型探索但在偏离太远时被轻轻推回专家路径;(3)自主探索——纯RL,无护栏。 关键洞察是这三者不是分离的训练运行——它们在单个批次中交织在一起,通过”混合策略”学习在每个训练阶段哪个比例最有效。
该机制还处理了一个微妙问题:当你在多个轨迹中使用共享专家前缀时,来自不同分支的模型梯度可能会冲突。 E3-TIR通过将每个分支视为独立优化问题,然后小心地合并更新以防止它们相互抵消来解决这个问题。
专家轨迹:  S0 -> S1 -> S2 -> S3 -> S4(目标)
            |     |     |
            +-----+-----+--- 专家前缀
                  |
                  +--- 专家引导(偏离时推回)
                  |
                  +--- 自主探索(自由漫游)

混合策略学习:何时使用哪个源
把它想象成一个向指挥学习的爵士乐团。 指挥(专家)演奏开场乐句。 一些音乐家(专家前缀)演奏开场,然后自由即兴。 另一些(专家引导)即兴但保持一只耳朵听指挥的和声结构。 少数(自主探索)就是随意演奏。 乐团指挥(混合策略)决定在每个小节中展示多少种类型。 早期,更多音乐家跟随指挥。 随着他们变得更好,更多人即兴演奏。 魔法在于他们都在同一个房间里一起演奏,实时从彼此的错误中学习,而不是分开练习。
关键概念
-
模式退化:当RL智能体找到一个成功策略时,它停止探索并永远重复它。 想象一个机器人学会了通过推动来打开门——它随后在每个问题上都推动,即使拉动会更有效。 E3-TIR通过混合引导和自主探索分支来防止这种情况,这些分支奖励找到不同的解决方案。
-
低熵崩溃:在专家数据上进行SFT后,模型的输出分布变得狭窄——它学会了如此完美地模仿专家的风格,以至于即使应该偏离也无法偏离。 就像一个学生逐字逐句背诵了老师的讲座,但无法回答稍微不同的问题。 E3-TIR通过明确分配计算资源进行自主探索来保持熵高,迫使模型保持创意。
-
分布转移:当你在专家数据上训练然后切换到RL时,模型看到轨迹外观的突然变化(专家vs.自生成)。 这种冲击导致不稳定。 E3-TIR通过逐步增加自主探索比例来平滑这一过程,使模型逐步适应而不是一次性适应。
框架转变
之前(主流方法):                之后(本文方法):

专家数据    RL训练                专家数据
  |          |                       |
  v          v                       v
SFT      微调                    混合策略
  |          |                    /  |  \
  +----+-----+            专家  引导  自主
       |                  前缀  探索  探索
       v                    |    |    |
     智能体                 +----+----+
                                 |
                                 v
                              智能体
                            (自适应)

从:顺序阶段(SFT然后RL)
到:并行混合与动态加权
核心转变:从将专家知识和探索视为顺序阶段,转变为将它们视为单一训练过程的并发、动态加权组件。
专家评审
选题眼光:这是真实的缺口。 SFT-then-RL瓶颈在RL社区中是众所周知的,论文正确地指出问题不仅仅是数据成本——而是保持扎根和保持灵活之间的根本张力。 定位是稳健的。
方法成熟度:核心思想优雅但不是革命性的。 在训练期间混合不同数据源是标准做法;新颖之处在于如何混合(三向分割与动态加权)和为什么有效(解决共享前缀的梯度冲突)。 混合策略机制在摘要中感觉有点不够具体——我想看看它实际上是如何学习的。 是单独的网络吗? 手工调整的时间表吗? 这对可重现性很重要。
实验诚意:6倍改进令人印象深刻,但我会仔细审查基线。 他们是在与最佳SFT-then-RL设置比较,还是与稻草人比较? “少于10%的合成数据”声明很强——绝对数字是多少? 此外,ROI指标(1.46×)很有趣但感觉是精心挑选的。 为什么是性能、数据成本和训练效率的这个特定组合? 如果你以不同的方式加权它们会怎样? 论文需要在这里显示敏感性分析。
写作功力:摘要密集且充满术语(“低熵崩溃”、“分布转移”、“共享前缀”)。 论文会受益于在深入技术细节之前更清晰的直观解释。 我上面使用的爵士乐比喻不在论文中——这是一个缺口。 好论文让核心思想在30秒内可以理解。
判决:弱接收 — 问题是真实的,解决方案是合理的,但执行感觉是增量的。 这是一个坚实的工程贡献(聪明地混合三个数据源)而不是概念突破。 实验结果足够强大可以发表,但该方法在工具使用任务之外的通用性不清楚。 如果你在从事LLM的RL工作,值得阅读;如果你在寻找基础洞见,可以跳过。
要点总结
-
从锚点分支:与其纯探索或纯模仿,不如使用专家轨迹作为起点并让模型发散。 这个模式适用于工具使用之外——任何有一些专家数据但需要模型超越它的领域。
-
梯度冲突解决:当多个训练目标共享早期阶段表示时,在合并之前明确分离它们的优化路径。 这是多任务学习的通用技术。
-
数据源的动态加权:与其固定的训练/验证分割或静态课程,不如学习在每一步从哪个数据源采样。 这可以迁移到其他课程学习问题。
-
ROI作为指标:将性能、数据成本和训练效率组合成单个数字是务实的。 如果你在发布模型,这比优化任何单一指标更好。