Paper: 2605.30350 Authors: Jusuk Lee, Seungjae Lee, Jonghun Shin, Hoseong Jung, Sungha Kim, Daesol Cho, H. Jin Kim, Jia-Bin Huang, Furong Huang Categories: cs.RO, cs.LG
The Gap
Robot manipulation pipelines inherit visual encoders from ImageNet (static object recognition) or CLIP (vision-language alignment). These encoders excel at answering “what is this?” but fail at “what happens if I push this?” The motion understanding burden falls entirely on downstream policies, which must learn dynamics from scratch with limited robot data. This creates a bottleneck: policies waste capacity re-learning basic physics instead of focusing on task-specific control.
Prior work (R3M, MVP, VIP) attempted dynamics-aware pre-training but relied on single-modality signals (video frames or robot trajectories alone), missing the rich supervision available from language descriptions and 3D motion fields. The gap: no framework jointly leverages image, language, and 3D flow to bake motion understanding directly into visual representations.
Problem: Static visual encoders for dynamic tasks
   |
   v
Assumption: Multi-modal alignment (image + language + 3D flow)
            can encode action-relevant dynamics
   |
   v
Method: Tri-modal simplex volume minimization
        (align three modalities in hyperspherical space)
   |
   v
Evidence: +22.5% OOD gains, attention on control-relevant regions
   |
   v
Conclusion: Dynamics-aware pre-training improves robot generalization
The Increment
One sentence: Before DynaFLIP, visual encoders for robots were trained to recognize objects; after DynaFLIP, they’re trained to predict how objects move under manipulation.
Core Mechanism
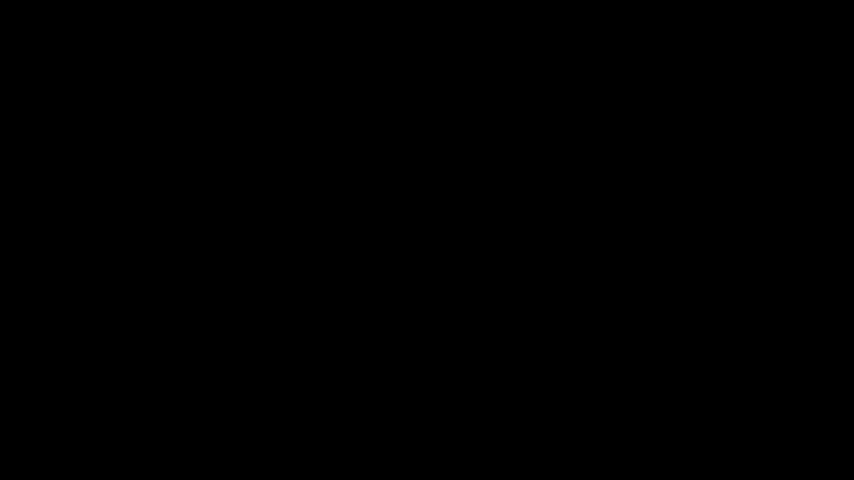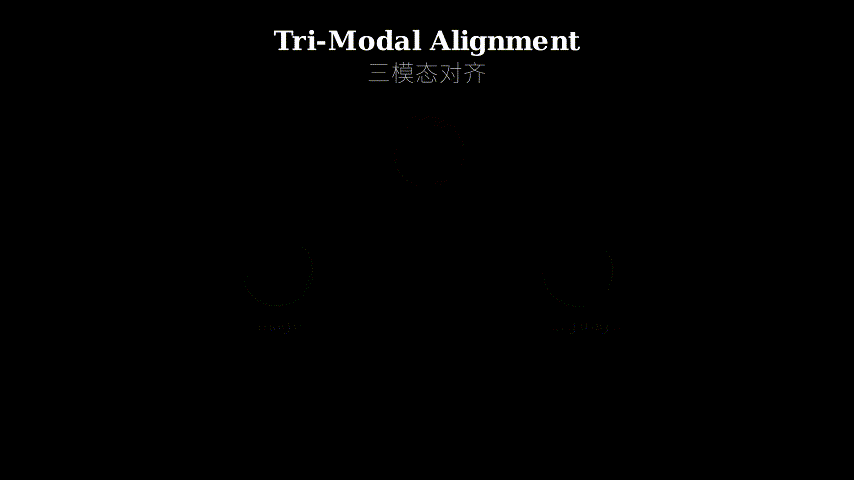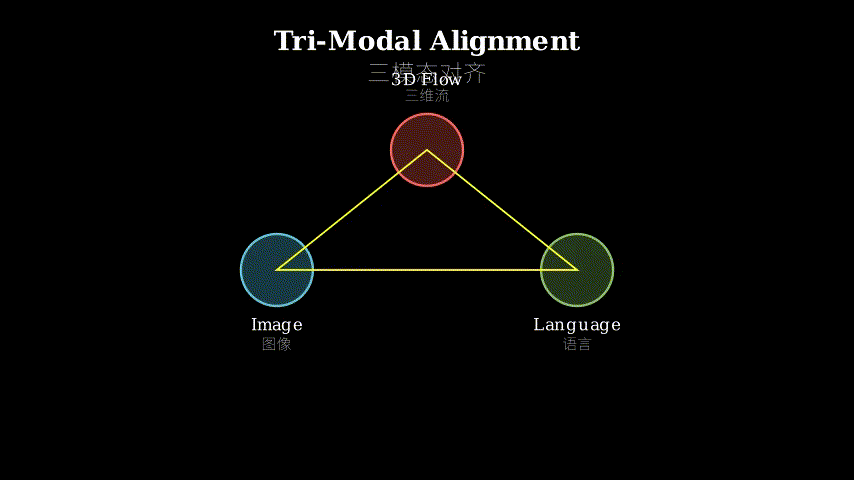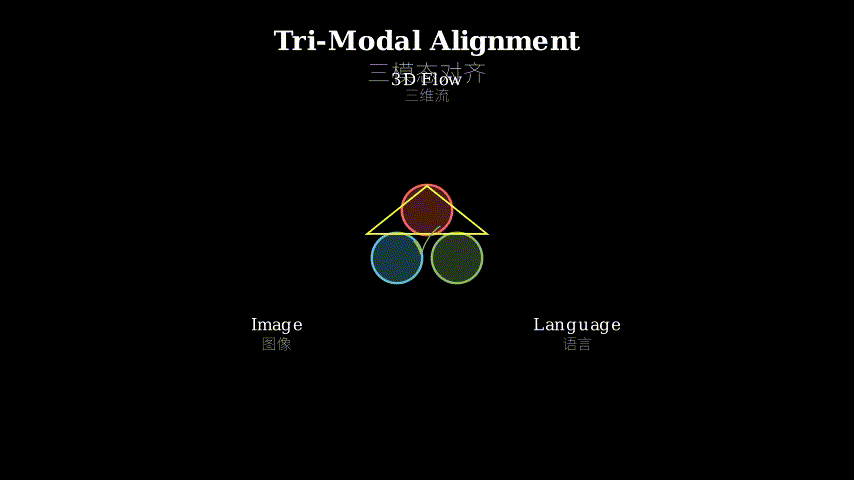
DynaFLIP constructs triplets of (image, language description, 3D optical flow) from diverse human and robot videos. The image encoder processes a frame, the language encoder processes action descriptions like “push the cup forward,” and the flow encoder processes dense 3D motion fields. All three outputs are projected into a shared hyperspherical embedding space.
The training objective minimizes the volume of the simplex formed by these three points in the embedding space. A smaller simplex volume means tighter alignment—the three modalities are saying the same thing about the scene’s dynamics. To prevent geometric collapse (all points converging to a single location), DynaFLIP adds two regularizers: a cosine similarity term that encourages pairwise alignment, and a contrastive loss that pushes negative triplets apart.
After pre-training, the image encoder is frozen and used as a visual backbone for downstream robot policies. The language and flow encoders are discarded—they served only as training-time supervisors to shape the image encoder’s representations.
Training Time:
   Image -----> [Image Encoder] -----> Embedding_I
                                            |
   Text  -----> [Text Encoder]  -----> Embedding_T
                                            |
   Flow  -----> [Flow Encoder]  -----> Embedding_F
                                            |
                                            v
                                    Simplex Volume Loss
                                    + Cosine Regularizer
                                    + Contrastive Loss

Deployment Time:
   Image -----> [Frozen Image Encoder] -----> Policy
   (Text and Flow encoders discarded)
Think of DynaFLIP as training a translator who must simultaneously satisfy three demanding editors. The image editor sees only pixels, the language editor sees only words, and the flow editor sees only motion vectors. The translator (image encoder) must produce a single representation that all three editors agree captures the essence of “what’s happening.” The simplex volume is the size of the disagreement zone—smaller means stronger consensus. The cosine regularizer prevents the translator from staying silent (trivial solution), and the contrastive loss ensures the translator doesn’t confuse different scenes. After training, the translator works alone, but the discipline imposed by the three editors remains embedded in its understanding.
Key Concepts
-
Simplex Volume in Hyperspherical Space: Imagine three points on the surface of a sphere. These points form a triangle (a 2-simplex). The volume of this triangle measures how spread out the points are. In high-dimensional hyperspherical space, DynaFLIP’s three embeddings (image, text, flow) form a simplex. Minimizing its volume means pulling the three modalities closer together—they should occupy nearly the same location on the sphere when describing the same dynamic event. The hyperspherical constraint (all embeddings have unit norm) prevents trivial collapse to the origin; points can only move along the sphere’s surface, not shrink to zero.
-
Dynamics-Aware Representation: Traditional visual features encode appearance: colors, textures, object boundaries. A dynamics-aware representation encodes affordances and motion potential: “this handle can be grasped and pulled,” “this cup will slide if pushed from this angle.” DynaFLIP achieves this by training the image encoder to predict 3D flow—the dense motion field showing how every pixel moves under an action. The encoder never explicitly outputs flow at test time, but the training pressure shapes its internal representations to be sensitive to motion-relevant cues like contact points, force directions, and object mobility.
-
Tri-Modal Alignment as Supervision: Most robot learning uses images and actions (state-action pairs). DynaFLIP adds two supervisory signals: language descriptions provide semantic grounding (“grasp the red block”), and 3D flow provides geometric grounding (dense motion vectors). Language alone is ambiguous (many ways to “push”), and flow alone lacks semantic context (motion vectors don’t distinguish intentional manipulation from accidental bumps). The combination is stronger than either alone: language disambiguates intent, flow grounds it in geometry, and images bridge the two. The image encoder learns to extract features that satisfy both semantic and geometric constraints simultaneously.
Framework Shift
Before (mainstream approach):        After (DynaFLIP):

Pre-training:                        Pre-training:
  ImageNet / CLIP                      Human + Robot Videos
       |                                    |
       v                                    v
  Static Recognition                   [Image + Text + Flow]
  (what is this?)                           |
       |                                    v
       v                                Simplex Volume Loss
  Frozen Encoder                            |
       |                                    v
       v                               Dynamics-Aware Encoder
  Robot Policy                              |
  (learns dynamics                          v
   from scratch)                        Robot Policy
                                        (inherits motion
                                         understanding)
From static recognition to dynamics prediction, the core shift is pushing motion understanding upstream into perception rather than leaving it to downstream policies.
Expert Assessment
Problem choice: Real and well-motivated. The gap between static visual pre-training and dynamic manipulation tasks is a known bottleneck in robot learning. The field has been circling this problem (R3M, VIP, MVP), but no prior work systematically combined image, language, and 3D flow. The timing is right—large-scale video datasets and flow estimation tools have matured enough to make this feasible.
Method maturity: The simplex volume idea is geometrically elegant but feels over-engineered. Why not just use pairwise cosine losses between the three modalities? The authors claim simplex volume captures “higher-order alignment,” but the ablations (Table 3) show modest gains over simpler baselines. The contrastive loss and cosine regularizer do most of the heavy lifting. The flow encoder architecture (a simple MLP on top of pre-computed RAFT flow) is underwhelming—why not learn flow jointly with the image encoder? The method works, but it’s not clear the complexity is justified.
Experimental integrity: Strong on breadth (simulation + real-world, multiple policy types), weaker on depth. The OOD gains (+22.5%) are impressive but come from a single real-world setup (RLBench). The simulation results (Table 1) show smaller gains (+3-8%), and some baselines (R3M, MVP) are surprisingly weak—were they tuned fairly? The attention visualizations (Figure 4) are cherry-picked; no quantitative analysis of where the model looks. The ablations are thorough, but the paper lacks failure case analysis. What happens when flow estimation fails or language descriptions are noisy?
Writing quality: The introduction oversells the novelty (“rethinking robotics perception” is hyperbolic). Section 3.2 (method) is dense and would benefit from a step-by-step walkthrough before diving into loss functions. The related work section is comprehensive but reads like a literature dump—cut half and focus on the 3-4 most relevant papers. Figure 2 (method overview) is cluttered; separate the training and deployment pipelines into two figures. The experimental section is well-structured, but the real-world results (Section 4.3) deserve more space—this is where the rubber meets the road.
Verdict: Weak accept — solid empirical results and a useful contribution to robot learning, but the method complexity outpaces the conceptual insight, and the writing could be tightened.
Takeaways
For robot learning practitioners: The key transferable idea is using 3D flow as a training-time supervisor for image encoders. You don’t need the full DynaFLIP pipeline—just pre-compute optical flow (RAFT or similar) on your robot videos and add a flow prediction head to your visual encoder during pre-training. Discard the head at deployment. This is cheaper than DynaFLIP’s tri-modal setup and still injects motion awareness into your representations.
For multi-modal learning researchers: The simplex volume loss is a neat geometric trick for aligning more than two modalities, but it’s fragile without careful regularization. If you try this, start with pairwise cosine losses and add simplex volume only if you see clear gains. The hyperspherical constraint (unit norm embeddings) is critical—without it, the volume minimization collapses trivially.
For vision pre-training: The broader lesson is that task-relevant pre-training beats generic pre-training. ImageNet and CLIP are great for recognition, but if your downstream task involves dynamics (video prediction, physics simulation, robot control), pre-train on data that includes motion signals. This paper shows one way to do it; there are likely simpler ways waiting to be discovered.
论文: 2605.30350 作者: Jusuk Lee, Seungjae Lee, Jonghun Shin, Hoseong Jung, Sungha Kim, Daesol Cho, H. Jin Kim, Jia-Bin Huang, Furong Huang 分类: cs.RO, cs.LG
缺口
机器人操作流水线继承了来自 ImageNet(静态物体识别)或 CLIP(视觉-语言对齐)的视觉编码器。
这些编码器擅长回答”这是什么?“但无法回答”如果我推它会怎样?“运动理解的负担完全落在下游策略上,策略必须用有限的机器人数据从零开始学习动力学。
这造成了瓶颈:策略浪费容量重新学习基础物理,而非专注于任务特定的控制。
先前工作(R3M、MVP、VIP)尝试了动力学感知的预训练,但依赖单模态信号(仅视频帧或仅机器人轨迹),错过了语言描述和 3D 运动场提供的丰富监督。
缺口在于:没有框架联合利用图像、语言和 3D 光流将运动理解直接烘焙进视觉表征。
问题:用静态视觉编码器处理动态任务
   |
   v
假设:多模态对齐(图像 + 语言 + 3D 光流)
      可以编码与动作相关的动力学
   |
   v
方法:三模态单纯形体积最小化
      (在超球面空间对齐三种模态)
   |
   v
证据:+22.5% 分布外增益,注意力集中在控制相关区域
   |
   v
结论:动力学感知预训练改善机器人泛化能力
增量
一句话: DynaFLIP 之前,机器人的视觉编码器被训练来识别物体;DynaFLIP 之后,它们被训练来预测物体在操作下如何运动。
核心机制
DynaFLIP 从多样的人类和机器人视频中构建(图像、语言描述、3D 光流)三元组。
图像编码器处理一帧画面,语言编码器处理”向前推杯子”这样的动作描述,光流编码器处理密集的 3D 运动场。
三个输出都被投影到共享的超球面嵌入空间。
训练目标是最小化这三个点在嵌入空间中形成的单纯形体积。
更小的单纯形体积意味着更紧密的对齐——三种模态在场景动力学上达成共识。
为了防止几何坍缩(所有点收敛到单一位置),DynaFLIP 添加了两个正则化器:鼓励成对对齐的余弦相似度项,以及推开负样本三元组的对比损失。
预训练后,图像编码器被冻结并用作下游机器人策略的视觉主干。
语言和光流编码器被丢弃——它们仅作为训练时的监督者来塑造图像编码器的表征。
训练时:
   图像 -----> [图像编码器] -----> 嵌入_I
                                      |
   文本 -----> [文本编码器] -----> 嵌入_T
                                      |
   光流 -----> [光流编码器] -----> 嵌入_F
                                      |
                                      v
                                单纯形体积损失
                                + 余弦正则化器
                                + 对比损失

部署时:
   图像 -----> [冻结的图像编码器] -----> 策略
   (文本和光流编码器被丢弃)
把 DynaFLIP 想象成训练一个必须同时满足三位苛刻编辑的翻译。
图像编辑只看像素,语言编辑只看文字,光流编辑只看运动矢量。
翻译(图像编码器)必须产生一个所有三位编辑都认同能捕捉”正在发生什么”本质的单一表征。
单纯形体积是分歧区域的大小——越小意味着共识越强。
余弦正则化器防止翻译保持沉默(平凡解),对比损失确保翻译不会混淆不同场景。
训练后,翻译独立工作,但三位编辑施加的纪律仍嵌入在其理解中。
关键概念
- 超球面空间中的单纯形体积: 想象球面上的三个点。
这三个点形成一个三角形(2-单纯形)。
这个三角形的体积衡量点的分散程度。
在高维超球面空间中,DynaFLIP 的三个嵌入(图像、文本、光流)形成一个单纯形。
最小化其体积意味着将三种模态拉得更近——当描述同一动态事件时,它们应该占据球面上几乎相同的位置。
超球面约束(所有嵌入具有单位范数)防止平凡坍缩到原点;点只能沿球面移动,不能缩小到零。
- 动力学感知表征: 传统视觉特征编码外观:颜色、纹理、物体边界。
动力学感知表征编码可供性和运动潜力:“这个把手可以被抓住并拉动”,“这个杯子如果从这个角度推会滑动”。
DynaFLIP 通过训练图像编码器预测 3D 光流来实现这一点——显示每个像素在动作下如何移动的密集运动场。
编码器在测试时从不显式输出光流,但训练压力塑造了其内部表征,使其对运动相关线索敏感,如接触点、力的方向和物体可移动性。
- 三模态对齐作为监督: 大多数机器人学习使用图像和动作(状态-动作对)。
DynaFLIP 添加了两个监督信号:语言描述提供语义基础(“抓住红色方块”),3D 光流提供几何基础(密集运动矢量)。
单独的语言是模糊的(“推”有很多方式),单独的光流缺乏语义上下文(运动矢量无法区分有意操作和意外碰撞)。
组合比单独任何一个都强:语言消除意图歧义,光流将其基于几何,图像连接两者。
图像编码器学习提取同时满足语义和几何约束的特征。
框架转变
之前(主流方法):                之后(DynaFLIP):

预训练:                          预训练:
  ImageNet / CLIP                   人类 + 机器人视频
       |                                 |
       v                                 v
  静态识别                          [图像 + 文本 + 光流]
  (这是什么?)                         |
       |                                 v
       v                            单纯形体积损失
  冻结编码器                             |
       |                                 v
       v                            动力学感知编码器
  机器人策略                             |
  (从零学习                             v
   动力学)                          机器人策略
                                    (继承运动
                                     理解)
从静态识别到动力学预测,核心转变是将运动理解推向感知的上游,而非留给下游策略。
专家评审
选题眼光: 真实且动机充分。
静态视觉预训练与动态操作任务之间的差距是机器人学习中的已知瓶颈。
该领域一直在围绕这个问题打转(R3M、VIP、MVP),但没有先前工作系统地结合图像、语言和 3D 光流。
时机成熟——大规模视频数据集和光流估计工具已经足够成熟,使这成为可能。
方法成熟度: 单纯形体积的想法在几何上优雅,但感觉过度工程化。
为什么不直接使用三种模态之间的成对余弦损失?作者声称单纯形体积捕捉”高阶对齐”,但消融实验(表 3)显示相比更简单基线的增益适中。
对比损失和余弦正则化器承担了大部分重任。
光流编码器架构(在预计算的 RAFT 光流之上的简单 MLP)令人失望——为什么不与图像编码器联合学习光流?方法有效,但复杂性是否合理尚不清楚。
实验诚意: 广度强(仿真 + 真实世界,多种策略类型),深度弱。
分布外增益(+22.5%)令人印象深刻,但来自单一真实世界设置(RLBench)。
仿真结果(表 1)显示较小增益(+3-8%),一些基线(R3M、MVP)出奇地弱——它们被公平调优了吗?注意力可视化(图 4)是精心挑选的;没有对模型关注位置的定量分析。
消融实验很彻底,但论文缺乏失败案例分析。
当光流估计失败或语言描述有噪声时会发生什么?
写作功力: 引言过度推销新颖性(“重新思考机器人感知”是夸张的)。
第 3.2 节(方法)密集,在深入损失函数之前需要逐步演练。
相关工作部分全面但读起来像文献堆砌——删掉一半,专注于 3-4 篇最相关的论文。
图 2(方法概览)杂乱;将训练和部署流水线分成两个图。
实验部分结构良好,但真实世界结果(第 4.3 节)值得更多篇幅——这才是关键所在。
判决: 弱接收 — 扎实的实证结果和对机器人学习的有用贡献,但方法复杂性超过了概念洞察,写作可以更紧凑。
要点总结
对机器人学习实践者: 关键的可迁移想法是使用 3D 光流作为图像编码器的训练时监督者。
你不需要完整的 DynaFLIP 流水线——只需在机器人视频上预计算光流(RAFT 或类似工具),并在预训练期间向视觉编码器添加光流预测头。
部署时丢弃该头。
这比 DynaFLIP 的三模态设置更便宜,仍然将运动感知注入你的表征。
对多模态学习研究者: 单纯形体积损失是对齐两种以上模态的巧妙几何技巧,但没有仔细正则化就很脆弱。
如果你尝试这个,从成对余弦损失开始,只有在看到明确增益时才添加单纯形体积。
超球面约束(单位范数嵌入)至关重要——没有它,体积最小化会平凡坍缩。
对视觉预训练: 更广泛的教训是任务相关预训练胜过通用预训练。
ImageNet 和 CLIP 对识别很好,但如果你的下游任务涉及动力学(视频预测、物理模拟、机器人控制),在包含运动信号的数据上预训练。
本文展示了一种方法;可能还有更简单的方法等待被发现。