Paper: 2603.12250 Authors: Hongfei Zhang, Harold Haodong Chen, Chenfei Liao, Jing He, Zixin Zhang, Haodong Li, Yihao Liang, Kanghao Chen, Bin Ren, Xu Zheng Categories: cs.CV
The Gap
Video depth estimation has two camps, and both are stuck.
Generative models (think Marigold, DepthCrafter) borrow the rich visual priors baked into diffusion models. The problem: diffusion is inherently stochastic. Run it twice, get two different depth maps. Across video frames, this produces “geometric hallucinations” — surfaces that flicker, scale that drifts, geometry that contradicts itself temporally. You can average over multiple samples to stabilize, but that’s expensive and still doesn’t fully fix the consistency problem.
Discriminative models (think UniDepth, Depth Anything) are deterministic and fast. But they’re hungry — they need massive labeled datasets to learn the semantic cues that resolve depth ambiguity (is that a dark patch a shadow or a hole?). Collecting metric depth labels at scale is genuinely hard, so these models hit a ceiling defined by annotation cost.
The gap: nobody has successfully converted a generative video model into a deterministic regressor while preserving the geometric priors that made the generative model good in the first place.
Problem: Generative = stochastic + hallucinations
         Discriminative = deterministic + data-hungry
         |
         v
Assumption: Diffusion models encode deep geometric priors
            that can be unlocked without the stochastic sampling loop
         |
         v
Method: Freeze backbone, repurpose timestep as anchor,
        add LMR for sharpness, global affine coherence for long video
         |
         v
Evidence: SOTA zero-shot on multiple benchmarks,
          163x less training data than leading baselines
         |
         v
Conclusion: Generative priors + deterministic inference is achievable
            and data-efficient
The Increment
One sentence: Before DVD, you had to choose between geometric richness (generative, stochastic) and reliable determinism (discriminative, data-hungry) — DVD shows you can have both by treating diffusion as a feature extractor rather than a sampler.
Core Mechanism
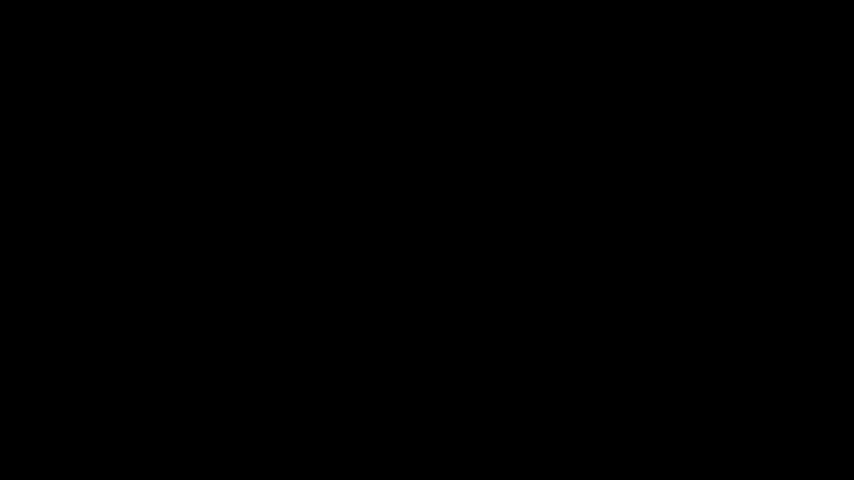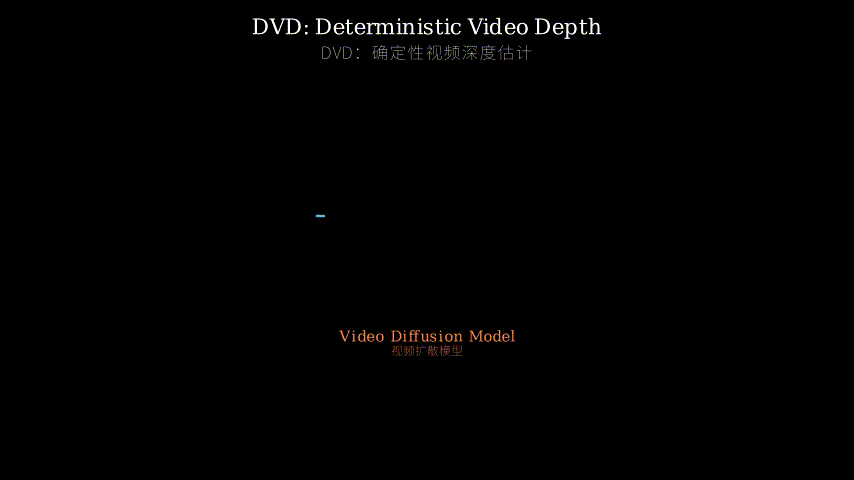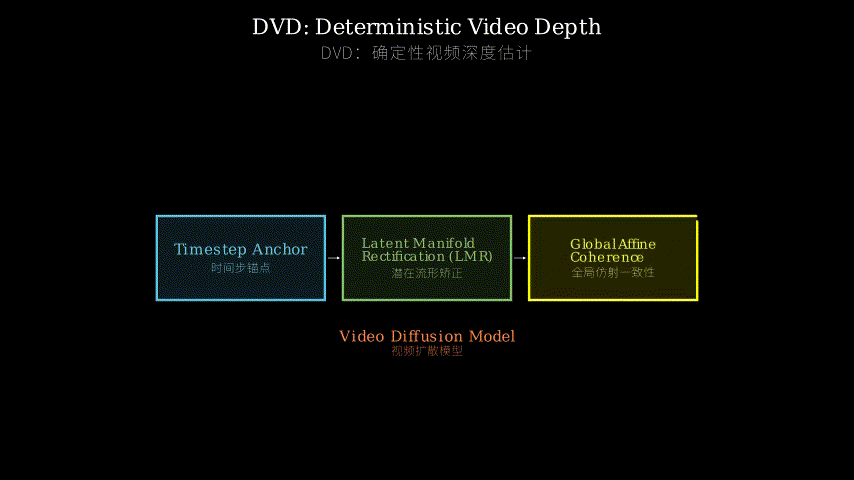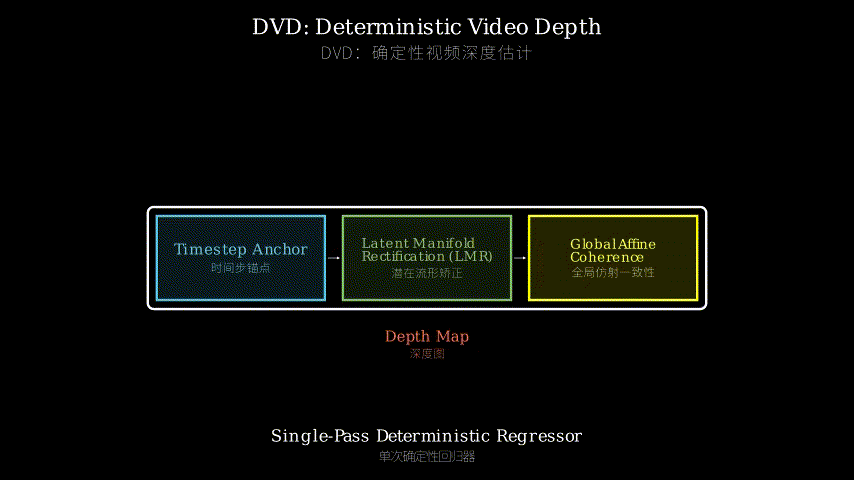
DVD takes a pre-trained video diffusion model and surgically converts it into a depth regressor. The key insight is that the diffusion model’s internal representations already encode geometry — the denoising process has learned what surfaces, edges, and spatial relationships look like. You don’t need to run the full stochastic sampling chain to access those representations.
The first design is the timestep anchor. In normal diffusion, the timestep tells the network “how noisy is this input right now.” DVD fixes the timestep at a specific value during inference — not running the denoising chain, just using that fixed timestep as a conditioning signal. This turns out to balance two things: low timesteps give you fine-grained detail sensitivity, high timesteps give you global structural stability. Picking the right fixed value lets you tune this trade-off once and bake it in.
The second design is Latent Manifold Rectification (LMR). When you convert a generative model to a regressor, the training objective changes from “reconstruct the data distribution” to “minimize regression loss.” This tends to produce over-smoothed outputs — the model hedges its bets and blurs boundaries. LMR adds a differential constraint during training that penalizes smoothing at edges, essentially telling the model “if there’s a sharp boundary in the input, preserve it in the depth map.” The third design is global affine coherence — a property they derive showing that across temporal windows, the predicted depth maps are bounded in how much their global scale and shift can diverge. This means you can process long videos in chunks and stitch them without complex post-hoc alignment.
Input Video Frames
       |
       v
  +--------------------+
  | Video Diffusion    |
  | Backbone (frozen)  |  <-- fixed timestep t* as structural anchor
  +--------------------+
       |
       | latent features (rich geometric priors)
       v
  +--------------------+
  | Depth Regression   |
  | Head               |  <-- trained on task-specific data (163x less)
  +--------------------+
       |
       | raw depth (over-smoothed)
       v
  +--------------------+
  | LMR                |
  | (differential      |  <-- restores sharp boundaries + motion edges
  |  constraints)      |
  +--------------------+
       |
       v
  Depth Map (sharp, temporally coherent)
       |
  [long video: global affine coherence bounds window-to-window drift]
Think of it like a master chef’s knife being repurposed as a scalpel. The knife (diffusion model) was forged with incredible metallurgy — the steel knows how to hold an edge, the balance is perfect, the geometry is refined over years. A scalpel needs different things: precision over power, determinism over versatility. You don’t reforge the steel (retrain the backbone). Instead, you reshape the handle (add a regression head), add a depth stop (timestep anchor so you always cut to the same depth), and add a guide rail (LMR to keep the cut clean at boundaries). The knife’s metallurgy — its geometric priors — transfers completely. The scalpel’s precision comes from the new fixtures, not new steel.
Key Concepts
-
Stochastic geometric hallucination: In diffusion-based depth estimation, the model samples from a probability distribution over possible depth maps. Two runs of the same model on the same frame can produce geometrically inconsistent results — a wall might be at depth 2m in one sample and 2.3m in another. Across video frames, this compounds into flickering and drift. It’s not noise in the signal-processing sense; it’s the model genuinely being uncertain and expressing that uncertainty as variation. The problem is that for downstream tasks (3D reconstruction, robotics), you need one answer, not a distribution.
-
Latent Manifold Rectification (LMR): When you train a model with L1 or L2 regression loss, it learns to minimize average error. At ambiguous boundaries — where depth changes sharply — the safest bet for minimizing average error is to predict a smooth transition rather than a sharp edge. LMR adds a term that explicitly penalizes this smoothing by comparing spatial gradients in the prediction against gradients in the input. If the input has a strong edge, the depth map should too. “Manifold” here refers to the idea that valid depth maps live on a lower-dimensional surface in the space of all possible depth maps — LMR pushes predictions back onto that surface.
-
Global affine coherence: Depth maps are often predicted up to an unknown scale and shift (affine ambiguity). For long videos processed in windows, each window might drift in its global scale. This paper derives a bound showing that their architecture’s outputs across windows can only differ by a bounded affine transformation — meaning the drift is controlled and predictable, not unbounded. This is what lets them skip the complex temporal alignment post-processing that other methods need.
Framework Shift
Before (mainstream approach):        After (this paper):

  Generative path:                     Single deterministic path:
  Input -> Diffusion -> Sample         Input -> Frozen Diffusion
        -> Sample                             Backbone (fixed t*)
        -> Sample                             -> Regression Head
        -> Average -> Depth                   -> LMR
  (slow, stochastic, drifts)                  -> Depth
                                       (fast, deterministic, coherent)
  Discriminative path:
  Input -> Trained-from-scratch        Data requirement:
         Encoder                       163x LESS labeled data
         (needs massive labels)        (priors already in backbone)
         -> Depth
  (fast but data-hungry, misses
   subtle geometry)

  Long video:
  Window1 -> align -> Window2          Window1 -> Window2 -> Window3
          -> align -> Window3          (global affine coherence bounds
  (complex post-hoc alignment)          drift automatically)
From stochastic sampling or data-hungry training, the core shift is: treat the diffusion backbone as a frozen geometric prior extractor, not as a generative engine.
Expert Assessment
Problem choice: This is a real gap. The generative-vs-discriminative tension in depth estimation is well-documented, and the specific failure mode of temporal inconsistency in video diffusion depth is a genuine pain point for practitioners. The paper is well-positioned in the field’s trajectory — diffusion models have matured enough that “repurpose rather than retrain” is a credible research direction. Not manufactured.
Method maturity: The timestep-as-anchor idea is clever and underexplored. LMR is a reasonable engineering fix for a known regression pathology, though differential constraints on depth maps aren’t new in isolation — the novelty is applying them in this specific conversion context. The global affine coherence claim is the most interesting theoretical contribution, but the paper would benefit from a cleaner derivation. Overall: more clever insight than brute force, but the components are individually incremental; the value is in the combination.
Experimental integrity: The 163x data efficiency claim is striking and, if the baselines are fair, genuinely impressive. The concern is whether the comparison is apples-to-apples — leading baselines like DepthCrafter were trained on different data distributions with different objectives, so “163x less data” needs careful reading. Zero-shot benchmarks are the right evaluation choice. I’d want to see ablations on the timestep anchor value sensitivity and failure cases on scenes with unusual lighting or transparent surfaces, which are the classic stress tests for geometric priors.
Writing quality: The global affine coherence section feels rushed. It’s the most theoretically novel claim in the paper, but it’s presented more as an empirical observation than a derived property. If the authors tightened the mathematical argument there and showed exactly what assumptions it rests on, the paper would be significantly stronger. The LMR motivation is clear; the coherence derivation is not.
Verdict: weak accept — solid engineering contribution with a genuinely clever core idea, but the theoretical claims need more rigorous treatment and the experimental comparisons need clearer framing around data distribution differences.
Takeaways
The timestep-as-anchor trick is directly stealable for any task where you want to repurpose a diffusion model as a deterministic predictor. The insight — that a fixed timestep acts as a structural conditioning signal rather than a noise level — generalizes to optical flow, surface normals, or any dense prediction task where diffusion models have been applied generatively.
The LMR approach (adding differential constraints to fight regression-induced smoothing) is a clean, low-overhead fix that could be dropped into any dense regression pipeline where boundary sharpness matters. It’s not specific to depth or diffusion.
The broader framing — “frozen backbone as prior extractor, lightweight head as task adapter, minimal task-specific data” — is a template worth keeping in mind as foundation models get larger and labeled data stays expensive.
论文: 2603.12250 作者: Hongfei Zhang, Harold Haodong Chen, Chenfei Liao, Jing He, Zixin Zhang, Haodong Li, Yihao Liang, Kanghao Chen, Bin Ren, Xu Zheng 分类: cs.CV
缺口
视频深度估计领域有两个阵营,都卡住了。
生成模型(Marigold、DepthCrafter 这类)借用扩散模型里丰富的视觉先验。 问题在于:扩散本质上是随机的。 同一帧跑两次,得到两张不同的深度图。 跨帧累积下来,就出现”几何幻觉”——表面闪烁、尺度漂移、时序上自相矛盾的几何结构。 多次采样取平均可以稳定一些,但代价高昂,而且治标不治本。
判别模型(UniDepth、Depth Anything 这类)确定性强、速度快。 但它们很”饿”——需要海量标注数据才能学会消解深度歧义(那块暗区是阴影还是洞?)。 大规模采集度量深度标注本来就难,所以这类模型的天花板由标注成本决定。
缺口在这里:没有人成功地把生成式视频模型转化为确定性回归器,同时保留让生成模型表现优秀的几何先验。
问题:生成式 = 随机 + 几何幻觉
      判别式 = 确定性 + 数据饥渴
      |
      v
假设:扩散模型编码了深层几何先验
      无需随机采样循环也能解锁这些先验
      |
      v
方法:冻结主干,时间步作锚点,
      LMR 恢复锐度,全局仿射一致性处理长视频
      |
      v
证据:多个基准零样本 SOTA,
      训练数据比主流基线少 163 倍
      |
      v
结论:生成先验 + 确定性推理可以兼得,
      且数据效率极高
增量
一句话:DVD 之前,你必须在几何丰富性(生成式、随机)和可靠确定性(判别式、数据饥渴)之间二选一;DVD 证明了把扩散模型当特征提取器而非采样器,可以两者兼得。
核心机制
DVD 拿来一个预训练视频扩散模型,外科手术式地把它改造成深度回归器。 核心洞察是:扩散模型的内部表示已经编码了几何信息——去噪过程学会了表面、边缘和空间关系长什么样。 你不需要跑完整的随机采样链就能访问这些表示。
第一个设计是时间步锚点。 正常扩散里,时间步告诉网络”当前输入有多少噪声”。 DVD 在推理时把时间步固定在某个特定值——不跑去噪链,只把这个固定时间步作为条件信号。 这个设计平衡了两件事:低时间步给你细粒度细节敏感性,高时间步给你全局结构稳定性。 选对一个固定值,就能把这个权衡一次性烘焙进去。
第二个设计是潜在流形矫正(LMR)。 把生成模型转成回归器时,训练目标从”重建数据分布”变成”最小化回归损失”。 这往往产生过度平滑的输出——模型在边界处两边下注,把锐利边缘模糊掉。 LMR 在训练时加入微分约束,惩罚边缘处的平滑行为,本质上是告诉模型”输入里有锐利边界,深度图里也要保留”。
第三个设计是全局仿射一致性——他们推导出的一个性质,表明跨时序窗口的预测深度图在全局尺度和偏移上的偏差是有界的。 这意味着长视频可以分块处理再拼接,不需要复杂的后处理对齐。
输入视频帧
       |
       v
  +--------------------+
  | 视频扩散主干       |
  | (冻结参数)       |  <-- 固定时间步 t* 作结构锚点
  +--------------------+
       |
       | 潜在特征(富含几何先验)
       v
  +--------------------+
  | 深度回归头         |
  |                    |  <-- 用少 163 倍的任务数据训练
  +--------------------+
       |
       | 原始深度(过度平滑)
       v
  +--------------------+
  | LMR                |
  | (微分约束)       |  <-- 恢复锐利边界 + 运动边缘
  +--------------------+
       |
       v
  深度图(锐利、时序一致)
       |
  [长视频:全局仿射一致性自动约束窗口间漂移]
用一个核喻来理解:把主厨刀改造成手术刀。
主厨刀(扩散模型)是用顶级冶金工艺锻造的——钢材懂得如何保持锋利,平衡感完美,几何形状经过多年打磨。 手术刀需要不同的东西:精准胜于力量,确定性胜于通用性。 你不需要重新锻造钢材(重训主干)。 你只需要重塑刀柄(加回归头),加一个深度限位器(时间步锚点,让每次切割深度一致),再加一个导轨(LMR,让边界处的切割保持干净)。 刀的冶金工艺——它的几何先验——完整地迁移过来了。 手术刀的精准来自新夹具,而不是新钢材。
关键概念
- 随机几何幻觉:在基于扩散的深度估计中,模型从可能深度图的概率分布中采样。同一帧跑两次,可能得到几何上不一致的结果——一堵墙在一次采样里是 2 米,另一次是 2.3 米。跨视频帧累积,就变成闪烁和