
Paper: 2603.22280 Authors: Zhide Zhong, Junfeng Li, Junjie He, Haodong Yan, Xin Gong, Guanyi Zhao, Yingjie Cai, Jiantao Gao, Xu Yan, Bingbing Liu Categories: cs.CV, cs.RO
The Gap
Vision-Language-Action (VLA) models have reached a point where they can handle simple robotic tasks by mapping visual observations and language instructions directly to actions. But they hit a wall with complex, multi-step tasks. Recent work added Chain-of-Thought (CoT) reasoning—making robots “think before acting”—but these CoT-VLA models have two critical flaws: they use single-modal CoT (either visual or linguistic, not both), missing either low-level spatial details or high-level planning logic; and they decode reasoning steps autoregressively (one token at a time), creating latency bottlenecks and compounding errors.
Problem: Complex tasks need both spatial precision + logical planning
    |
    v
Limitation: Single-modal CoT can't capture both simultaneously
    |                                    |
    v                                    v
Visual CoT only                    Linguistic CoT only
(spatial details,                  (high-level planning,
 no planning logic)                 no spatial precision)
    |                                    |
    +------------------------------------+
                    |
                    v
        Additional bottleneck:
    Autoregressive decoding = slow + error accumulation
                    |
                    v
        Solution: DualCoT-VLA
    (parallel visual + linguistic reasoning)
                    |
                    v
        Evidence: SOTA on LIBERO, RoboCasa, real robots
                    |
                    v
        Conclusion: Dual-modal parallel reasoning > single-modal sequential
The Increment
One sentence: Before this paper, robots reasoned in one modality at a time sequentially; after, they reason in both visual and linguistic modalities simultaneously in parallel.
Core Mechanism
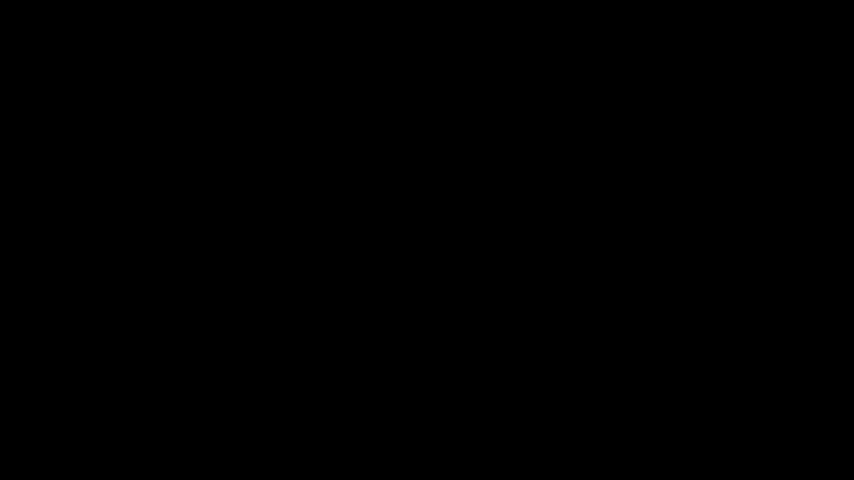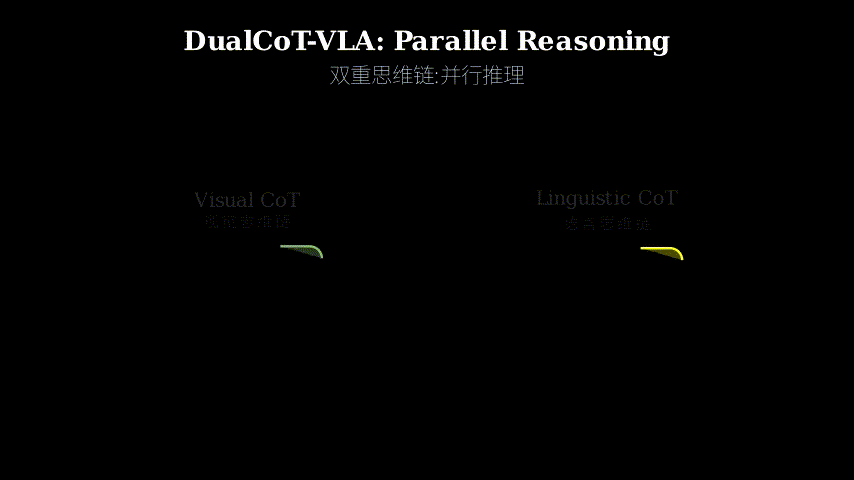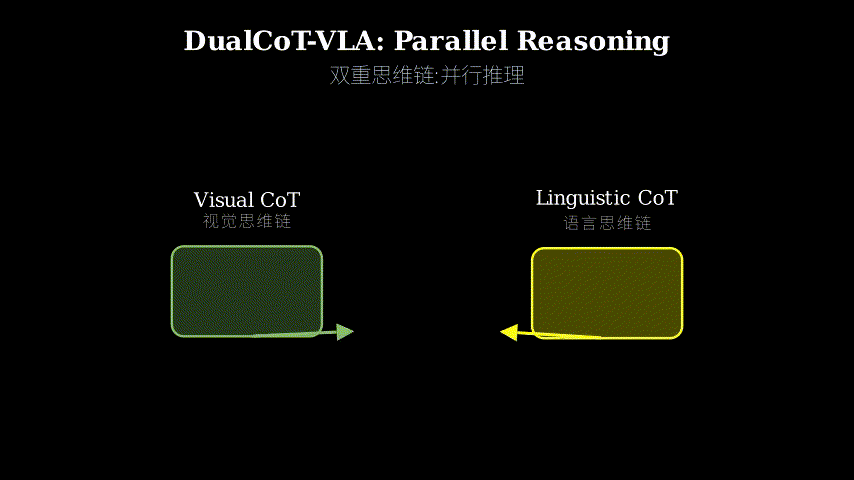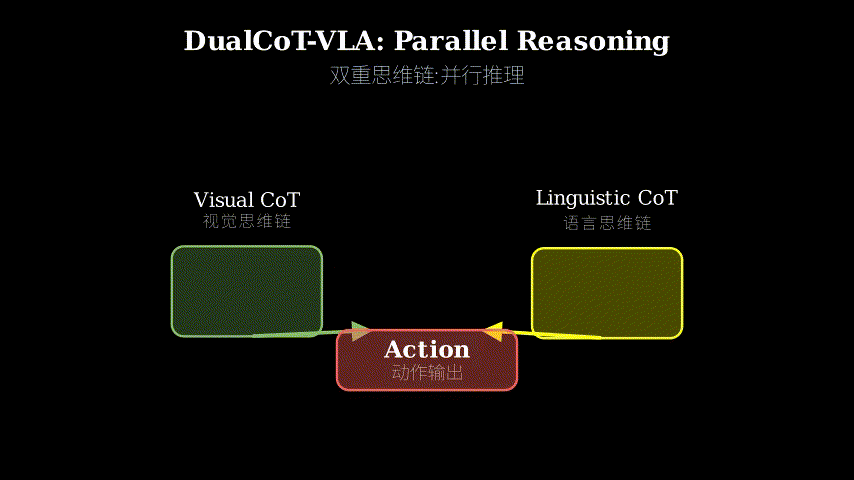
DualCoT-VLA has three main components: a visual CoT branch, a linguistic CoT branch, and a parallel reasoning mechanism. The visual CoT branch processes image observations through learnable query tokens to extract spatial relationships and low-level details—things like “the cup is 5cm to the left of the plate.” The linguistic CoT branch takes language instructions and generates high-level task plans—like “first grasp the cup, then move it to the sink.”
Instead of generating these reasoning chains token-by-token (which is slow), DualCoT-VLA uses two sets of learnable query tokens that are fed into the model in a single forward pass. The visual queries attend to image features, the linguistic queries attend to instruction embeddings, and both produce their reasoning outputs simultaneously. These dual reasoning outputs are then fused and fed into an action decoder that predicts the robot’s next action.
Input: Image + Language Instruction
    |
    +------------------+------------------+
    |                                     |
    v                                     v
Visual Query Tokens              Linguistic Query Tokens
    |                                     |
    v                                     v
[Attend to image features]      [Attend to instruction]
    |                                     |
    v                                     v
Visual CoT Output               Linguistic CoT Output
(spatial reasoning)             (task planning)
    |                                     |
    +------------------+------------------+
                       |
                       v
                 Fusion Layer
                       |
                       v
                 Action Decoder
                       |
                       v
                Robot Action
Think of it like a chef and a sous-chef working in parallel. The chef (linguistic CoT) reads the recipe and plans the sequence: “first dice onions, then sauté, then add tomatoes.” The sous-chef (visual CoT) watches the cutting board and stove, tracking spatial details: “the knife is 2 inches from the onion, the pan is at medium heat.” In traditional CoT, the chef would have to stop and ask the sous-chef about every detail sequentially—“where’s the knife? okay, now where’s the onion?”—which is slow and error-prone. In DualCoT-VLA, both work simultaneously, and their outputs merge at the moment of action: the chef’s plan says “dice now” and the sous-chef’s spatial awareness says “knife is positioned correctly,” so the action executes immediately.
Key Concepts
-
Chain-of-Thought (CoT) for Robots: In language models, CoT means generating intermediate reasoning steps before the final answer (“let’s think step by step”). For robots, it means generating intermediate reasoning about the task before executing actions. Instead of directly mapping “pick up the cup” to motor commands, the robot first reasons: “the cup is on the table, I need to approach from above, grasp with 3cm grip width, then lift.” This helps with complex tasks that require planning, but traditional CoT is sequential and slow—each reasoning step waits for the previous one to finish.
-
Learnable Query Tokens: These are special input tokens that aren’t tied to specific words or pixels—they’re learned parameters that the model trains to “ask questions” of the input. Imagine you’re at a museum with a guide. Instead of the guide describing every painting in order, you hand them a list of specific questions: “Which paintings have blue backgrounds? Which are from the 1800s?” The guide scans the room and answers all your questions at once. Learnable query tokens work the same way: they’re trained to extract specific types of information (spatial relationships, task steps) from the input in a single pass, rather than generating it token-by-token.
-
Parallel vs. Autoregressive Reasoning: Autoregressive means generating outputs one piece at a time, where each piece depends on the previous ones—like writing a sentence word-by-word, where you can’t write “dog” until you’ve written “the brown.” Parallel reasoning means generating all outputs simultaneously in one forward pass. The key insight: if you know what questions to ask (via learnable queries), you don’t need to wait for previous answers to formulate the next question. It’s the difference between a sequential interview (“tell me about step 1… okay, now step 2…”) and a survey form where you answer all questions at once.
Framework Shift
Before (CoT-VLA):                        After (DualCoT-VLA):

Input                                    Input
  |                                        |
  v                                        v
Single CoT Branch                      Dual CoT Branches
  |                                    /           \
  v                                   v             v
Step 1 reasoning                  Visual CoT    Linguistic CoT
  |                                (spatial)      (planning)
  v                                   |             |
Step 2 reasoning                      +------+------+
  |                                          |
  v                                          v
Step 3 reasoning                        Fusion
  |                                          |
  v                                          v
Action                                    Action

(Sequential, slow,                   (Parallel, fast,
 single modality)                     dual modality)
From sequential single-modal reasoning to parallel dual-modal reasoning, the core shift is replacing autoregressive token generation with simultaneous query-based extraction.
Expert Assessment
Problem choice: This is a real gap. The robotics community has been struggling with the trade-off between end-to-end learning (fast but brittle) and explicit planning (robust but slow). CoT-VLA was a promising middle ground, but the single-modality limitation is genuine—spatial reasoning and task planning require different representations. The problem sits at a natural inflection point where the field is moving from simple pick-and-place to multi-step manipulation.
Method maturity: The parallel query mechanism is clever, not brute force. However, the paper doesn’t deeply explore why learnable queries can replace autoregressive generation without losing reasoning quality—this feels like an empirical discovery more than a principled design. A simpler approach might be caching visual features and doing linguistic CoT only, but the authors don’t ablate this thoroughly.
Experimental integrity: Baselines are fair—they compare against recent CoT-VLA methods and standard VLA models. The numbers look solid across LIBERO and RoboCasa benchmarks, plus real-world validation. One red flag: the paper doesn’t report failure modes or show where dual CoT doesn’t help. The ablation studies are present but could be more granular—what happens if you remove only visual CoT vs. only linguistic CoT?
Writing quality: The method section is dense and could benefit from more intuitive explanations before diving into architecture details. The related work section is thorough but reads like a literature dump. If the authors rewrote Section 3.2 (Parallel CoT Mechanism) with clearer motivation for why parallel beats sequential, the whole paper would click better.
Verdict: weak accept — solid empirical contribution with a practical method, but lacks deeper theoretical insight into why the approach works and when it might fail.
Takeaways
Practitioners can steal the parallel query mechanism for any task where you need multiple types of reasoning simultaneously. The key transferable idea: if you can identify distinct reasoning modalities (spatial, temporal, causal, etc.), train separate query sets to extract them in parallel rather than forcing a single sequential chain. This applies beyond robotics—imagine video understanding where you need both object tracking (visual) and event sequencing (linguistic), or medical diagnosis where you need both image analysis and patient history reasoning. The latency reduction from parallel inference is real and matters for real-time systems.
论文: 2603.22280 作者: Zhide Zhong, Junfeng Li, Junjie He, Haodong Yan, Xin Gong, Guanyi Zhao, Yingjie Cai, Jiantao Gao, Xu Yan, Bingbing Liu 分类: cs.CV, cs.RO
缺口
视觉-语言-行动(VLA)模型已经能够处理简单的机器人任务,直接将视觉观察和语言指令映射到动作。
但在复杂的多步骤任务上它们遇到了瓶颈。
最近的工作加入了思维链(CoT)推理——让机器人”先思考再行动”——但这些CoT-VLA模型有两个致命缺陷:它们使用单模态CoT(要么视觉要么语言,不能同时),要么缺失低层空间细节,要么缺失高层规划逻辑;
而且它们自回归地解码推理步骤(一次一个token),造成延迟瓶颈和误差累积。
问题:复杂任务需要空间精度 + 逻辑规划
    |
    v
局限:单模态CoT无法同时捕获两者
    |                                    |
    v                                    v
仅视觉CoT                           仅语言CoT
(空间细节,                         (高层规划,
 无规划逻辑)                         无空间精度)
    |                                    |
    +------------------------------------+
                    |
                    v
            额外瓶颈:
    自回归解码 = 慢 + 误差累积
                    |
                    v
        解决方案:DualCoT-VLA
    (并行视觉 + 语言推理)
                    |
                    v
    证据:LIBERO、RoboCasa、真实机器人上达到SOTA
                    |
                    v
    结论:双模态并行推理 > 单模态顺序推理
增量
一句话: 这篇论文之前,机器人一次在一个模态中顺序推理;
之后,它们在视觉和语言两个模态中同时并行推理。
核心机制
DualCoT-VLA有三个主要组件:视觉CoT分支、语言CoT分支和并行推理机制。
视觉CoT分支通过可学习的查询token处理图像观察,提取空间关系和低层细节——比如”杯子在盘子左边5厘米”。
语言CoT分支接收语言指令并生成高层任务规划——比如”先抓住杯子,然后移动到水槽”。
DualCoT-VLA不是逐token生成这些推理链(很慢),而是使用两组可学习的查询token,在单次前向传播中输入模型。
视觉查询关注图像特征,语言查询关注指令嵌入,两者同时产生推理输出。
这些双重推理输出随后融合并输入动作解码器,预测机器人的下一个动作。
输入:图像 + 语言指令
    |
    +------------------+------------------+
    |                                     |
    v                                     v
视觉查询Token                      语言查询Token
    |                                     |
    v                                     v
[关注图像特征]                    [关注指令]
    |                                     |
    v                                     v
视觉CoT输出                       语言CoT输出
(空间推理)                        (任务规划)
    |                                     |
    +------------------+------------------+
                       |
                       v
                   融合层
                       |
                       v
                   动作解码器
                       |
                       v
                   机器人动作
把它想象成主厨和副厨并行工作。
主厨(语言CoT)读菜谱并规划顺序:“先切洋葱,然后炒,再加番茄”。
副厨(视觉CoT)盯着砧板和炉灶,追踪空间细节:“刀离洋葱2英寸,锅是中火”。
在传统CoT中,主厨必须停下来顺序询问副厨每个细节——“刀在哪?好,洋葱在哪?“——这很慢且容易出错。
在DualCoT-VLA中,两者同时工作,输出在行动时刻合并:主厨的计划说”现在切”,副厨的空间意识说”刀位置正确”,所以动作立即执行。
关键概念
- 机器人的思维链(CoT): 在语言模型中,CoT意味着在最终答案前生成中间推理步骤(“让我们一步步思考”)。
对机器人来说,它意味着在执行动作前生成关于任务的中间推理。
不是直接将”拿起杯子”映射到电机命令,机器人先推理:“杯子在桌上,我需要从上方接近,用3厘米握力抓取,然后抬起”。
这有助于需要规划的复杂任务,但传统CoT是顺序且慢的——每个推理步骤等待前一个完成。
- 可学习查询Token: 这些是特殊的输入token,不绑定到特定单词或像素——它们是模型训练来”询问”输入的学习参数。
想象你在博物馆有导游。
导游不是按顺序描述每幅画,而是你给他们一张具体问题清单:“哪些画有蓝色背景?哪些来自1800年代?“导游扫视房间并一次回答所有问题。
可学习查询token以同样方式工作:它们被训练从输入中提取特定类型的信息(空间关系、任务步骤),在单次传播中完成,而不是逐token生成。
- 并行vs自回归推理: 自回归意味着一次生成一个输出片段,每个片段依赖前面的——就像逐词写句子,在写”the brown”之前不能写”dog”。
并行推理意味着在一次前向传播中同时生成所有输出。
关键洞察:如果你知道要问什么问题(通过可学习查询),就不需要等待前面的答案来制定下一个问题。
这是顺序访谈(“告诉我步骤1…好,现在步骤2…”)和调查表(你一次回答所有问题)的区别。
框架转变
之前(CoT-VLA):                      之后(DualCoT-VLA):

输入                                    输入
  |                                        |
  v                                        v
单一CoT分支                            双CoT分支
  |                                    /           \
  v                                   v             v
步骤1推理                          视觉CoT       语言CoT
  |                                (空间)         (规划)
  v                                   |             |
步骤2推理                              +------+------+
  |                                          |
  v                                          v
步骤3推理                                 融合
  |                                          |
  v                                          v
动作                                      动作

(顺序,慢,                          (并行,快,
 单模态)                              双模态)
从顺序单模态推理到并行双模态推理,核心转变是用同时的基于查询的提取替代自回归token生成。
专家评审
选题眼光: 这是真缺口。
机器人社区一直在端到端学习(快但脆弱)和显式规划(鲁棒但慢)之间挣扎。
CoT-VLA是有前景的中间路线,但单模态局限是真实的——空间推理和任务规划需要不同的表示。
这个问题处于自然拐点,领域正从简单抓取放置转向多步骤操作。
方法成熟度: 并行查询机制是巧劲,不是蛮力。
但论文没有深入探讨为什么可学习查询能在不损失推理质量的情况下替代自回归生成——这感觉更像经验发现而非原则性设计。
更简单的方法可能是缓存视觉特征只做语言CoT,但作者没有充分消融这个。
实验诚意: 基线公平——他们与最近的CoT-VLA方法和标准VLA模型比较。
数字在LIBERO和RoboCasa基准上看起来扎实,加上真实世界验证。
一个警示:论文没有报告失败模式或展示双CoT不起作用的地方。
消融研究存在但可以更细粒度——如果只移除视觉CoT vs只移除语言CoT会怎样?
写作功力: 方法部分密集,在深入架构细节前可以有更多直观解释。
相关工作部分彻底但读起来像文献堆砌。
如果作者重写3.2节(并行CoT机制),更清楚地说明为什么并行胜过顺序,整篇论文会更通透。
判决: 弱接收 — 扎实的经验贡献和实用方法,但缺乏对方法为何有效以及何时可能失败的更深理论洞察。
要点总结
实践者可以为任何需要同时进行多种推理的任务偷走并行查询机制。
关键可迁移思想:如果你能识别不同的推理模态(空间、时间、因果等),训练独立的查询集来并行提取它们,而不是强制单一顺序链。
这超越机器人——想象视频理解需要物体跟踪(视觉)和事件排序(语言),或医疗诊断需要图像分析和病史推理。
并行推理带来的延迟降低是真实的,对实时系统很重要。