Paper: 2608.09902 Authors: Derin Gezgin, Jim O’Connor, Tanner Goodwin, Gary B. Parker Categories: cs.AI, cs.NE
The Gap
Almost every RL benchmark we love is secretly a benchmark about cheap sampling. The Arcade Learning Environment runs an emulator you can spin at hundreds of times real time and fork into a thousand parallel copies. ProcGen is fast and procedurally generated. VizDoom is fast. MineRL is slower but still an emulated-ish sandbox with a huge human demonstration corpus bolted on. SC2LE is the closest prior art for “real commercial game, real complexity,” but it too can be accelerated and it hands you a structured feature-layer observation plus a fairly informative score signal.
That shared property — you can buy performance with compute — quietly determines what counts as a “solved” benchmark. Sample efficiency becomes a nice-to-have rather than the binding constraint. The gap DSLE goes after is the regime where you cannot buy your way out: a real-time commercial action game, running at 1x, where every environment step is a real button press against a live process, where the reward is essentially a single bit delivered at the end of a one-to-three-minute episode, and where the observation is raw pixels with no privileged feature layers.
There’s a second, smaller gap: reproducibility of these setups. Prior Dark Souls agent work exists mostly as hobbyist repos and one-off scripts tied to a specific machine. Nobody had packaged the thing so two labs could compare numbers.
PROBLEM: our benchmarks are all cheap to sample;
         real-time games with terminal-only rewards are not
   |
   v
ASSUMPTION: a wall-clock-bound, sparse-reward, pixel-only arena
            exposes failure modes that Atari / ProcGen hide
   |
   v
METHOD: containerize Dark Souls: Remastered behind a Gymnasium
        shim -- 22 boss encounters, plus DSLE-5, a 5-boss subset
        chosen for orthogonal difficulty types
   |
   v
EVIDENCE: 5 methods on DSLE-5
          . expert system  -> 63% peak on tutorial boss
          . evolutionary   -> 43% peak on tutorial boss
          . PPO / DQN      -> <= 0.33% tutorial, 0% elsewhere
          . cost           -> tens of wall-clock hours per run
          . all 22 bosses w/ level-50 stats -> a few early wins
   |
   v
CONCLUSION: model-free pixel RL here is not slow, it is *flat*.
            Report survival time + damage dealt, because win rate
            is a constant zero and tells you nothing.
The Increment
One sentence: Before, “hard RL benchmark” meant an environment that needs a lot of samples; after DSLE, there’s a standardized environment where the samples themselves cost real seconds and current model-free methods produce a completely flat learning curve — plus the metrics to describe *how they fail instead of just noting that they do.
Core Mechanism
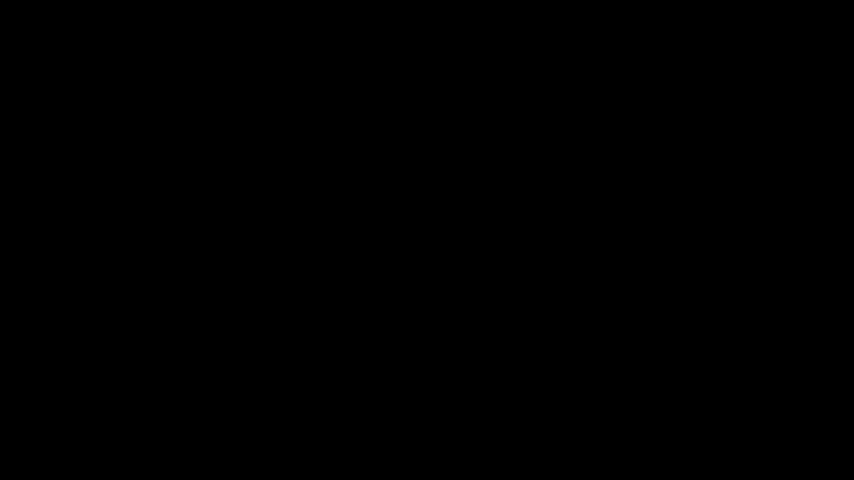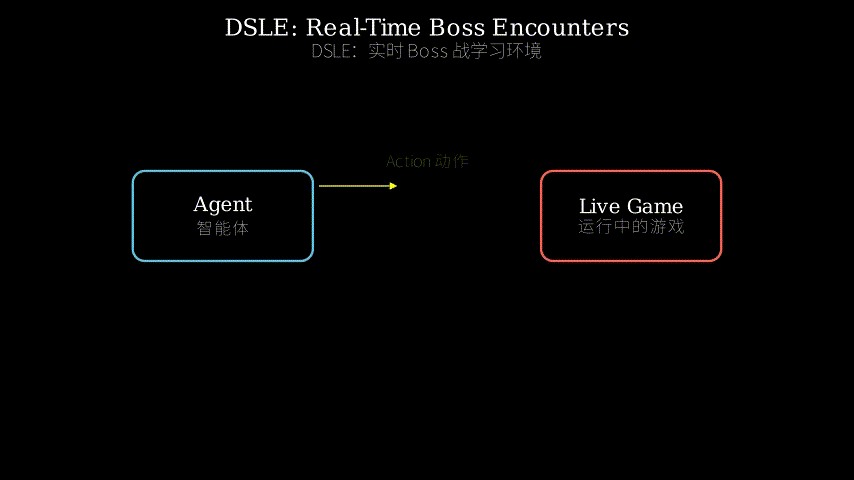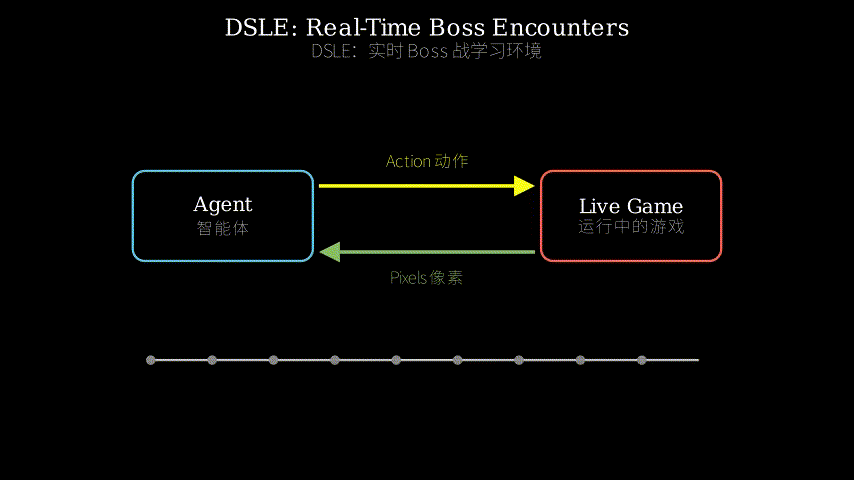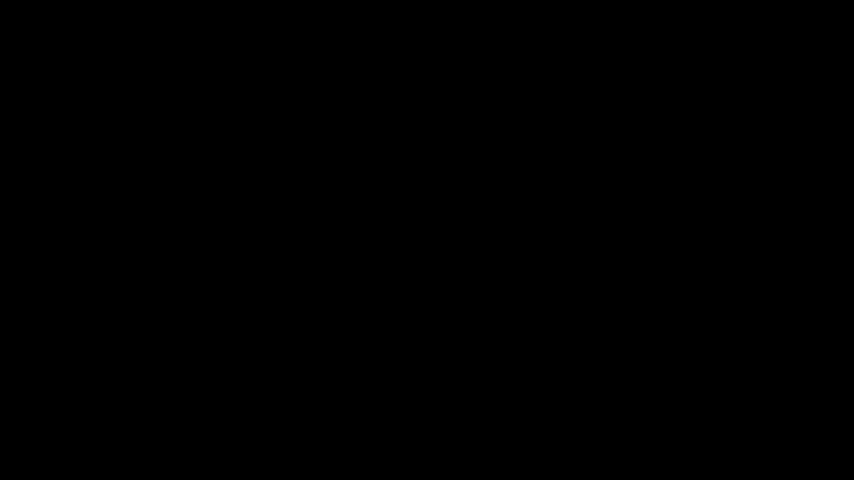
The engineering core is a container that holds the actual game process plus three bridges to it. An input injector turns discrete actions (attack, roll, block, lock-on, movement) into synthetic keyboard/gamepad events delivered to the running game. A frame grabber pulls the rendered screen as the observation, which is why the agent sees exactly what a human sees — health bars, stamina, boss animations — with no parsed structure. A state reader pulls the small set of scalars needed to compute rewards and terminations: player HP, boss HP, alive/dead flags. Around these sits a thin Gymnasium shim exposing reset / step / observation and action spaces, so anything written against Gym-style APIs plugs in unchanged.
The part that hurts is reset. In an emulator you restore a save state in microseconds. Here you have to bring a commercial game back to a known pre-boss configuration — respawn, walk-in, fog gate, boss re-instantiation — and that is real wall-clock time on every single episode. Combine that with episodes that last tens of seconds and a reward that arrives only at the end, and you get the paper’s central cost fact: tens of hours per training run, which is roughly a rounding error’s worth of experience by Atari standards.
The scientific core is the benchmark design. Rather than dumping 22 tasks and letting everyone cherry-pick, the authors curate DSLE-5 with one boss per failure *type: a plain melee duel, a cramped arena where space is the constraint, a fight where the environment itself kills you, a multi-target fight, and a fast final boss. Then, because every learned method scores zero, they switch the reporting axis to survival time and damage dealt — partial credit that separates “died in eight seconds to a two-enemy pincer” from “stood there for ninety seconds dealing almost no damage.” Those are opposite pathologies and win rate collapses them into the same number.
  +----------------------- container image ----------------------+
  |                                                              |
  |     [ Dark Souls: Remastered process ]   1x real time only   |
  |         ^                          |                         |
  |         | synthetic key / pad      | frames + memory         |
  |         |                          v                         |
  |   [ input injector ]      [ frame grabber ]  [ state reader ] |
  |         ^                          |               |         |
  +---------|--------------------------|---------------|---------+
            |                          v               v
         action                   pixel obs      player HP / boss HP
            ^                          |               / dead flag
            |                          +-------+-------+
            |                                  v
       [ agent ] <--- obs, reward, done --- [ Gymnasium shim ]
                                                  |
                                    reset: respawn + walk-in
                                    (costs real seconds, no rewind)

  reward:  ~0 for the whole episode,  +/- 1 at death or kill
  metrics: win rate  (useless: 0)
           survival time + damage dealt  (the informative pair)
Think of it as a boxing gym that only has one real professional fighter in it. The container is the gym building: standardized ring, standardized lighting, so a trainee’s performance in Cologne means the same thing as in Connecticut. The frame grabber is the trainee’s eyes — they get no telemetry from the opponent’s nervous system, just the same view a spectator has. The input injector is their gloves and feet. The state reader is the scoreboard visible ringside: your HP, their HP, and whether anyone’s on the canvas. The Gymnasium shim is the standard rulebook, so any trainee from any school can step in without renegotiating what a round means.
And reset is the part that makes this gym expensive: you cannot rewind a sparring session. After every knockout, someone has to mop the mat, revive the opponent, and walk the trainee back through the door. The terminal reward is a knockout-only scoring rule — jabs don’t count, only the final result. That’s why the coaches (the authors) add judges’ scorecards: when every trainee loses every bout, “lost” is not a measurement, but “lasted four rounds and landed thirty punches” versus “flattened in eight seconds” is. The DSLE-5 selection is picking five sparring partners who each punish a different weakness — one tests footwork, one tests fighting with your back to the ropes, one tests fighting on a slippery floor, one puts two opponents in the ring, one is simply faster than you.
Key Concepts
-
Wall-clock-bound environment: Most RL environments have a knob labeled “go faster.” Emulators run at 1000x; simulators fork into parallel workers; you trade dollars for experience. DSLE has no such knob — the game renders at its own pace and there is no rewind. Concretely: if an episode is 40 seconds of fight plus 20 seconds of reset, you get 60 episodes per hour per instance. PPO on Atari commonly consumes tens of millions of frames; here, tens of hours buys you something like a few thousand episodes. So “PPO didn’t learn” is genuinely ambiguous between “PPO can’t do this” and “PPO never got a real chance” — and that ambiguity *is the property the benchmark is designed to expose, because no amount of engineering removes it.
-
Terminal-only sparse reward: Imagine learning chess where the only feedback is “you won” or “you lost” at the end, with no piece values, no captures noted, nothing. Every move in a 60-move game gets equal credit for the outcome. That’s the credit-assignment problem at its worst. Dark Souls bosses are exactly this shape: a two-minute fight is hundreds of decisions and one bit of feedback. Note that DSLE *reads boss HP, so a shaped reward (damage dealt per step) is available — the paper’s default just doesn’t use it, which is both the honest hard version and, as I’ll argue below, a missed baseline.
-
Partial-credit metrics for zero-saturated benchmarks: When every method scores 0% you have a measurement problem, not just a performance problem — you can’t rank, can’t detect progress, can’t tell a promising agent from a broken one. The fix is to find intermediate quantities that correlate with progress. Here: how long did you stay alive, and how much damage did you land. Two agents with identical 0% win rates can be worlds apart on those axes, and the failure taxonomy the paper reports (8-second deaths vs. 90-second no-damage stalemates) only becomes visible once you look at them.
Framework Shift
Before (mainstream benchmark):        After (DSLE):

  [ emulator ]                          [ one game, one clock ]
     x1000 parallel copies                 x1  no parallel copies
     speed: 100x-1000x                     speed: 1x, no rewind
     reset: microseconds                   reset: real seconds

  reward every frame                    reward once, at the end
    +--+--+--+--+--+--+                  ...................+-
    (dense score signal)                 (one bit per episode)

  budget: 200M frames                   budget: hours of wall clock
          (a weekend of GPUs)                   (a weekend, period)

  metric: mean score                    metric: survival time
          (always informative)                  + damage dealt
                                                (because win rate = 0)

  conclusion shape:                     conclusion shape:
    "method A > method B"                 "everything is at zero;
                                           here is *how* each fails"
One sentence: from how many samples does your method need to what can you learn when samples cost seconds and feedback is one bit, the core shift is treating wall-clock cost and reward sparsity as the benchmark’s subject matter rather than as inconveniences to engineer away.
Expert Assessment
Problem choice: The gap is real, though narrower than the framing implies. The genuinely valuable observation is that our field’s difficulty axis has quietly been “sample count” for a decade, and that hides methods’ behavior in the regime where a robot, a lab instrument, or a production system gives you one trial per minute. Dark Souls is a legitimate, well-chosen stand-in for that regime, with the bonus that it comes with a natural difficulty curriculum and a community consensus on what’s hard. The counterargument: you can approximate the same regime by throttling ALE and truncating rewards, and you’d get reproducibility for free. What DSLE adds beyond that is genuine visual and mechanical complexity — plus a licensing headache, since anyone reproducing this needs their own legal copy of the game, which is exactly the kind of friction that killed several prior “real game” benchmarks.
Method maturity: The environment engineering is competent and unglamorous — screen capture, input injection, memory reads, containerization. Standard techniques, well assembled. The *baselines are where I’d push back hard. Reporting that PPO and DQN score 0.33% and 0% is an honest data point, but it’s a weak one, because the obvious ladder of intermediate steps was skipped. The environment already exposes boss HP, so dense damage-based reward shaping is one line away and is the single most likely thing to move the needle; running the flagship result without it makes the negative claim look stronger than the evidence supports. Same for the missing items: no behavior cloning from human play (Dark Souls has effectively unlimited demonstration video), no model-based agent (Dreamer-class methods exist precisely for expensive environments), no temporally abstracted action space, no frame-skip or macro-action study. As it stands, “model-free pixel RL at 1x with terminal rewards and a few thousand episodes fails” is close to a foregone conclusion — nobody in the field would have predicted otherwise. The interesting question is which of the missing rungs is the first to succeed, and the paper doesn’t ask it.
Experimental integrity: Refreshingly honest, and the metric choice is the paper’s best idea. Two caveats. First, statistical strength: at tens of wall-clock hours per run you can’t have many seeds, and a 0.33% win rate is likely a single lucky episode. That number should be reported with a count (“1 win in 300 episodes”), not a percentage that implies precision. Second, the all-22-bosses study at level-50 stats is a nice stress-relief control — it separates “the agent is weak” from “the character is weak” — but advantaged stats also change the fights’ dynamics, so it’s not a clean ablation of policy quality. The comparison between the hand-written expert system (63%) and the evolutionary baseline (43%) is the most informative contrast in the paper, and it’s the one that gets the least analysis.
Writing quality: The abstract is unusually candid, which I appreciate. Where I suspect corners were cut: the environment characterization. Anyone building on DSLE immediately needs numbers the abstract doesn’t hint at — mean step latency and its jitter, reset duration, determinism guarantees, whether the game is paused between steps or runs asynchronously (this determines whether the benchmark is even Markovian in practice), and what happens under frame drops. If I could rewrite one section, it’d be that one; a proper latency-and-determinism appendix is what turns this from a paper into infrastructure other people trust. Second choice: a “what would it take” roadmap section converting the failure taxonomy into concrete hypotheses.
Verdict: weak accept — a useful, well-scoped artifact with commendably honest negative results, held back by a baseline suite that stops one rung short of where the interesting findings begin.
Takeaways
Concrete things worth stealing:
-
The three-bridge pattern for wrapping any live application as an RL environment: frame grabber for observations, memory/state reader for reward and termination, synthetic input injector for actions, all inside a container with a Gym shim on top. This transfers directly to GUI agents, legacy desktop software, CAD tools, and any closed-source system with no API. The container is what makes results portable across labs; the state reader is what makes reward computation possible without instrumenting the app.
-
Design your metric for the regime you’re actually in. When your headline metric saturates at zero, it has stopped being a measurement. Find intermediate quantities on the causal path to success — here, survival time and damage dealt — and you regain the ability to rank, debug, and detect progress. This is generalizable advice for anyone benchmarking on tasks that are currently out of reach: 0% pass rate across five agents means you need a different y-axis, not a bigger training budget.
-
Failure taxonomy as a result. “8-second deaths in cramped multi-target arenas” and “90-second stalemates dealing no damage” are opposite pathologies pointing at different fixes (survival/positioning vs. commitment/aggression). Reporting failure *kinds rather than a single aggregate is a cheap way to make a negative result actionable.
-
Curate a small subset with orthogonal difficulty axes. DSLE-5 picks five tasks that each stress a different capability instead of shipping 22 and inviting cherry-picking. This is good benchmark hygiene generally: a small, defensible default suite plus a full set for later, with the selection rationale stated in terms of what each task tests.
-
Wall-clock as the budget unit. Reporting “tens of hours per run” instead of “N million steps” is the right currency for any expensive-environment work, and it changes which methods look attractive — model-based and imitation-bootstrapped approaches gain a lot of ground the moment steps stop being free.
What I wouldn’t take: the specific numbers. They tell you that untuned model-free pixel RL with terminal rewards fails here, which you already believed.
论文: 2608.09902 作者: Derin Gezgin, Jim O’Connor, Tanner Goodwin, Gary B. Parker 分类: cs.AI, cs.NE
缺口
我们熟悉的强化学习基准,几乎都暗地里是”采样便宜”的基准。
Atari(ALE)背后是模拟器,可以跑到实时速度的几百倍,还能开上千个并行副本。 ProcGen 快,而且是程序化生成的。 VizDoom 快。 MineRL 慢一些,但仍是可加速的沙盒,还外挂了庞大的人类演示数据集。 SC2LE 是”真实商业游戏 + 真实复杂度”最接近的先例,但它同样可以加速,而且直接给你结构化的特征层观测和信息量不小的分数信号。
这个共同属性——可以用算力买经验——悄悄定义了什么叫”解决了一个基准”。 样本效率变成了加分项,而不是硬约束。
DSLE 要打的缺口,正是那个你无法用钱买通的区间:一个真实商业动作游戏,只能以 1x 速度运行,每一个环境步都是对活着的进程按下一次真实按键;奖励基本上是一到三分钟的回合结束时才交付的一个比特;观测是原始像素,没有任何特权特征层。
还有一个次要缺口:可复现性。 此前的《黑暗之魂》Agent 工作大多以业余仓库和绑死某台机器的一次性脚本形式存在。 没人把它打包到”两个实验室能对比同一个数字”的程度。
问题: 现有基准都是采样廉价的;
      真实实时游戏 + 只有终局奖励, 不是
   |
   v
假设: 一个受挂钟时间约束、奖励稀疏、纯像素的战斗场,
      能暴露出 Atari / ProcGen 掩盖掉的失败模式
   |
   v
方法: 把《黑暗之魂: 重制版》容器化, 套上 Gymnasium 接口
      -- 22 场 Boss 战, 外加 DSLE-5:
         按"难点类型互不重叠"挑出的 5 个 Boss 子集
   |
   v
证据: 5 种方法在 DSLE-5 上
      . 专家系统    -> 教程 Boss 峰值胜率 63%
      . 进化算法    -> 教程 Boss 峰值胜率 43%
      . PPO / DQN   -> 教程 <= 0.33%, 其余 0%
      . 代价        -> 每次训练数十小时挂钟时间
      . 全 22 Boss + 50 级属性 -> 只多赢几个前期 Boss
   |
   v
结论: 无模型的像素到动作 RL 在这里不是"慢", 是"平".
      改用存活时间 + 造成伤害来报告,
      因为胜率恒为零, 什么都说明不了.
增量
一句话:以前”困难 RL 基准”意味着需要海量样本的环境;DSLE 之后,我们有了一个标准化环境,其中样本本身要花掉真实的秒数,而当前的无模型方法给出的是一条完全平坦的学习曲线——外加一套能描述它们”怎么失败”而不只是”失败了”的指标。
核心机制
工程主体是一个容器,里面装着真正的游戏进程,加上三条通往它的桥。
输入注入器把离散动作(攻击、翻滚、格挡、锁定、移动)变成合成的键鼠/手柄事件,发给运行中的游戏。
画面抓取器把渲染好的屏幕当作观测,所以 Agent 看到的和人类完全一样——血条、耐力、Boss 动作——没有任何被解析过的结构。
状态读取器只取计算奖励和终止所需的少量标量:玩家 HP、Boss HP、生死标志。
外面套一层薄薄的 Gymnasium 适配层,暴露 reset / step 和观测、动作空间,任何按 Gym 风格写的代码都能直接插上。
真正疼的地方是 reset。
在模拟器里恢复存档状态只需微秒。
这里你得把一个商业游戏搬回已知的 Boss 战前状态——重生、走位、穿雾门、Boss 重新实例化——而这在每一个回合上都是真实的挂钟时间。
再叠加上”回合几十秒”和”奖励只在结尾出现”,就得到了论文的核心代价事实:每次训练数十小时,而按 Atari 的标准,这点经验量约等于四舍五入误差。
科学主体是基准设计。 作者没有直接扔出 22 个任务让大家各自挑好看的,而是精选了 DSLE-5:每种失败类型配一个 Boss——纯近战对决、以空间为约束的狭窄场地、环境本身会杀你的战斗、多目标战斗、以及一个速度极快的最终 Boss。 然后,因为所有学习方法都是零分,他们把报告轴换成了存活时间和造成伤害——这是能把”被两个敌人夹击 8 秒内暴毙”和”站着打 90 秒几乎没造成伤害”区分开的部分分。 这是两种相反的病理,而胜率会把它们压成同一个数字。
  +--------------------- 容器镜像 -----------------------+
  |                                                      |
  |    [ 黑暗之魂: 重制版 进程 ]     只能 1x 实时         |
  |        ^                    |                        |
  |        | 合成按键 / 手柄     | 画面 + 内存             |
  |        |                    v                        |
  |  [ 输入注入器 ]      [ 画面抓取 ]   [ 状态读取 ]       |
  |        ^                    |             |          |
  +--------|--------------------|-------------|----------+
           |                    v             v
        动作               像素观测      玩家HP / BossHP
           ^                    |          / 死亡标志
           |                    +-----+-----+
           |                          v
      [ Agent ] <-- 观测,奖励,done -- [ Gymnasium 适配层 ]
                                            |
                              reset: 重生 + 走回场地
                              (花真实的秒数, 无法回退)

  奖励:  整局约为 0,  死亡或击杀时 +/- 1
  指标:  胜率        (无用: 恒为 0)
         存活时间 + 造成伤害  (真正有信息量的一对)
可以把它想成一间只有一位真人职业拳手的拳馆。
容器是拳馆建筑本身:标准擂台、标准灯光,所以学员在科隆的表现和在康涅狄格的表现含义相同。 画面抓取器是学员的眼睛——他们拿不到对手神经系统的遥测数据,只有和看台观众一样的视野。 输入注入器是他们的拳套和双脚。 状态读取器是台边可见的记分牌:你的血、他的血、有没有人倒在地上。 Gymnasium 适配层是统一规则手册,任何流派的学员都能上台,不必重新协商”一个回合”是什么意思。
而 reset 就是让这间拳馆昂贵的那部分:对练无法回放。
每次被击倒之后,都得有人擦干地垫、把对手复活、把学员从门口重新领进来。
终局奖励是”只算 KO”的计分规则——刺拳不算分,只有最终结果算。
这就是教练(作者)为什么要加裁判评分表:当所有学员每场都输,“输了”不是一次测量,但”撑了四回合、命中三十拳”和”8 秒被放倒”就是。
DSLE-5 的选法,就是挑五个各自惩罚不同弱点的对练伙伴——一个考步法,一个考被逼到绳边怎么打,一个考在滑地板上打,一个直接放两个人上台,一个纯粹就是比你快。
关键概念
-
受挂钟时间约束的环境:大多数 RL 环境都有一个写着”加速”的旋钮。 模拟器能跑 1000x;仿真器能开并行 worker;你用钱换经验。 DSLE 没有这个旋钮——游戏按自己的节奏渲染,而且没有回退。 具体算一下:如果一局是 40 秒战斗加 20 秒重置,那么单实例每小时 60 局。 Atari 上的 PPO 动辄消耗几千万帧;这里,数十小时买到的大概是几千局。 所以”PPO 没学会”在”PPO 做不到”和”PPO 根本没得到公平机会”之间是真的有歧义——而这个歧义本身就是这个基准要暴露的属性,因为再多的工程优化也消不掉它。
-
只有终局的稀疏奖励:想象学下棋,唯一的反馈是结束时的”你赢了”或”你输了”,没有子力价值,不告诉你吃了什么子,什么都没有。 一局 60 步棋里,每一步对结果分到的功劳都一样。 这是信用分配问题最糟糕的形态。 《黑暗之魂》的 Boss 战正是这个形状:两分钟战斗是几百个决策,反馈只有一个比特。 注意 DSLE 是能读到 Boss HP 的,所以塑形奖励(每步造成的伤害)本来就在手边——论文的默认设定只是没用它,这既是诚实的”最难版本”,也是(下面会说)一个被漏掉的基线。
-
零饱和基准的部分分指标:当所有方法都是 0% 时,你面对的是一个测量问题,不只是性能问题——没法排序、没法察觉进步、没法区分有潜力的 Agent 和坏掉的 Agent。 解法是找到与成功相关的中间量。 这里是:你活了多久,你打出了多少伤害。 两个胜率都是 0% 的 Agent,在这两条轴上可能相差十万八千里;而论文报告的失败分类学(8 秒暴毙 vs 90 秒零伤害僵持)只有在看这两条轴时才会显形。
框架转变
之前(主流基准):                    之后(DSLE):

  [ 模拟器 ]                            [ 一个游戏, 一个时钟 ]
     x1000 并行副本                        x1  无并行副本
     速度: 100x-1000x                      速度: 1x, 不能回退
     重置: 微秒级                          重置: 真实的秒

  每帧都有奖励                          只在结尾给一次奖励
    +--+--+--+--+--+--+                  ...................+-
    (密集分数信号)                       (每局一个比特)

  预算: 2 亿帧                          预算: 数十小时挂钟时间
        (一个周末的 GPU)                       (一个周末, 就这样)

  指标: 平均分                          指标: 存活时间
        (永远有信息量)                         + 造成伤害
                                               (因为胜率 = 0)

  结论形状:                             结论形状:
    "方法 A > 方法 B"                     "全部为零;
                                           以下是各自怎么失败的"
一句话:从你的方法需要多少样本,到当样本按秒计价、反馈只有一个比特时你还能学到什么,核心转变是把挂钟成本和奖励稀疏性当成基准的研究对象,而不是要用工程手段绕开的麻烦。
专家评审
选题眼光:缺口是真的,但比论文的框架暗示的窄一些。 真正有价值的观察是:我们这个领域的”难度轴”十年来悄悄地就是”样本数量”,而这掩盖了方法在”每分钟只能试一次”这种区间里的行为——机器人、实验仪器、生产系统都在这个区间。 《黑暗之魂》作为这个区间的替身是合理且挑得不错的选择,附带好处是它自带天然的难度课程,社区对”什么算难”也有共识。 反驳意见:你把 ALE 限速再截断奖励,也能近似出同一个区间,而且顺带免费获得可复现性。 DSLE 超出这一点的部分是真实的视觉和机制复杂度——以及一个许可证麻烦:任何想复现的人都得自备正版游戏,而这类摩擦恰好是杀死过好几个”真实游戏基准”的东西。
方法成熟度:环境工程扎实但不炫技——屏幕抓取、输入注入、内存读取、容器化。 标准技术,组装得不错。 真正要被推一把的是基线。 报告 PPO 和 DQN 拿到 0.33% 和 0% 是诚实的数据点,但它是一个弱数据点,因为一整排显而易见的中间台阶被跳过了。 环境本来就暴露了 Boss HP,所以基于伤害的密集奖励塑形只差一行代码,而且它是最可能让指针动起来的那一项;旗舰结果不带它跑,会让这个负面结论看起来比证据支持的更强。 其他缺失的同理:没有从人类游玩做行为克隆(《黑暗之魂》的演示视频事实上无限多),没有基于模型的 Agent(Dreamer 一类方法正是为昂贵环境而生),没有时间抽象的动作空间,没有跳帧或宏动作的研究。 就目前而言,“1x 速度、终局奖励、几千局的无模型像素 RL 会失败”几乎是既定结论——领域里没人会预测别的。 有意思的问题是:那排缺失的台阶里,哪一级先成功?而论文没问。
实验诚意:难得的坦率,而指标选择是全文最好的想法。 两点保留。 第一,统计强度:每次训练数十小时,你不可能跑很多 seed,而 0.33% 的胜率很可能就是一局侥幸。 这个数字应该以计数形式报告(“300 局中赢 1 局”),而不是一个暗示精度的百分比。 第二,全 22 Boss 的 50 级属性研究是个不错的减压对照——它把”Agent 弱”和”角色弱”分开了——但优势属性也改变了战斗的动力学,所以它不是策略质量的干净消融。 手写专家系统(63%)和进化基线(43%)之间的对比是全文最有信息量的一组,偏偏也是分析最少的一组。
写作功力:摘要异常诚实,这一点我给分。 我怀疑偷懒的地方是环境刻画。 任何想在 DSLE 上做东西的人立刻需要摘要里毫无线索的数字——每步延迟的均值和抖动、重置耗时、确定性保证、步之间游戏是暂停还是异步运行(这决定了这个基准在实践中到底是不是马尔可夫的)、以及掉帧时会发生什么。 如果只能重写一节,就是这一节;一份像样的延迟与确定性附录,才能把它从”一篇论文”变成”别人敢依赖的基础设施”。 第二选择:加一节”要怎样才能做到”,把失败分类学转换成具体假设。
判决:弱接收 —— 一个有用、范围明确的工件,负面结果诚实可嘉,但基线组合在”有趣发现开始的地方”前停了一级台阶。
要点总结
值得”偷”走的具体东西:
-
把任意活体应用包成 RL 环境的三桥模式:画面抓取器出观测,内存/状态读取器出奖励和终止,合成输入注入器出动作,全部塞进一个容器,上面套 Gym 适配层。 这可以直接迁移到 GUI Agent、遗留桌面软件、CAD 工具,以及任何没有 API 的闭源系统。 容器是让结果能跨实验室搬运的东西;状态读取器是让你不用改造应用就能算奖励的东西。
-
按你真正所处的区间来设计指标。 当你的头号指标饱和在零,它就不再是一次测量了。 去找因果路径上的中间量——这里是存活时间和造成伤害——你就重新获得了排序、调试和察觉进步的能力。 这条建议对任何在”当前做不到的任务”上做基准的人都通用:五个 Agent 全是 0% 通过率,意味着你需要换一根纵轴,而不是换一个更大的训练预算。
-
把失败分类学当成结果本身。 “狭窄多目标场地里 8 秒暴毙”和”90 秒零伤害僵持”是两种相反的病理,指向不同的修法(生存/走位 vs 出手/进攻性)。 报告失败的种类而不是一个聚合数字,是让负面结果变得可行动的廉价办法。
-
精选一个难点轴互不重叠的小子集。 DSLE-5 挑了五个各压不同能力的任务,而不是丢出 22 个然后邀请大家挑好看的。 这是普适的基准卫生学:一个小而站得住的默认套件,加一个留待以后的全集,并且用”每个任务测什么”来陈述挑选理由。
-
以挂钟时间为预算单位。 在任何昂贵环境的工作里,报告”每次运行数十小时”而不是”N 百万步”才是正确的货币,而且它会改变哪些方法看起来有吸引力——一旦步数不再免费,基于模型的方法和用模仿学习引导的方法立刻大幅占优。
我不会拿走的:具体数字。 它们告诉你的是”没调过的无模型像素 RL 在终局奖励下会失败”,而这你本来就相信。