Paper: 2608.12308 Authors: Yan Deng, Fei Xu Categories: cs.AI, cs.CV
The Gap
Aerial vision-language navigation is the ugly sibling of indoor VLN. Indoor agents move on a discretized navigation graph with a handful of viewpoints; a drone lives in continuous 3D, sees mostly rooftops and treelines, and has to decide altitude as well as heading. The OpenFly benchmark made this tractable enough to benchmark, and the obvious move was to port the Vision-Language-Action (VLA) recipe over: encode the image, encode the instruction, decode an action. Recent diffusion-based VLAs like Dream-VLA do this with a generative action head instead of a classifier, which handles multimodal action distributions better.
Three specific things break when you do that port naively, and this paper names all three:
First, memory. Most VLA policies condition on the current frame (or a tiny stack of frames). But an instruction like “fly past the second intersection, then turn toward the red warehouse” is unanswerable from one frame — you cannot know it is the *second intersection without history. Naive attempts to add history in a training pipeline that packs whole trajectories into a sequence leak future frames into the current decision, so validation numbers look good and deployment does not.
Second, horizon. Single-step action prediction gives the policy no supervision about where the trajectory is going. Robot manipulation solved this years ago with action chunking (ACT, Diffusion Policy) — predict K steps, execute all K — but executing a whole chunk open-loop is dangerous when a drone is closing on an obstacle at speed.
Third, termination. Most VLN agents fold “stop” into the action vocabulary as a token and hope the policy emits it at the right moment. Under partial observability the goal often looks similar for several consecutive steps, so the stop token is the single most fragile symbol in the vocabulary. A miss costs you the episode even if the whole trajectory was correct — SR and SPL both go to zero.
   PROBLEM
   aerial VLN: partial obs, long instructions, continuous 3D
        |
        +--> no usable history .... temporal reasoning fails
        +--> 1-step horizon ...... no trajectory-level signal
        +--> implicit stop token . termination unreliable
        |
        v
   ASSUMPTION
   these three are separable failures, fixable in one backbone
   ( Dream-VLA diffusion policy ), not requiring a new architecture
        |
        v
   METHOD  ( DreamFly )
   [causal memory] + [receding-horizon diffusion] + [LiteStop]
     past-only        plan K, execute 1           logits at
     fusion           replan every step           all-mask state
        |
        v
   EVIDENCE
   OpenFly test-seen  : 32.04 SR / 28.22 SPL
   OpenFly test-unseen: 29.46 SR / 23.54 SPL
   lowest NE among compared methods
        |
        v
   CONCLUSION
   history + future-action structure + explicit stop
   are complementary, not redundant
The Increment
One sentence: Before this paper, aerial VLA agents were amnesiac, myopic, and bad at knowing they had arrived; after it, the same backbone gets a leakage-free memory, a rehearsal-then-commit action loop, and a stop decision that no longer competes with steering for the same output slot.
Core Mechanism
Start with the backbone. Dream-VLA is a diffusion (more precisely, mask-and-denoise) policy: instead of classifying the next action, it starts from a fully masked action sequence and iteratively fills it in, conditioned on vision and language. DreamFly keeps this intact and bolts three modules around it.
Causally aligned historical memory. At decision step *t, the model builds a representation that fuses the current observation with encoded observations from steps 1..t-1 only. The word doing the work is “only” — the constraint is a masking discipline, enforced so that no observation at index >= t can influence the step-t representation. This is exactly the causal-mask idea from autoregressive language modeling, transplanted to an observation stream. It sounds trivial, and it is trivial to state; it is easy to violate in practice because trajectory-level batching, bidirectional attention over a frame stack, and normalization statistics computed over the whole episode all quietly import the future.
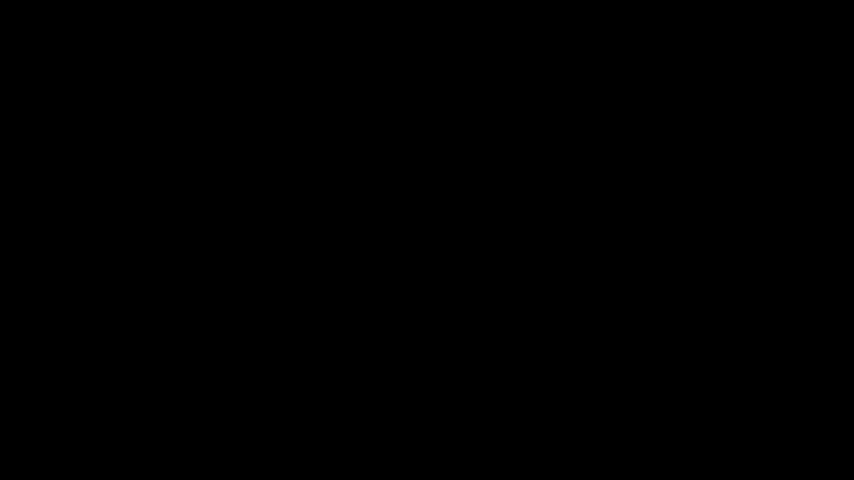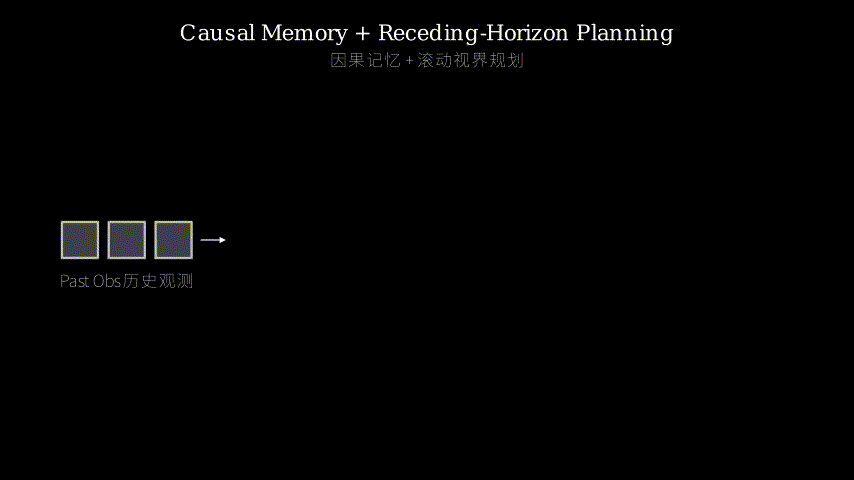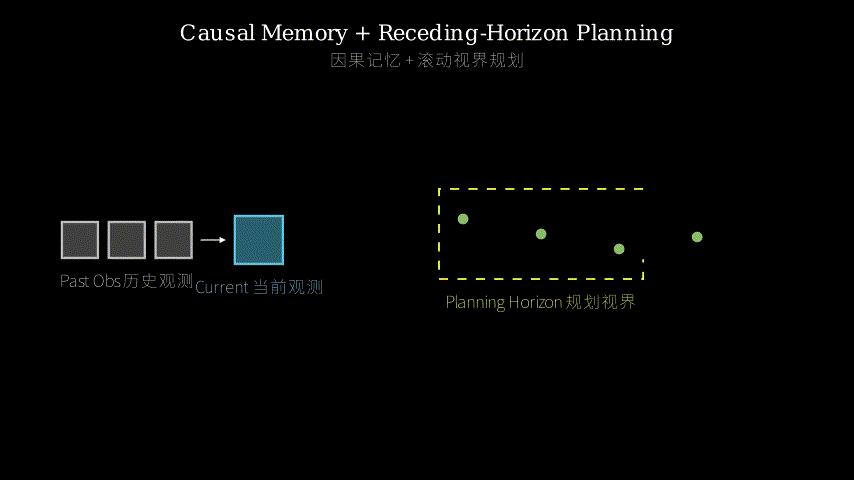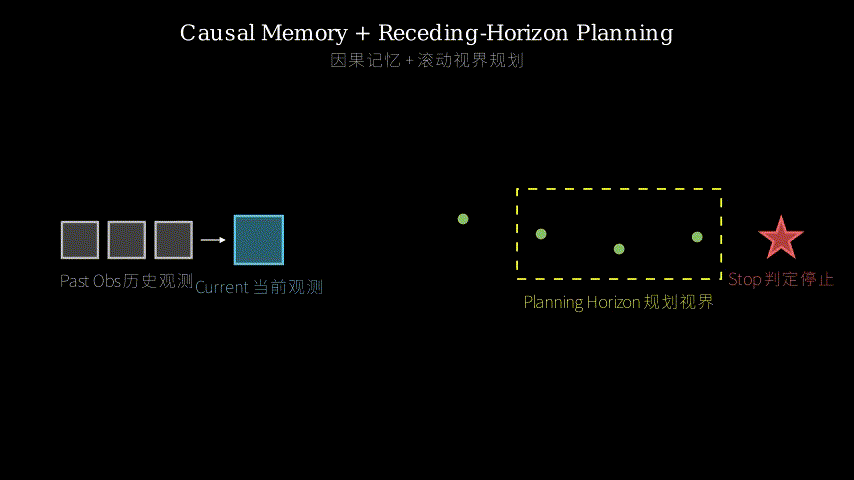
Receding-horizon diffusion planning. The action head predicts a chunk of *K future actions. Then the agent throws away K-1 of them, executes only the first, takes a new observation, and re-plans from scratch. The discarded actions are not wasted: during training they are auxiliary supervision targets that force the latent to encode where the trajectory is headed, and at inference the joint prediction acts as a consistency constraint on the first action. This is model-predictive control’s receding horizon, applied to a learned generative planner. The tradeoff is explicit: you pay K-step compute per single executed step, and you buy back closed-loop visual feedback that pure action chunking gives up.
LiteStop. Instead of a stop token inside the action vocabulary, LiteStop reads the action logits at the *initial all-mask state — the very first forward pass, before any denoising has happened — and maps them to a stop probability. The intuition: at the all-mask state the model’s output is its prior belief about “what kind of action situation is this”, ungarbled by partially-committed action content. If the situation is “nothing left to do”, that shows up in the shape of the prior. Cost is one linear head; no extra forward pass.
   instruction ----------------------+
                                     |
   obs_1 .. obs_(t-1)                |
        |                            |
        v                            |
   [ encoder ] --+                    |
                 v                    v
        [ CAUSAL FUSION ]  <----- obs_t
        strictly past-only            |
                 |                    |
                 v                    v
        +====================================+
        |        Dream-VLA backbone          |
        |  ( masked diffusion action head )  |
        +====================================+
             |                         |
             | all-mask state          | denoise x N
             v                         v
        [ LiteStop ]            a_t, a_t+1, ... a_t+K-1
        p(stop) from logits           |
             |                        +--- a_t+1..a_t+K-1
             |                        |    ( training target
             |                        |      only, DISCARDED
             |                        |      at inference )
             |                        |
             |                        v
             +---- stop? ---- no --> execute a_t
                     |                        |
                    yes                       v
                     |                  new obs_(t+1)
                     v                        |
                  TERMINATE                   +--> loop back
The metaphor: a ship’s navigator with a logbook. Picture a pre-GPS navigator on a bridge, working from a written sailing order (“past the second headland, then bear toward the lighthouse”).
The logbook is the causal memory. It contains every bearing and landmark already passed — and nothing else. Nobody hands the navigator tomorrow’s page. That absence is the entire contribution of the memory module: a logbook that contained future entries would let you “count the second headland” without ever having sailed past the first, which is precisely the leakage that makes benchmark numbers lie.
The penciled course on the chart is the K-step plan. The navigator does not draw one tick mark; he sketches the next several legs, because you cannot judge whether this turn is right without seeing where it leads. But then he sails only to the first buoy, walks back to the chart, takes a fresh sighting, and redraws the whole course. The erased pencil marks did their job — they disciplined the first leg — and they are not commitments. That is plan-*K, execute-one.
The lookout in the crow’s nest is LiteStop. His only job is to shout “we’re here, drop anchor.” Crucially he is not also steering. In the old design the helmsman had to both steer and yell “stop”, and the yell competed with steering commands for his one mouth. And the moment LiteStop looks — the all-mask state — is the lookout’s first glance at the horizon *before anyone starts drawing the new course. The unprejudiced first glance is the most reliable read on “have we arrived”.
Key Concepts
-
Causal alignment (no future leakage): Imagine training a student to predict tomorrow’s weather, but the practice worksheets accidentally include tomorrow’s answer in the margin. The student scores brilliantly on practice and uselessly in the field. In sequence models this happens through attention: if the step-*t representation can attend to frame t+3, the model learns shortcuts that do not exist at deployment. The fix is a mask that makes it structurally impossible, not a promise to be careful. In a navigation trajectory the leak is especially seductive because a future frame often shows the goal, so a leaky model can look like it has excellent “long-horizon reasoning” when it is just peeking.
-
Receding horizon: You plan a long trip in detail but only book tonight’s hotel, because you will know more tomorrow. Formally: optimize over *K steps, commit to step 1, discard the rest, repeat. Industrial process control has run this way for decades (it is what MPC means). The insight worth transplanting is that planning far and committing short are not in conflict — the long plan improves the short commitment by giving it context, without inheriting the long plan’s accumulated uncertainty.
-
All-mask state as a readout point: In a masked-diffusion action head, generation begins with every action slot blank. The model’s output at that instant is not an action — it is a summary of “given what I see and what I was told, what family of behaviors is appropriate here?” That is an unusually clean place to ask a yes/no question about the situation, because nothing has been committed yet that could bias the answer. The reusable trick: a generative model’s *initial state often carries the cleanest situational signal, and you can hang cheap auxiliary classifiers there.
Framework Shift
Before (mainstream aerial VLA):        After (DreamFly):

  obs_t                                 obs_1..obs_(t-1)   obs_t
    |                                        \             /
    v                                         \           /
 [ VLA policy ]                             [ causal fusion ]
    |                                              |
    v                                              v
 a_t  ( includes "STOP"                      [ diffusion head ]
       as one token among                     /             \
       many, competing )                     /               \
    |                                [ LiteStop ]      a_t..a_t+K-1
    v                                p(stop) at            |
 execute a_t                         all-mask              | keep a_t
    |                                     |                | drop rest
    +--> loop ( no memory,                +---- gate ------+
               no lookahead,                        |
               fragile stop )                       v
                                                execute, re-plan
                                          ( memory grows, horizon
                                            rehearsed, stop separate )
From a reactive single-step classifier to a closed-loop planner with a written past and a rehearsed future, the core shift is that time is represented explicitly in three directions at once — backward as leakage-free memory, forward as discarded rehearsal, and terminally as its own decision.
Expert Assessment
Problem choice: The gap is real, though it is a maintenance gap rather than a frontier gap. Aerial VLN genuinely is under-served relative to indoor VLN, and all three named failure modes are things practitioners complain about. The termination point in particular is under-discussed: in VLN, SR and SPL are both gated on stopping correctly, so a systematically weak stop decision silently caps every other improvement you make. That is a good observation. What keeps this from being a frontier contribution is that none of the three problems were *unknown — they were known and unaddressed in this specific setting. The paper sits in the consolidation phase of the aerial-VLA trajectory: someone was going to do this within a year.
Method maturity: Clever assembly, not a new idea. Causal masking is inherited from autoregressive LMs. Plan-K-execute-one is textbook MPC and has been standard in manipulation since Diffusion Policy and RT-style chunking; applying it to aerial VLN is a port, not an invention. LiteStop is the only piece with genuine novelty, and it is a small, tasteful one — reading the all-mask logits is cheaper and cleaner than adding a separate stop network or a dedicated forward pass. Simpler alternatives the paper should have to beat: a plain frame-stack with a causal mask (does the fancier memory actually help over concatenating the last N frames?), and a vanilla auxiliary stop head on the pooled visual-language embedding (does reading from the all-mask state specifically matter, or would any stop head do?). If the ablation does not isolate those two, the contribution shrinks considerably. Also unaddressed in the abstract: the compute cost. Plan-K-execute-one means roughly *K times the planning compute per executed step, on a platform where latency is a physical safety constraint. For a drone this is not a footnote.
Experimental integrity: The headline numbers are honest-looking, which is to say low. 32.04% seen / 29.46% unseen SR on OpenFly is a hard benchmark being hard. The seen-to-unseen gap is small (~2.6 SR points), which is either encouraging generalization or a sign that the model has not fit the seen environments especially well either. Note that the SPL gap is larger (28.22 vs 23.54), meaning unseen successes are reached less efficiently — consistent with more wandering before the stop fires. Two things I would want before believing the story: per-component ablations with the causal mask *removed (this is the one number that would confirm the leakage claim is load-bearing rather than rhetorical), and a sweep over K, since if performance is flat in K the receding-horizon framing is decorative. “Outperforming all compared methods on both metrics” is a claim whose weight depends entirely on which methods were compared and whether baselines got the same backbone, the same training budget, and the same input history. Reimplementing baselines without history and then reporting that history helps is a familiar way to win.
Writing quality: The abstract is well-organized and unusually clear about what each module does — three problems, three modules, clean mapping. The corner cut is almost certainly justification of *why the specific design choices beat their cheap alternatives; abstracts that read this tidily usually have ablations that are thinner than the narrative. The section that would most elevate the paper is the LiteStop analysis: if the authors can show why the all-mask logits carry stop-relevant information — a probe, a visualization of logit geometry near goals, a precision/recall curve against an implicit stop token — that turns the paper’s one novel idea from a trick into a finding worth citing. Right now it reads as “we tried this and it worked.”
Verdict: weak accept — a competent, well-motivated consolidation of three known techniques into an under-served domain, carried by one genuinely nice idea (LiteStop) whose supporting analysis is probably thinner than it needs to be.
Takeaways
Things worth stealing, in rough order of transferability:
-
Read cheap auxiliary decisions off a generative model’s initial state. If your model starts from an all-mask or pure-noise state, that first forward pass is a free, uncontaminated situational summary. Hang classifiers on it — termination, safety gating, mode selection, abstention. Costs one linear layer and no extra pass. This generalizes far beyond navigation.
-
Decouple “when to stop” from “what to do”. Any policy that packs termination into the action vocabulary is making its most consequential decision compete with its most frequent one. This applies to agentic LLM loops just as much as drones: “call a tool” vs “I’m done” as sibling tokens is a known failure surface. Give termination its own head and its own threshold you can tune on a precision/recall curve.
-
Predict long, commit short. Use the far-future part of a prediction as *supervision and throw it away at inference. You get trajectory-level gradient signal without inheriting open-loop drift. Cheap to try on any sequence policy that currently predicts one step.
-
Treat causal masking as a structural invariant, not a discipline. If your training pipeline batches whole episodes, assume you have a leak until you have proven otherwise, and prove it by construction (masking) rather than by inspection. Then report the ablation with the mask off — that number is the honest measure of how much your “temporal reasoning” was actually peeking.
What is not here: a new architecture, a new benchmark, or a scaling insight. If you are looking for a conceptual advance in embodied navigation, skip it. If you are shipping a VLA policy and need three concrete engineering fixes with a benchmark showing they compose, it is a useful 20 minutes.
论文: 2608.12308 作者: Yan Deng, Fei Xu 分类: cs.AI, cs.CV
缺口
空中视觉语言导航(aerial VLN)一直是室内 VLN 的”穷亲戚”。
室内智能体在离散化的导航图上跳点,可选视角就那么几个;无人机则活在连续三维空间里,视野中大多是屋顶和树线,还得同时决定航向和高度。
OpenFly 基准把这件事变得可量化之后,最自然的做法就是把 VLA(视觉-语言-动作)那套配方搬过来:编码图像、编码指令、解码动作。
最近像 Dream-VLA 这类扩散式 VLA 又把分类式动作头换成了生成式动作头,能更好地处理多峰动作分布。
但这种”直接搬”会在三个地方断掉,本文把三个都点了名。
第一是记忆。 大多数 VLA 策略只以当前帧(或很小的帧栈)为条件。
可是”飞过第二个路口,然后朝红色仓库转向”这种指令,单帧根本无法回答——你没有历史,就不知道眼前这个是不是”第二个”。
而如果在把整条轨迹打包成序列的训练管线里草率地加历史,未来帧就会泄漏进当前决策,结果是验证集分数很漂亮、真机部署很难看。
第二是视野长度。 单步动作预测不给策略任何”轨迹要去哪”的监督信号。
机器人操作领域几年前就用动作分块(action chunking,如 ACT、Diffusion Policy)解决了这个问题——预测 K 步、执行 K 步。
但无人机高速逼近障碍物时,开环执行一整块动作是危险的。
第三是终止判断。 大多数 VLN 智能体把”停止”折叠成动作词表里的一个 token,然后指望策略在恰当时刻吐出它。
在部分可观测条件下,目标区域连续好几步看起来都差不多,于是这个 stop token 成了整个词表里最脆弱的符号。
漏了一次,整条 episode 就废了——就算轨迹全对,SR 和 SPL 也一起归零。
   问题
   空中 VLN : 部分可观测 + 长指令 + 连续三维
        |
        +--> 没有可用历史 ...... 时序推理失效
        +--> 单步视野 .......... 无轨迹级信号
        +--> 隐式 stop token ... 终止不可靠
        |
        v
   假设
   这三者是可分离的故障, 可以在同一个骨干
   ( Dream-VLA 扩散策略 ) 上分别修补,
   不需要新架构
        |
        v
   方法  ( DreamFly )
   [因果记忆] + [滚动视野扩散规划] + [LiteStop]
     只看过去     规划K步只执行1步     全掩码态
     的融合       每步重规划          读 logits
        |
        v
   证据
   OpenFly test-seen  : 32.04 SR / 28.22 SPL
   OpenFly test-unseen: 29.46 SR / 23.54 SPL
   对比方法中导航误差最低
        |
        v
   结论
   历史上下文 + 未来动作结构 + 显式终止
   三者互补, 不冗余
增量
一句话:这篇论文之前,空中 VLA 智能体是”失忆 + 近视 + 不知道自己到了没有”;之后,同一个骨干拿到了无泄漏的记忆、“先预演再落子”的动作循环,以及一个不再和转向指令抢同一个输出口的停止决策。
核心机制
先说骨干。Dream-VLA 是扩散式(更准确说是掩码-去噪式)策略:它不直接分类下一个动作,而是从一串全掩码的动作序列出发,在视觉和语言条件下迭代填充。
DreamFly 完整保留这个骨干,在它周围挂了三个模块。
因果对齐的历史记忆。 在决策步 t,模型把当前观测与 *仅来自 1..t-1 步 的编码观测融合。
关键词是”仅”。这个约束本质上是一种掩码纪律:结构上保证任何下标 >= t 的观测都无法影响第 t 步的表示。
这就是自回归语言模型里的因果掩码,移植到观测流上。
听起来平凡,说起来也确实平凡;但它在工程上极容易被破坏——按轨迹分批、帧栈上的双向注意力、在整条 episode 上算的归一化统计量,都会悄悄把未来引进来。
滚动视野扩散规划。 动作头一次预测 K 步未来动作,然后智能体扔掉 K-1 步,只执行第一步,取一帧新观测,从头重新规划。
被扔掉的动作没有白算:训练时它们是辅助监督目标,逼着隐表示编码”轨迹要去哪”;推理时联合预测对第一步动作构成一致性约束。
这就是模型预测控制的滚动视野,套在一个学出来的生成式规划器上。
代价写得很明白:每执行一步要付 K 步的计算量,换回来的是纯动作分块所放弃的闭环视觉反馈。
LiteStop。 它不在动作词表里放 stop token,而是读取 *初始全掩码状态 下的动作 logits——也就是任何去噪还没发生时的第一次前向——把它映射成停止概率。
直觉是:在全掩码态,模型的输出不是某个具体动作,而是”给定我看到的和被告知的,这里该属于哪一类行为”的先验判断,还没被半成品动作内容搅浑。
如果情况是”没什么可做了”,这会体现在先验的形状里。
代价是一个线性头,不需要额外前向。
   指令 ------------------------------+
                                       |
   obs_1 .. obs_(t-1)                  |
        |                              |
        v                              |
   [ 编码器 ] ---+                      |
                 v                      v
        [ 因果融合 ]  <----------- obs_t
        严格只看过去                    |
                 |                      |
                 v                      v
        +====================================+
        |         Dream-VLA 骨干             |
        |    ( 掩码扩散式动作头 )            |
        +====================================+
             |                         |
             | 全掩码态                | 去噪 N 次
             v                         v
        [ LiteStop ]            a_t, a_t+1, ... a_t+K-1
        由 logits 得 p(stop)          |
             |                        +--- a_t+1..a_t+K-1
             |                        |    ( 只作训练目标,
             |                        |      推理时全部丢弃 )
             |                        |
             |                        v
             +---- 停? ---- 否 ---> 执行 a_t
                     |                        |
                    是                        v
                     |                   新 obs_(t+1)
                     v                        |
                   终止                       +--> 回到循环
核喻:带航海日志的老式领航员。
想象一位 GPS 之前时代的领航员站在船桥上,手里是一份文字航行指令(“过第二个海角,然后朝灯塔方向偏航”)。
航海日志就是因果记忆。
上面记着已经走过的每一个方位和地标——仅此而已。
没人会把明天那一页递给他。
这个”缺席”就是记忆模块的全部贡献:一本记着未来条目的日志,会让你在还没经过第一个海角时就”数出”第二个,而这恰恰是让基准分数说谎的泄漏。
铅笔画在海图上的航线就是 K 步规划。
领航员不会只点一个记号;他会草草画出接下来好几段航程,因为不看后续走向,你判断不了眼下这一次转向对不对。
但他只把船开到第一个浮标,就回到海图前重新观测、把整条航线重画一遍。
那些被擦掉的铅笔线并没有浪费——它们约束了第一段航程——而且它们不是承诺。
这就是”规划 K 步、执行 1 步”。
桅顶的瞭望员就是 LiteStop。
他唯一的职责是喊”到了,抛锚”。
要点在于他不同时掌舵。
旧设计里舵手既要掌舵又要喊停,那声”停”和转向指令抢同一张嘴。
而 LiteStop 观察的那个时刻——全掩码态——正是瞭望员在任何人开始画新航线 之前 的第一眼。
未被成见污染的第一眼,恰恰是”我们到了吗”最可靠的读数。
关键概念
-
因果对齐(无未来泄漏):想象你训练一个学生预测明天的天气,但练习册的页边不小心印着明天的答案。
他练习时分数惊人,实战时一无是处。
在序列模型里这种泄漏通过注意力发生:如果第 t 步的表示能注意到第 t+3 帧,模型就会学到部署时不存在的捷径。
修法是用掩码让它 结构上不可能,而不是”我们会小心的”这种承诺。
在导航轨迹里这个泄漏特别诱人,因为未来帧往往 直接显示了目标,所以一个漏水的模型看起来会像具备极强的”长时序推理”,其实只是在偷看。
-
滚动视野(receding horizon):你把一次长途旅行的细节都规划好,但只订今晚的酒店,因为明天你会知道更多。
形式化地说:在 K 步上做优化,只承诺第 1 步,其余丢弃,然后重复。
工业过程控制几十年来就是这么干的(这就是 MPC 的含义)。
值得移植的洞见是:“规划得远”和”承诺得短”并不矛盾——长规划通过提供上下文改善了短承诺,同时又不继承长规划累积起来的不确定性。
-
把全掩码态当读数点:在掩码扩散式动作头里,生成从所有动作槽位全空开始。
那一瞬间模型的输出并不是一个动作,而是”给定我看到的和被告知的,这里适合哪一类行为”的概括。
这是一个异常干净的位置去问关于当前情境的是非题,因为还没有任何已提交的内容能带偏答案。
可复用的技巧是:生成模型的 初始 状态往往携带最干净的情境信号,你可以在那里挂廉价的辅助分类器。
框架转变
之前(主流空中 VLA):                之后(DreamFly):

  obs_t                                obs_1..obs_(t-1)  obs_t
    |                                       \            /
    v                                        \          /
 [ VLA 策略 ]                              [ 因果融合 ]
    |                                             |
    v                                             v
 a_t  ( "STOP" 只是词表里                   [ 扩散动作头 ]
       的一个 token, 与转向                  /            \
       动作互相竞争 )                       /              \
    |                              [ LiteStop ]      a_t..a_t+K-1
    v                              全掩码态             |
 执行 a_t                          读 p(stop)           | 留 a_t
    |                                   |               | 弃其余
    +--> 循环 ( 无记忆,                 +---- 门控 -----+
               无前瞻,                          |
               停止脆弱 )                       v
                                            执行, 重规划
                                      ( 记忆在长, 视野被预演,
                                        停止独立成头 )
一句话:从 被动的单步分类器 到 带书面过去与预演未来的闭环规划器,核心转变是把时间在三个方向上同时显式建模——向后是无泄漏的记忆,向前是被丢弃的预演,终点上是一个独立的决策。
专家评审
选题眼光:缺口是真的,但属于”补课型”缺口而非”前沿型”缺口。
空中 VLN 相对室内 VLN 确实被严重忽视,点出的三个失效模式也都是实践者天天抱怨的东西。
其中终止判断这一点尤其被低估:VLN 里 SR 和 SPL 都以”正确停止”为闸门,所以一个系统性偏弱的停止决策会悄悄给你其余所有改进设上天花板。
这是个好观察。
但让它成不了前沿贡献的原因是:三个问题没有一个是 未知 的——它们是已知且在这个具体设定下没人处理。
这篇论文位于空中 VLA 轨迹的整合期:一年之内总会有人做。
方法成熟度:巧在组装,不在原创。
因果掩码继承自自回归语言模型。
“规划 K 步执行 1 步”就是教科书 MPC,在操作领域自 Diffusion Policy 和 RT 系列的动作分块以来已是标配;搬到空中 VLN 是移植,不是发明。
LiteStop 是唯一有真正新意的一块,而且是小而得体的一块——读全掩码 logits 比另建一个停止网络或多跑一次前向都更省更干净。
论文应该被要求击败的更简单方案有两个:一是加了因果掩码的朴素帧栈(那套更花哨的记忆真的比直接拼最近 N 帧强吗?);二是挂在池化后的视觉-语言嵌入上的普通辅助停止头(“专门从全掩码态读”真的重要吗,还是任何停止头都行?)。
如果消融实验没把这两个隔离出来,贡献会缩水不少。
摘要里还完全没提计算代价:规划 K 步执行 1 步意味着每执行一步大约要付 K 倍规划算力,而这是在一个延迟本身就是物理安全约束的平台上。
对无人机来说这不是脚注。
实验诚意:头条数字看起来是诚实的——也就是说,它们很低。
OpenFly 上 32.04% (seen) / 29.46% (unseen) 的 SR,说明这个基准就是难。
seen 到 unseen 的差距很小(SR 约 2.6 个点),这既可以解读为泛化不错,也可能说明模型对 seen 环境本身也没拟合得太好。
值得注意的是 SPL 的差距更大(28.22 对 23.54),意味着 unseen 下即使成功了效率也更差——这与”停止触发前多绕了路”是一致的。
在完全相信这个故事之前我想看两样东西:把因果掩码 去掉 的逐组件消融(这是唯一能证明泄漏论点是承重结构而非修辞的数字),以及对 K 的扫描——如果性能对 K 基本平坦,那”滚动视野”的说法就只是装饰。
“在两个指标上都超过所有对比方法”这句话的分量,完全取决于对比了哪些方法、这些基线是否用了同样的骨干、同样的训练预算、同样的输入历史。
把基线复现成”没有历史”的版本,然后报告”加历史有用”,是一种熟悉的赢法。
写作功力:摘要组织得好,而且异常清楚地说明了每个模块干什么——三个问题、三个模块、干净的一一对应。
偷懒的地方几乎肯定是”为什么这个具体设计打得过它的廉价替代品”的论证;读起来这么整齐的摘要,背后的消融往往比叙事单薄。
最能把整篇论文抬一档的是 LiteStop 的分析部分:如果作者能展示 为什么 全掩码 logits 携带了与停止相关的信息——一个探针实验、目标附近 logit 几何的可视化、与隐式 stop token 对比的 precision/recall 曲线——那就能把本文唯一的新想法从”一个小技巧”变成”一个值得被引用的发现”。
现在它读起来是”我们试了,有用”。
判决:弱接收 —— 把三个已知技术能干地整合进一个被忽视的领域,靠一个确实漂亮的想法(LiteStop)撑着,而支撑那个想法的分析大概比它需要的要薄。
要点总结
值得”偷”的东西,按可迁移性大致排序:
-
从生成模型的初始状态上廉价读取辅助决策。 如果你的模型从全掩码态或纯噪声态出发,那第一次前向就是一份免费、未被污染的情境概括。
在上面挂分类器——终止、安全门控、模式选择、拒答。
成本是一层线性层,不需要额外前向。
这个技巧远远超出导航的范围。
-
把”何时停”和”做什么”解耦。 任何把终止塞进动作词表的策略,都在让它最重要的决策去和最频繁的决策抢位置。
这对 agentic LLM 循环同样适用:“调用工具”和”我完成了”作为兄弟 token,是一个已知的失效面。
给终止一个独立的头和一个可以在 precision/recall 曲线上调的阈值。
-
预测得远,承诺得近。 把预测中远期的那部分当作 监督信号,推理时丢掉。
你得到轨迹级的梯度信号,又不继承开环漂移。
任何目前只预测一步的序列策略都可以低成本试一下。
-
把因果掩码当作结构不变量,而不是自觉纪律。 如果你的训练管线按整条 episode 分批,那就先假定你在泄漏,直到你用构造(掩码)而不是靠眼睛检查证明了没有。
然后请把”掩码关掉”的消融数字报出来——那个数字才是你的”时序推理”里有多少其实是偷看的诚实度量。
这里没有的东西:新架构、新基准、可扩展性洞见。
如果你在找具身导航的概念性突破,可以跳过。
如果你正在把一个 VLA 策略推向落地,需要三个具体的工程修补以及一个证明它们能叠加的基准结果,那这二十分钟花得值。