Paper: 2603.11024 Authors: Marvin Limpijankit, Milad Alshomary, Yassin Oulad Daoud, Amith Ananthram, Tim Trombley, Elias Stengel-Eskin, Mohit Bansal, Noam M. Elcott, Kathleen McKeown Categories: cs.CV, cs.AI
The Gap
VLMs have gotten surprisingly good at art-related tasks — classifying style, describing paintings, even generating art in specific movements. But the field has mostly treated this as a benchmark problem: does the model get the right label? Nobody asked the harder question: why does it get the right label, and does that reasoning look anything like how a trained art historian would reason?
Prior interpretability work on vision models (CLIP probing, concept bottleneck models, saliency maps) tells you what features activate, but not whether those features are semantically coherent in the domain-specific sense that experts care about. You can find that “brushstroke texture” activates for Impressionism, but is that actually what distinguishes Monet from Renoir in the way an art historian would argue? That gap — between model-internal concepts and expert-validated reasoning — is what this paper targets.
Problem: VLMs predict style well, but HOW?
    |
    v
Prior work: saliency maps, probing classifiers
    |
    * Limitation: no domain-expert validation
    * Limitation: no causal link to prediction
    |
    v
Assumption: latent space encodes interpretable concepts
    |
    v
Method: decompose latent space -> extract concepts
        -> causal test -> art historian evaluation
    |
    v
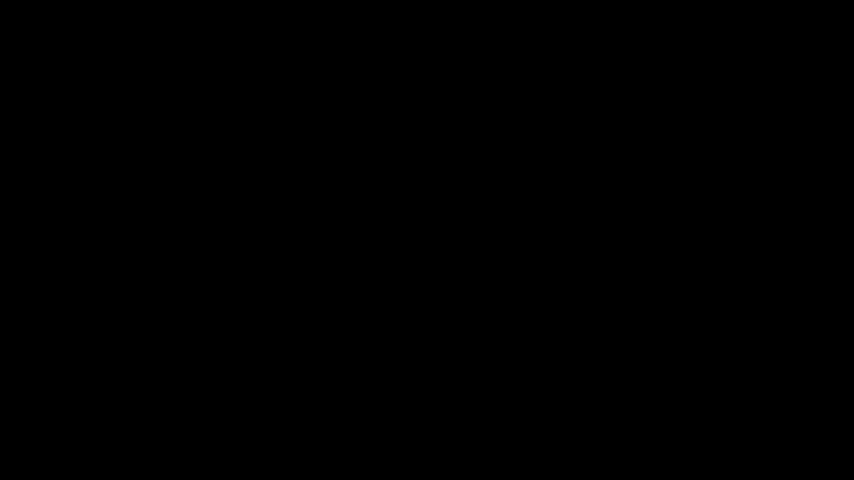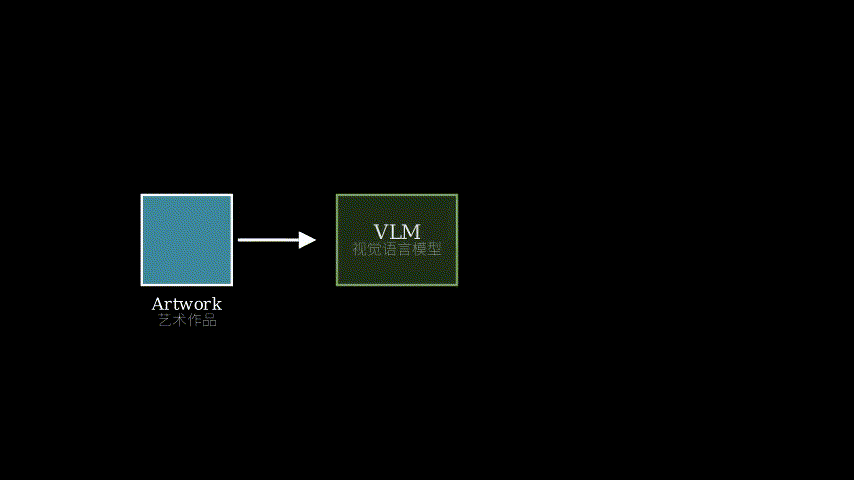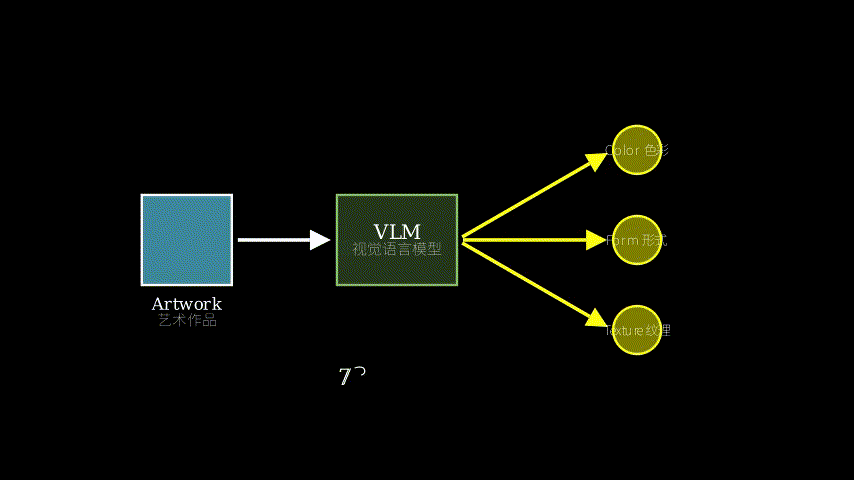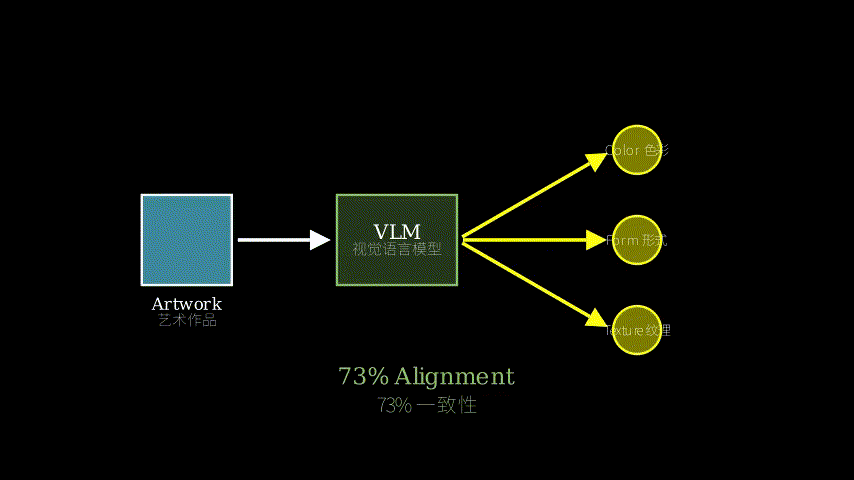
Evidence: 73% coherent concepts, 90% relevant to style
    |
    v
Conclusion: VLMs partially align with art-historical
            reasoning, but with interesting divergences
The Increment
One sentence: Before this paper, we knew VLMs could recognize artistic style; after it, we have a validated map of *which internal concepts drive that recognition and a human-expert verdict on whether those concepts are art-historically meaningful.
Core Mechanism
The method starts by taking a VLM’s latent representation of artworks and decomposing it using a technique called Non-negative Matrix Factorization (NMF). The idea is that the high-dimensional embedding of an artwork can be expressed as a weighted sum of a smaller set of basis vectors — each basis vector is a “concept.” NMF is chosen specifically because it produces additive, non-negative components, which tend to be more interpretable than PCA components that can cancel each other out.
Each extracted concept is then visualized by finding the image patches that maximally activate it. This gives you something a human can look at: a grid of patches that all share some visual property. The next step is causal — they intervene on the concept activations (ablate them, amplify them) and measure the effect on the style prediction. This separates concepts that are merely correlated with a style from those that actually drive the prediction.
Finally, art historians evaluate each concept on two axes: (1) does it represent a coherent, semantically meaningful visual feature? (2) is it relevant to the style being predicted? This is the part that makes the paper unusual — the ground truth isn’t a benchmark label, it’s expert human judgment.
Artwork images
    |
    v
VLM encoder -> latent embeddings (high-dim)
    |
    v
NMF decomposition
    |
    +---> Concept 1 (basis vector + activation weights)
    +---> Concept 2
    +---> Concept N
    |
    v
For each concept:
  [patch visualization] -> human-readable
  [causal ablation]     -> does removing it hurt prediction?
    |
    v
Art historian evaluation:
  coherent? (yes/no)  x  relevant? (yes/no)
    |
    v
Alignment score between VLM reasoning
and art-historical reasoning
Think of it like a wine sommelier exam, but in reverse. Normally, a sommelier tastes a wine and explains why they think it’s a 2015 Burgundy — the tannin structure, the nose, the finish. Here, the model is the sommelier, and the researchers are the examiners. They crack open the sommelier’s head, pull out the list of features they used (“dark fruit,” “earthy finish,” “medium acidity”), and then ask a Master of Wine: “Are these actually the right things to be noticing for a Burgundy?” The NMF decomposition is the head-cracking. The patch visualization is reading the feature list. The causal ablation is checking which features actually drove the call. The art historian evaluation is the Master of Wine’s verdict.
Key Concepts
-
Non-negative Matrix Factorization (NMF): Imagine you have a big spreadsheet where each row is an artwork and each column is a dimension in the VLM’s embedding space. NMF finds a smaller set of “prototype patterns” such that every artwork can be described as a mix of those patterns, with all weights positive. The positivity constraint is key — it means concepts add together rather than cancel, which makes them easier to interpret. Concretely: if concept 3 activates strongly for a painting, you can look at the patches that define concept 3 and say “ah, this is about diagonal brushstrokes in warm tones.”
-
Causal ablation: Correlation isn’t causation, even inside a model. A concept might activate strongly for Baroque paintings just because Baroque paintings tend to be dark, and the concept happens to encode darkness — but darkness might not be *why the model says “Baroque.” Causal ablation tests this by zeroing out a concept’s contribution and seeing if the prediction changes. If the prediction tanks, the concept was load-bearing. If it doesn’t, the concept was a passenger.
-
Art-historical style reasoning: Art historians don’t just say “this looks like Impressionism.” They argue from specific formal properties — broken brushwork, optical color mixing, rejection of sharp contour, interest in transient light. These are domain-specific criteria with a long scholarly tradition. The paper uses this as an external validity check: does the model’s internal reasoning vocabulary overlap with this tradition?
Framework Shift
Before (mainstream approach):        After (this paper):

  Artwork                              Artwork
     |                                    |
     v                                    v
  VLM                                  VLM encoder
     |                                    |
     v                                    v
  Style label                          NMF concepts
     |                                  /   |   \
  Benchmark                           C1   C2   C3
  accuracy                             |    |    |
     |                               causal test
  "Model works"                         |
                                   art historian
                                    evaluation
                                        |
                                   "Model reasons
                                    like this,
                                    experts say
                                    X% is valid"
From accuracy-as-proxy to mechanism-as-subject, the core shift is: stop asking if the model is right and start asking how it’s right (or wrong).
Expert Assessment
Problem choice: This is a real gap, not a manufactured one. The interpretability-meets-domain-expertise angle is genuinely underexplored, and art is a good testbed because the expert vocabulary is rich and well-documented. The timing is right — VLMs are capable enough that the question is interesting, and the field is hungry for interpretability work that goes beyond saliency maps.
Method maturity: NMF for concept extraction is not new — it’s been used in neuroscience and NLP for years. The novelty is the pipeline: NMF + causal ablation + expert evaluation, applied to art style. That’s a reasonable combination, not a breakthrough. The causal ablation step is the most technically interesting piece; the NMF itself is fairly standard. One could ask whether more recent concept extraction methods (e.g., sparse autoencoders, which are having a moment in mechanistic interpretability) would have been more principled, and the paper doesn’t really engage with that literature.
Experimental integrity: The 73% and 90% numbers sound impressive but depend heavily on how the art historian evaluation was structured — inter-rater agreement, how “coherent” and “relevant” were defined, how many historians were involved, and whether they were blind to the model’s predictions. The abstract doesn’t give enough detail to fully trust these numbers, and that’s a flag. If the evaluation protocol is loose, the headline stats could be inflated. The causal ablation is more trustworthy because it’s quantitative and model-internal.
Writing quality: The abstract buries the most interesting finding — the cases where an irrelevant concept *still successfully predicts style, and the art historians’ explanation (formal properties like light/dark contrast). That’s the intellectually richest part of the paper and it’s mentioned almost as an afterthought. A rewrite of the results section that leads with the failure modes and their interpretations would make this paper significantly more memorable.
Verdict: weak accept — solid interdisciplinary contribution with a real gap, but the evaluation methodology needs more transparency and the method is incremental rather than novel.
Takeaways
The most transferable idea here is the expert-in-the-loop concept validation pipeline: decompose latent space with NMF, visualize concepts as patch grids, run causal ablation to filter to load-bearing concepts, then bring in domain experts to evaluate coherence and relevance. This exact pipeline could be dropped into medical imaging (do the concepts a radiology model uses match what radiologists look for?), legal document classification (do the features a contract classifier uses match legal doctrine?), or any domain where there’s a rich expert vocabulary to compare against.
The specific finding about “irrelevant but successful” concepts is also worth stealing as a framing device: when a model gets the right answer for the wrong reason, what does that tell you about what the model has actually learned? That’s a useful lens for any interpretability work, not just art.
论文: 2603.11024 作者: Marvin Limpijankit, Milad Alshomary, Yassin Oulad Daoud, Amith Ananthram, Tim Trombley, Elias Stengel-Eskin, Mohit Bansal, Noam M. Elcott, Kathleen McKeown 分类: cs.CV, cs.AI
缺口
视觉语言模型在艺术相关任务上的表现越来越好——风格分类、画作描述、甚至按特定流派生成图像。 但整个领域基本上把这当成一个基准测试问题:模型有没有给出正确标签? 没有人追问更难的问题:它为什么给出正确标签?它的推理过程和训练有素的艺术史家的推理过程有没有任何相似之处?
此前的视觉模型可解释性工作(CLIP 探针、概念瓶颈模型、显著性图)能告诉你哪些特征被激活,但无法告诉你这些特征在领域专家眼中是否语义连贯。 你可以发现”笔触纹理”在印象派作品上激活,但这真的是艺术史家区分莫奈和雷诺阿的方式吗? 模型内部概念与专家验证推理之间的这道鸿沟,正是本文要填补的。
问题:VLM 能预测风格,但凭什么?
    |
    v
已有工作:显著性图、探针分类器
    |
    * 局限:没有领域专家验证
    * 局限:没有与预测的因果联系
    |
    v
假设:潜在空间编码了可解释的概念
    |
    v
方法:分解潜在空间 -> 提取概念
      -> 因果检验 -> 艺术史家评估
    |
    v
证据:73% 概念连贯,90% 与风格相关
    |
    v
结论:VLM 部分对齐艺术史推理,
      但存在有趣的偏差
增量
一句话:这篇论文之前,我们知道 VLM 能识别艺术风格;之后,我们有了一张经过人类专家验证的地图,知道哪些内部概念驱动了这种识别,以及这些概念在艺术史意义上是否真的说得通。
核心机制
方法的第一步是拿到 VLM 对画作的潜在表示,用非负矩阵分解(NMF)对其进行分解。 核心思路是:一幅画的高维嵌入可以表示为一组基向量的加权和,每个基向量就是一个”概念”。 选择 NMF 的原因在于它产生加法性、非负的分量——这比 PCA 分量更容易解释,因为 PCA 分量可以相互抵消。
每个提取出的概念通过找到最大激活它的图像块来可视化。 这给了人类一个可以直接看的东西:一组共享某种视觉属性的图像块网格。 下一步是因果性的——他们对概念激活进行干预(消融或放大),测量对风格预测的影响。 这把”仅仅与某种风格相关”的概念和”真正驱动预测”的概念区分开来。
最后,艺术史家从两个维度评估每个概念:(1)它是否代表一个连贯的、语义上有意义的视觉特征?(2)它与被预测的风格是否相关? 这是让这篇论文与众不同的部分——真值不是基准标签,而是专家的人类判断。
画作图像
    |
    v
VLM 编码器 -> 潜在嵌入(高维)
    |
    v
NMF 分解
    |
    +---> 概念 1(基向量 + 激活权重)
    +---> 概念 2
    +---> 概念 N
    |
    v
对每个概念:
  [图像块可视化] -> 人类可读
  [因果消融]     -> 移除它会影响预测吗?
    |
    v
艺术史家评估:
  连贯?(是/否)  x  相关?(是/否)
    |
    v
VLM 推理与艺术史推理的对齐程度
把这个方法想象成一场反向的品酒师考试。 通常,侍酒师品一口酒,解释为什么认为这是 2015 年的勃艮第——单宁结构、香气、余味。 这里,模型是侍酒师,研究者是考官。 他们打开侍酒师的脑袋,取出他用到的特征清单(“深色水果”、“泥土气息”、“中等酸度”),然后问一位葡萄酒大师:“这些真的是判断勃艮第该注意的东西吗?” NMF 分解是打开脑袋的过程。 图像块可视化是读取特征清单。 因果消融是检验哪些特征真正驱动了判断。 艺术史家评估是葡萄酒大师的裁决。
关键概念
-
非负矩阵分解(NMF):想象一张大表格,每行是一幅画,每列是 VLM 嵌入空间的一个维度。 NMF 找到一组更小的”原型模式”,使得每幅画都能用这些模式的正权重混合来描述。 非负约束是关键——它意味着概念只能叠加,不能相互抵消,这让解释变得更容易。 具体来说:如果概念 3 对某幅画强烈激活,你可以看定义概念 3 的图像块,然后说”啊,这是关于暖色调中的斜向笔触”。
-
因果消融:即使在模型内部,相关性也不等于因果性。 一个概念可能在巴洛克画作上强烈激活,仅仅因为巴洛克画作往往很暗,而这个概念恰好编码了暗度——但暗度未必是模型说”巴洛克”的原因。 因果消融通过清零一个概念的贡献并观察预测是否改变来检验这一点。 如果预测崩了,这个概念是承重墙;如果没变,它只是个乘客。
-
艺术史风格推理:艺术史家不只是说”这看起来像印象派”。 他们从具体的形式属性出发——破碎的笔触、光学色彩混合、拒绝清晰轮廓、对瞬息光线的兴趣。 这些是有着悠久学术传统的领域特定标准。 本文用这套标准作为外部效度检验:模型的内部推理词汇表与这套传统有多少重叠?
框架转变
之前(主流方法):                之后(本文方法):

  画作                              画作
   |                                  |
   v                                  v
  VLM                              VLM 编码器
   |                                  |
   v                                  v
  风格标签                          NMF 概念
   |                               /   |   \
  基准准确率                       C1   C2   C3
   |                                |    |    |
 "模型有效"                       因果检验
                                      |
                                  艺术史家评估
                                      |
                                  "模型这样推理,
                                   专家说 X% 有效"
从”准确率作为代理”到”机制本身作为研究对象”,核心转变是:不再问模型对不对,而是问它怎么对的(或怎么错的)。
专家评审
选题眼光:这是真缺口,不是人造的。 可解释性与领域专业知识结合的角度确实被严重低估,艺术是个好的测试床,因为专家词汇丰富且有文献记录。 时机也对——VLM 已