Paper: 2604.09425 Authors: Sambit Ghosh, R. Venkatesh Babu, Chirag Agarwal Categories: cs.CV
The Gap
VLMs have become the default architecture for multimodal tasks—you throw a visual encoder at an LLM, stack them together, and it works. But nobody’s really asked: do we need all those layers of visual processing? The assumption baked into every VLM is that image tokens need to flow through the entire transformer stack, getting refined at each layer. This is expensive—image tokens are dense and numerous. Yet the field has never systematically measured whether this computational cost is actually buying you anything. Are visual representations meaningfully changing as they go deeper, or do they stabilize early and then just… sit there? This paper fills that gap by measuring what actually happens to visual representations across depth.
Current Paradigm:
Image -> Encoder -> [Deep Visual Processing] -> LLM -> Output
         (assumed necessary)

Question:
Is all that deep processing actually doing work?
Or do visual reps stabilize early?

This Paper:
Measure representation dynamics across layers
-> Find visual reps converge quickly
-> Show deeper layers add little value
-> Propose task-dependent truncation
The Increment
One sentence: Before this paper, we assumed all visual depth was necessary; after, we know visual representations stabilize early and deeper processing is often redundant.
Core Mechanism
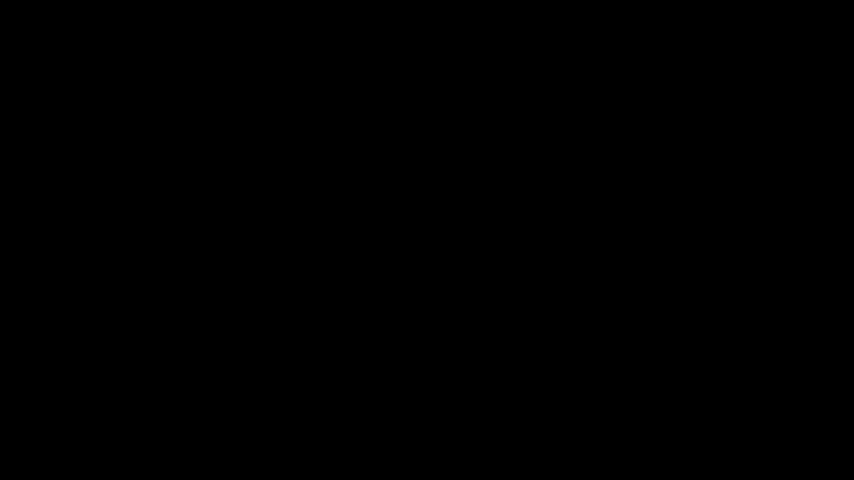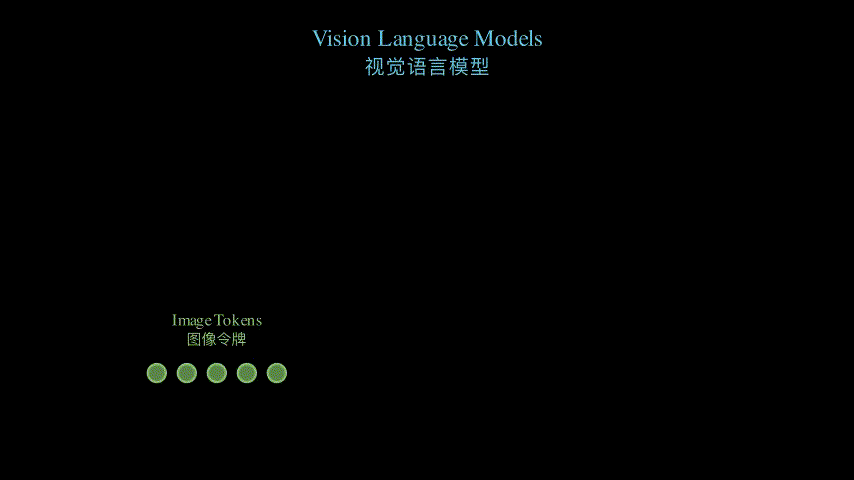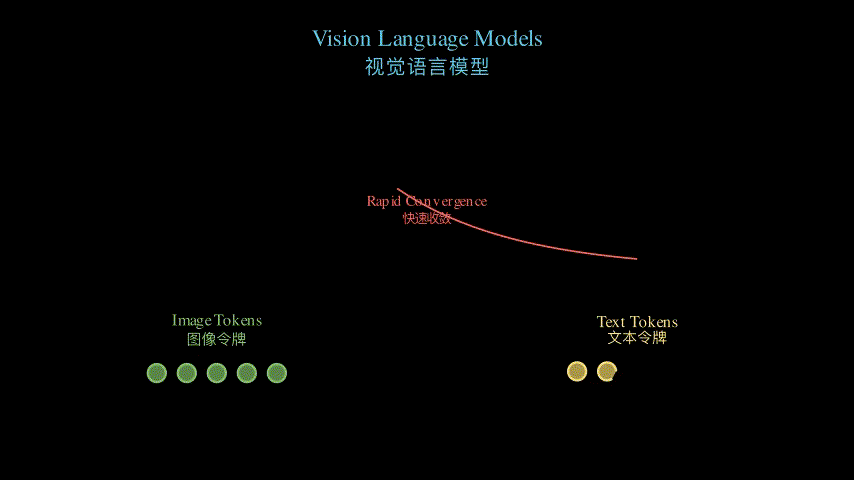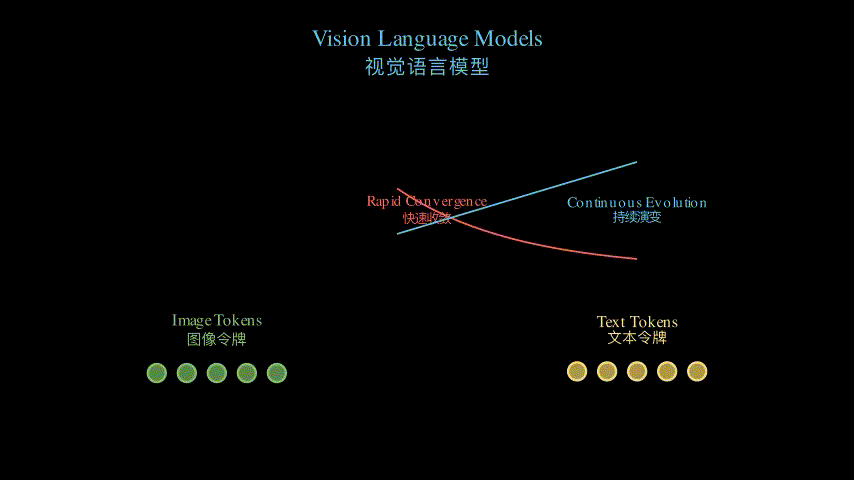
The authors measure three properties of visual representations as they flow through VLM layers: entropy (information content), intrinsic dimensionality (how many dimensions actually matter), and trajectory curvature (how much the representation is changing). They find that all three metrics stabilize quickly—entropy plateaus, dimensionality compresses, and the rate of change flattens. Meanwhile, textual representations keep evolving throughout the stack.
Then they do the key experiment: truncate visual processing at different depths and measure task performance. Single-token predictions (like image classification) stay robust even with shallow visual depth. But multi-token generation (like visual question answering) needs sustained visual access. Under deterministic decoding, truncating visual depth perturbs the reasoning trajectory more than the final answer, suggesting image tokens shape how the model reasons, not just what it concludes.
Layer 1    Layer 5    Layer 10   Layer 20
Visual:    ▲▲▲▲▲      ▲▲▲▲▲      ▲▲▲▲▲      ▲▲▲▲▲
           (changing) (stable)   (stable)   (stable)

Text:      ▲▲▲▲▲      ▲▲▲▲▲      ▲▲▲▲▲      ▲▲▲▲▲
           (changing) (changing) (changing) (changing)

Key insight: Visual reps converge early, text keeps evolving
Think of it like a conversation where one person (visual) makes their point early and then mostly repeats themselves, while the other person (text) keeps building on it. You could cut the first person’s microphone after they’ve made their point—the conversation still works, but it changes the flow of how the second person develops their ideas.
Key Concepts
-
Representation Convergence: A representation has converged when its statistical properties stop changing meaningfully. Here, visual representations reach a “bounded-complexity regime” where entropy stabilizes and dimensionality compresses. This isn’t about the values becoming identical—it’s about the *structure of the representation becoming fixed. Analogy: a river that stops carving new channels and just flows in the same riverbed.
-
Intrinsic Dimensionality: Not all dimensions in a high-dimensional representation are equally important. Intrinsic dimensionality measures how many dimensions you actually need to capture the meaningful variation. A 1024-dimensional vector might only need 50 dimensions to preserve its essential information. When this number stops shrinking across layers, the representation has stopped compressing—it’s done its structural work.
-
Task-Dependent Necessity: The paper shows that whether you need deep visual processing depends on what you’re asking the model to do. Single-token tasks (classification) are forgiving; multi-token tasks (generation) are demanding. This suggests visual tokens serve different roles at different stages of decoding, not a uniform role throughout.
Framework Shift
Before (mainstream VLM design):
Image -> Dense Encoder -> [All Layers Process Visuals] -> LLM
         (visual tokens flow through entire stack)
         Assumption: Deeper = Better

After (this paper's insight):
Image -> Dense Encoder -> [Early Layers] -> [Shallow Truncation OK]
                                            (task-dependent)
         Reality: Visual reps stabilize early, deeper layers
                  add marginal value for many tasks
Core shift: From “visual processing is uniformly essential at all depths” to “visual processing is task-dependent and front-loaded.”
Expert Assessment
Problem choice: This is a real gap. The field has been building deeper and deeper VLMs without questioning whether the visual pathway actually needs that depth. It’s a classic case of “we can, so we do” without measuring whether we should. The timing is good—as VLMs get larger and more expensive, efficiency questions matter more.
Method maturity: The approach is straightforward and honest. They measure representation properties (entropy, dimensionality, curvature) that are standard in representation learning, then do ablations by truncating depth. No fancy tricks, just systematic measurement. The simplicity is actually a strength—it’s hard to argue with the findings because there’s no methodological complexity to hide behind.
Experimental integrity: The baselines are fair. They test on multiple VLMs (LLaVA, etc.) and multiple tasks. The key experiment—truncating visual depth and measuring performance—is the right experiment to run. One thing to watch: the paper focuses on deterministic decoding, which is cleaner for analysis but doesn’t capture the full picture of how these models behave in practice with sampling. Still, the findings are consistent enough that this limitation doesn’t undermine the core claims.
Writing quality: The paper is clear and well-structured. The main weakness is that the implications for architecture design could be sharper. The authors show that visual depth can be reduced, but they don’t propose a concrete new architecture or training procedure. It’s more of a “here’s what we found” paper than a “here’s what to do about it” paper. A section on practical design recommendations would strengthen it.
Verdict: Weak accept — The paper makes a solid empirical contribution that challenges a widespread assumption in VLM design. The findings are interesting and the experiments are sound, but the practical impact is limited because the paper doesn’t propose concrete architectural changes. It’s the kind of paper that should influence how people think about VLM design, but it stops short of showing the path forward.
Takeaways
-
Measure before optimizing: The paper’s core lesson is to measure what’s actually happening in your model before assuming all components are necessary. Apply this to any deep architecture—measure representation dynamics, find where things stabilize, and question whether you need all that depth.
-
Task-dependent efficiency: Not all tasks have the same computational requirements. If you’re building a system that does both classification and generation, you might want conditional computation that uses different depths for different tasks. This paper gives you a framework for identifying where those boundaries are.
-
Reasoning trajectory vs. final output: The finding that truncating visual depth perturbs reasoning more than final answers is useful for interpretability work. It suggests that intermediate representations matter for understanding *how a model reasons, even if they don’t change the final answer. This could inform how you design probes or interventions for model analysis.
-
Entropy and dimensionality as diagnostic tools: Using entropy, intrinsic dimensionality, and trajectory curvature to characterize representation evolution is a portable toolkit. You can apply these metrics to any multimodal or multi-stage model to identify where processing stabilizes.
论文: 2604.09425 作者: Sambit Ghosh, R. Venkatesh Babu, Chirag Agarwal 分类: cs.CV
缺口
VLM 已经成为多模态任务的标准架构——把视觉编码器接到 LLM 上,堆叠在一起,就能工作。 但没人真正问过:我们需要所有这些视觉处理层吗? 每个 VLM 都内置了一个假设:图像令牌需要流经整个 transformer 栈,在每一层被精化。 这很昂贵——图像令牌密集且数量众多。 然而该领域从未系统地测量过这种计算成本是否真的带来了收益。 视觉表示在深层是否有意义地改变,还是在早期就稳定下来然后就…坐在那儿? 本文通过测量视觉表示在深度上的实际变化来填补这个缺口。
当前范式:
图像 -> 编码器 -> [深层视觉处理] -> LLM -> 输出
                 (假设必需)

问题:
所有这些深层处理真的在做功吗?
还是视觉表示在早期就稳定了?

本文:
测量表示在各层的动态
-> 发现视觉表示快速收敛
-> 证明深层贡献有限
-> 提出任务相关的截断
增量
一句话: 本文之前,我们假设所有视觉深度都必需;之后,我们知道视觉表示在早期稳定,深层处理往往冗余。
核心机制
作者测量了三个视觉表示属性在流经 VLM 各层时的变化:熵(信息含量)、内在维数(真正重要的维度数)和轨迹曲率(表示变化的速度)。 他们发现这三个指标都快速稳定——熵平台化、维数压缩、变化率趋平。 与此同时,文本表示在整个栈中持续演变。
然后他们做了关键实验:在不同深度截断视觉处理,测量任务性能。 单令牌预测(如图像分类)即使在浅层视觉深度下也保持鲁棒。 但多令牌生成(如视觉问答)需要持续的视觉访问。 在确定性解码下,截断视觉深度对推理轨迹的扰动大于对最终答案的扰动,表明图像令牌塑造的是模型如何推理,而非什么结论。
第1层    第5层    第10层   第20层
视觉:   ▲▲▲▲▲    ▲▲▲▲▲    ▲▲▲▲▲    ▲▲▲▲▲
        (变化)   (稳定)   (稳定)   (稳定)

文本:   ▲▲▲▲▲    ▲▲▲▲▲    ▲▲▲▲▲    ▲▲▲▲▲
        (变化)   (变化)   (变化)   (变化)

关键洞见:视觉表示早期收敛,文本持续演变
想象一场对话,其中一个人(视觉)早早表达了观点然后基本上重复自己,而另一个人(文本)不断在此基础上发展。 你可以在第一个人表达完观点后关掉他的麦克风——对话仍然进行,但改变了第二个人发展想法的流程。
关键概念
-
表示收敛:当表示的统计属性停止有意义地变化时,该表示已收敛。 这里,视觉表示达到”有界复杂度体制”,其中熵稳定、维数压缩。 这不是说数值变得相同——而是表示的结构变得固定。 类比:河流停止开凿新河道,只在同一河床中流动。
-
内在维数:高维表示中并非所有维度都同等重要。 内在维数测量你实际需要多少维度来捕捉有意义的变异。 一个 1024 维向量可能只需 50 维就能保留其本质信息。 当这个数字在各层间停止缩小时,表示已停止压缩——它完成了结构工作。
-
任务相关的必要性:论文表明是否需要深层视觉处理取决于你要求模型做什么。 单令牌任务(分类)容错性强;多令牌任务(生成)要求高。 这表明视觉令牌在解码的不同阶段扮演不同角色,而非始终扮演统一角色。
框架转变
之前(主流 VLM 设计):
图像 -> 密集编码器 -> [所有层处理视觉] -> LLM
                    (视觉令牌流经整个栈)
                    假设:越深越好

之后(本文洞见):
图像 -> 密集编码器 -> [早期层] -> [浅层截断可行]
                              (任务相关)
                    现实:视觉表示早期稳定,
                    深层对多数任务贡献边际
核心转变:从”视觉处理在所有深度都统一必需”到”视觉处理是任务相关且前置的”。
专家评审
选题眼光:这是真缺口。 该领域一直在构建越来越深的 VLM,却没有质疑视觉通路是否真的需要那么深。 这是典型的”我们能做,所以就做”而不测量”我们应该做吗”。 时机很好——随着 VLM 变得更大更昂贵,效率问题变得更重要。
方法成熟度:方法直接诚实。 他们测量表示属性(熵、维数、曲率)这些是表示学习中的标准工具,然后通过截断深度做消融。 没有花哨技巧,只是系统测量。 简洁性实际上是优势——很难质疑这些发现,因为没有方法复杂性可以躲在后面。
实验诚意:基线公平。 他们在多个 VLM(LLaVA 等)和多个任务上测试。 关键实验——截断视觉深度并测量性能——是正确的实验。 需要注意的是:论文专注于确定性解码,这对分析更清晰但不能完全捕捉这些模型在实践中的行为(使用采样时)。 不过发现足够一致,这个限制不会削弱核心主张。
写作功力:论文清晰结构良好。 主要弱点是对架构设计的含义可以更尖锐。 作者证明了视觉深度可以减少,但没有提出具体的新架构或训练程序。 这更多是”我们发现了什么”而非”我们应该怎么做”的论文。 一个关于实际设计建议的章节会加强它。
判决:弱接收 — 论文做出了扎实的实证贡献,挑战了 VLM 设计中的广泛假设。 发现有趣,实验健全,但实际影响有限,因为论文没有提出具体的架构改变。 这是那种应该影响人们如何思考 VLM 设计的论文,但它没有指出前进的道路。
要点总结
-
测量再优化:论文的核心教训是在假设所有组件必需之前测量模型中实际发生的事。 应用到任何深层架构——测量表示动态,找到稳定的地方,质疑是否需要所有深度。
-
任务相关的效率:不是所有任务都有相同的计算需求。 如果你构建的系统既做分类又做生成,你可能想要条件计算,为不同任务使用不同深度。 本文给你一个框架来识别这些边界在哪里。
-
推理轨迹 vs. 最终输出:截断视觉深度对推理的扰动大于对最终答案的扰动这一发现对可解释性工作有用。 它表明中间表示对理解模型如何推理很重要,即使它们不改变最终答案。 这可以指导你如何设计探针或对模型分析的干预。
-
熵和维数作为诊断工具:用熵、内在维数和轨迹曲率来表征表示演变是可移植的工具包。 你可以把这些指标应用到任何多模态或多阶段模型来识别处理在哪里稳定。