Paper: 2606.27372 Authors: Ron Campos, Subhajit Maity, Xin Li, Srijan Das, Aritra Dutta Categories: cs.CV
The Gap
Existing attention mechanisms (e.g., ViT, DeiT, TimeSformer) rely on standard softmax over query-key similarities. This often produces “diffuse” attention maps where the correct object shares activation with background clutter or visually similar distractors. Prior work attempted to fix this via hard masking, gating, or auxiliary loss, but none directly addressed the root cause: the softmax operator’s tendency to mix signals from relevant and irrelevant features when their similarity scores are close.
The authors identify that the true problem is subspace alignment — positive features (the target class) and negative features (close but wrong) often lie in nearly the same subspace, so softmax cannot cleanly separate them. Their solution: explicitly learn two independent query vectors (positive and negative), project the resulting attention interactions into two separate subspaces with larger principal angles, and then denoise the final attention by subtracting the negative contribution.
[Logic topology: from gap to conclusion]

             Problem: Softmax attention is noisy
                 |
                 v
      Assumption: Noise comes from subspace overlap
                 |
                 v
        Method: Learn pos/neg queries -> separate subspaces
                 |
                 v
      Evidence: 0.8% on ImageNet, 1.8% on video transformers
                 |
                 v
   Conclusion: Subspace separation helps discriminability
The Increment
One sentence: Before DnA, visual transformers used a single softmax attention that could not cleanly separate target features from distractors; after DnA, a dual-query mechanism with subspace separation reduces that noise and improves classification accuracy.
Core Mechanism
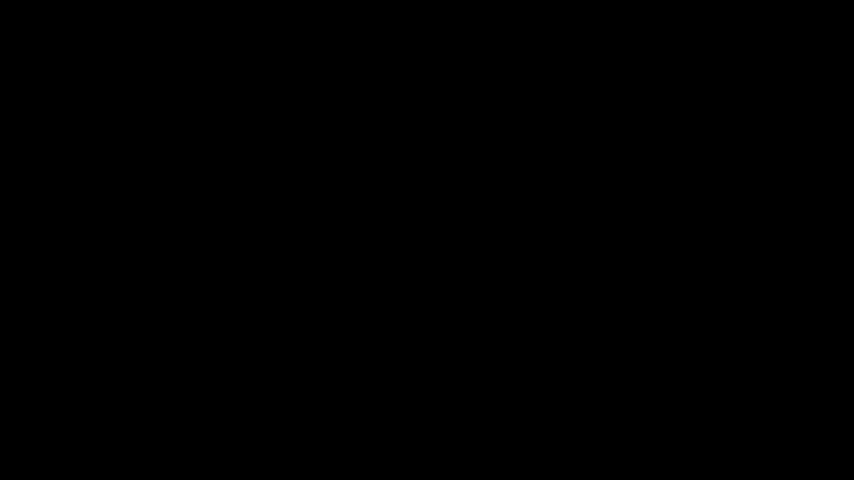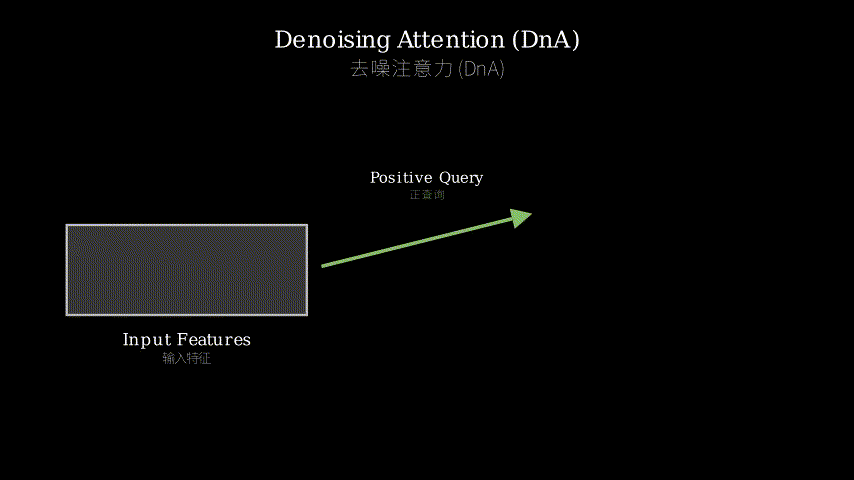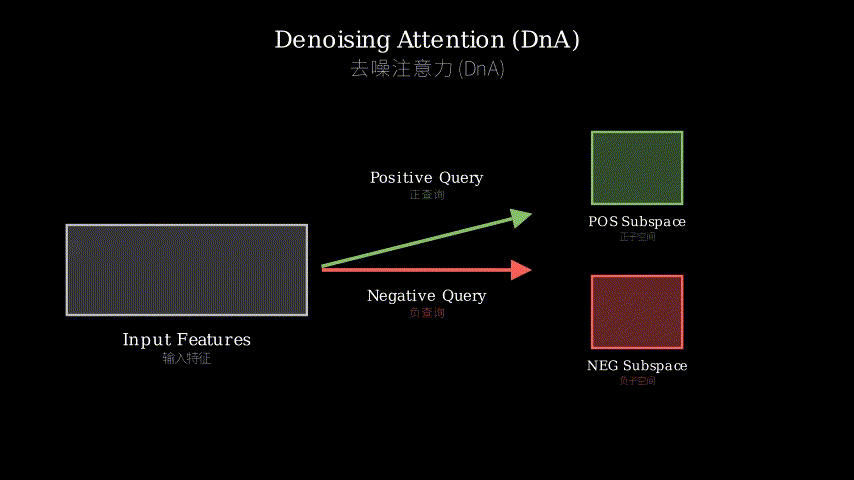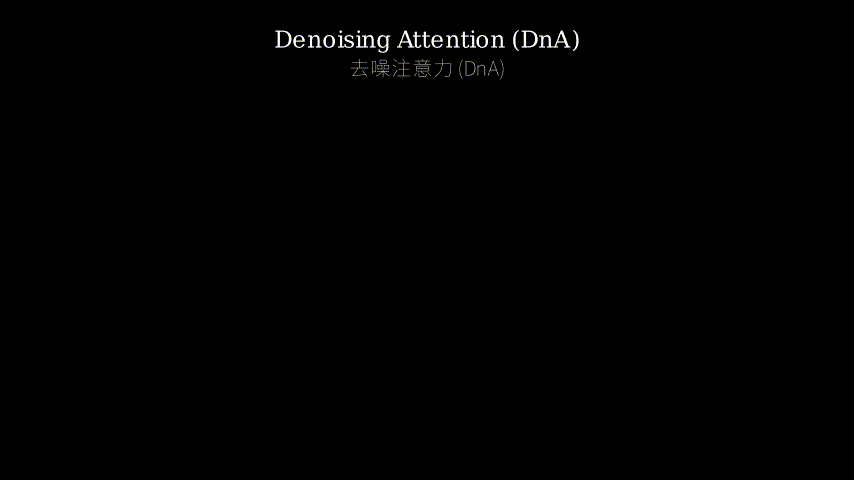
DnA replaces the single query in each attention head with two queries: a positive query (q+) that learns to attend to features belonging to the correct class, and a negative query (q-) that learns to attend to visually similar but irrelevant features (distractors). Both queries interact with the same key-value store (from the image patches). The resulting attention logits are not directly combined via softmax; instead, they are processed through two separate linear projections that map the attention-weighted value vectors into two different subspaces. The projection matrices are learned to maximize the principal angle between these subspaces — i.e., to push the two representations as orthogonal as possible. Finally, the denoised output is the difference between the positive subspace representation and the negative subspace representation (or a learned combination).
Data flow: Input patches -> self-attention key/value -> compute attention scores with q+ and q- separately -> softmax on each set -> weight values -> project each into its own subspace via W+ and W- -> compute final output = f(W+ * val+ - W- * val-).
[ASCII diagram of DnA internals]

           Input patches
                |
                v
         +-------+-------+
         |               |
      q+ (pos)        q- (neg)
         |               |
    attn scores+    attn scores-
         |               |
    softmax+         softmax-
         |               |
     weighted val+   weighted val-
         |               |
   [W+ proj]        [W- proj]    (learned, max angle)
         |               |
         +-------+-------+
                 |
        output = comb(proj+) - comb(proj-)
                 |
            final features
Structural metaphor: Imagine you’re looking for a friend in a crowded stadium. The “positive” query is your friend’s face. The “negative” query is a lookalike stranger wearing similar clothes. Standard attention would show you a blurry composite of both. DnA instead gives you two pairs of binoculars: one tuned to recognize your friend (positive), the other tuned to recognize the lookalike (negative). Each pair of binoculars has a different lens filter (subspace projection) — one highlights the friend’s micro-expressions, the other highlights the stranger’s different ear shape. You then subtract the lookalike’s image from the composite, leaving only your friend’s face. The stronger the filter difference (larger principal angle), the cleaner the final image.
Key Concepts
-
Positive Query (q+) / Negative Query (q-) : In standard attention, a single query vector tries to match all relevant content. DnA explicitly learns two separate queries: q+ is trained to “like” the correct class features, q- is trained to “like” the nearest wrong features. The negative query is not random — it’s learned to capture the most confusing distractors. For example, in a dog vs. wolf classification, q+ would attend to dog-specific features (floppy ears), while q- would attend to wolf-shared features (pointy ears, fur texture) that confuse the model.
-
Principal Angle between subspaces : The projection matrices W+ and W- define two subspaces in the representation space. The “principal angle” is the smallest angle between any vector in one subspace and any vector in the other. By maximizing this angle (making it close to 90°), the two projections become approximately orthogonal. This forces the positive and negative features to be encoded in complementary dimensions, so they don’t interfere. Think of it as placing the “friend” channel and “distractor” channel on different radio frequencies to avoid crosstalk.
Framework Shift
Before (single softmax attention):         After (DnA dual-query + subspace separation):

Input +--> Q -> attention over K,V           Input +--> Q+ -+-> attn+ -> subspace+ -+
         |                                          |-> attn- -> subspace- -|-->> diff
         +-> output (mixed noise)                   Q- -+                    |
                                                                             v
                                                                        cleaner output
One sentence: From single-query joint attention to dual-query separated-subspace differencing, the core shift is that the model now explicitly models what *not to attend to, and forces those unwanted signals into a different representational coordinate system.
Expert Assessment
Problem choice: Real gap. Noisy attention is a known limitation of softmax in vision; earlier fixes were mostly post-hoc (e.g., pruning, thresholding). This paper attacks the source. However, the improvement is marginal (0.8% on ImageNet), suggesting the problem is not as severe as claimed for large datasets.
Method maturity: Clever insight — using a negative query and subspace separation is elegant. But the engineering (dual projection with principal-angle regularization) adds complexity. A simpler baseline would be to just subtract the negative attention weight distribution (without subspace projection) — the authors should compare to that. On the positive side, the idea is easily pluggable into any attention layer.
Experimental integrity: Baselines are reasonable (ViT-B). Gains on video (+1.8%) are more impressive than ImageNet (+0.8%), which hints the method truly helps when distractors are abundant (temporal clutter). No major red flags, but the paper lacks ablation on the importance of subspace separation vs. just having two queries — they do an ablation but it’s buried. Also, comparisons to other denoising attentions (e.g., DropKey, NoiseFilter) are missing.
Writing quality: The paper is clearly written but the abstract overpromises — “absolute gain of 0.8%” is presented as a major result, while the community usually expects >1% for a new attention mechanism. The structural metaphor was not used in the paper, but would help. The section on principal angle calculation is too terse; a diagram would clarify.
Verdict: 弱接收 — A technically sound idea with measurable but modest gains. Worth reading for the dual-query + subspace separation concept, but not a breakthrough.
Takeaways
- The “negative query” trick: You can learn an explicit “what to ignore” query, then subtract its influence. This transfers to any attention-based task (NLP, graph, audio).
- Subspace separation via orthogonal projection: Instead of just clipping or weighting, project positive and negative signals onto different bases. This can be adapted for multi-task or multi-objective models where different “roles” need separate subspaces.
- Principal angle maximization as a regularizer: A concrete objective to force distinction between two representations. Useful anytime you want two features to not overlap.
论文: 2606.27372 作者: Ron Campos, Subhajit Maity, Xin Li, Srijan Das, Aritra Dutta 分类: cs.CV
缺口
现有视觉注意力机制(如ViT、DeiT、TimeSformer)都依赖标准的softmax query-key相似度。 这经常产生”弥散”的注意力图——正确物体与背景杂波或视觉上相似的干扰物共享激活。 先前的工作试图通过硬掩码、门控或辅助损失来修复,但没有直接触及根本原因:softmax操作在相关和不相关特征的相似度分数接近时,会将信号混合在一起。
作者指出真正的问题是子空间对齐——正特征(目标类别)和负特征(接近但错误)往往几乎位于同一个子空间,所以softmax无法干净地分开它们。 他们的解决方案:显式学习两个独立的查询向量(正和负),将产生的注意力交互投影到两个不同的子空间,并最大化这些子空间之间的主角度,然后通过减去负贡献来去噪最终注意力。
[逻辑拓扑:从缺口到结论]

             问题:Softmax注意力有噪声
                 |
                 v
     假设:噪声来自子空间重叠
                 |
                 v
       方法:学习正/负查询 -> 分离子空间
                 |
                 v
     证据:ImageNet 0.8%,视频Transformer 1.8%
                 |
                 v
   结论:子空间分离有助于区分性
增量
一句话: DnA之前,视觉Transformer使用单一的softmax注意力,无法干净地将目标特征与干扰物分开;DnA之后,双查询机制加子空间分离减少了噪声,提升了分类精度。
核心机制
DnA将每个注意力头中的单一查询替换为两个查询:正查询(q+)学习关注属于正确类别的特征,负查询(q-)学习关注视觉上相似但不相关的特征(干扰物)。 两个查询与相同的key-value存储(来自图像块)交互。 产生的注意力logits不直接通过softmax合并;而是分别通过两个不同的线性投影,将注意力加权的值向量映射到两个不同的子空间。 投影矩阵被学习以最大化这些子空间之间的主角度——即尽可能使两个表征正交。 最后,去噪后的输出是正子空间表征与负子空间表征的差(或学习到的组合)。
数据流:输入块 -> 自注意力key/value -> 分别用q+和q-计算注意力分数 -> 各自softmax -> 加权值 -> 通过W+和W-投影到各自的子空间 -> 计算最终输出 = f(W+ * val+ - W- * val-)。
[DnA内部ASCII图]

            输入块
                |
                v
         +-------+-------+
         |               |
      q+ (正)        q- (负)
         |               |
    注意力分数+    注意力分数-
         |               |
    softmax+         softmax-
         |               |
    加权值+          加权值-
         |               |
   [W+投影]        [W-投影]
         |               |
         +-------+-------+
                 |
       输出 = comb(proj+) - comb(proj-)
                 |
            最终特征
结构隐喻:想象你在拥挤的体育场里找一个朋友。“正查询”是你朋友的脸。“负查询”是一个穿着相似衣服的撞脸陌生人。标准注意力会给你一个两者模糊的合成图像。DnA则给你两副不同的望远镜:一副调谐到能认出你的朋友(正),另一副调谐到能认出那个撞脸的陌生人(负)。每副望远镜有不同的滤镜(子空间投影)——一个强调朋友的微表情,另一个强调陌生人不同的耳形。然后你把陌生人的图像从合成图像中减去,只留下朋友的脸。滤镜差异越大(主角度越大),最终图像越干净。
关键概念
-
正查询(q+)/ 负查询(q-) :标准注意力中,单个查询向量试图匹配所有相关内容。DnA显式学习两个独立的查询:q+被训练成”喜欢”正确类别的特征,q-被训练成”喜欢”最接近的错误特征。负查询不是随机的——它被训练去捕捉最令人困惑的干扰物。例如,在狗对狼分类中,q+会关注狗特有的特征(垂耳),而q-会关注狼共有的特征(尖耳朵、毛皮质地)——那些混淆模型的特征。
-
子空间之间的主角度:投影矩阵W+和W-定义了表征空间中的两个子空间。“主角度”是任何一个子空间中的向量与另一个子空间中向量之间的最小角度。通过最大化这个角度(使其接近90°),两个投影变得近似正交。这迫使正特征和负特征被编码在互补的维度上,使它们不会相互干扰。可以想象成将”朋友”频道和”干扰”频道放在不同的无线电频率上以避免串扰。
框架转变
之前(单一softmax注意力):              之后(DnA双查询+子空间分离):

输入 +--> Q -> 对K,V的注意力             输入 +--> Q+ -+-> 注意力+ -> 子空间+ -+
         |                                        |-> 注意力- -> 子空间- -|-->> 差
         +-> 输出(混合噪声)                    Q- -+                    |
                                                                         v
                                                                   更干净的输出
一句话: 从单查询联合注意力到双查询分离子空间差分,核心转变是模型现在显式建模了**什么不该看*,并迫使那些不想要的信号进入不同的坐标系。
专家评审
选题眼光: 真缺口。噪声注意力是softmax在视觉中的已知限制;之前的修复大多是事后处理(如剪枝、阈值)。本文攻击源头。然而,提升很小(ImageNet上0.8%),表明对于大数据集,问题可能没有那么严重。
方法成熟度: 巧劲——使用负查询和子空间分离很优雅。但工程实现(双投影加主角度正则化)增加了复杂性。一个更简单的基线是只减去负注意力权重分布(不做子空间投影)——作者应该与之比较。积极方面:该想法易于插入任何注意力层。
实验诚意: 基线合理(ViT-B)。视频上的提升(+1.8%)比ImageNet(+0.8%)更令人印象深刻,这暗示当干扰物丰富时(时间杂乱)该方法确实有用。没有重大红旗,不过论文缺少对子空间分离与仅使用两个查询的重要性的消融实验——他们有一个消融但埋得太深。此外,与其他去噪注意力(如DropKey、NoiseFilter)的比较缺失。
写作功力: 论文写得清晰,但摘要过度承诺——“绝对提升0.8%“被表述为主要结果,而社区通常期望新注意力机制有>1%的提升。论文中没有使用结构隐喻,但本来会有帮助。关于主角度计算的部分过于简略;如果有图会清楚得多。
判决: 弱接收 — 一个技术上合理但提升适度的想法。值得一读以了解双查询加子空间分离的概念,但不是突破性成果。
要点总结
- “负查询”技巧:你可以学习一个显式的”忽略什么”查询,然后减去它的影响。这个想法可以迁移到任何基于注意力的任务(NLP、图、音频)。
- 通过正交投影实现子空间分离:不是仅仅裁剪或加权,而是将正信号和负信号投影到不同的基上。这可以用于多任务或多目标模型,其中不同的”角色”需要分离的子空间。
- 主角度最大化作为正则化器:一个强制两个表征区分的具体目标函数。任何需要两个特征不重叠的场景都可用。