
Paper: 2603.14923 Authors: Kevin Taylor Categories: cs.LG, cs.AI
The Gap
Transformer research has mapped individual attention heads extensively—we know some do induction, others track syntax, some handle factual recall. But we’ve been studying the musicians while ignoring the conductor. Prior work prunes heads, analyzes their functions in isolation, or stacks more layers. The implicit assumption: computational power lives in the components themselves.
The boundary: We don’t know whether attention heads matter because of what they compute individually, or because of how they’re coordinated. Are heads irreplaceable specialists, or interchangeable parts in a larger coordination scheme?
Problem: Which matters more—components or coordination?
   |
   v
Assumption: Add lightweight coordination, measure what breaks
   |
   v
Method: Directional routing (3.9% params) + systematic ablation
   |
   v
Evidence: Router removal -> collapse / Head removal -> negligible
   |
   v
Conclusion: Coordination mechanism > Individual components
The Increment
One sentence: Before this paper, we thought attention heads were the critical computational units; after, we know the routing mechanism coordinating them is what actually matters.
Core Mechanism
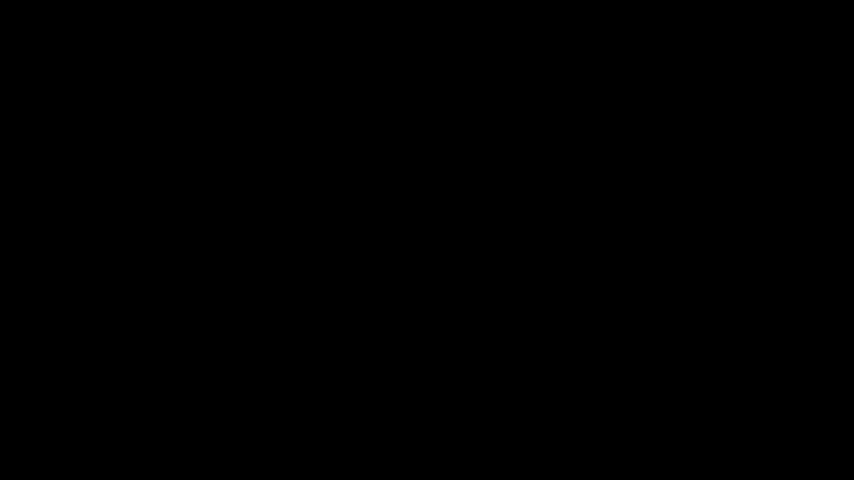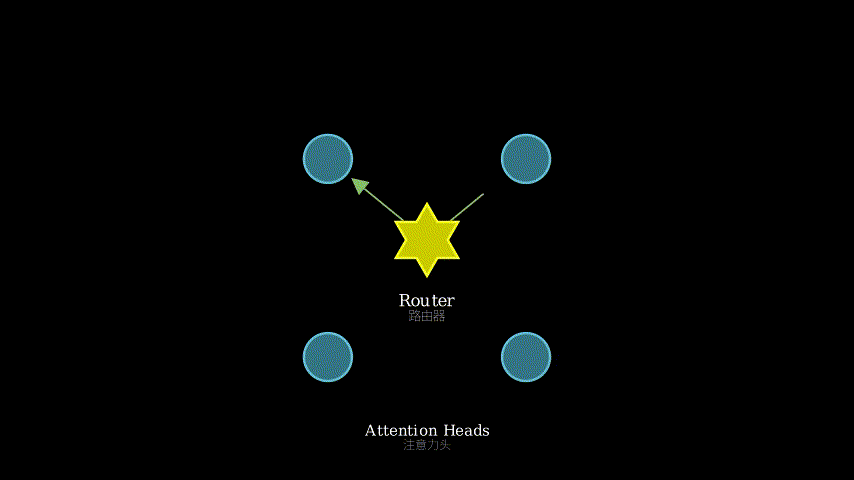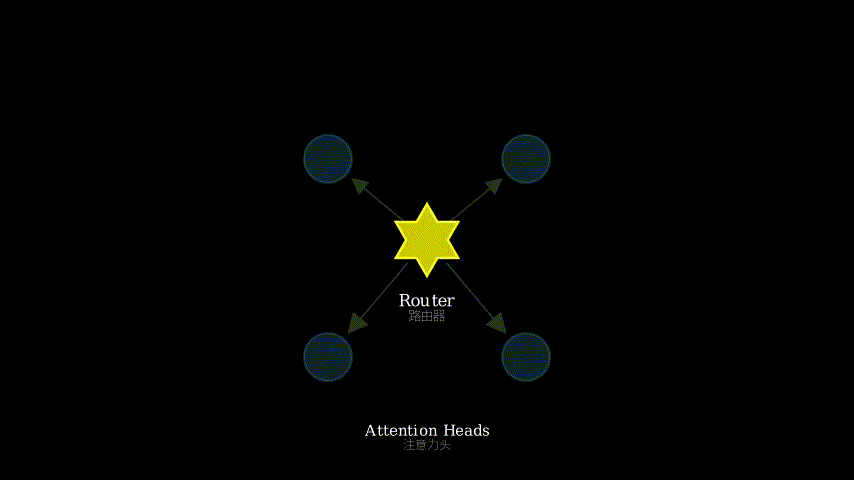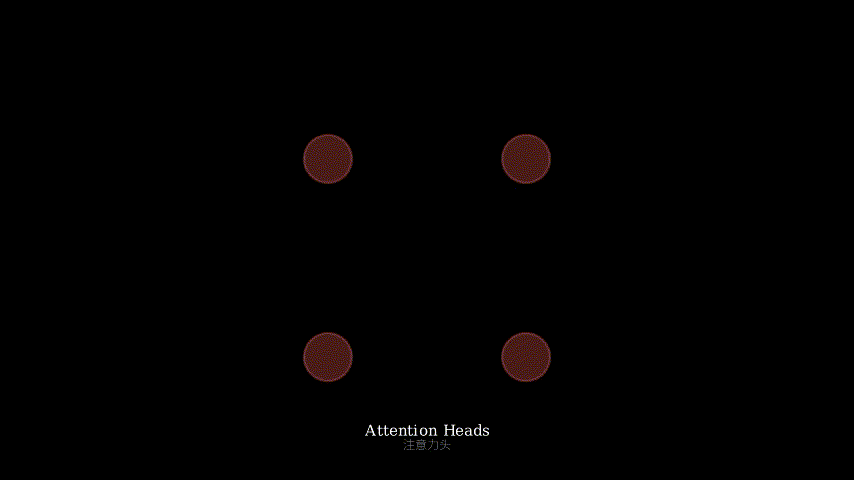
Directional routing adds two components to each attention head: learned suppression directions (vectors that specify what patterns to ignore) and a shared router that controls when these suppressions activate. The router is a single network that looks at the input and decides, for each head, whether to apply its suppression direction. Cost: 3.9% additional parameters.
Data flows like this: input → router generates suppression signals → each attention head receives its signal → heads compute attention but can suppress certain directions → outputs combine as usual. The router is shared across all heads and layers, creating a global coordination mechanism.
The authors trained a 433M-parameter model with routing alongside an identical baseline, then systematically disabled components. Disabling the router collapsed factual recall to near-zero and dropped induction accuracy from 93.4% to 0.0%. Removing individual heads—even the strongest ones—had minimal impact. One head’s removal actually improved performance.
Input sequence
      |
      v
  [Router] <--- shared across all heads
   |  |  |
   v  v  v
 [H1][H2][H3]... <--- each head gets suppression signal
   |  |  |
   +--+--+
      |
      v
   Output

Router disabled:     Head removed:
   Collapse!         Barely noticed.
Think of a traffic control system in a city. Each intersection (attention head) has traffic lights and lanes that can handle vehicles. The central traffic control system (router) coordinates all lights, deciding when to restrict flow at each intersection based on overall traffic patterns. Individual intersections can be closed for construction—traffic reroutes and the city functions. But disable the central control system, and every intersection operates independently: gridlock, accidents, chaos.
The suppression directions are like “no left turn” or “lane closed” signs that the control system can dynamically place. The router doesn’t tell intersections how to process traffic (that’s the attention mechanism’s job), it just coordinates which flows to suppress. You can replace any intersection with a different design, but without central coordination, the system collapses.
Key Concepts
-
Suppression directions: Imagine attention heads as spotlights that can illuminate different parts of the input sequence. A suppression direction is like putting a filter over the spotlight that blocks certain colors. The head still shines, but specific patterns get dimmed. Mathematically, it’s a learned vector that, when active, reduces attention weights in certain directions. Example: a head tracking subject-verb agreement might have a suppression direction that blocks attention to punctuation when the router determines punctuation isn’t relevant for the current prediction.
-
Shared router: Instead of each attention head deciding independently what to attend to, a single network observes the input and broadcasts coordination signals to all heads. It’s shared in two senses: (1) one router serves all heads, and (2) it operates across layers. This creates a global view—the router can suppress early-layer heads based on what late-layer heads will need. The router doesn’t replace attention; it modulates it.
-
Mechanistic interpretability: Rather than treating the model as a black box and only measuring outputs, the authors traced actual computational pathways—which heads activated, how information flowed, where the router intervened. They built a circuit diagram of the model’s internals. This revealed that routing became the dominant pathway: most computation flowed through router-modulated heads rather than unmodulated ones.
Framework Shift
Before (mainstream approach):        After (this paper):

[Head1] [Head2] [Head3]              [Head1] [Head2] [Head3]
   |       |       |                    ^       ^       ^
   |       |       |                    |       |       |
   +-------+-------+                    +-------+-------+
           |                                    |
        Output                             [Router]
                                                |
Each head operates                           Input
independently                                   |
                                             Output

Focus: What does each                Focus: How does coordination
head compute?                        enable computation?
From independent specialists to coordinated generalists, the core shift is: computational power emerges from coordination mechanisms, not component sophistication.
Expert Assessment
Problem choice: Real gap. The field has been in a “more layers, bigger models” phase, with interpretability work focused on cataloging head functions. Asking “what if coordination matters more than components?” is a genuine pivot. It sits at the intersection of efficiency research (how to do more with less) and interpretability (what actually matters in these models).
Method maturity: Elegant in its simplicity—3.9% parameters is cheap for the insight gained. But this feels more like a diagnostic tool than an architecture proposal. The fact that downstream benchmarks don’t improve despite 31-56% perplexity reduction suggests the routing mechanism is revealing something about transformers rather than fixing them. A more mature version would explain why perplexity and task performance diverge.
Experimental integrity: Strong ablation methodology—training routing and baseline models in a single run eliminates confounds. The honesty about downstream benchmark failures is refreshing. However, 8 test prompts for factual recall is thin. The mechanistic interpretability claims need more detail: “tracing circuits” could mean many things, and the paper doesn’t show the actual circuit diagrams. The self-organization finding (early layers adaptive, late layers fixed) is intriguing but feels under-explored.
Writing quality: The abstract packs too much into too little space—“coordination mechanism is irreplaceable; components are not” is the headline, but it’s buried. The paper would benefit from leading with the central finding and building from there. The section on self-organization into two regimes deserves expansion—this could be the more interesting result.
Verdict: Weak accept—reveals an important architectural principle (coordination > components) with honest reporting of limitations, but unclear whether this specific mechanism is the right solution or just a useful probe.
Takeaways
For architecture designers: Before adding more components, add coordination mechanisms and measure which matters more. The 3.9% parameter budget for routing is a template: lightweight coordination can outperform heavyweight components.
For interpretability researchers: Ablate mechanisms, not just components. Removing individual neurons/heads has been the standard test, but this paper shows that coordination pathways can be more critical than any individual element.
For practitioners: Perplexity improvements don’t guarantee downstream gains. The 31-56% perplexity reduction that didn’t transfer to benchmarks is a cautionary tale about proxy metrics.
Transferable technique: The “train with and without mechanism in single run” methodology eliminates training variance as a confound. Use this when comparing architectural variants.
Negative result worth remembering: Self-organization into different computational regimes (adaptive early, fixed late) happened without explicit pressure. This suggests models find their own computational strategies—designing for this might be more effective than imposing structure.
论文: 2603.14923 作者: Kevin Taylor 分类: cs.LG, cs.AI
缺口
Transformer 研究已经详尽地绘制了单个注意力头的功能图谱——我们知道有些头做归纳,有些跟踪句法,有些处理事实回忆。
但我们一直在研究乐手,却忽略了指挥。
先前的工作剪枝注意力头、孤立地分析它们的功能,或者堆叠更多层。
隐含假设:计算能力存在于组件本身。
边界问题:我们不知道注意力头重要是因为它们各自计算什么,还是因为它们如何被协调。
头是不可替代的专家,还是更大协调方案中的可互换部件?
问题:组件重要还是协调重要?
   |
   v
假设:添加轻量级协调,测量什么会崩溃
   |
   v
方法:方向路由(3.9%参数)+ 系统性消融
   |
   v
证据:移除路由器 -> 崩溃 / 移除单头 -> 可忽略
   |
   v
结论:协调机制 > 单个组件
增量
一句话: 这篇论文之前,我们认为注意力头是关键计算单元;之后,我们知道协调它们的路由机制才是真正重要的。
核心机制
方向路由为每个注意力头添加两个组件:学习到的抑制方向(指定要忽略哪些模式的向量)和一个共享路由器,控制这些抑制何时激活。
路由器是单个网络,观察输入并为每个头决定是否应用其抑制方向。
成本:额外 3.9% 参数。
数据流动方式:输入 → 路由器生成抑制信号 → 每个注意力头接收其信号 → 头计算注意力但可以抑制某些方向 → 输出照常组合。
路由器在所有头和层之间共享,创建全局协调机制。
作者训练了一个 433M 参数的带路由模型和一个相同的基线模型,然后系统性地禁用组件。
禁用路由器导致事实回忆崩溃至接近零,归纳准确率从 93.4% 降至 0.0%。
移除单个头——即使是最强的头——影响微乎其微。
一个头的移除实际上提高了性能。
输入序列
      |
      v
  [路由器] <--- 所有头共享
   |  |  |
   v  v  v
 [H1][H2][H3]... <--- 每个头获得抑制信号
   |  |  |
   +--+--+
      |
      v
   输出

路由器禁用:     单头移除:
   崩溃!         几乎没注意到。
想象一个城市的交通控制系统。
每个路口(注意力头)有红绿灯和车道可以处理车辆。
中央交通控制系统(路由器)协调所有灯,根据整体交通模式决定何时限制每个路口的流量。
单个路口可以因施工关闭——交通改道,城市继续运转。
但禁用中央控制系统,每个路口独立运作:交通堵塞、事故、混乱。
抑制方向就像”禁止左转”或”车道关闭”标志,控制系统可以动态放置。
路由器不告诉路口如何处理交通(那是注意力机制的工作),它只是协调要抑制哪些流量。
你可以用不同设计替换任何路口,但没有中央协调,系统就会崩溃。
关键概念
- 抑制方向: 想象注意力头是可以照亮输入序列不同部分的聚光灯。
抑制方向就像在聚光灯上放一个滤镜,阻挡某些颜色。
头仍然发光,但特定模式被调暗。
数学上,它是一个学习到的向量,激活时会降低某些方向的注意力权重。
例子:跟踪主谓一致的头可能有一个抑制方向,当路由器确定标点符号与当前预测无关时,阻止对标点符号的注意力。
- 共享路由器: 不是每个注意力头独立决定关注什么,而是单个网络观察输入并向所有头广播协调信号。
它在两个意义上是共享的:(1) 一个路由器服务所有头,(2) 它跨层操作。
这创建了全局视图——路由器可以根据后层头的需求抑制早层头。
路由器不替代注意力;它调节注意力。
- 机制可解释性: 不是将模型视为黑盒只测量输出,作者追踪了实际的计算路径——哪些头激活了、信息如何流动、路由器在哪里干预。
他们构建了模型内部的电路图。
这揭示了路由成为主导路径:大部分计算通过路由器调节的头流动,而不是未调节的头。
框架转变
之前(主流方法):              之后(本文方法):

[头1] [头2] [头3]              [头1] [头2] [头3]
   |     |     |                  ^     ^     ^
   |     |     |                  |     |     |
   +-----+-----+                  +-----+-----+
         |                              |
      输出                          [路由器]
                                        |
每个头独立运作                        输入
                                        |
                                      输出

焦点:每个头计算什么?          焦点:协调如何实现计算?
从独立专家到协调通才,核心转变是:计算能力来自协调机制,而非组件复杂度。
专家评审
选题眼光: 真实缺口。
该领域一直处于”更多层、更大模型”阶段,可解释性工作专注于编目头功能。
提出”如果协调比组件更重要呢?“是真正的转向。
它位于效率研究(如何用更少做更多)和可解释性(这些模型中什么真正重要)的交叉点。
方法成熟度: 简洁优雅——3.9% 参数对于获得的洞见来说很便宜。
但这感觉更像诊断工具而非架构提案。
尽管困惑度降低 31-56%,下游基准测试没有改善,这表明路由机制揭示了关于 transformer 的某些东西,而不是修复它们。
更成熟的版本会解释为什么困惑度和任务性能会分离。
实验诚意: 强大的消融方法论——在单次运行中训练路由和基线模型消除了混淆因素。
对下游基准测试失败的坦诚令人耳目一新。
然而,8 个测试提示用于事实回忆太少。
机制可解释性声明需要更多细节:“追踪电路”可能意味着很多事情,论文没有展示实际的电路图。
自组织发现(早层自适应,晚层固定)很有趣但感觉探索不足。
写作功力: 摘要在太小的空间里塞了太多东西——“协调机制不可替代;组件可以替代”是标题,但被埋没了。
论文应该从中心发现开始并从那里构建。
关于自组织成两种机制的部分值得扩展——这可能是更有趣的结果。
判决: 弱接收——揭示了重要的架构原则(协调 > 组件),诚实报告局限性,但不清楚这个特定机制是正确的解决方案还是只是有用的探针。
要点总结
对架构设计者: 在添加更多组件之前,添加协调机制并测量哪个更重要。
路由的 3.9% 参数预算是一个模板:轻量级协调可以胜过重量级组件。
对可解释性研究者: 消融机制,不仅仅是组件。
移除单个神经元/头一直是标准测试,但本文表明协调路径可能比任何单个元素更关键。
对实践者: 困惑度改善不保证下游收益。
31-56% 的困惑度降低没有转移到基准测试是关于代理指标的警示故事。
可迁移技术: “在单次运行中训练有无机制”方法论消除了训练方差作为混淆因素。
比较架构变体时使用这个。
值得记住的负面结果: 自组织成不同计算机制(早期自适应,晚期固定)在没有明确压力的情况下发生。
这表明模型找到自己的计算策略——为此设计可能比强加结构更有效。