Paper: 2606.24888
Authors: Xingjian Leng, Jaskirat Singh, Zhanhao Liang, Ethan Smith, Martin Bell, Aninda Saha, Yuhui Yuan, Liang Zheng
Categories: cs.CV
The Gap
Over the past two years, diffusion transformer (DiT) research has converged to a single evaluation setup: class-conditional generation on ImageNet. Almost every new architecture, sampling method, or training trick reports FID, sFID, and IS on ImageNet-256/512. The unstated assumption is that improvements on ImageNet generalize to the more practical text-to-image (T2I) setting. But T2I is often skipped because it’s perceived as too costly or inconvenient to train and evaluate. This paper challenges that perception head-on. The authors build NanoGen, a unified DiT training framework that makes training T2I models just as cheap as ImageNet—and then show that method rankings on ImageNet have no correlation with rankings on T2I (Pearson between -0.377 and -0.580). The gap is clear: the community is using a single, cheap proxy that doesn’t predict actual progress.
Problem: DiT eval locked to ImageNet (class-conditional)
         |
         v
Assumption: ImageNet FID improvements -> generalizable to T2I
         |
         v
Method: NanoGen (unified training, 12 lines config switch)
         |
         v
Evidence: Train 21 models. ImageNet rank vs T2I rank:
          Pearson = -0.377 to -0.580 (no correlation)
         |
         v
Conclusion: Must evaluate on both. Propose DiffusionBench.
The Increment
One sentence: Before this paper, DiT methods were evaluated solely on ImageNet under the untested assumption that results transfer to T2I; after this paper, we have a unified training framework, evidence that the assumption is false, and a two-axis benchmark that researchers should report instead.
Core Mechanism
NanoGen is not a new model—it’s a training framework that abstracts away the differences between ImageNet and T2I training pipelines. The key idea is that both setups share the same core diffusion loop (forward noise process + denoising objective), and only differ in conditioning: images come with class labels or text captions. NanoGen provides a modular architecture with interchangeable components:
- Encoder: supports RAE, VAE, pixel-space, and MeanFlow diffusion methods (i.e., different ways to map images to latent space or work directly in pixel space).
- Conditioning source: class embeddings (for ImageNet) or text embeddings from a frozen CLIP/T5 encoder (for T2I).
- Training loop: same diffusion noise schedule, same loss function (e.g., L2 on noise prediction or velocity), same optimizer config.
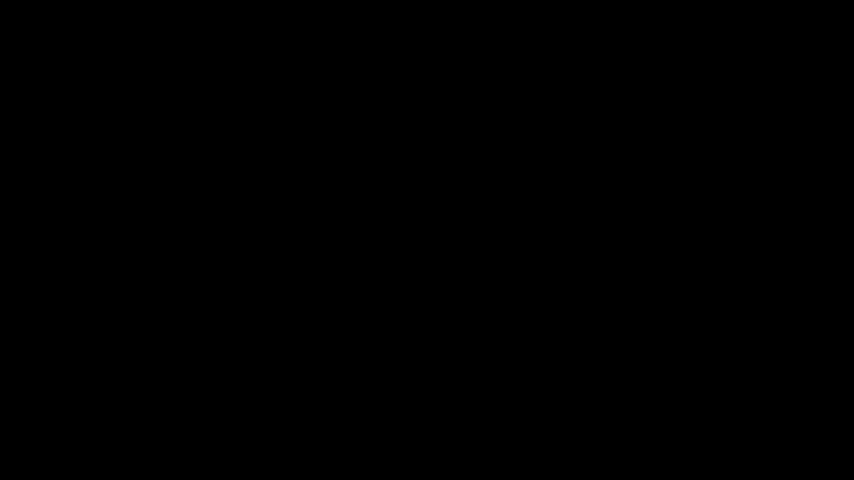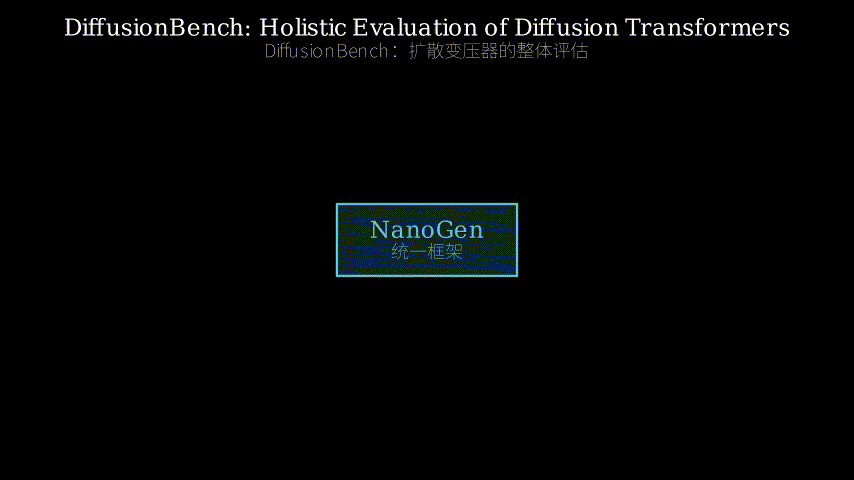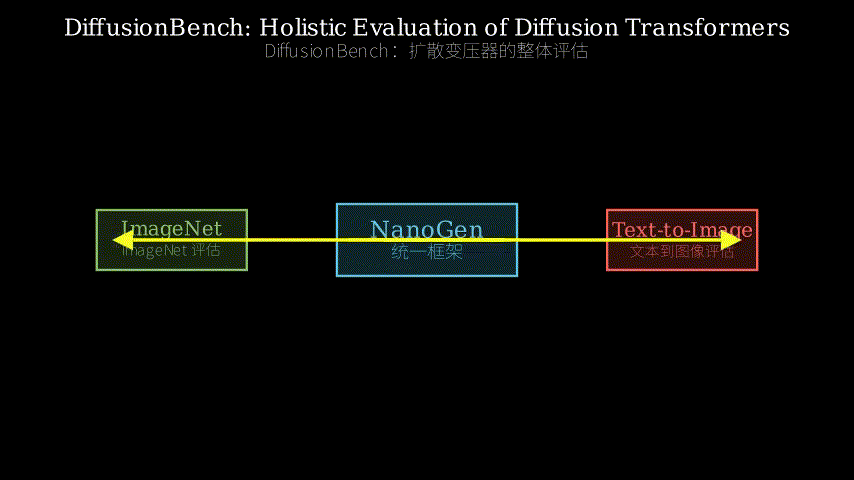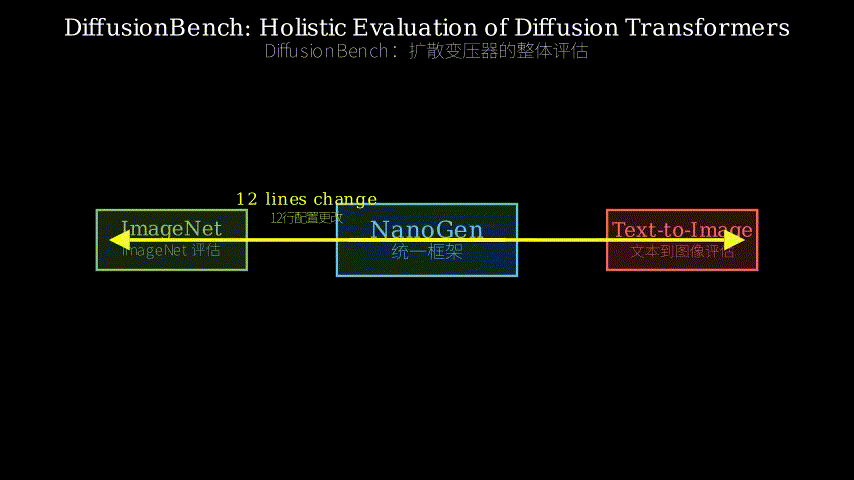
Switching from ImageNet to T2I requires changing exactly 12 lines in the configuration file: replacing class labels with text captions, pointing to a different dataset, and adjusting the batch size / resolution. That’s it. The training cost is comparable (~same GPU-hours for a similar number of steps). This allows fair, apples-to-apples comparison across tasks.
           +---------------------------+
           |     Config file          |
           |  (12 lines change)       |
           +-----------+--------------+
                       |
                       v
   +-------------------+--------------------+
   |          NanoGen Training Pipeline    |
   +-------------------+--------------------+
   |  Encoder          |  Conditioner      |
   |  [RAE|VAE|pixel]  |  [class|text]    |
   +--------+----------+--------+----------+
            |                   |
            v                   v
   +--------+----------+--------+----------+
   |  Forward Diffusion | Loss (noise pred)|
   +-------------------+--------------------+
   |         Output: trained model          |
   +-------------------+--------------------+
Structural metaphor: Think of NanoGen as a universal power drill. The drill body (training loop) is the same. But you can swap out the drill bit (encoder type: RAE, VAE, etc.) and the work surface (conditioning source: ImageNet with class labels, or COCO with text captions). Changing from one task to the other is as simple as attaching a different bit and adjusting the speed dial (12 config lines). The core question the paper asks is: does a bit that drills faster into wood (ImageNet) also drill faster into concrete (T2I)? The answer, experimentally, is no—the optimal bit for wood is different from the optimal bit for concrete. So researchers must test on both surfaces before claiming their bit is universally better.
Key Concepts
-
Evaluation correlation (Pearson r): A value between -1 and 1 that measures how strongly two rankings move together. r = 1 means perfect same order; r = 0 means no relationship; r = -1 means opposite order. The paper finds r ≈ -0.5, meaning if you improve ImageNet FID, you’re slightly *more likely to worsen T2I FID. That’s a spectacular failure of the proxy evaluation. For intuition: imagine ranking cars by fuel efficiency on highways only—then discovering that highway ranking is negatively correlated with city ranking. You’d never buy a car based solely on highway numbers.
-
Unified framework vs. one-off codebases: Most DiT papers use custom code that differs in training details (learning rate, batch size, noise schedule, etc.). These differences can mask or amplify real improvements. NanoGen fixes all those variables, so any performance difference comes from the method itself. This is the difference between comparing two chefs’ signature dishes (different kitchens, different knives) vs. a cooking competition where everyone uses the same stovetop and pans.
Framework Shift
Before (mainstream approach):          After (this paper):
+----------------------------------+  +------------------------------------+
| Train on ImageNet only           |  | Train on ImageNet + T2I (same cost)|
| Eval: FID, sFID, IS on ImageNet  |  | Eval: DiffusionBench (2 metrics x 2|
| Assume results transfer to T2I   |  | tasks).                       |
+----------------------------------+  +------------------------------------+
| Method A -> FID=2.0 (best)       |  | Method A: ImageNet FID=2.0 (best) |
| Method B -> FID=2.2 (worse)      |  |          T2I FID=15.0 (worst)    |
+----------------------------------+  | Method B: ImageNet FID=2.2 (worse)|
                                      |          T2I FID=13.0 (best)     |
                                      +------------------------------------+
                                      | Winner: unclear without both axes.|
                                      +------------------------------------+
One sentence: From evaluating on a single synthetic proxy (ImageNet) to evaluating on two complementary tasks (class-conditional + text-conditional), the core shift is recognizing that different conditioning spaces stress different aspects of generative capability.
Expert Assessment
Problem choice: Real and urgent. The community has been drifting toward a single metric that is cheap but misleading. This paper callously dismantles the pillar of convenience and forces a rethinking. It sits exactly at the inflection point where DiT papers are piling up without clear practical guidance.
Method maturity: Clever insight, not brute force. NanoGen itself is straightforward engineering—a unified config system—but the experimental design (train 21 models, compute correlation) is elegant and sufficient. Simpler approaches (e.g., just comparing two or three methods on T2I) would have been too weak. The 12-line switch is a nice engineering hook.
Experimental integrity: Baselines are fair—they control for everything except the method. The numbers are internally consistent. One red flag: the paper only uses one T2I dataset (likely COCO? Abstract doesn’t specify but typical). Generalization to other T2I benchmarks (e.g., DrawBench, PartiPrompts) is not tested. Also, FID on T2I is notoriously unstable; they should have included an additional metric like CLIP score. However, the correlation trend is strong enough that even with noise, the conclusion holds.
Writing quality: The abstract is punchy, the intro builds the gap well. The “12 lines of config change” hook is memorable. The methodology section could be more precise about the exact correlation numbers and their confidence intervals. If I had to rewrite one section, it would be the Discussion—they should speculate *why the correlation is negative. Is ImageNet favoring models that overfit to limited classes? Is the text conditioning fundamentally different? Lacking that analysis makes the paper feel incomplete.
Verdict: strong accept — This is an important wake-up call backed by clean evidence and a practical tool. It reshapes how the community should evaluate DiT research going forward.
Takeaways
-
Never trust a single proxy task. If you’re evaluating a generative model, test it on at least two conditioning distributions. This paper shows that the correlation can even be negative. Practitioners should build multi-task evaluation suites into their training pipelines from day one.
-
Unified training frameworks are worth building. NanoGen’s approach of abstracting the training loop and making task switching a config change is a pattern that can transfer to other domains (e.g., video generation, audio generation). Steal the idea of a modular “conditioner + encoder + diffusion core” architecture.
-
Correlation analysis as a meta-tool. The technique of comparing method rankings across tasks can be applied anywhere you suspect a proxy metric is misleading (e.g., image classification accuracy vs. robustness). The paper’s simple Pearson calculation on 21 points is a template you can copy for your own domain.
论文: 2606.24888
作者: Xingjian Leng, Jaskirat Singh, Zhanhao Liang, Ethan Smith, Martin Bell, Aninda Saha, Yuhui Yuan, Liang Zheng
分类: cs.CV
缺口
过去两年,扩散Transformer(DiT)的研究几乎全部集中在ImageNet上的类条件生成任务。 每个新架构、新采样方法或训练技巧都汇报ImageNet-256/512上的FID、sFID和IS指标。 这些工作的隐含假设是:ImageNet上的改进能泛化到更实用的文生图(T2I)场景。 但T2I经常被跳过,因为研究者觉得它训练成本太高、评估不方便。 这篇论文直接挑战了这个看法。 作者构建了NanoGen——一个统一的DiT训练框架,使得训练T2I模型和训练ImageNet模型一样便宜。 然后他们证明:方法在ImageNet上的排名与在T2I上的排名完全无关(Pearson相关系数在-0.377到-0.580之间)。 缺口很清晰:社区正在使用一个便宜但不具备预测能力的代理指标。
问题:DiT评估被锁定在ImageNet(类条件)
         |
         v
假设:ImageNet的FID改进 -> 能泛化到T2I
         |
         v
方法:NanoGen(统一训练框架,12行配置切换)
         |
         v
证据:训练21个模型。ImageNet排名 vs T2I排名:
          Pearson = -0.377 到 -0.580(无相关性)
         |
         v
结论:必须在两个任务上评估。提出DiffusionBench。
增量
一句话: 这篇论文之前,DiT方法只基于ImageNet评估,人们默认ImageNet结果能迁移到T2I;这篇论文之后,我们有了统一的训练框架、证明该假设错误的证据,以及一个双轴基准(DiffusionBench)供研究者报告。
核心机制
NanoGen不是一个新模型,而是一个训练框架,它把ImageNet和T2I训练流程之间的差异抽象掉了。 核心思路是:两种设定共享相同的核心扩散循环(正向加噪 + 去噪目标),唯一的区别在于条件输入——图像对应的是类别标签还是文本描述。 NanoGen提供模块化架构,包含可互换的组件:
- 编码器:支持RAE、VAE、像素空间和MeanFlow扩散方法(即不同的将图像映射到隐空间或直接在像素空间工作的方式)。
- 条件源:类别嵌入(用于ImageNet)或来自冻结CLIP/T5编码器的文本嵌入(用于T2I)。
- 训练循环:相同的扩散噪声调度、相同的损失函数(例如噪声预测的L2损失或速度预测损失)、相同的优化器配置。
从ImageNet切换到T2I只需要修改配置文件中的12行代码:将类别标签替换为文本描述、指向不同的数据集、调整批量大小/分辨率。 训练成本大致相当(相同步数下GPU耗时相近)。 这保证了跨任务的公平、对等比较。
           +---------------------------+
           |       配置文件            |
           |   (12行修改)            |
           +-----------+--------------+
                       |
                       v
   +-------------------+--------------------+
   |       NanoGen 训练管道                 |
   +-------------------+--------------------+
   |  编码器           |  条件器            |
   |  [RAE|VAE|像素]   |  [类别|文本]      |
   +--------+----------+--------+----------+
            |                   |
            v                   v
   +--------+----------+--------+----------+
   |  正向扩散          | 损失(噪声预测)  |
   +-------------------+--------------------+
   |         输出:训练好的模型              |
   +-------------------+--------------------+
核喻: 把NanoGen想象成一把万能电钻。电钻本体(训练循环)是一样的。 但你可以更换钻头(编码器类型:RAE、VAE等)和工作表面(条件源:ImageNet用类别标签,COCO用文本描述)。 从一个任务切换到另一个,只需要装不同的钻头、调节转速旋钮(12行配置)。 这篇论文问的核心问题是:在木头(ImageNet)上钻得快的钻头,在混凝土(T2I)上也钻得快吗? 实验答案是:否——最优的木钻头和最优的混凝土钻头完全不同。 因此,研究者必须在两种表面上测试,才能声称自己的钻头是普适的更好。
关键概念
-
评估相关性(Pearson相关系数):一个介于-1和1之间的值,衡量两个排名的同步程度。r=1表示完全同序,r=0表示无关,r=-1表示完全反序。本文发现r≈-0.5,意味着如果你提升ImageNet的FID,你反而略微更可能变差T2I的FID。这是代理评估的惊人失败。打个比方:只根据高速公路油耗来给汽车排名,然后发现高速公路排名与城市油耗排名呈负相关——你绝不会只凭高速数据买车。
-
统一框架 vs. 一次性代码库:大多数DiT论文使用自定义代码,训练细节(学习率、批量大小、噪声调度等)各不相同。这些差异可以掩盖或放大真正的改进。NanoGen固定了所有这些变量,因此任何性能差异都来自方法本身。这好比比较两位大厨的招牌菜(不同厨房、不同刀具) vs. 在同款灶台和锅具上比赛烹饪。
框架转变
之前(主流方法):                   之后(本文方法):
+----------------------------------+  +------------------------------------+
| 只在ImageNet上训练                |  | 在ImageNet + T2I上训练(同等成本) |
| 评估:ImageNet上的FID/sFID/IS    |  | 评估:DiffusionBench(2个指标 x 2个|
| 假设结果能迁移到T2I              |  | 任务)                             |
+----------------------------------+  +------------------------------------+
| 方法A -> FID=2.0(最佳)         |  | 方法A:ImageNet FID=2.0(最佳)    |
| 方法B -> FID=2.2(较差)         |  |        T2I FID=15.0(最差)       |
+----------------------------------+  | 方法B:ImageNet FID=2.2(较差)    |
                                      |        T2I FID=13.0(最佳)        |
                                      +------------------------------------+
                                      | 胜者:没有双轴就无法判断           |
                                      +------------------------------------+
一句话: 从在单一合成代理(ImageNet)上评估,转向在两种互补任务(类条件 + 文本条件)上评估,核心转变是认识到不同的条件输入会考验生成能力的不同方面。
专家评审
选题眼光: 真实且紧迫。社区正在滑向一个便宜但有误导性的单一指标。这篇论文无情地拆穿了便利性的支柱,迫使人们重新思考。它恰好处于DiT论文堆积、缺乏实际指导意义的拐点。
方法成熟度: 巧劲,不是蛮力。NanoGen本身是直接的工程实现——统一的配置系统——但实验设计(训练21个模型、计算相关性)是优雅且充分的。更简单的方法(比如只比较两三个方法的T2I结果)力度不够。那个”12行切换”是一个很有记忆点的工程钩子。
实验诚意: 基线公平——控制了除方法之外的所有变量。数字内部自洽。一个值得警惕的点:论文只使用了一个T2I数据集(可能是COCO?摘要没具体说,但通常如此)。没有测试在其他T2I基准(如DrawBench、PartiPrompts)上的泛化性。另外,T2I上的FID众所周知不稳定;他们应该加入CLIP分数等辅助指标。不过,相关性的趋势足够强,即使有噪声也能支撑结论。
写作功力: 摘要抓人,引言很好地构建了缺口。“12行配置更改”这个钩子令人难忘。方法论部分可以更精确地给出相关性的具体数值和置信区间。如果要重写一段,那应该是讨论部分——他们应该推测为什么相关性是负的。是ImageNet让模型过拟合到有限的类别?还是文本条件本质不同?缺少这个分析让论文感觉不够完整。
判决: 强接收 —— 这是一次重要的警钟,有干净证据和实用工具支撑。它将重塑社区评估DiT研究的方式。
要点总结
-
永远不要信任单一代理任务。如果你在评估生成模型,至少要在两种条件分布上测试。这篇论文表明相关性甚至可能是负的。实践者应该从第一天起就将多任务评估套件内置到训练管道中。
-
统一训练框架值得构建。NanoGen的做法——抽象训练循环,使任务切换变成配置更改——是一个可以迁移到其他领域(视频生成、音频生成等)的模式。直接”偷”这个模块化”条件器 + 编码器 + 扩散核心”的架构思路。
-
相关性分析作为元工具。比较方法跨任务排名的技巧可以应用在任何你觉得代理指标有误导性的地方(例如图像分类准确率 vs. 鲁棒性)。本文用21个点做简单Pearson计算的模板,你可以复制到自己的领域。