Paper: 2602.23336 Authors: Camilo Gomez, Pengyang Wang, Liansheng Tang Categories: cs.LG, stat.ML
Abstract
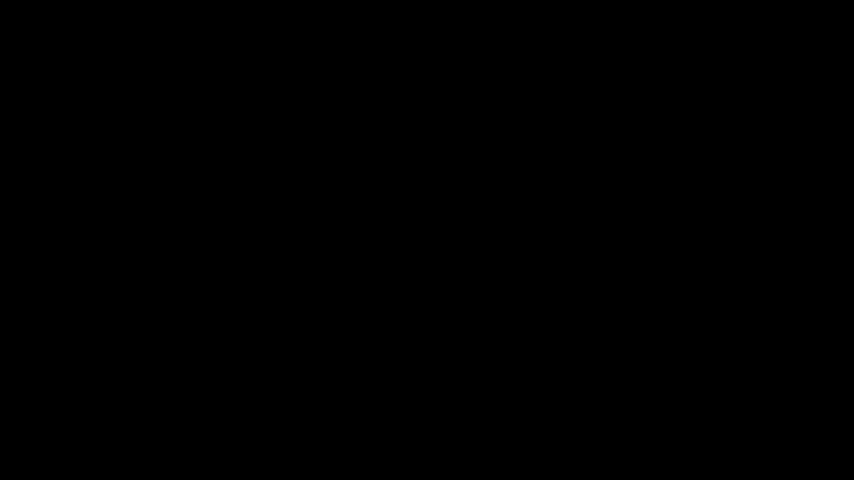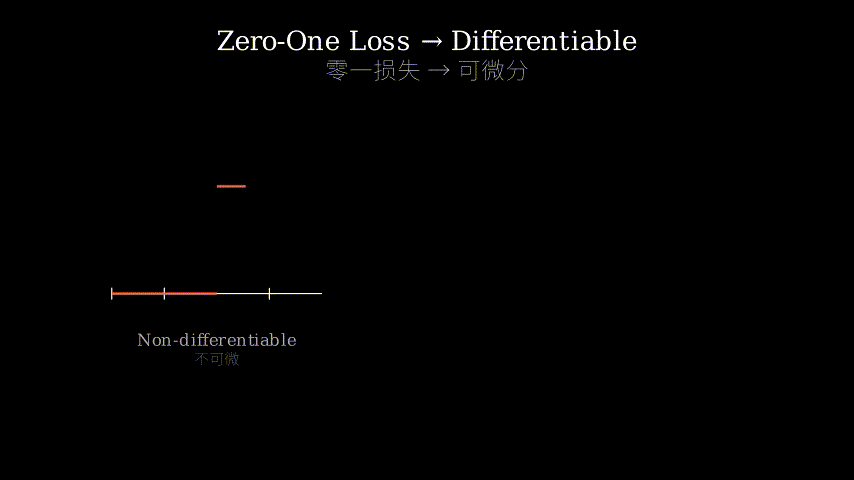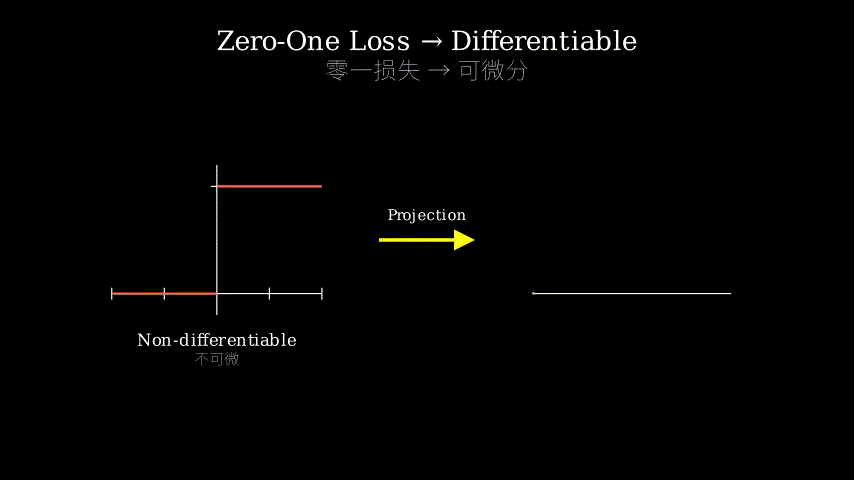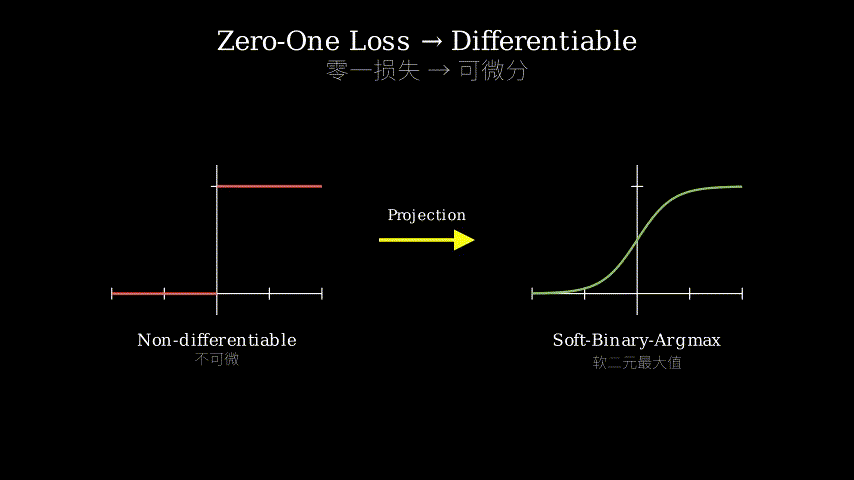
This paper introduces a differentiable approximation to the zero-one loss function, addressing a fundamental challenge in classification tasks. While the zero-one loss directly measures classification accuracy, its non-differentiability has made it incompatible with gradient-based optimization methods. The authors propose a novel approach using smooth projections onto the -dimensional hypersimplex, creating a new operator called Soft-Binary-Argmax. This method enables end-to-end differentiable training while maintaining order-preserving properties. Experimental results demonstrate significant improvements in generalization performance, particularly under large-batch training scenarios where traditional methods typically suffer from performance degradation.
Key Contributions
- Introduction of a differentiable approximation to the zero-one loss through hypersimplex projections
- Development of the Soft-Binary-Argmax operator with proven mathematical properties and efficient Jacobian computation
- A constrained optimization framework that constructs smooth, order-preserving projections
- Demonstration of improved generalization under large-batch training by imposing geometric consistency constraints on output logits
- Integration methodology for both binary and multiclass classification systems
Methodology: Hypersimplex Projections
The core innovation lies in constructing a smooth projection onto the hypersimplex , defined as:
Traditional classification uses the argmax operation, which is non-differentiable. The authors replace this with a constrained optimization problem that projects logits onto the hypersimplex while preserving ordering relationships. The Soft-Binary-Argmax operator emerges from solving:
where represents the input logits. This formulation maintains differentiability while approximating the discrete nature of classification decisions. The projection is computed efficiently using dual optimization techniques, and the resulting Jacobian can be derived analytically, enabling seamless integration into backpropagation frameworks.
The order-preserving property ensures that if logit , then the projected value , maintaining the ranking structure essential for classification tasks.
Large-Batch Training and Geometric Consistency
A significant empirical contribution addresses the well-known generalization gap in large-batch training. When batch sizes increase, neural networks often exhibit degraded test performance despite achieving similar training accuracy. The authors demonstrate that their hypersimplex projection imposes geometric consistency constraints on the output space.
By constraining predictions to lie on the hypersimplex, the model’s output geometry becomes more structured. This regularization effect prevents the optimizer from exploiting batch-specific patterns that don’t generalize. The geometric constraints act as an implicit regularizer, similar to how batch normalization or weight decay improve generalization, but operating directly on the prediction space.
Experimental results show that models trained with the Soft-Binary-Argmax operator maintain performance across varying batch sizes, effectively narrowing the gap between small-batch and large-batch training regimes. This has practical implications for distributed training and scenarios where computational efficiency demands larger batches.
Theoretical Properties and Computational Efficiency
The paper provides rigorous mathematical analysis of the Soft-Binary-Argmax operator. Key theoretical results include:
- Smoothness: The projection operator is continuously differentiable, enabling gradient flow
- Order preservation: Maintains ranking relationships from input logits to projected outputs
- Convexity: The underlying optimization problem is convex, guaranteeing unique solutions
- Lipschitz continuity: Bounded sensitivity to input perturbations, ensuring training stability
Computational efficiency is achieved through specialized algorithms for hypersimplex projection. Rather than solving a general quadratic program, the authors exploit the structure of to derive closed-form solutions for the dual problem. The Jacobian computation leverages implicit differentiation, avoiding expensive second-order operations.
The overall computational overhead is comparable to standard softmax operations, making the approach practical for large-scale applications. Integration into existing frameworks requires minimal code changes, as the operator can be implemented as a differentiable layer.
Takeaways
- The zero-one loss can be approximated in a differentiable manner through hypersimplex projections, bridging the gap between discrete classification objectives and continuous optimization
- The Soft-Binary-Argmax operator provides a principled alternative to softmax with provable mathematical properties including smoothness and order preservation
- Geometric consistency constraints imposed by hypersimplex projections significantly improve generalization in large-batch training scenarios
- The method achieves computational efficiency comparable to standard operations while providing theoretical guarantees on convergence and stability
- This work demonstrates how structured optimization components can be integrated into end-to-end learning systems to better align with task-specific objectives
论文: 2602.23336 作者: Camilo Gomez, Pengyang Wang, Liansheng Tang 分类: cs.LG, stat.ML
摘要
本文提出了零一损失函数的可微分近似方法,解决了分类任务中的一个基本挑战。虽然零一损失直接衡量分类准确率,但其不可微性使其无法与基于梯度的优化方法兼容。作者提出了一种新颖的方法,通过对维超单纯形进行平滑投影,创建了一个称为Soft-Binary-Argmax的新算子。该方法在保持保序性质的同时实现了端到端可微分训练。实验结果表明,该方法在大批量训练场景下显著改善了泛化性能,而传统方法在这种场景下通常会出现性能下降。
主要贡献
- 通过超单纯形投影引入零一损失的可微分近似
- 开发了具有严格数学性质和高效雅可比计算的Soft-Binary-Argmax算子
- 构建了平滑保序投影的约束优化框架
- 通过对输出logits施加几何一致性约束,证明了在大批量训练下泛化能力的改善
- 提供了适用于二分类和多分类系统的集成方法
方法论:超单纯形投影
核心创新在于构造对超单纯形的平滑投影,其定义为:
传统分类使用argmax操作,但它是不可微的。作者用约束优化问题替代它,将logits投影到超单纯形上同时保持排序关系。Soft-Binary-Argmax算子源于求解:
其中表示输入logits。这种形式在近似分类决策的离散性质的同时保持了可微性。投影通过对偶优化技术高效计算,得到的雅可比矩阵可以解析推导,使其能够无缝集成到反向传播框架中。
保序性质确保如果logit ,则投影值,保持了分类任务所需的排序结构。
大批量训练与几何一致性
一个重要的实证贡献解决了大批量训练中众所周知的泛化差距问题。当批量大小增加时,神经网络尽管达到相似的训练准确率,但测试性能往往下降。作者证明他们的超单纯形投影对输出空间施加了几何一致性约束。
通过约束预测位于超单纯形上,模型的输出几何结构变得更加规整。这种正则化效应防止优化器利用不能泛化的批次特定模式。几何约束充当隐式正则化器,类似于批归一化或权重衰减改善泛化的方式,但直接作用于预测空间。
实验结果表明,使用Soft-Binary-Argmax算子训练的模型在不同批量大小下保持性能,有效缩小了小批量和大批量训练机制之间的差距。这对分布式训练和计算效率要求更大批量的场景具有实际意义。
理论性质与计算效率
论文对Soft-Binary-Argmax算子进行了严格的数学分析。关键理论结果包括:
- 平滑性: 投影算子连续可微,支持梯度流动
- 保序性: 保持从输入logits到投影输出的排序关系
- 凸性: 底层优化问题是凸的,保证唯一解
- Lipschitz连续性: 对输入扰动的敏感性有界,确保训练稳定性
计算效率通过超单纯形投影的专用算法实现。作者没有求解通用二次规划,而是利用的结构推导对偶问题的闭式解。雅可比计算利用隐式微分,避免了昂贵的二阶运算。
整体计算开销与标准softmax操作相当,使该方法适用于大规模应用。集成到现有框架只需最少的代码更改,因为该算子可以实现为可微分层。
要点总结
- 零一损失可以通过超单纯形投影以可微分方式近似,在离散分类目标和连续优化之间架起桥梁
- Soft-Binary-Argmax算子提供了softmax的原则性替代方案,具有可证明的数学性质,包括平滑性和保序性
- 超单纯形投影施加的几何一致性约束显著改善了大批量训练场景下的泛化能力
- 该方法在提供收敛性和稳定性理论保证的同时,实现了与标准操作相当的计算效率
- 这项工作展示了如何将结构化优化组件集成到端到端学习系统中,以更好地与任务特定目标对齐