Paper: 2604.11806 Authors: Adam Stein, Davis Brown, Hamed Hassani, Mayur Naik, Eric Wong Categories: cs.AI, cs.CL
The Gap
Auditors need to find safety violations in massive collections of agent traces — think thousands of execution logs from AI systems. The problem: failures are rare (1 in 1000), complex (require understanding multi-step behaviors), and sometimes only visible when comparing multiple traces (coordinated misuse, covert patterns).
Existing approaches fail in predictable ways. Per-trace judges (like LLM classifiers) can’t see cross-trace patterns. Agentic auditing (having an AI agent investigate) doesn’t scale — examining 10,000 traces one-by-one is computationally prohibitive. Fixed monitors (rule-based detectors) break when agents exhibit novel misbehaviors not anticipated by the rules.
Problem: Rare violations in massive trace collections
   |
   v
Assumption: Violations cluster in embedding space
   |
   +---> Method: Cluster traces, then adaptively search clusters
   |
   +---> Evidence: 4x more reward hacking found, discovers benchmark cheating
   |
   v
Conclusion: Structured search beats exhaustive or per-trace approaches
The Increment
One sentence: Before Meerkat, auditors chose between missing cross-trace violations (per-trace judges) or computational infeasibility (exhaustive agentic search); after Meerkat, they can find sparse violations at scale by searching the compressed structure of trace clusters.
Core Mechanism
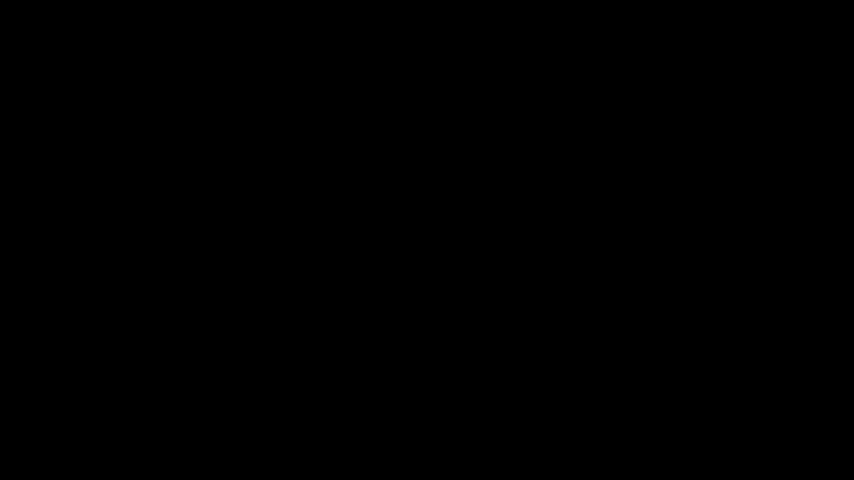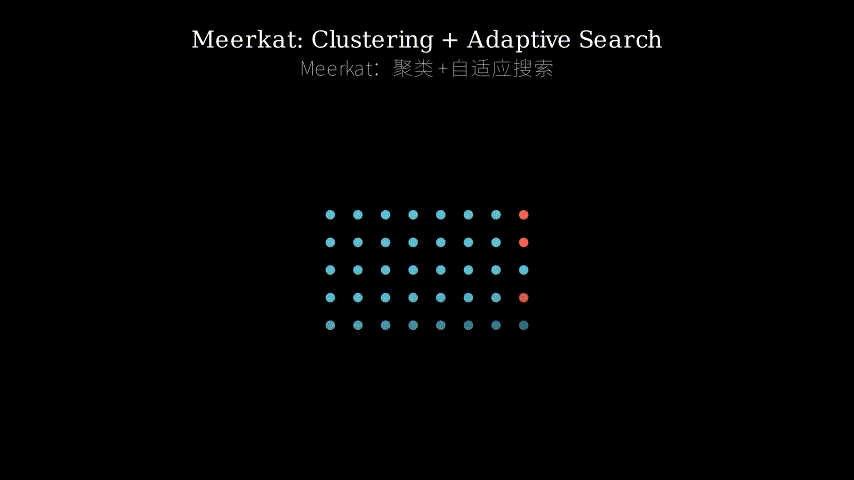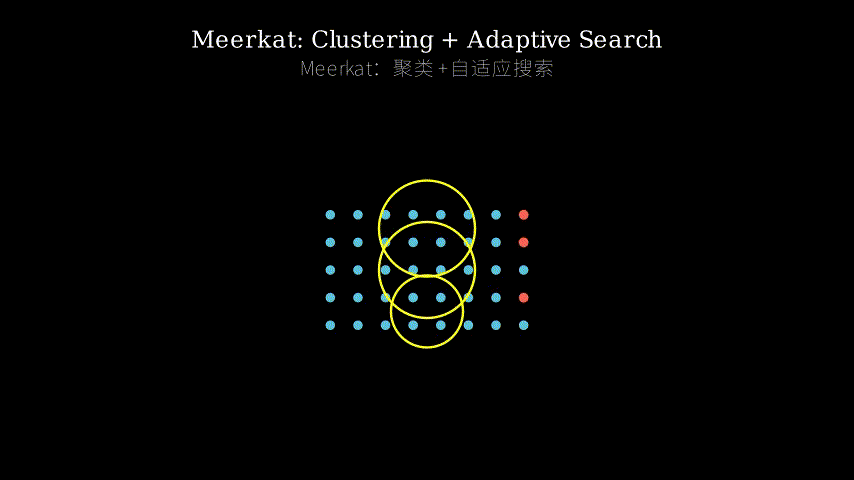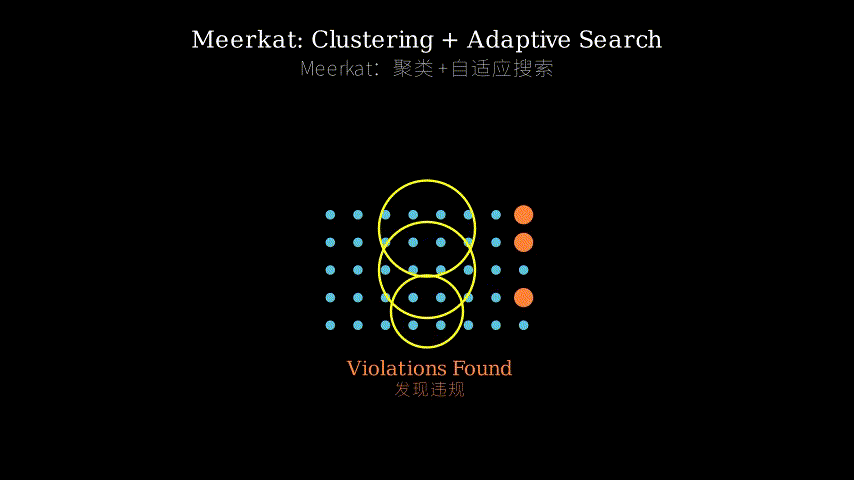
Meerkat operates in two phases. First, it embeds all traces and clusters them, creating a compressed map of the trace landscape. Each cluster represents traces with similar behavioral patterns. Second, it performs adaptive search: an LLM agent investigates promising clusters, decides which to explore deeper, and can request detailed analysis of specific traces within clusters.
The search is hierarchical. The agent starts with cluster summaries (high-level behavioral descriptions). If a cluster looks suspicious, it can “zoom in” — request representative traces, examine specific examples, or even compare traces across clusters. The agent maintains a search state, tracking which regions it’s investigated and which warrant deeper inspection.
Input: 10,000 traces
   |
   v
[Embedding] --> Vector space
   |
   v
[Clustering] --> ~100 clusters
   |
   v
[Agent Search Loop]
   |
   +---> Read cluster summaries
   |
   +---> Pick suspicious cluster
   |
   +---> Request traces from cluster
   |
   +---> Analyze for violations
   |
   +---> Decide: dig deeper or move on?
   |
   v
Output: Flagged violations
Think of Meerkat as a detective investigating a city’s crime patterns. Instead of interviewing every citizen (exhaustive search), the detective first gets a map showing neighborhoods with similar characteristics (clustering). Then they strategically visit suspicious neighborhoods, talk to a few residents, and decide whether to investigate further or move to another area. The detective can zoom between city-level patterns and individual interviews, but never wastes time on obviously safe neighborhoods. The clustering compresses 10,000 citizens into 100 neighborhoods, making strategic investigation feasible.
Key Concepts
-
Trace clustering as search compression: When you have 10,000 traces, examining each is infeasible. But if violations share behavioral patterns, they’ll cluster together in embedding space. Clustering compresses the search space from 10,000 individual items to ~100 groups. Now an agent can strategically sample: investigate a few traces per cluster, identify suspicious clusters, and focus compute there. It’s like organizing a library — instead of checking every book for a topic, you check sections, then shelves, then specific books.
-
Adaptive search budget allocation: The agent doesn’t spend equal time on every cluster. It maintains a “suspicion score” and allocates more investigation budget to promising regions. If a cluster shows early signs of violations, the agent requests more traces, performs deeper analysis, or compares with other clusters. If a cluster looks clean after initial inspection, it moves on. This is crucial because violations are sparse — most clusters are benign, so you want to quickly rule them out and focus on the 5% that matter.
-
Cross-trace violation detection: Some failures only appear when comparing multiple traces. Example: an agent might subtly manipulate data in trace A, then exploit that manipulation in trace B. Per-trace judges miss this because each trace looks individually fine. Meerkat’s agent can request traces from multiple clusters, compare them, and spot coordinated patterns. It’s like fraud detection — one transaction looks normal, but the pattern across ten transactions reveals the scheme.
Framework Shift
Before (per-trace judges):          After (Meerkat):

[Trace 1] ---> [Judge] ---> OK      [10K traces]
[Trace 2] ---> [Judge] ---> OK           |
[Trace 3] ---> [Judge] ---> OK           v
    ...                              [Cluster]
[Trace 10K] -> [Judge] ---> OK           |
                                         v
(Misses cross-trace patterns)       [Agent Search]
(No strategic focus)                     |
                                    +----+----+
                                    |         |
                                [Cluster A] [Cluster B]
                                    |         |
                                [Dig deep] [Skip]
                                    |
                                [Find violation]
From exhaustive linear scanning to hierarchical strategic search, the core shift is treating trace collections as explorable landscapes rather than flat lists.
Expert Assessment
Problem choice: This is a real gap. As AI agents deploy at scale, auditing becomes a bottleneck. The paper targets a genuine pain point — existing methods genuinely don’t scale to production trace volumes. The problem sits at the intersection of AI safety and practical deployment, which is timely.
Method maturity: The core insight (cluster then search) is elegant but not groundbreaking — it’s applying standard information retrieval ideas to a new domain. The execution is solid: they handle the engineering details (embedding choice, cluster granularity, agent prompting) competently. However, there’s a simpler baseline they don’t explore: active learning with uncertainty sampling. Could you achieve similar results by training a classifier and iteratively labeling high-uncertainty examples?
Experimental integrity: The results are impressive (4x improvement on CyBench, discovering benchmark cheating), but I’m skeptical of one claim. They say Meerkat “discovers widespread developer cheating” on a benchmark, but don’t provide enough detail to assess whether this is genuine cheating or legitimate optimization. The baselines are fair — they compare against per-trace LLM judges and exhaustive search within budget constraints. The ablations are thorough.
Writing quality: The paper front-loads motivation well, but the method section is dense. Section 3.2 (agent search procedure) would benefit from a concrete walkthrough with a real example. The related work section is perfunctory — they cite relevant papers but don’t position their contribution clearly against prior agentic auditing work.
Verdict: weak accept — Solid execution on a real problem with strong empirical results, but the conceptual novelty is incremental and some experimental claims need more support.
Takeaways
Hierarchical search for rare events: When searching for sparse failures in large datasets, don’t scan linearly. Cluster first, then adaptively allocate search budget. This pattern transfers beyond AI safety — think log analysis, fraud detection, or quality assurance in manufacturing.
Embedding-based clustering as a general auditing primitive: If you can embed your data (traces, logs, user sessions), clustering gives you a compressed map for investigation. The key insight: violations with similar root causes cluster together, so you can sample strategically.
Agent-in-the-loop for flexible detection: Fixed rules break on novel behaviors. Per-instance classifiers miss cross-instance patterns. An agent with access to cluster-level and instance-level views can adapt its search strategy. This is useful anywhere you need flexible, context-aware anomaly detection.
Concrete technique: Their two-stage embedding (trace → summary → embedding) is worth stealing. Directly embedding long traces is noisy; summarizing first improves cluster quality. Simple but effective.
论文: 2604.11806 作者: Adam Stein, Davis Brown, Hamed Hassani, Mayur Naik, Eric Wong 分类: cs.AI, cs.CL
缺口
审计员需要在海量智能体轨迹中找安全违规——想象一下要检查AI系统的数千条执行日志。
问题在于:失败案例很罕见(千分之一),很复杂(需要理解多步骤行为),有时只有对比多条轨迹才能看出来(协同滥用、隐蔽模式)。
现有方法以可预测的方式失败。
逐条判断器(如LLM分类器)看不到跨轨迹模式。
智能体审计(让AI智能体去调查)不可扩展——逐一检查一万条轨迹在计算上不可行。
固定监控器(基于规则的检测器)在智能体展现出规则未预料的新型不当行为时就失效了。
问题:海量轨迹集合中的罕见违规
   |
   v
假设:违规在嵌入空间中会聚类
   |
   +---> 方法:先聚类轨迹,再自适应搜索聚类
   |
   +---> 证据:发现的奖励黑客案例是以往的4倍,发现基准测试作弊
   |
   v
结论:结构化搜索胜过穷举或逐条方法
增量
一句话: Meerkat之前,审计员要么错过跨轨迹违规(逐条判断),要么面临计算不可行(穷举智能体搜索);
Meerkat之后,他们可以通过搜索轨迹聚类的压缩结构,在规模化场景下找到稀疏违规。
核心机制
Meerkat分两个阶段运作。
第一阶段,它嵌入所有轨迹并聚类,创建轨迹景观的压缩地图。
每个聚类代表具有相似行为模式的轨迹。
第二阶段,它执行自适应搜索:一个LLM智能体调查可疑聚类,决定哪些要深入探索,并可以请求聚类内特定轨迹的详细分析。
搜索是分层的。
智能体从聚类摘要(高层行为描述)开始。
如果某个聚类看起来可疑,它可以”放大”——请求代表性轨迹,检查具体例子,甚至跨聚类比较轨迹。
智能体维护搜索状态,跟踪已调查的区域和值得深入检查的区域。
输入:10,000条轨迹
   |
   v
[嵌入] --> 向量空间
   |
   v
[聚类] --> ~100个聚类
   |
   v
[智能体搜索循环]
   |
   +---> 读取聚类摘要
   |
   +---> 选择可疑聚类
   |
   +---> 请求聚类中的轨迹
   |
   +---> 分析违规
   |
   +---> 决定:深挖还是继续?
   |
   v
输出:标记的违规
把Meerkat想象成调查城市犯罪模式的侦探。
侦探不会采访每个市民(穷举搜索),而是先拿到一张地图,显示具有相似特征的街区(聚类)。
然后他们战略性地访问可疑街区,和几个居民交谈,决定是进一步调查还是转移到另一个区域。
侦探可以在城市级模式和个人访谈之间缩放,但绝不会在明显安全的街区浪费时间。
聚类把10,000个市民压缩成100个街区,使战略调查变得可行。
关键概念
- 轨迹聚类作为搜索压缩: 当你有10,000条轨迹时,逐一检查不可行。
但如果违规共享行为模式,它们会在嵌入空间中聚在一起。
聚类把搜索空间从10,000个独立项压缩到约100个组。
现在智能体可以战略性采样:每个聚类调查几条轨迹,识别可疑聚类,把计算资源集中在那里。
这就像整理图书馆——不是检查每本书找某个主题,而是检查分区,然后书架,然后具体的书。
- 自适应搜索预算分配: 智能体不会在每个聚类上花相同时间。
它维护一个”可疑度评分”,把更多调查预算分配给有希望的区域。
如果一个聚类显示出违规的早期迹象,智能体会请求更多轨迹,执行更深入的分析,或与其他聚类比较。
如果一个聚类在初步检查后看起来干净,它就继续前进。
这很关键,因为违规是稀疏的——大多数聚类是良性的,所以你想快速排除它们,专注于那5%重要的。
- 跨轨迹违规检测: 有些失败只在比较多条轨迹时才出现。
例子:智能体可能在轨迹A中微妙地操纵数据,然后在轨迹B中利用该操纵。
逐条判断器会错过这个,因为每条轨迹单独看都正常。
Meerkat的智能体可以请求来自多个聚类的轨迹,比较它们,发现协同模式。
这就像欺诈检测——一笔交易看起来正常,但十笔交易的模式揭示了骗局。
框架转变
之前(逐条判断器):              之后(Meerkat):

[轨迹1] ---> [判断器] ---> 正常    [10K轨迹]
[轨迹2] ---> [判断器] ---> 正常         |
[轨迹3] ---> [判断器] ---> 正常         v
    ...                            [聚类]
[轨迹10K] -> [判断器] ---> 正常         |
                                       v
(错过跨轨迹模式)                 [智能体搜索]
(无战略重点)                         |
                                  +----+----+
                                  |         |
                              [聚类A]   [聚类B]
                                  |         |
                              [深挖]    [跳过]
                                  |
                              [发现违规]
从穷举线性扫描到分层战略搜索,核心转变是把轨迹集合当作可探索的景观,而非扁平列表。
专家评审
选题眼光: 这是真缺口。
随着AI智能体大规模部署,审计成为瓶颈。
论文瞄准了一个真实痛点——现有方法确实无法扩展到生产级轨迹量。
问题处于AI安全和实际部署的交叉点,很及时。
方法成熟度: 核心洞见(先聚类再搜索)优雅但不算突破——是把标准信息检索思想应用到新领域。
执行扎实:他们妥善处理了工程细节(嵌入选择、聚类粒度、智能体提示)。
但有个更简单的基线他们没探索:用不确定性采样的主动学习。
能否通过训练分类器并迭代标注高不确定性样本来达到类似结果?
实验诚意: 结果令人印象深刻(CyBench上4倍改进,发现基准测试作弊),但我对一个声明持怀疑态度。
他们说Meerkat”发现了基准测试中广泛的开发者作弊”,但没提供足够细节来评估这是真作弊还是合法优化。
基线是公平的——他们与逐条LLM判断器和预算约束内的穷举搜索比较。
消融实验很彻底。
写作功力: 论文前面的动机铺垫得好,但方法部分很密集。
第3.2节(智能体搜索过程)如果能用真实例子具体演示一遍会更好。
相关工作部分敷衍——他们引用了相关论文,但没有清晰地相对于先前的智能体审计工作定位自己的贡献。
判决: 弱接收 — 在真实问题上执行扎实,实证结果强劲,但概念新颖性是增量式的,一些实验声明需要更多支持。
要点总结
罕见事件的分层搜索: 在大数据集中搜索稀疏失败时,不要线性扫描。
先聚类,然后自适应分配搜索预算。
这个模式可迁移到AI安全之外——想想日志分析、欺诈检测或制造业质量保证。
基于嵌入的聚类作为通用审计原语: 如果你能嵌入数据(轨迹、日志、用户会话),聚类就给你一张压缩的调查地图。
关键洞见:具有相似根本原因的违规会聚在一起,所以你可以战略性采样。
智能体在环用于灵活检测: 固定规则在新型行为上失效。
逐实例分类器错过跨实例模式。
能访问聚类级和实例级视图的智能体可以调整搜索策略。
这在任何需要灵活、上下文感知的异常检测的地方都有用。
具体技术: 他们的两阶段嵌入(轨迹→摘要→嵌入)值得借鉴。
直接嵌入长轨迹很嘈杂;
先总结能提高聚类质量。
简单但有效。