Paper: 2606.28294 Authors: Kevin Kingslin, Anish Natekar, Ashutosh Ranjan, Vivek Srivastava, Savita Bhat, Shirish Karande Categories: cs.LG, cs.MA
The Gap
Existing alignment methods, like RLHF, reduce human preferences to binary comparisons (A > B). Inverse Constitutional AI (ICAI) took a step forward by prompting an LLM to generate a single natural-language principle that explains why A beat B. But the problem is: real preferences are rarely one-dimensional. A creative writing judge might prefer story B because it is “more original” even though A is “better structured.” ICAI’s single-pass explanation collapses all such nuance into one capsule, losing the trade-off reasoning. This paper asks: what if we actively invite multiple competing perspectives before settling on a principle?
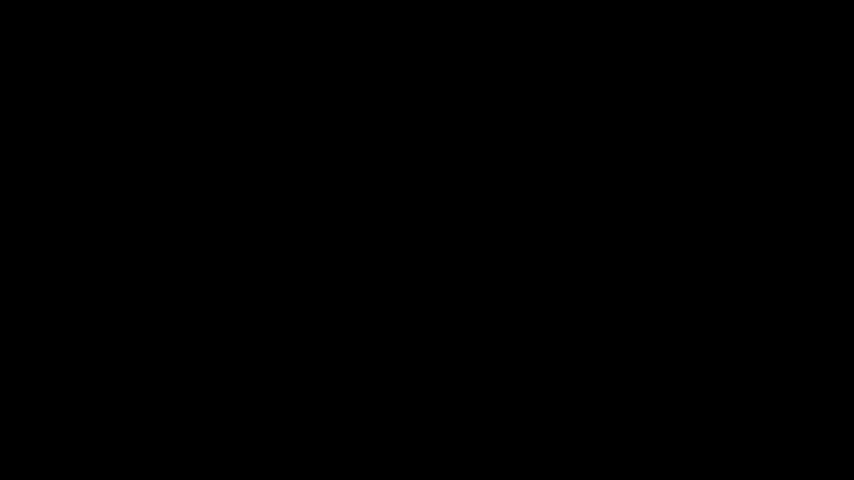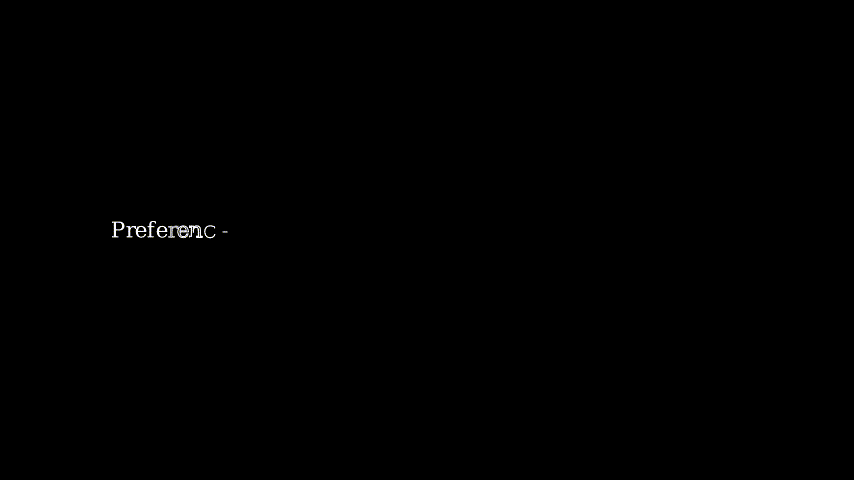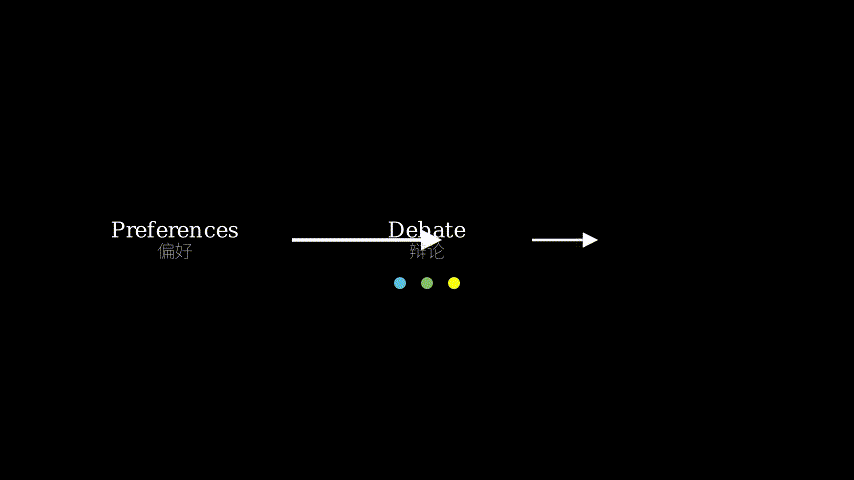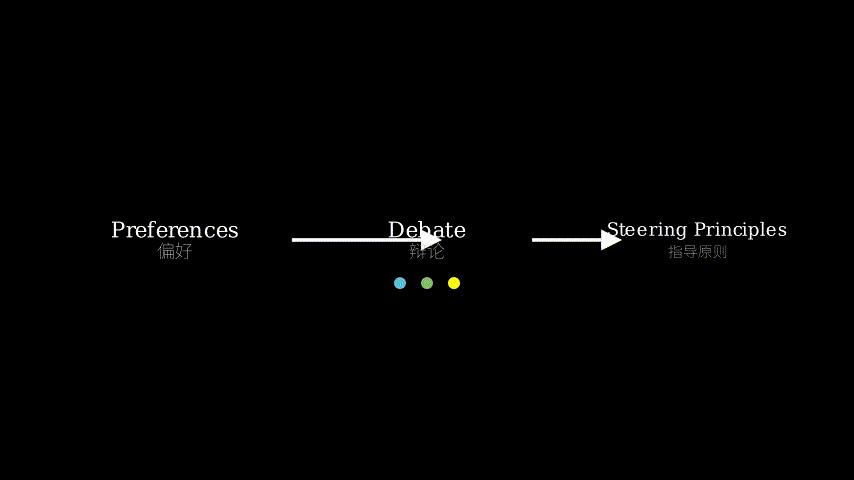
The logical path from gap to conclusion:
[Problem: single-pass ICAI misses multi-factor reasoning]
        |
        v
[Assumption: structured debate among diverse personas can surface richer rationales]
        |
        v
[Method: Democratic ICAI -- for each pair, spawn N personas, each argues for its preferred choice + rationale; aggregate rationales into a principle]
        |
        v
[Evidence: on MuCE-Pref and LiTBench (creative tasks), Democratic ICAI beats IPA (deliberative prompting) and single-pass ICAI in preference prediction accuracy; LLM annotators prefer its constitutions]
        |
        v
[Conclusion: multi-persona debate yields more faithful and interpretable steering principles]
The Increment
One sentence: Before this paper, preference principles were extracted from a single-shot explanation of why one item outranks another; after this paper, principles are extracted from a structured debate among multiple personas, each bringing a different criterion to the table.
Core Mechanism
Democratic ICAI works in three stages. First, persona debate: for each pair of items (A, B), the system initializes a set of LLM personas — each with a distinct “character” (e.g., “a literary critic valuing originality,” “a pragmatist valuing clarity”). Each persona argues why its favored item is better and provides a rationale. The arguments are collected without any interaction (parallel debate). Second, rationale aggregation: all arguments are fed into a separate aggregator LLM that synthesizes them into a *constitution — a set of natural-language principles that capture the multi-faceted reasoning underlying the data. Third, steering: these principles are then used to train either an LLM-based judge (via few-shot prompting) or a decision tree judge (by converting principles into decision rules) to predict future preferences.
[Data flow diagram]
Input:        (A, B) pairs + original preference labels
                |
                v
[Persona Pool] -- persona_1: "I prefer A because ..."
              |  persona_2: "I prefer B because ..."
              |  persona_3: "I prefer A because ..."
              |  ...  (N personas, each with own character)
                |
                v
[Aggregator] -- combines all rationales, extracts common criteria + conflicts
                |
                v
[Constitution] -- set of principles (e.g., "Prioritize originality over structure when genre is experimental")
                |
                v
[Judge]        -- LLM or decision tree; applies constitution to new pairs
Output:        predicted preference
Here is a structural metaphor: imagine a hospital multidisciplinary team (MDT) meeting. A patient (the preference pair) presents a complex case. Instead of one doctor giving a single opinion (ICA1), the MDT brings in a cardiologist, a neurologist, a social worker (personas), each with their own expertise and perspective. They argue their recommended treatment (which item is better) and the reasons (rationales). Then the chief physician (aggregator) listens to all views and writes a unified treatment protocol (constitution). This protocol is then used by the nursing team (judge) to make daily decisions (predict new preferences). The key is that the final protocol captures trade-offs that no single specialist would surface alone — exactly what Democratic ICAI does.
Key Concepts
-
Persona Debate: Instead of asking a single LLM “Why is A better than B?,” Democratic ICAI first defines a set of *personas — each is a short prompt describing a particular perspective (e.g., “You are a critic who values emotional resonance over technical correctness”). Each persona generates its own rationale for the same pair. The debate is asynchronous (no turn-taking) but the collection of arguments represents a kind of “internal committee.” This is important because it forces the system to consider criteria that might be suppressed in a single answer. Example: for a Haiku pair, one persona might favor the one with better syllable count, another the one with deeper metaphor. Both rationales are kept; neither is discarded.
-
Inverse Constitutional AI (ICAI): The precursor method. Given a set of human preferences, ICAI asks an LLM to generate a *constitution — a short list of principles that, if followed, would reproduce the preferences. It does this by prompting: “Summarize the preference pattern in a principle.” The problem is that the LLM tends to produce a single, often vague, principle (e.g., “favor conciseness”) that misses nuance. Democratic ICAI replaces this single prompt with the debate mechanism.
-
Faithfulness of Preference Modeling: How well does a model’s predicted preference agree with the ground truth human judgments? The paper measures this via accuracy on held-out pairs. But they also measure *annotator preference: they ask LLM judges which constitution (ICA1 vs Democratic ICAI) better explains the data. Higher faithfulness means the extracted principles actually reflect the reasoning that humans used, not just a superficial pattern.
Framework Shift
Draw a napkin sketch comparing the old pipeline and the new pipeline:
Before (single-pass ICAI):              After (Democratic ICAI):

   Human pairs                               Human pairs
        |                                         |
        v                                         v
   [Single LLM]                              [Persona L1] [Persona L2] ... [Persona Ln]
        |                                         |   |        |            |
        v                                         v   v        v            v
   [1 principle]                            [All rationales] --aggregate--> [Constitution]
        |                                         |
        v                                         v
   [Judge]                                   [Judge]
        |                                         |
        v                                         v
   Predictions                              Predictions
One sentence: From single-channel explanation to multi-channel deliberation, the core shift is that the system no longer forces a single LLM to compress all reasoning into one statement; instead it captures the inherent multi-criteria nature of human preferences by design.
Expert Assessment
Problem choice: Real gap. Anyone who has run RLHF knows that human judgments are messy and multi-dimensional. ICAI was a nice try but it papered over this messiness. Democratic ICAI goes after the root cause. It sits at a growing intersection of interpretability, alignment, and multi-agent debate. Good timing.
Method maturity: Clever insight rather than brute force. The idea of using personas to elicit multiple rationales is elegant and cheap (parallel calls; no adversarial training). However, it depends on two assumptions that are not deeply tested: (1) that the aggregator LLM can faithfully synthesize conflicting rationales without losing nuance, and (2) that the predefined personas are sufficiently diverse. The paper uses 5 personas per pair for creative tasks — that’s reasonable but the lack of ablation on persona count is a minor weakness. A simpler alternative would be to just ask the LLM for N different rationales in one call; the persona framing adds scaffolding but might not be strictly necessary. The authors should have compared to that.
Experimental integrity: Baselines are fair: they compare to a “deliberative prompting” baseline (just ask the LLM to think step by step) and to single-pass ICAI. The numbers on MuCE-Pref and LiTBench show clear improvements (roughly +3-6% accuracy). However, the “annotator preference” metric is a bit circular — they ask LLM annotators to rate which constitution they prefer, but those same LLMs might simply favor the longer, more detailed one (which Democratic ICAI naturally produces). A human evaluation would be stronger. Also, the paper only tests on creative tasks; it’s unclear how well this transfers to factual or moral domains. One red flag: the decision-tree judge experiment is small and the tree depth is not shown. But overall, the experimental design is competent and the results are credible.
Writing quality: The paper is well-structured and the introduction is motivating. The weakest section is the “Related Work” — it’s long but mostly name-drops without deep comparisons. I would rewrite the methods section to explain the persona generation prompt in full (the appendix has it, but the main text should at least show an example). Also, the ASCII figures are simple but functional.
Verdict: weak accept — The idea is novel and the mechanism is clean, but the evaluation has one too many shortcuts (no human eval, limited domain) to be a strong result. Still worth reading for the persona debate framing.
Takeaways
-
Persona-based debate as a cheap alternative to multi-agent RL: You don’t need adversarial training or turn-taking. Just prompt each persona independently in parallel, then aggregate. This can be applied to any problem where you want to surface multiple perspectives from one LLM (e.g., debugging, ethics review, summarization).
-
Constitution extraction with aggregation: After collecting multiple rationales, don’t just average them — let a separate LLM summarize them into a concise set of principles. This two-stage process (generate → distill) is a reusable pattern for extractive interpretability.
-
Decision tree as a faithful judge: Using the extracted principles to build a shallow decision tree is a nice idea for transparency. Practitioners can directly inspect the decision rules (e.g., “if genre == experimental then prefer originality > structure”). This is a practical way to convert an LLM-derived constitution into a deterministic, auditable model.
论文: 2606.28294 作者: Kevin Kingslin, Anish Natekar, Ashutosh Ranjan, Vivek Srivastava, Savita Bhat, Shirish Karande 分类: cs.LG, cs.MA
缺口
现有的对齐方法(如RLHF)将人类偏好简化为二元比较(A > B)。 逆宪法AI(ICAI)向前迈了一步:它让大语言模型生成一条自然语言原则来解释为什么A赢了B。 但问题是:真实的偏好很少是单维度的。 一位创意写作评审可能因为故事B“更有原创性”而选择它,即使故事A“结构更好”。 ICAI的单次解释将所有这些细微差异压缩进一个胶囊,丢失了权衡推理。 这篇论文问:如果我们主动邀请多个竞争性视角,然后再确立原则,会怎样?
从缺口到结论的逻辑路径:
[问题:单次ICAI遗漏多因素推理]
        |
        v
[假设:结构化辩论(不同角色)能浮现更丰富的理由]
        |
        v
[方法:民主ICAI——对每对样本,生成N个角色,每个角色论证其偏好并给出理由;聚合理由成原则]
        |
        v
[证据:在MuCE-Pref和LiTBench(创意任务)上,民主ICAI在偏好预测准确率上胜过IPA和单次ICAI;
       大语言模型标注者更喜欢民主ICAI生成的宪法]
        |
        v
[结论:多角色辩论产生更忠实且可解释的指导原则]
增量
一句话: 这篇论文之前,偏好原则是从单次解释中提取的(为什么一个比另一个好); 这篇论文之后,原则是从多个角色的结构化辩论中提取的,每个角色带来不同的评判标准。
核心机制
民主ICAI分三个阶段。第一,角色辩论:对每对(A, B),系统初始化一组大语言模型角色——每个都有独特的“个性”(例如,“一位重视原创性的文学评论家”,“一位重视清晰度的实用主义者”)。 每个角色论证自己为什么更喜欢哪一个,并提供理由。 辩论是并行的(没有轮次交流)。 第二,理由聚合:所有理由被送入另一个聚合器大语言模型,它将这些理由综合成一部《宪法》——一组自然语言原则,捕捉数据背后多方面的推理。 第三,引导:这些原则随后被用来训练基于大语言模型的评判者(通过少样本提示)或决策树评判者(将原则转化为决策规则),以预测未来的偏好。
[数据流图]
输入:        (A, B)对 + 原始偏好标签
                |
                v
[角色池] -- 角色1: "我更喜欢A,因为..."
         | 角色2: "我更喜欢B,因为..."
         | 角色3: "我更喜欢A,因为..."
         |  ...  (N个角色,每个有自己的个性)
                |
                v
[聚合器] -- 结合所有理由,提取共同标准 + 冲突点
                |
                v
[宪法] -- 一组原则(例如,“当体裁是实验性时,优先原创性而非结构”)
                |
                v
[评判者] -- 大语言模型或决策树;在新对子上应用宪法
输出:        预测的偏好
用一个结构性比喻:想象医院的多学科团队(MDT)会议。 一个病人(偏好对)呈现复杂病例。 不是一位医生给出单一意见(ICAI),而是MDT召集了心脏科医生、神经科医生、社会工作者(角色),每位都有各自的专长和视角。 他们争论推荐的治疗方案(哪个更好)以及理由。 然后主治医师(聚合器)听取所有意见,写下统一治疗方案(宪法)。 这个方案随后被护理团队(评判者)用来做日常决策(预测新偏好)。 关键是,最终方案捕捉了单个专家自己无法浮现的权衡——这正是民主ICAI所做的。
关键概念
-
角色辩论(Persona Debate):不是问单个大语言模型“为什么A比B好?”,民主ICAI先定义一组**角色*——每个都是描述特定视角的简短提示(例如,“你是一位重视情感共鸣胜过技术正确性的评论家”)。 每个角色为同一对样本生成自己的理由。 辩论是异步的(无需轮流发言),但所有理由的集合代表了一种“内部委员会”。 这很重要,因为它迫使系统考虑那些在单个答案中可能被压制的标准。 例子:对于一首俳句对,一个角色可能偏爱音节数更准的那首,另一个角色偏爱隐喻更深的那首。 两个理由都被保留,不丢弃任何一个。
-
逆宪法AI(Inverse Constitutional AI, ICAI):前身方法。 给定一组人类偏好,ICAI让大语言模型生成一部宪法——一组简短的原则,如果遵循这些原则,就能再现偏好。 它通过提示“用一个原则总结偏好模式”来实现。 问题是,大语言模型倾向于产生一条(通常模糊的)原则(如“偏爱简洁”),丢失了细微差别。 民主ICAI用辩论机制替换了这个单次提示。
-
偏好建模的忠实度(Faithfulness of Preference Modeling):模型预测的偏好与真实人类判断的一致程度。 论文通过留出对上的准确率来测量。 他们还测量了标注者偏好:他们问大语言模型评判者哪部宪法(ICAI vs 民主ICAI)更好地解释了数据。 更高的忠实度意味着提取的原则真正反映了人类用来推理的因素,而不仅仅是表面模式。
框架转变
画一张餐巾纸速写,对比旧流水线和新流水线:
之前(单次ICAI):                    之后(民主ICAI):

   人类偏好对                              人类偏好对
        |                                         |
        v                                         v
   [单个大语言模型]                       [角色1] [角色2] ... [角色N]
        |                                         |   |        |
        v                                         v   v        v
   [1条原则]                             [所有理由] --聚合--> [宪法]
        |                                         |
        v                                         v
   [评判者]                                   [评判者]
        |                                         |
        v                                         v
   预测                                      预测
一句话:从单通道解释到多通道审议,核心转变是系统不再强迫单个大语言模型将所有推理压缩成一个陈述,而是通过设计捕捉人类偏好的天然多准则性质。
专家评审
选题眼光: 真实的缺口。 任何做过RLHF的人都知道人类判断是杂乱和多维的。 ICAI是一次不错的尝试,但它掩盖了这种杂乱。 民主ICAI直击根源。 它置于可解释性、对齐和多智能体辩论的交汇点。 时机正好。
方法成熟度: 巧劲而非蛮力。 用角色引出多重理由的想法很优雅且廉价(并行调用,无需对抗训练)。 但它依赖于两个未经深入测试的假设:(1)聚合器大语言模型能忠实地综合冲突的理由而不丢失细微差别;(2)预定义的角色足够多样。 论文在创意任务上每对使用5个角色——这合理,但缺乏关于角色数量的消融实验是一个小弱点。 更简单的替代方案是让大语言模型在一次调用中产生N个理由;角色框架提供了一个脚手架,但可能不是绝对必要。 作者应该与此对比。
实验诚意: 基线公平:他们对比了“审议提示”基线(让大语言模型一步步思考)和单次ICAI。 在MuCE-Pref和LiTBench上的数字显示了清晰的改进(大约+3-6%准确率)。 然而,“标注者偏好”指标有点循环——他们让大语言模型标注者评价哪部宪法更好,但这些大语言模型可能天然更喜欢更长的、更详细的那一部(民主ICAI自然如此)。 人工评估会更强。 另外,论文只在创意任务上测试;不清楚这种方法如何迁移到事实或道德领域。 一个值得警惕的地方:决策树评判者实验很小,树深度没有展示。 但总体而言,实验设计合理,结果可信。
写作功力: 论文结构良好,引言具有激励性。 最薄弱的环节是“相关工作”——它很长,但主要是点名式列举,缺乏深入比较。 我建议重写方法部分,完整展示角色生成提示(附录中有,但正文至少应该给一个例子)。 另外,ASCII图简单但功能明确。
判决: 弱接收——想法新颖,机制干净,但评估有太多捷径(没有人工评估,领域有限),不足以成为强结果。仍值得阅读,因为角色辩论的框架有价值。
要点总结
-
角色辩论作为多智能体强化学习的廉价替代:你不需要对抗训练或轮流发言。只需对每个角色独立并行提示,然后聚合。这可以应用于任何想从一个LLM中浮现多个视角的问题(例如调试、伦理审查、摘要)。
-
带聚合的宪法提取:收集多个理由后,不要简单地平均——让另一个LLM将它们总结成一组简洁的原则。这种两步流程(生成→蒸馏)是可复用的可解释性提取模式。
-
决策树作为忠实评判者:使用提取的原则构建浅层决策树是一个很好的透明性想法。实践者可以直接检查决策规则(例如,“如果体裁是实验性,则偏好原创性胜过结构”)。这是将LLM衍生的宪法转换为确定性、可审计模型的一种实用方式。